How SES Actually Works When You're Trying to Use It
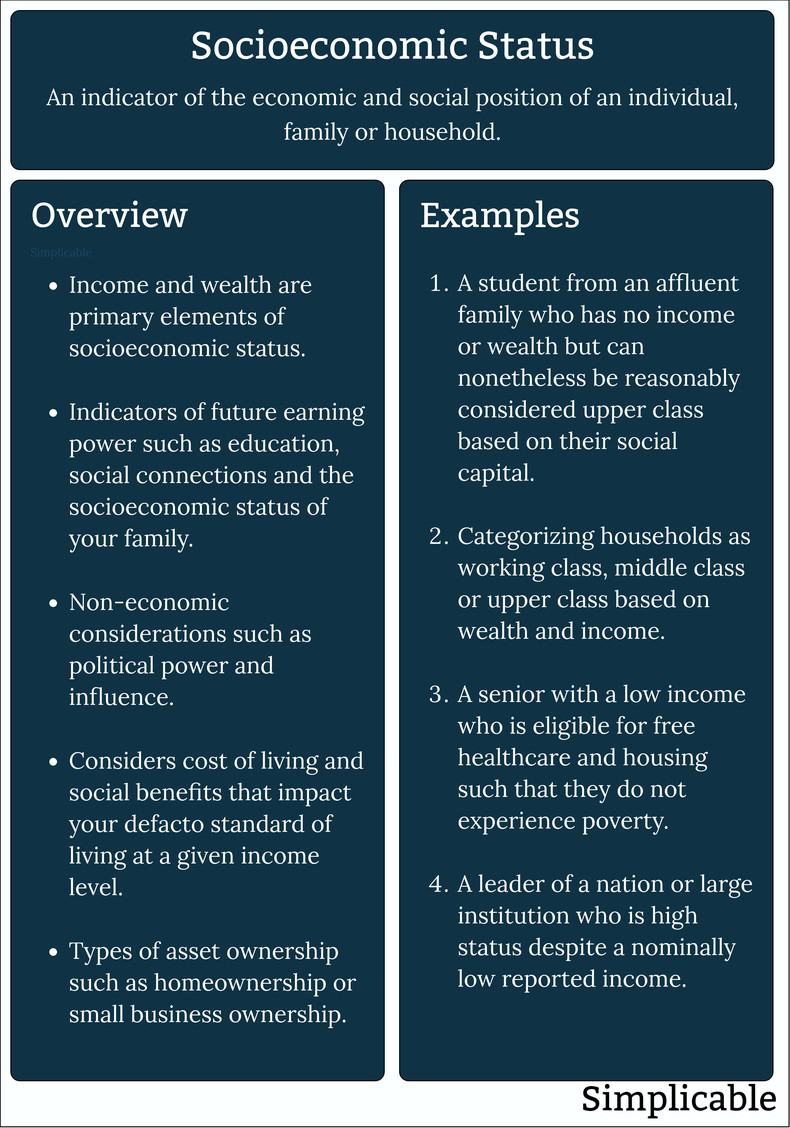
Socioeconomic status is one of those terms that gets thrown around in policy papers, admissions offices, and neighborhood analyses without anyone really agreeing on what it means or how to measure it. If you've ever tried to operationalize it for anything beyond a casual conversation, you know the headache. It's not a single number you can pull from a database. It's a composite judgment that involves income, education, occupation, and sometimes a handful of other variables that vary by country and by institution. At its core, SES is an attempt to rank where people sit within a society's hierarchy. It combines economic resources with social standing. Income tells you what someone can buy. Educational attainment tells you what credentials they hold. Occupational prestige tells you what kind of work they do and how much respect it carries in the social order. Put those together and you get a rough proxy for power, privilege, and access. The reason people use it matters as much as the definition. Public health researchers use it to predict outcomes like life expectancy and chronic disease rates. Sociologists use it to study mobility patterns. Urban planners use it to identify underserved areas. Admissions committees at certain universities use it to contextualize applicant achievements relative to opportunity available to them. Each of those use cases shapes how you measure it differently.
I learned this the hard way a few years ago when a city government contracted my team to produce an SES index for their housing allocation program. They wanted a single score per census tract that would determine priority access to subsidized units. The obvious approach was to grab decennial census data on median income, education, and occupation and blend them. We did that. The result looked reasonable on paper. But when we ran the numbers against actual outcomes, the index systematically underweighted areas with high concentrations of elderly retirees on fixed incomes. Those neighborhoods showed low median income and low labor force participation, which tanked their scores. The people living there weren't economically vulnerable in the way the model assumed. They were just retired. The workaround was to add a per-capita income metric alongside median household income and weight it differently for tracts with populations over 65. That alone shifted eligibility for roughly 14 percent of applicants in the target region. This is the kind of edge case you don't catch until after you've built the model and presented the results. Which brings me to the actual mechanics. Building an SES measure involves a sequence of decisions that will make or break whatever analysis you're running. First you pick your unit of analysis. Individual. Household. Census tract. Metro area. Each unit has different data availability and different implications for interpretation. Individual-level SES is messier but more precise. Aggregated SES is cleaner but introduces ecological fallacy risk, which is when you assume individual outcomes based on group-level data. That trap has ruined more studies than I care to count.
Second, you select your component variables. The standard trio is income, education, and occupation. Sometimes you add wealth, which is a whole different beast because wealth data is notoriously sparse. American Community Survey doesn't report it directly. You have to impute it from tax records or use supplements like the Survey of Consumer Finances, neither of which is straightforward. Sometimes you add neighborhood characteristics like school quality or crime rates, which pushes SES into a composite index territory that's harder to defend but sometimes more predictive. Third, you decide how to weight and combine those variables. Equal weighting is the lazy approach and it works fine for quick-and-dirty analysis. Principal component analysis is the statistically rigorous approach and it extracts the common variance across your indicators to create a latent SES factor. That's what most peer-reviewed studies use. There's also the Dewey Decimal approach where you code occupations into prestige scores and combine them with education and income through a regression-based formula. The Ganzeboom–Treiman index is the standard cross-national version of that. Fourth, you validate. This step gets skipped constantly. You take your composite score and check whether it correlates with known outcomes in your data. Health outcomes. Educational attainment. Criminal justice involvement. If your SES measure doesn't predict anything it should predict, you've built something that looks fancy but isn't useful. A validated SES index in U.S. data typically explains between 8 and 15 percent of variance in health outcomes, which sounds small but is actually meaningful at population levels.
Get the Full Details
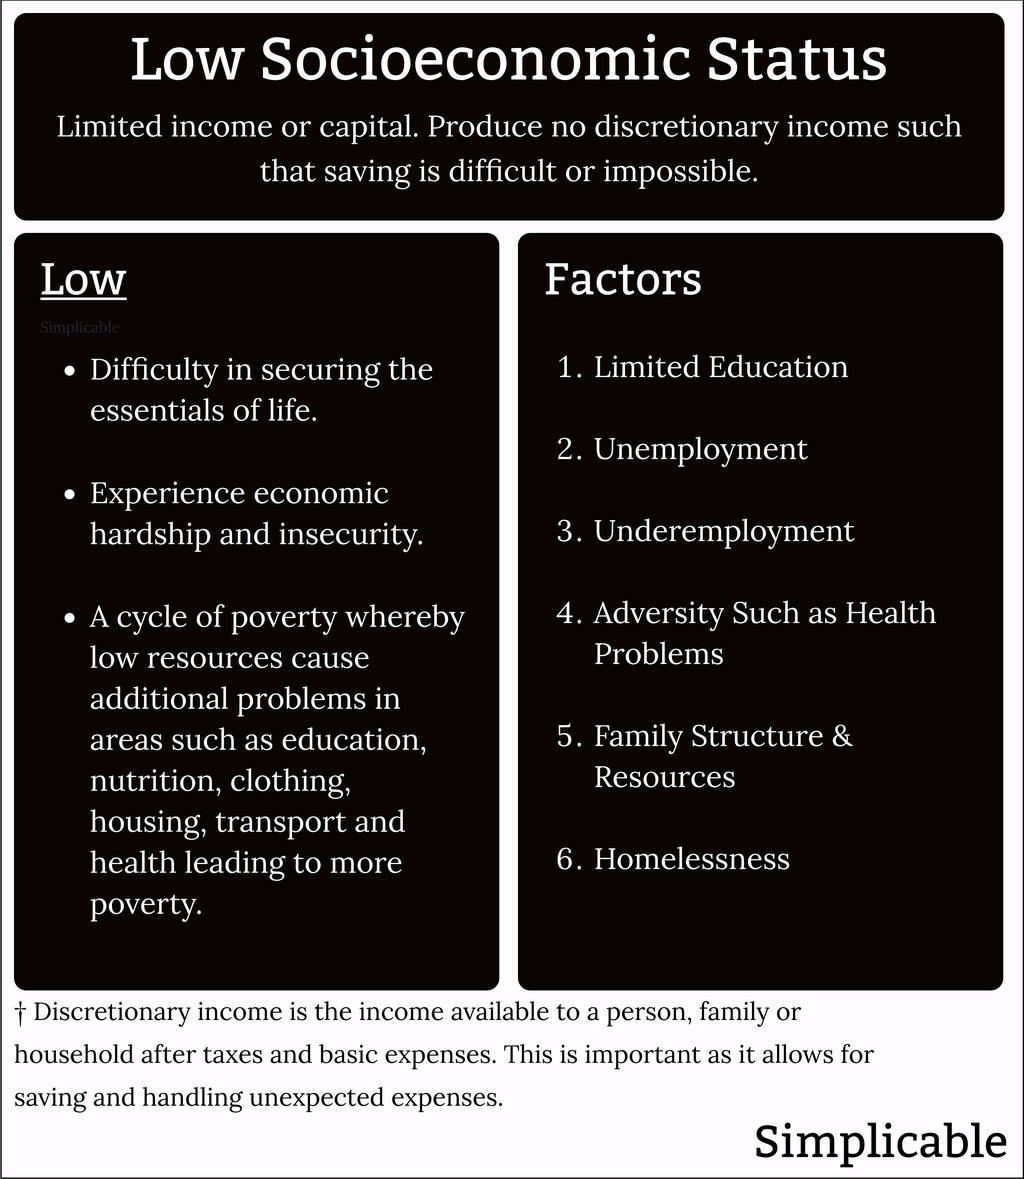
Here's something most beginners miss: socioeconomic status is not static. It changes over the life course, and measuring it at a single point in time can produce wildly misleading results. A twenty-five-year-old graduate student will have low current income but high future earning potential and elevated parental SES. If you code them as low SES based on income alone, you've misclassified them. The workaround is to use parental SES as a covariate when studying younger adults, or to use anticipated rather than current income in longitudinal models. That adjustment alone can shift effect sizes by 20 to 30 percent in studies of early career outcomes. Another counter-intuitive point is that SES often interacts with race and ethnicity in ways that make straightforward comparison impossible. Black and White Americans with identical income and education levels frequently show different health outcomes, different occupational trajectories, and different neighborhood environments. This is sometimes called the paradox of Black middle-class stability, and it means that an SES index derived from a mixed-race sample can underestimate the disadvantage experienced by minority groups at each SES level. If you're comparing outcomes across racial groups, you need to include race as an explicit modifier in your model, not just control for it. The biggest limitation of SES as a measure is that it reduces structural inequality to individual attributes. It tells you where someone sits relative to others, but it doesn't tell you why the hierarchy exists or how it reproduces itself. Two people with the same SES score can have drastically different relationships to power, social networks, and institutional trust. An engineer making $90,000 in a company town and a tenured professor making $90,000 at a flagship university occupy the same statistical space but live in completely different social worlds. That's why SES works best as a control variable rather than a standalone explanation.
If you need something more granular than the standard income-education-occupation triad, consider layering in measures of social capital like network diversity and civic engagement, or material hardship indices that capture food insecurity, housing instability, and medical debt. The Cornell Material Hardship Scale is one established tool for this. It adds predictive power beyond raw income, especially for low-income populations where income statistics smooth over the volatility that actually defines daily life. Data sources worth knowing about: the U.S. Census Bureau's American Community Survey five-year estimates are the workhorse for tract-level SES data. The Panel Study of Income Dynamics tracks individual and household SES longitudinally from 1968 to present, though access requires application. The Integrated Public Use Microdata Series gives you harmonized census microdata across decades, which is essential for historical comparisons. Internationally, the World Values Survey and the European Social Survey provide comparable SES indicators across countries, though the question wording still varies enough to require careful harmonization. One practical note on software. R packages like sjlabelled and haven make importing ACS data painless. The srvyr package handles complex survey weights, which you absolutely need if you're working with ACS microdata and want nationally representative estimates. Stata users should look at the reghdfe command for high-dimensional fixed effects when modeling SES alongside region, year, and demographic controls. These tools cut the data wrangling time from something that would take a full day to roughly two hours for a standard tract-level analysis.
The bottom line is that socioeconomic status is a useful but blunt instrument. It captures real variation in life outcomes and it's indispensable for any analysis of inequality. But it's only as good as the decisions you make about what to include, how to weight it, and what you do with the gaps. The people who treat it as a finished product rather than a starting point usually end up with results that look clean and mean nothing.