Practical Guide to the Five-Number Summary
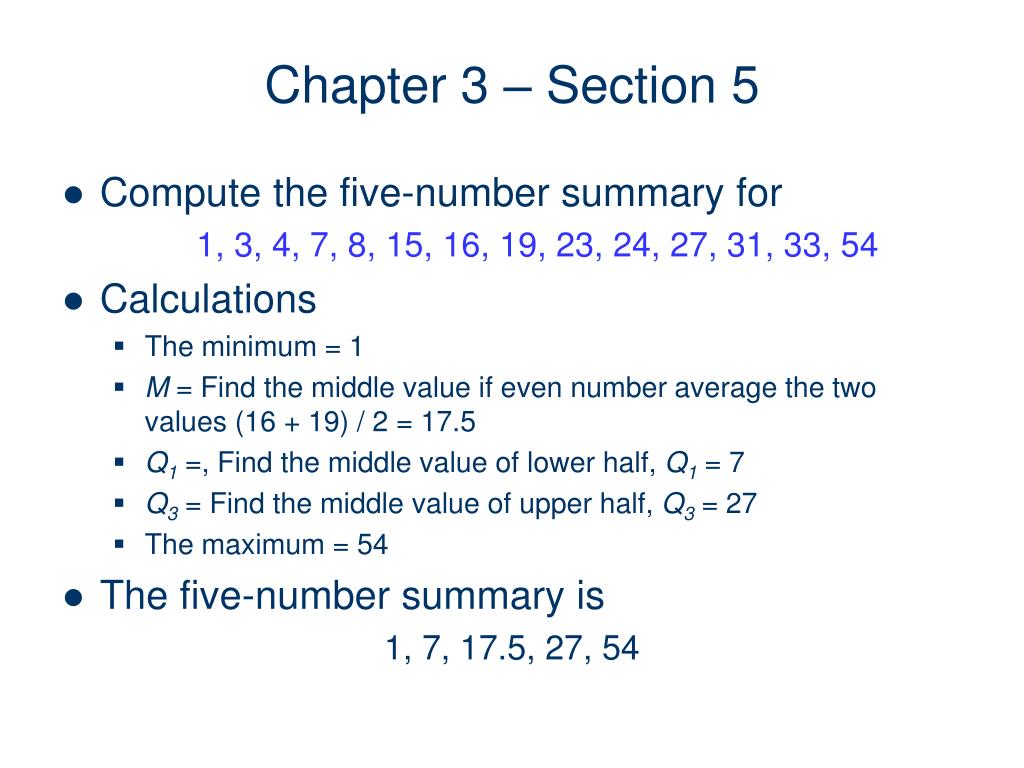
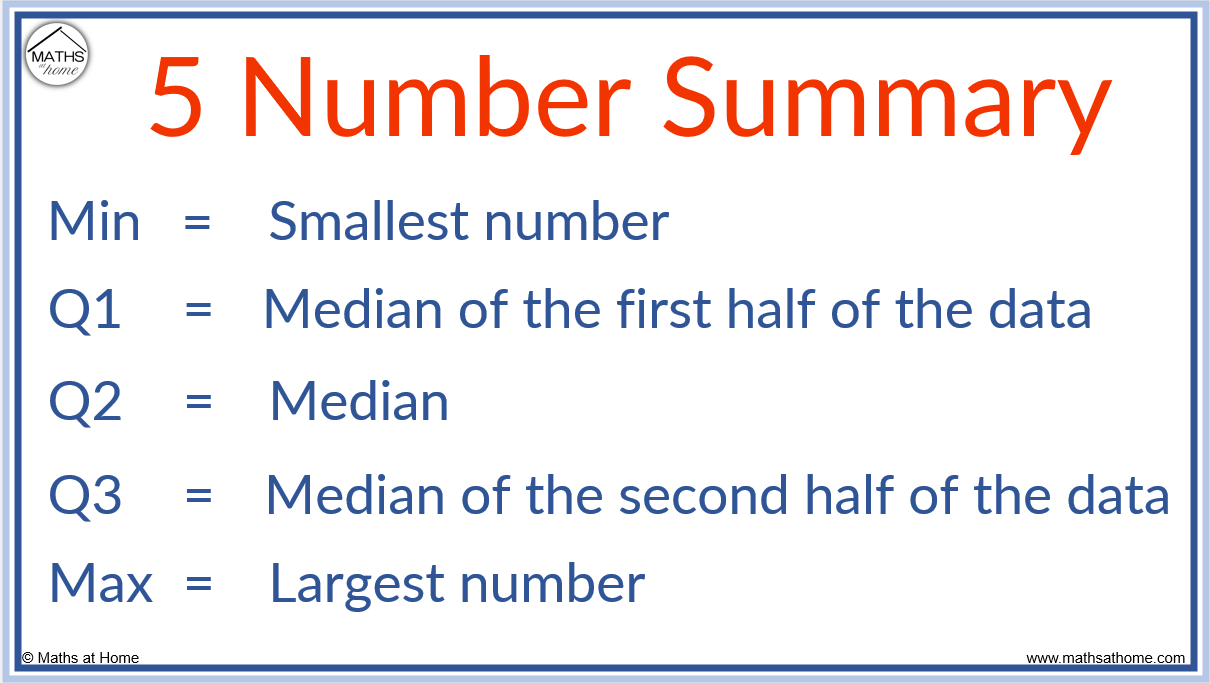
The five-number summary is simply five values that describe a dataset: minimum, first quartile (Q1), median, third quartile (Q3), and maximum. It is the numerical backbone behind a box plot. You sort your data, then extract those five points. That is the whole procedure. People often learn this concept in an intro stats class and then never touch it again until they need to do exploratory data analysis for real. The concept itself is trivial. The execution is where most mistakes happen. Here is how the calculation actually works. Take your raw data and order it from smallest to largest. The minimum is the first value. The maximum is the last value. The median is the middle value. If you have an even count of observations, the median is the average of the two center values. Q1 is the median of the lower half. Q3 is the median of the upper half.
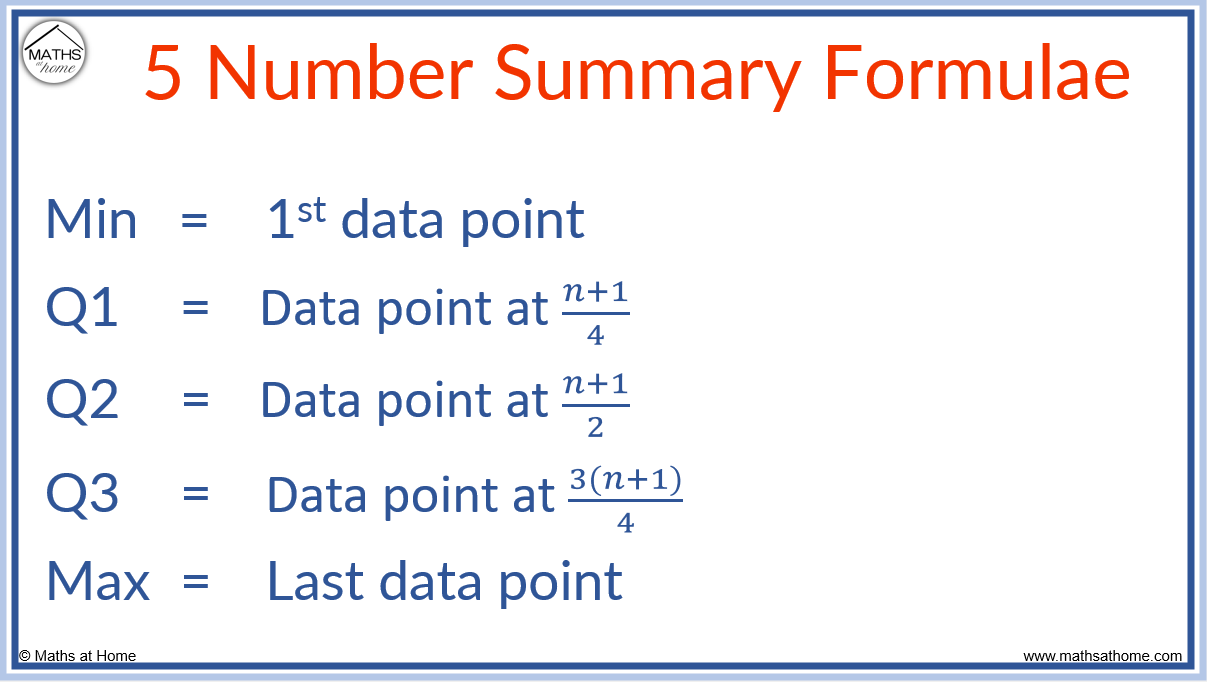
That is it. Now here is the part that trips people up consistently. When your dataset has an odd number of observations, do you include the median in both the lower and upper halves when computing Q1 and Q3? The answer depends on which method your software uses, and the methods disagree often enough to matter. Tukey's method, which is the default in Minitab and appears in most introductory textbooks, excludes the median from both halves when the dataset size is odd. The method used by Excel's QUARTILE.EXC function and R's default type 7 is different. It includes the median in the calculation through interpolation. These produce different numerical results, and they can differ enough to change how you interpret a box plot, especially with small datasets. I ran into this exact problem a couple years ago when I was analyzing survey response times from a single department rollout. I had roughly 40 data points. The online calculator I used first reported a Q1 that was about three seconds lower than what my colleague got using R. We spent twenty minutes chasing each other before I realized we were using different quartile definitions. The fix was simply agreeing on a method upfront. I switched everything to the type 7 method since that is what R and Python's numpy.percentile use by default, and we aligned our documentation around it.
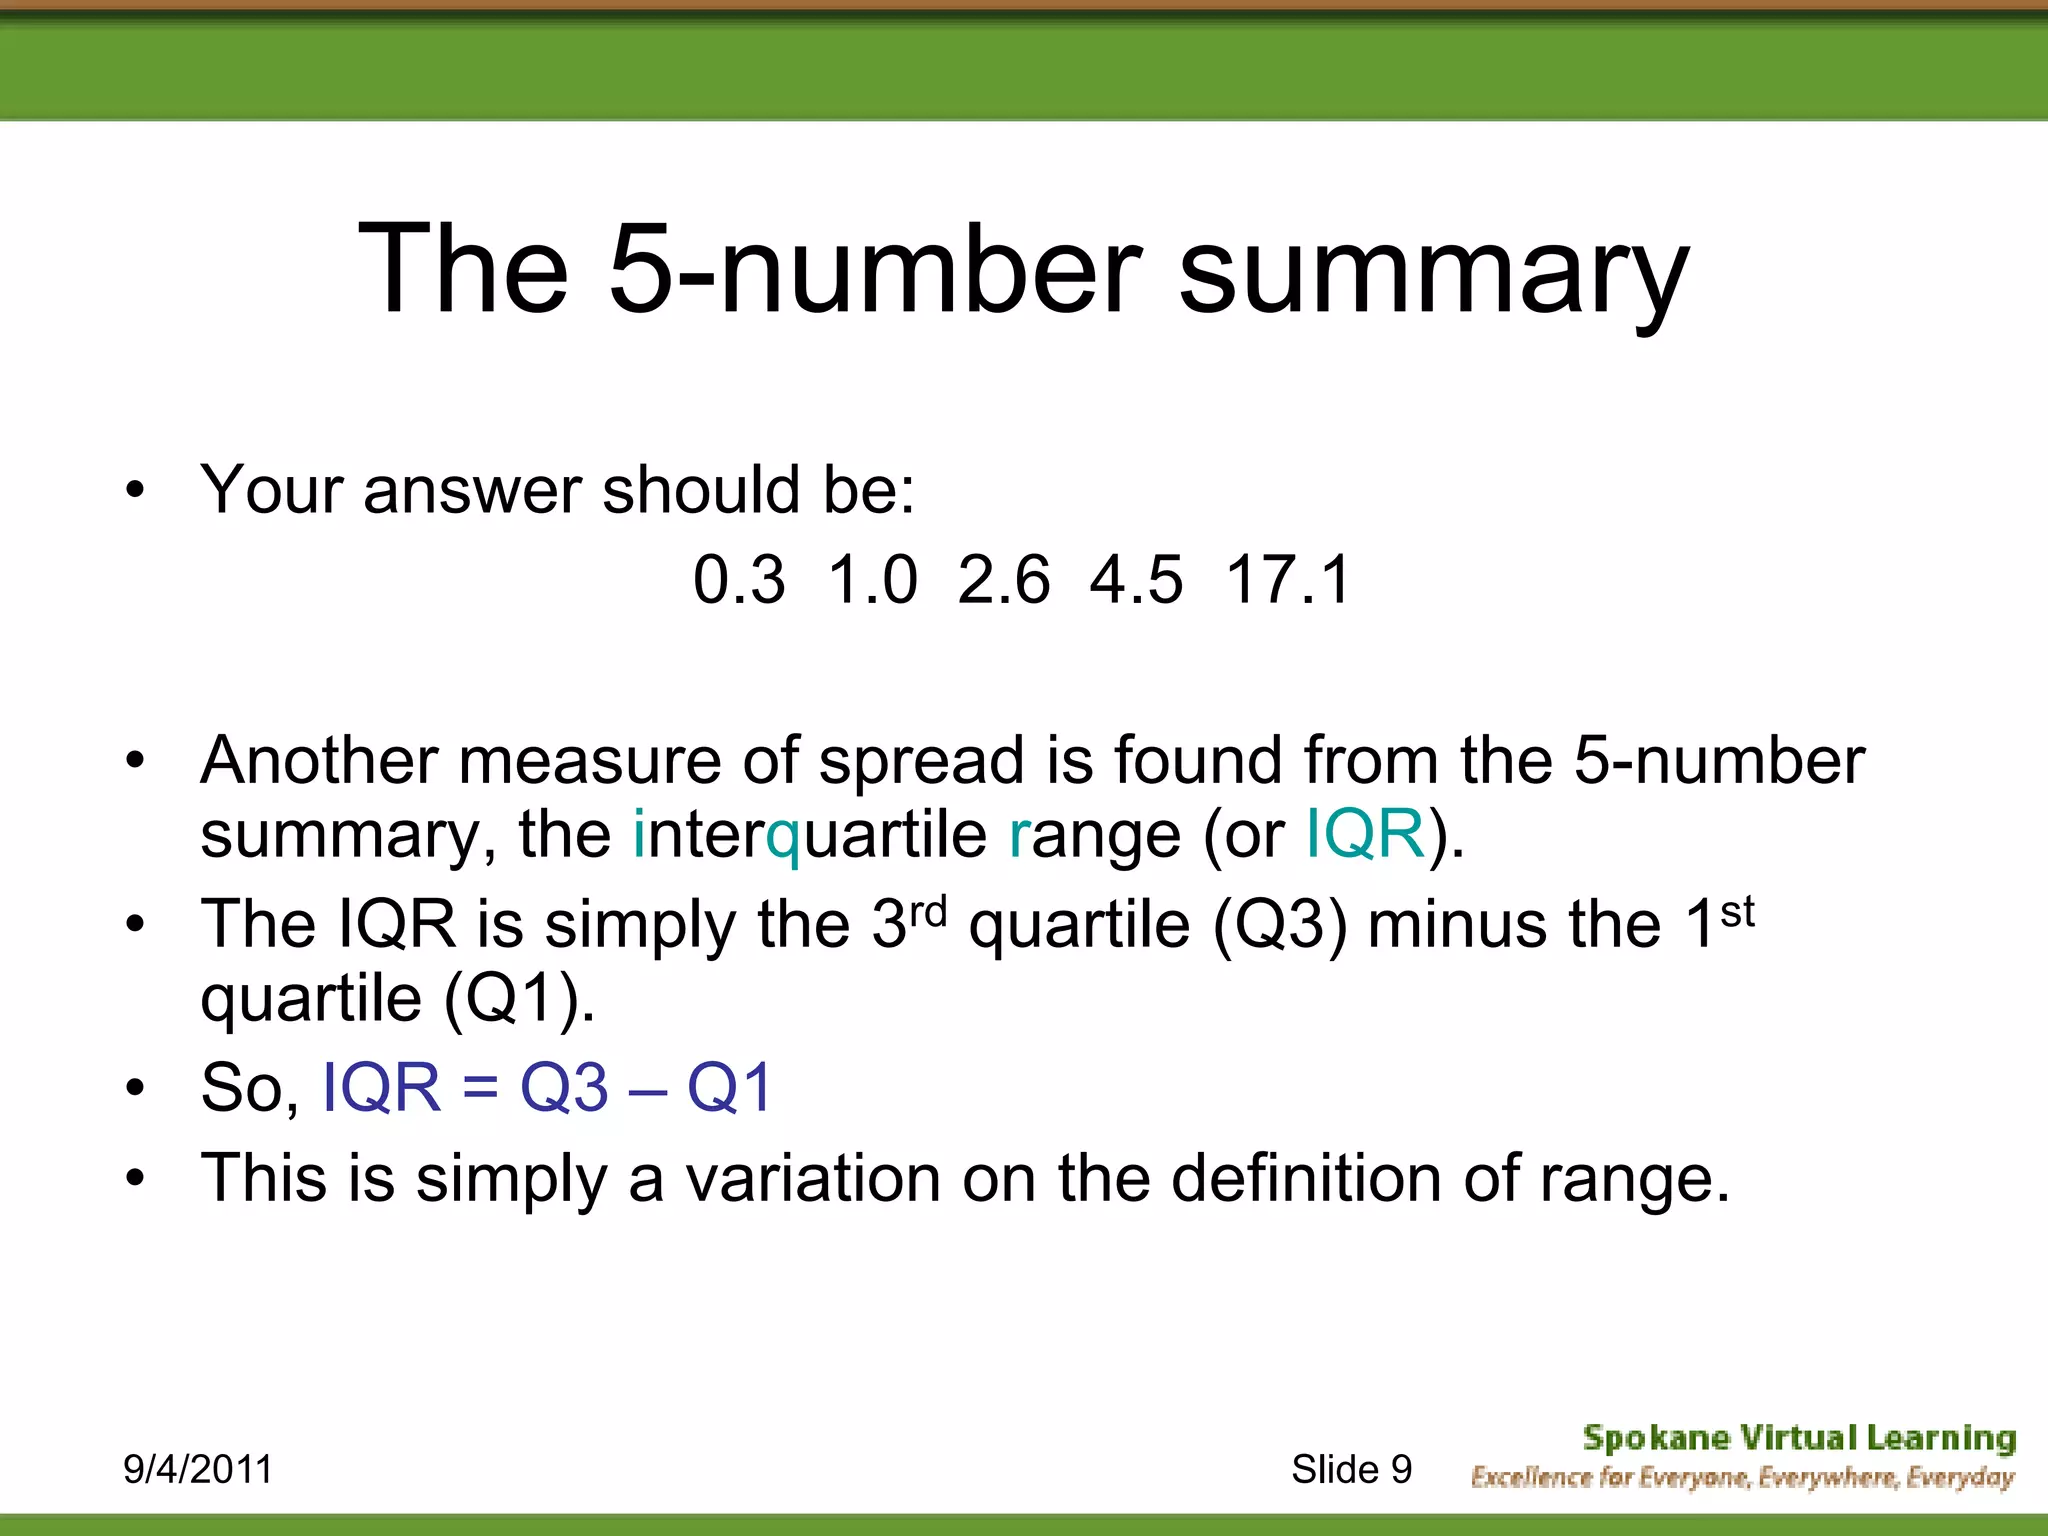
The five-number summary becomes genuinely useful when you need a fast sense of a distribution without running full parametric tests. It tells you the range, the center, and where the middle 50 percent sits. That last part is the interquartile range, or IQR, which is Q3 minus Q1. The IQR is how you identify outliers in a box plot. Any point below Q1 minus 1.5 times the IQR or above Q3 plus 1.5 times the IQR is flagged as a potential outlier. This is the standard fence calculation, not a suggestion. There are edge cases where the five-number summary completely falls apart. If your data is heavily skewed with a long tail on one side, the maximum or minimum can be so extreme that the box plot compresses the bulk of the data into an unreadable sliver. I had a dataset of server response times where most requests completed in under 200 milliseconds but a handful hung for 40 seconds. The box plot was basically a flat line with one whisker stretching across the entire chart. The five-number summary still reported correctly, but the visual representation became useless for communicating the actual distribution to stakeholders. Another limitation nobody mentions often enough is that the five-number summary discards information about the shape of the distribution between the quartiles. Two datasets can share identical five-number summaries but look completely different. One could be uniform, another could be bimodal, and the summary would not distinguish them. If you need to detect multimodality or other structural features, the five-number summary alone will not help you.
Get the Full Details

For most routine reporting, calculating a five-number summary takes about two minutes in any spreadsheet tool. The bottleneck is usually not the calculation itself but figuring out which quartile method your audience expects. I always note the method in the footnote of any table I publish. It prevents the kind of confusion I experienced with the survey data. A quick formula check in Excel: =MIN() for the minimum, =QUARTILE.INC() for Q1 and Q3 using the inclusive method, =MEDIAN() for the median, and =MAX() for the maximum. That covers the basics without overthinking it. Bottom line: the five-number summary is a quick descriptive tool, nothing more. It gives you a snapshot of where data lives and how spread out it is. It is not a substitute for understanding your data distribution, and it breaks down clearly when your data is extremely skewed or has structural features a box plot cannot capture. Use it when you need speed. Move past it when you need accuracy.