The shortcut nobody mentions until they need it
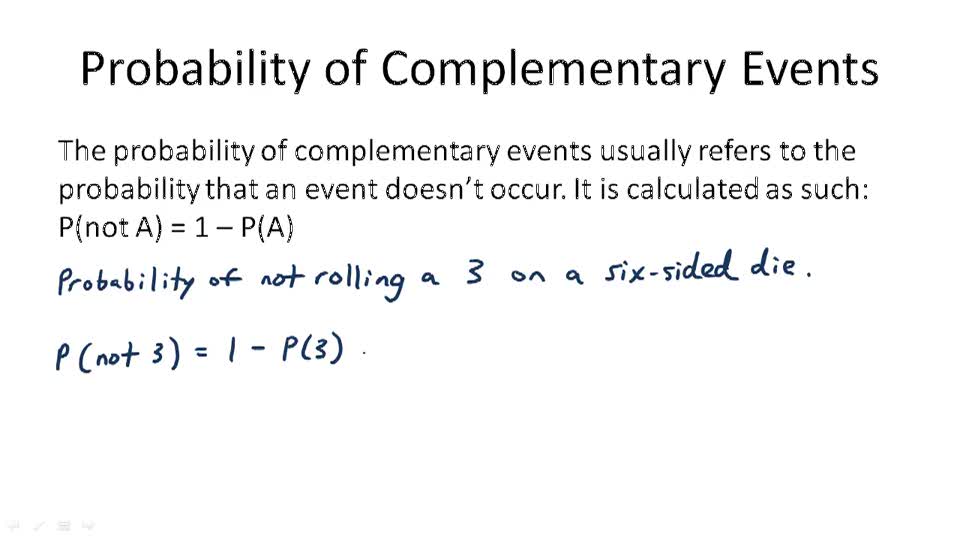
If you're calculating the probability of something happening and the direct approach requires adding together ten separate outcomes, stop and reconsider. Most people walk straight into that calculation. I've spent years watching engineers and analysts do exactly this, burning through time and introducing rounding errors when a single subtraction would have solved the problem in three seconds. The complement rule says what it says: P(not A) = 1 - P(A). The probability that an event does not occur equals one minus the probability that it does. It seems obvious until you're staring at a messy problem and don't see the opening.
What Is The Complement In Probability
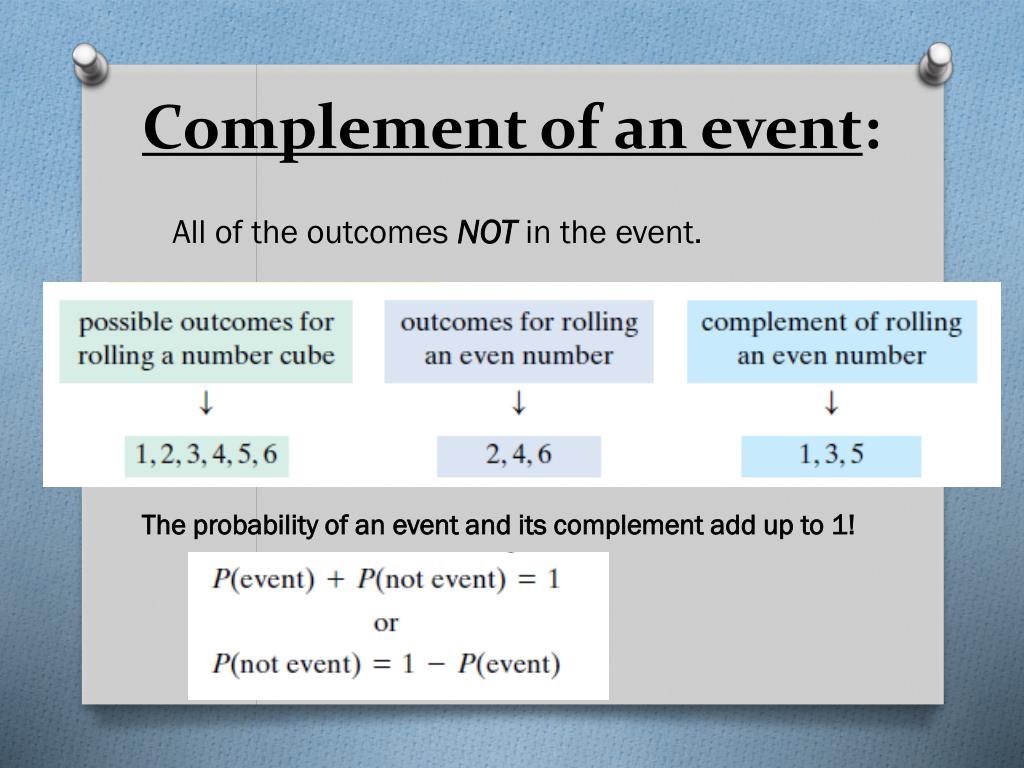
It's the mathematical way of saying: instead of counting every scenario where your event happens, count every scenario where it doesn't, subtract that from total certainty, and you're done. The complement of event A is everything in the sample space that isn't A. That's it. Nothing deeper than that. I ran into this exact situation working on a quality assurance project for semiconductor yields. We needed the probability that a wafer had at least one defect out of twenty-three possible defect sites. Calculating it directly meant accounting for one defect, two defects, three defects, all the way to twenty-three - each overlapping in ways that required inclusion-exclusion principles. The calculation would've taken hours and still might have been wrong. The workaround was to calculate the probability that the wafer had zero defects - which is a single, clean number - and subtract it from one. Took about forty-five seconds after I figured it out. The direct method probably would've taken me three to four hours.
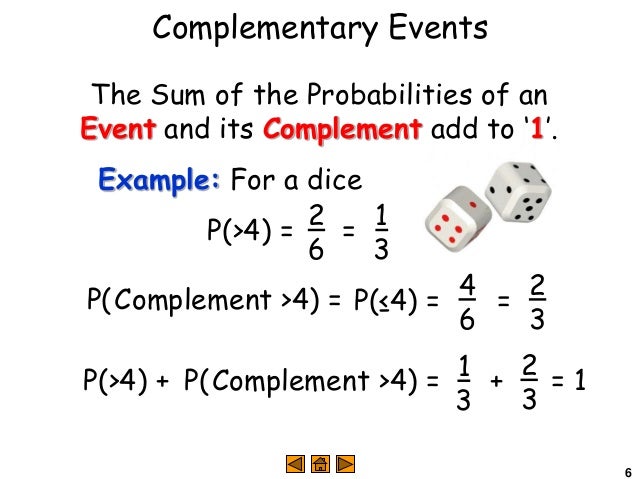
Here's a straightforward example. Suppose you roll a standard six-sided die and want the probability of rolling anything other than a four. The direct way: add up the probabilities of one, two, three, five, and six. Each is one-sixth, so five-sixths. The complement way: the probability of rolling a four is one-sixth, so the complement is one minus one-sixth, which is five-sixths. Same answer. The complement route is faster when the "other" category is smaller or when calculating P(A) directly is cumbersome. Consider drawing cards. What's the probability of getting at least one ace when you draw five cards from a standard deck? The direct calculation involves figuring out the probability of exactly one ace, exactly two aces, exactly three, and exactly four, then adding them together. That's four separate hypergeometric probability calculations. The complement: find the probability of getting zero aces in five draws, then subtract from one. Getting zero aces means all five cards come from the forty-eight non-aces. That's (48/52) times (47/51) times (46/50) times (45/49) times (44/48), which equals approximately 0.6588. So the probability of at least one ace is 1 minus 0.6588, or about 0.3412.
Get the Full Details

There are nuances that don't show up in textbook examples. The complement rule assumes you're working within a complete sample space where P(S) = 1. If your events aren't mutually exclusive or your sample space is incomplete, applying the complement blindly gives wrong answers. I've seen this trip up people building risk models where the event "system fails" doesn't capture all failure modes, leaving unaccounted probability mass outside their framework. Another thing: the complement rule works perfectly for single events, but combining complements across independent and dependent events requires care. If you're dealing with conditional probabilities, P(not A | B) is not simply 1 - P(A | B) in every context - actually, it is, but people sometimes miss that the conditioning event stays the same. The confusion usually comes from mixing P(not A | B) with P(not A and B), which are different things entirely. The method has clear limitations. It only helps when computing the complement is meaningfully easier than computing the original event. If P(A) and P(not A) are equally complex to calculate, using the complement buys you nothing. I've seen people force the complement rule on problems where the complement was actually harder, which just added an unnecessary step.
It also doesn't help with continuous distributions in the same straightforward way. For a continuous random variable, P(X = c) is zero, so the complement of X equaling some specific value is trivially one. The real question is always about intervals, and the complement of X being in some range is straightforward, but numerical integration or approximation methods may still be necessary either way. In practice, I use a quick heuristic: if "at least one" appears in the problem statement, the complement rule is almost always the right move. "At least one success," "at least one defect," "at least one occurrence" - these are all classic complement setups. Conversely, if you're asked for the probability of exactly k occurrences or for overlapping unions of events, the complement might not be the optimal path. The rule itself is mathematically airtight. It follows directly from the axioms of probability. The complement of A and A together cover the entire sample space and cannot overlap, so their probabilities sum to one. Every application is just exploiting that fact strategically.
I don't recommend trying to memorize edge cases for when the complement won't work. Just internalize the rule, recognize the "at least one" pattern, and verify that your sample space is properly defined before you start subtracting. That covers the vast majority of real-world situations where this comes up.