Getting Past The Mean When Your Data Won't Behave
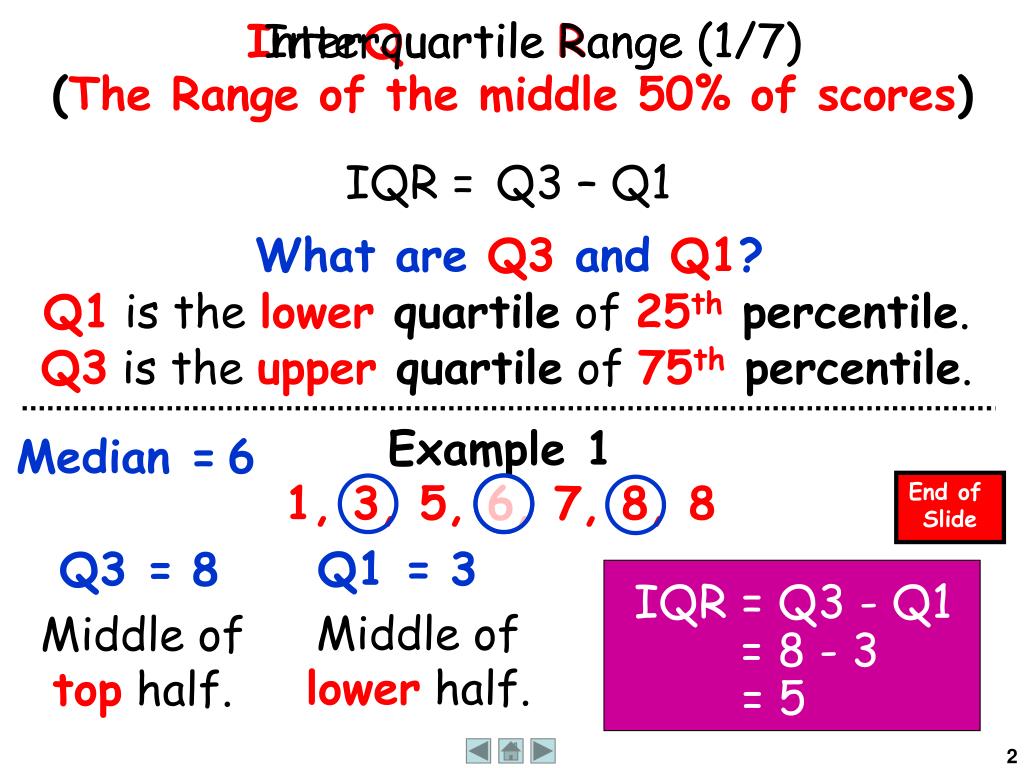
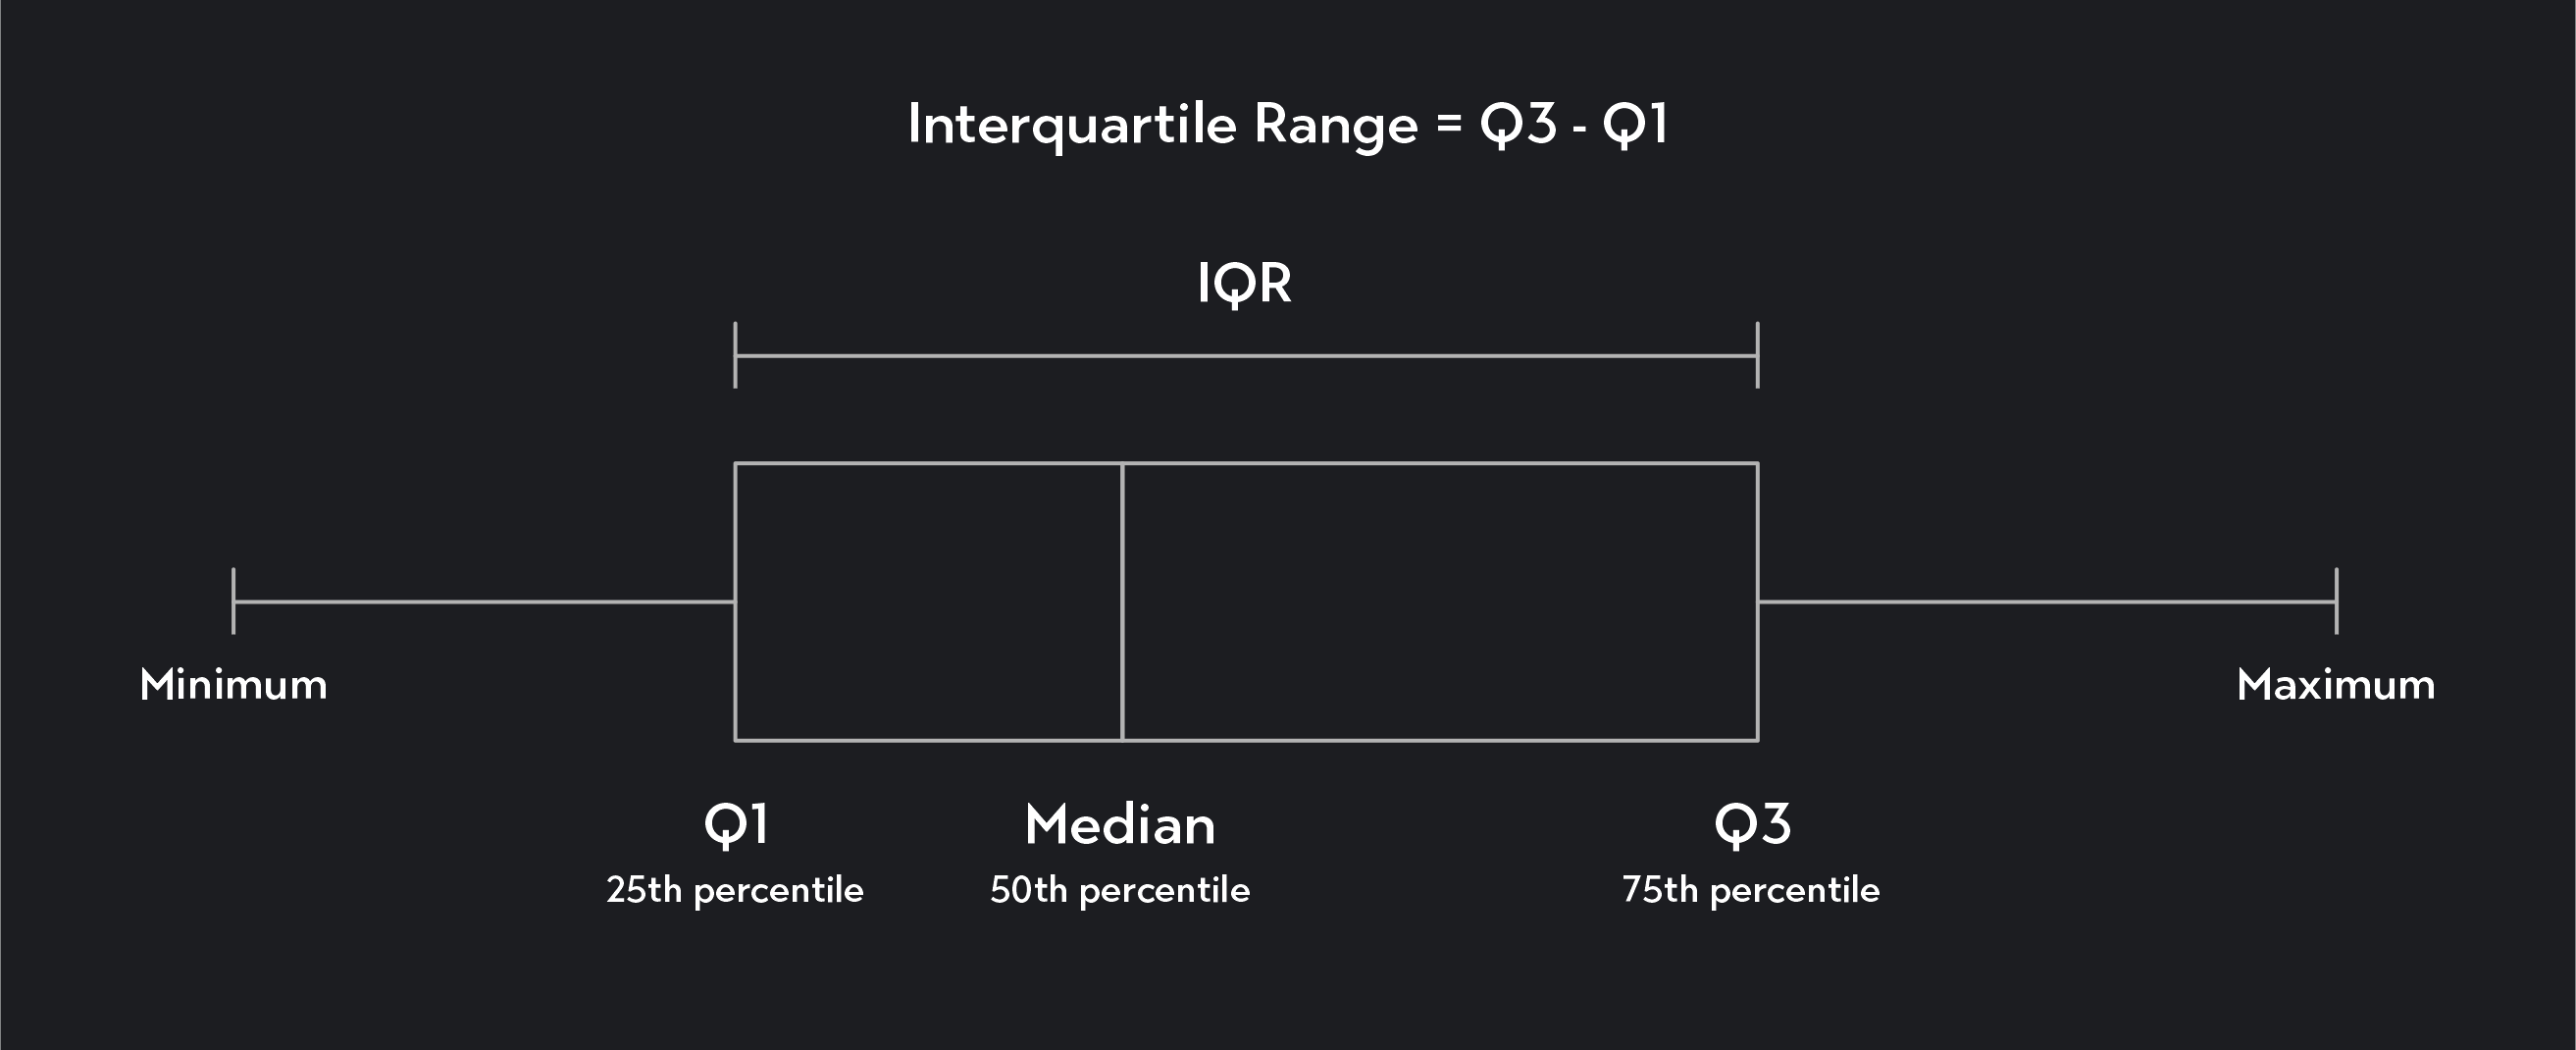
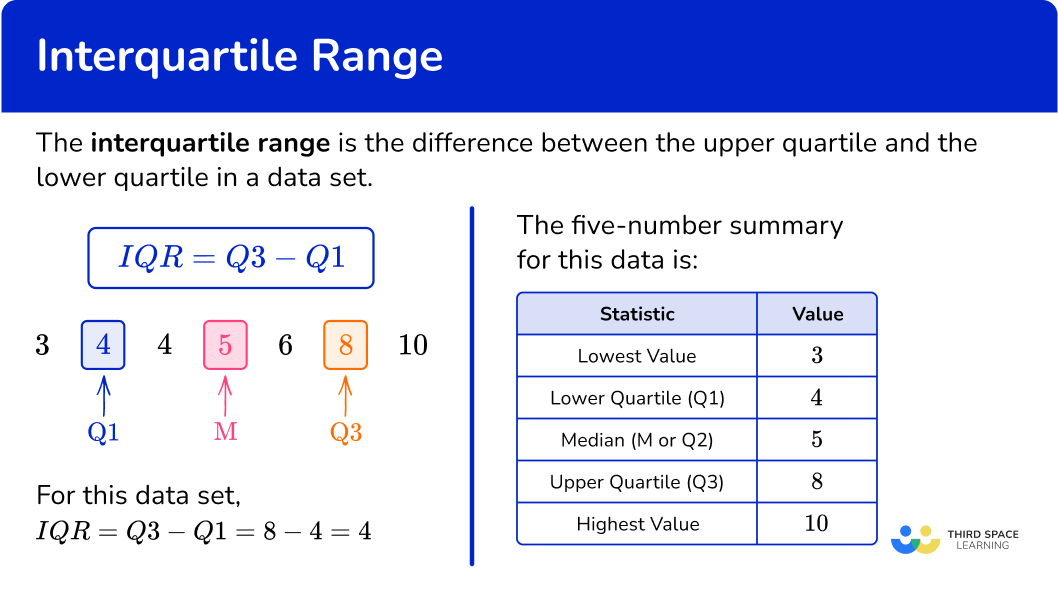
I spent three years working in quality control for a manufacturing plant where our measurements were never clean. We had outliers everywhere—machine malfunctions, thermal drift, one time a whole batch got recorded in inches instead of millimeters. The mean kept lying to us. That's when the interquartile range stopped being some statistics lecture concept and became something we actually relied on every shift. The interquartile range is the spread of the middle fifty percent of your data. You take the third quartile minus the first quartile and you get a number that tells you how tightly clustered your central observations are, completely ignoring whatever extreme garbage sits at the tails. It's denoted as IQR or sometimes Q3 minus Q1. That's it. No poetry required. Here's the actual process, not the textbook version. First, sort your dataset from smallest to largest. Then find the median—that's your second quartile, Q2. If your dataset has an odd number of values, the median sits on one of the actual data points and you split the remaining values into a lower half and an upper half, leaving out the median itself from both halves. This trips people up constantly. If you have seven values, the median is the fourth one. The lower half is the first three. The upper half is the last three. Don't include the median in either half when you compute Q1 and Q3.
Q1 is the median of the lower half. Q3 is the median of the upper half. The IQR is Q3 minus Q1. When you have an even number of values in a half-set, you average the two middle numbers to get the quartile. That's the whole procedure. Let me walk through a real example. Say your dataset is: 4, 7, 9, 12, 15, 18, 22, 25, 31. Nine values. The median is 15. Lower half: 4, 7, 9, 12. Upper half: 18, 22, 25, 31. Q1 is the median of 4, 7, 9, 12, which is (7 + 9) divided by 2, so 8. Q3 is the median of 18, 22, 25, 31, which is (22 + 25) divided by 2, so 23.5. The IQR is 23.5 minus 8, which equals 15.5. Now here's where things get tricky in practice. There are multiple methods for computing quartiles and different software packages implement them differently. Excel's QUARTILE.EXC and QUARTILE.INC give you different answers. R has nine different methods built into its quantile function. Python's numpy and pandas can diverge from both. I once spent four hours tracking down why our QA team's IQR calculations didn't match the engineering team's. They were using different quartile interpolation methods on the same dataset. The difference was small—about 0.3 on an IQR of 14—but in our world that 0.3 translated to accepting parts that should have been rejected.
The workaround was simple but expensive in terms of lost time. We documented exactly which method we were using and locked it in. I recommend using the inclusive method (Excel's QUARTILE.INC or R's default type 7) and explicitly stating it in any report. Don't leave it ambiguous. Your audience will assume you used the same method they did, and they won't be right.
Get the Full Details
Why The IQR Actually Matters Beyond Homework
The mean is sensitive to every single value in your dataset. One outlier can pull it dramatically. The IQR doesn't care about outliers at all. It only looks at the middle bulk of your data. That's its main advantage and it's not a minor one. In the manufacturing setting I mentioned, our dimension measurements would occasionally spike to three times the normal value because a tool broke mid-run. The mean would jump up noticeably. The IQR stayed completely flat because those bad readings were in the tails, outside the 25th to 75th percentile band. This leads directly to the most common practical use: outlier detection. The standard fence method multiplies the IQR by 1.5 and marks anything below Q1 minus 1.5 times the IQR or above Q3 plus 1.5 times the IQR as a mild outlier. Anything beyond 3 times the IQR is a extreme outlier. I say "standard" because this isn't a law of physics. It's a convention Tukey came up with, and it works well enough for most real-world datasets. Sometimes 1.5 is too aggressive for your particular data. If your distribution is inherently wide, you might need a different multiplier. There's no universal rule here. Another thing beginners miss: the IQR doesn't tell you anything about symmetry. Two datasets can have identical IQRs and completely different shapes. One could be symmetric around its median while the other is heavily skewed, with the same middle fifty spread. Always look at the position of Q1 and Q3 relative to the median. If the median is closer to Q1, your data is right-skewed. If it's closer to Q3, it's left-skewed. The IQR alone hides that information.
There's also a limitation worth being honest about. The IQR is based on quartiles, which means it only uses the middle 50 percent of your data. That's both its strength and its weakness. If your dataset is small—say fewer than twenty values—the quartiles become unstable. A single value shift can move Q1 or Q3 significantly, which means your IQR fluctuates a lot. With small samples, the IQR is a rough estimate at best. In those cases, consider using the range or a bootstrapped confidence interval instead, or just acknowledge the uncertainty explicitly rather than presenting the IQR as if it's precise. I've also seen people try to use the IQR on purely categorical data or on ordinal data where the distances between ranks aren't meaningful. That doesn't work. The IQR requires at least interval-level measurement. If you're dealing with rankings like "first place, second place, third place" without any underlying numerical scale, the IQR is meaningless. This sounds obvious but I've seen it in published papers. The computational side is straightforward. For a dataset of n values, sorting takes O(n log n) time. Finding the median and quartiles after sorting is essentially linear. So the whole process is dominated by the sort. On modern hardware with any reasonable dataset size, this is effectively instant. The bottleneck is almost always data cleaning, not the IQR calculation itself.