Understanding Mean Average Deviation in Practice
When you're dealing with quality control data or production metrics, you'll run into mean average deviation pretty quickly. It's one of those statistics that sounds more complicated than it actually is, but people tend to overcomplicate it because they've been taught to think about standard deviation first. Let me walk you through how it works when you're not doing it by hand for a classroom assignment. Mean average deviation, sometimes called mean absolute deviation, measures how spread out your data points are from the average. The calculation is straightforward: you find the mean of your dataset, then calculate the absolute difference between each data point and that mean, and finally average those differences. That's it. No squaring, no square roots, no fancy math that requires a calculator app.
What Is The Mean Average Deviation
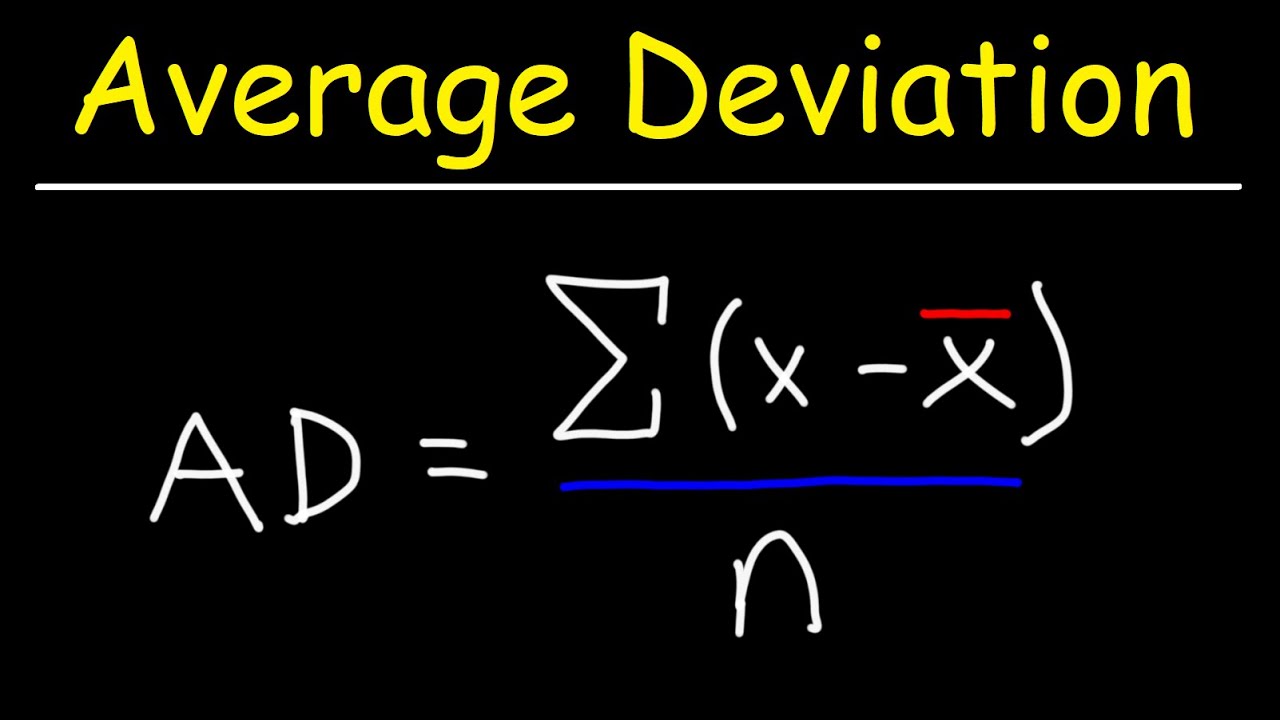
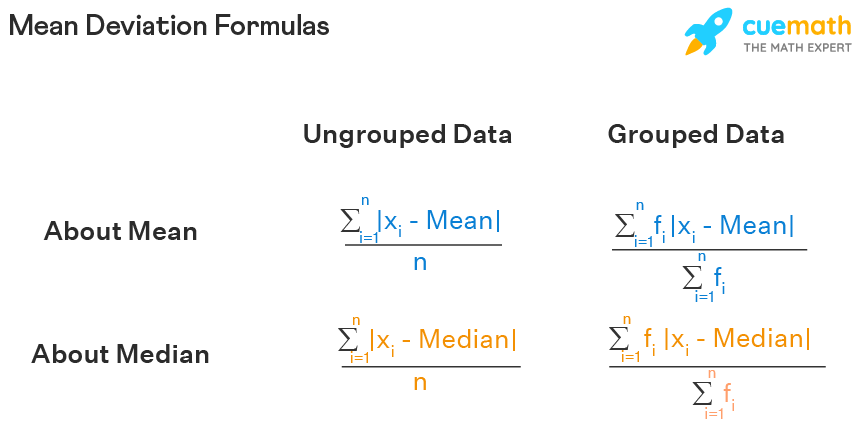
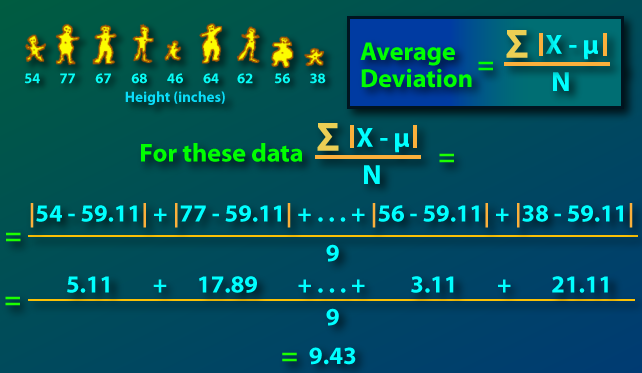
Here's the formula, presented plainly: MAD = (1/n) * |xi - x|. You sum up all the absolute deviations and divide by your sample size. Simple enough. I remember the first time I had to explain this concept to a manufacturing team that was used to looking at standard deviation. They kept asking why the numbers didn't match what they expected. The issue was that standard deviation weights larger deviations more heavily because of the squaring step. Mean average deviation treats every deviation equally, which actually makes more intuitive sense for certain types of analysis. Let me give you a concrete example. Say you have these five measurements from a production line: 10, 12, 14, 16, 18. The mean is 14. The absolute deviations from the mean are 4, 2, 0, 2, 4. Add those up and you get 12. Divide by 5 and your mean average deviation is 2.4. That means, on average, each measurement deviates from the mean by about 2.4 units.
There's a practical reason this matters. When I was working with a supply chain team, we needed to understand variability in delivery times. Standard deviation gave us a number, but it didn't translate well to the people making operational decisions. Mean average deviation of 1.3 days meant something concrete: deliveries typically arrive about a day and a bit off schedule. That's easier to act on than a standard deviation of 1.7 days, which feels abstract to someone who just wants to know when their shipment is coming. One thing most guides don't mention is that mean average deviation is more sensitive to small outliers than people realize. Because you're using absolute values rather than squared values, a single extreme data point doesn't get the dramatic amplification it gets in standard deviation calculations. This can be an advantage or a disadvantage depending on what you're measuring. I ran into a specific problem last year with a dataset where about 5% of the readings were way off due to sensor errors. Standard deviation jumped to alarming levels, making it look like the process was completely unstable. Mean average deviation stayed relatively grounded because those extreme values didn't get squared. I ended up using both metrics together — mean average deviation for the general picture and standard deviation to flag when something was truly out of bounds. This combined approach gave stakeholders both the day-to-day picture and the early warning system they needed.
Get the Full Details

The calculation itself can be done in several ways depending on your tools. Excel has no built-in function for MAD, which is surprising given how useful it is. You'd use something like =AVERAGE(ABS(A1:A10-AVERAGE(A1:A10))) as an array formula. Google Sheets works the same way. For Python users, you can calculate it with numpy or scipy, or just use the statistics module in Python 3.4 and later, though you'll need to install the statistics module separately since it's not always available in minimal installs. If you're working in R, the mad function is built in and handles median absolute deviation by default, which is slightly different. You can calculate mean average deviation with a simple custom function or use the DescTools package which has a MADE function. SPSS users will need to go through the descriptive statistics menu and request mean absolute deviation through the explore function. It's not the most obvious path in SPSS, but it's there once you know where to look.
For those doing this manually or teaching the concept, here's a practical step-by-step that I've used with students and colleagues alike:
- Calculate the arithmetic mean of your dataset
- Find the deviation of each data point from that mean
- Take the absolute value of each deviation
- Add up all the absolute deviations
- Divide by the number of data points
There are some common mistakes people make that I see all the time. First, forgetting to take the absolute value before averaging. If you skip that step, positive and negative deviations cancel each other out and you get zero every single time, which is mathematically correct but completely useless. Second, confusing mean average deviation with median absolute deviation. They're related but different, and mixing them up will give you the wrong answer. Another pitfall is using mean average deviation when your data has a very non-normal distribution. In those cases, the mean itself might not be the best measure of center, and using it as your reference point for deviation calculations can give misleading results. I learned this the hard way when analyzing wait time data that had a long right tail. The mean was pulled upward significantly, and the mean average deviation came out much larger than what people experienced most of the time. Switching to median-based deviation gave a more accurate picture of typical variability. Mean average deviation also has limitations that people should know about before relying on it. It's not as mathematically tractable as standard deviation, which is why it got pushed aside in many statistics courses. If you're doing advanced statistical modeling or hypothesis testing, standard deviation and variance are generally preferred because they play nicely with the mathematics involved. Mean average deviation is mostly useful for descriptive analysis and when you need an intuitive measure of spread.
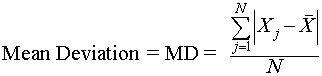
One counter-intuitive insight: mean average deviation is always less than or equal to standard deviation for the same dataset. This isn't something most people realize, but it follows directly from the fact that squaring larger numbers amplifies them more than taking absolute values does. So if someone tells you their MAD is larger than their standard deviation, you should double-check their calculations. Another thing worth noting is how mean average deviation scales with your data. If you multiply all your values by a constant, the MAD gets multiplied by that same constant. This property makes it useful for comparing variability across different scales, though standard deviation has the same property, so this doesn't give MAD any particular advantage here. For practical purposes, if you need a downloadable resource or calculator, there are several options. Excel templates are widely available online. Some statistical software packages include MAD in their output by default. Online calculators exist but many of them only do standard deviation. I recommend building your own simple spreadsheet with the formula I mentioned above — it takes about five minutes and gives you full control over your calculations without depending on third-party tools that might change or disappear.
When presenting mean average deviation to others, always clarify what it represents in the context of your specific data. A MAD of 5 means something completely different depending on whether your values range from 1 to 10 or from 100 to 200. Expressing it as a percentage of the mean, sometimes called the coefficient of mean deviation, can help with communication, though this also has its own complications if your mean is near zero. The bottom line is that mean average deviation is a legitimate and useful statistical measure that deserves more attention than it gets. It's easier to understand than standard deviation, more intuitive for non-technical audiences, and perfectly adequate for most practical applications where you just need to understand how much your data varies. Don't let the fact that it's less commonly taught make you second-guess using it when it's the right tool for the job. If you're working with data that has meaningful outliers or when your audience needs to understand variability without getting into statistical theory, mean average deviation is often the better choice. It's the metric I reach for when I want people to actually grasp what the numbers mean rather than just citing a statistic and moving on.