The Scientific Method Before the Textbooks Got to It
I spent about three years trying to model enzyme kinetics in a university lab, and the first thing I learned was that nobody actually works the way the flowchart on the wall says. You formulate a hypothesis, yes, but then your spectrophotometer drifts, your reagents degrade between batches, and you end up iterating on the experimental design itself more than the theory. The model isn't some clean sequence. It's a set of practices for reducing uncertainty, and the scientific model is really just a loose framework for doing that repeatedly. People conflate the scientific model with the scientific method, which is a separate thing. The model is the structured representation. The method is the process. In practice, a model in science usually means something computable or visualizable that maps inputs to outputs. A regression equation. A differential equation describing population decay. A finite element mesh predicting stress distribution in a titanium implant. None of those are the method. They're the artifacts of it.
What Is The Scientific Model
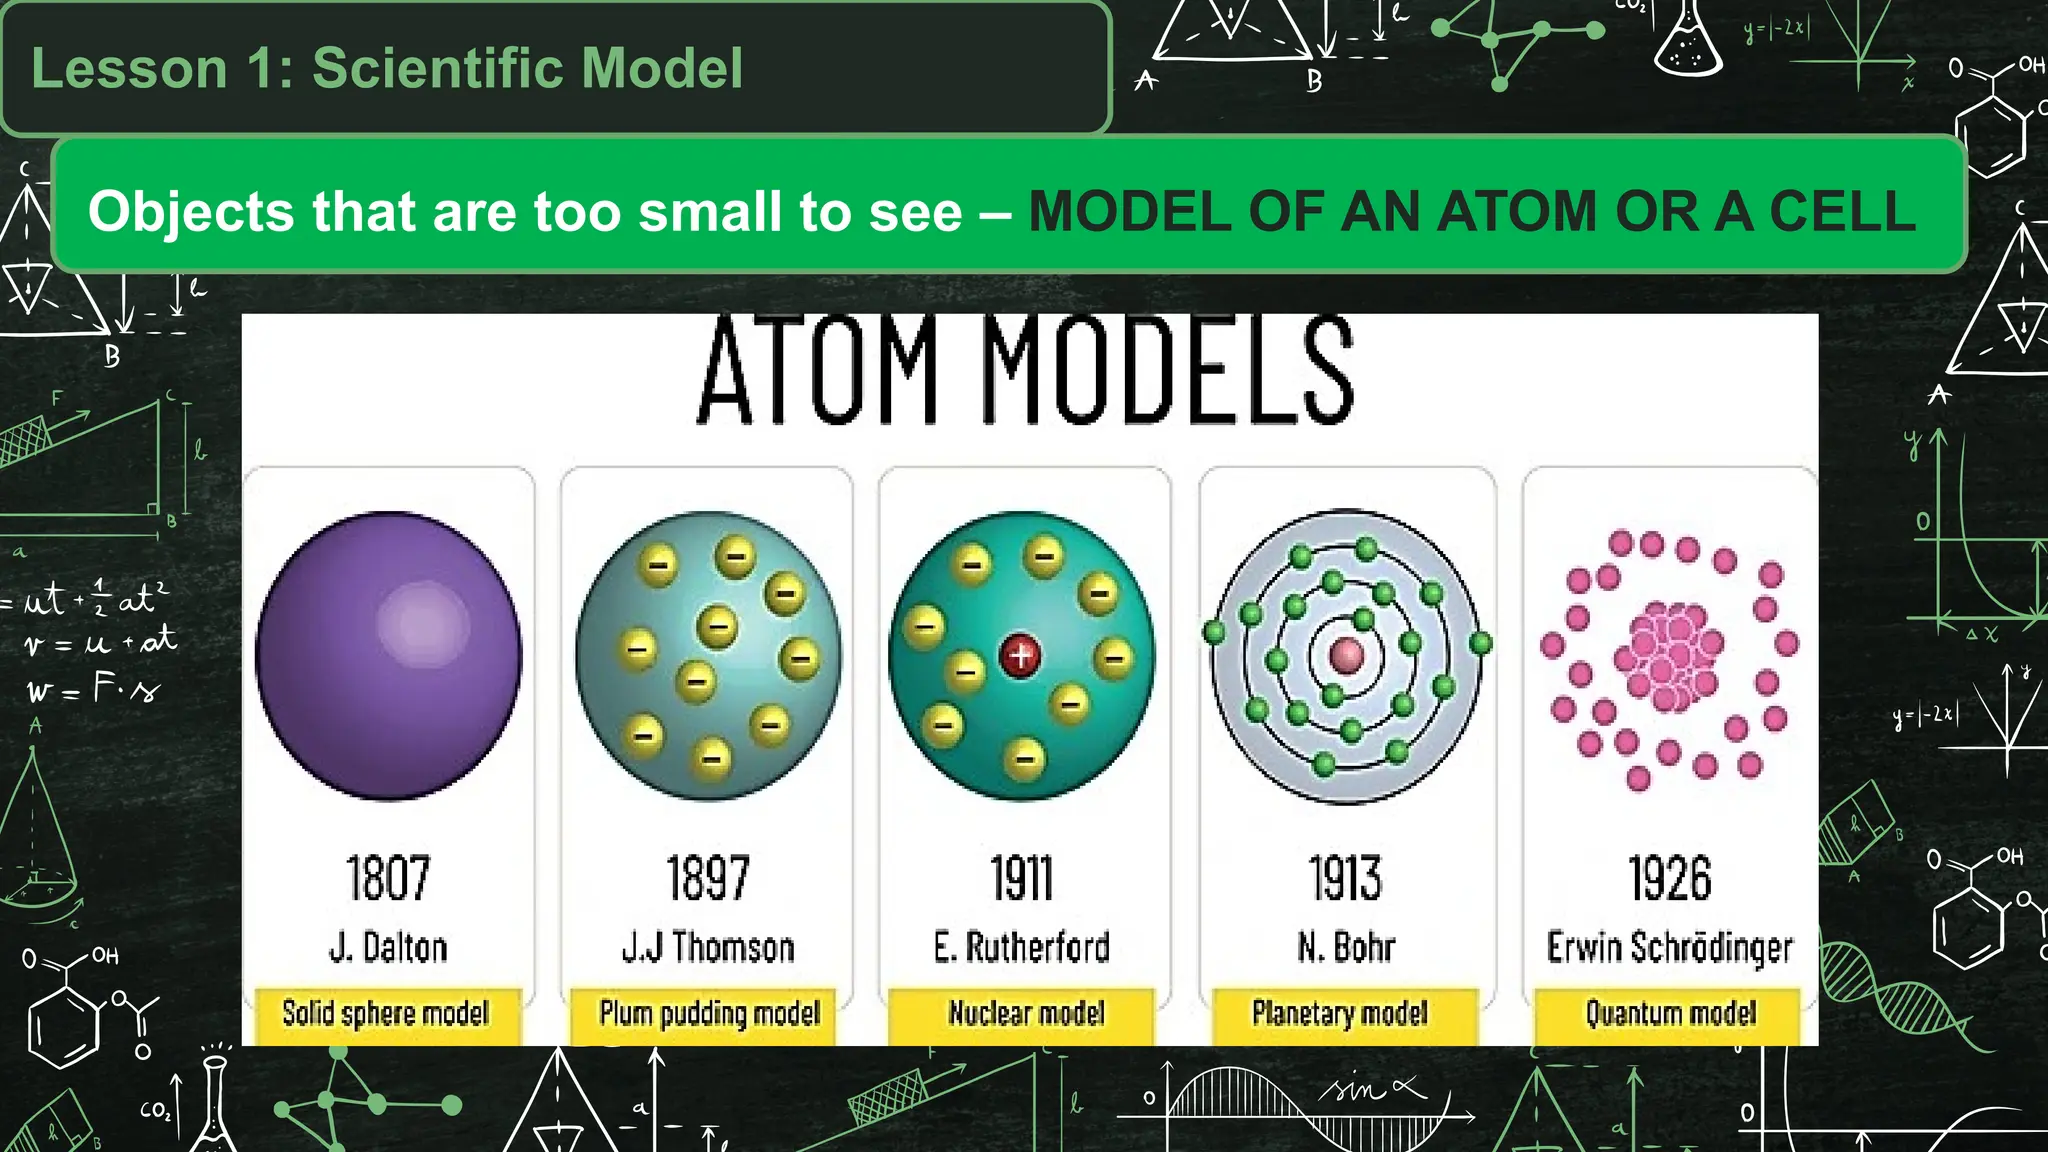
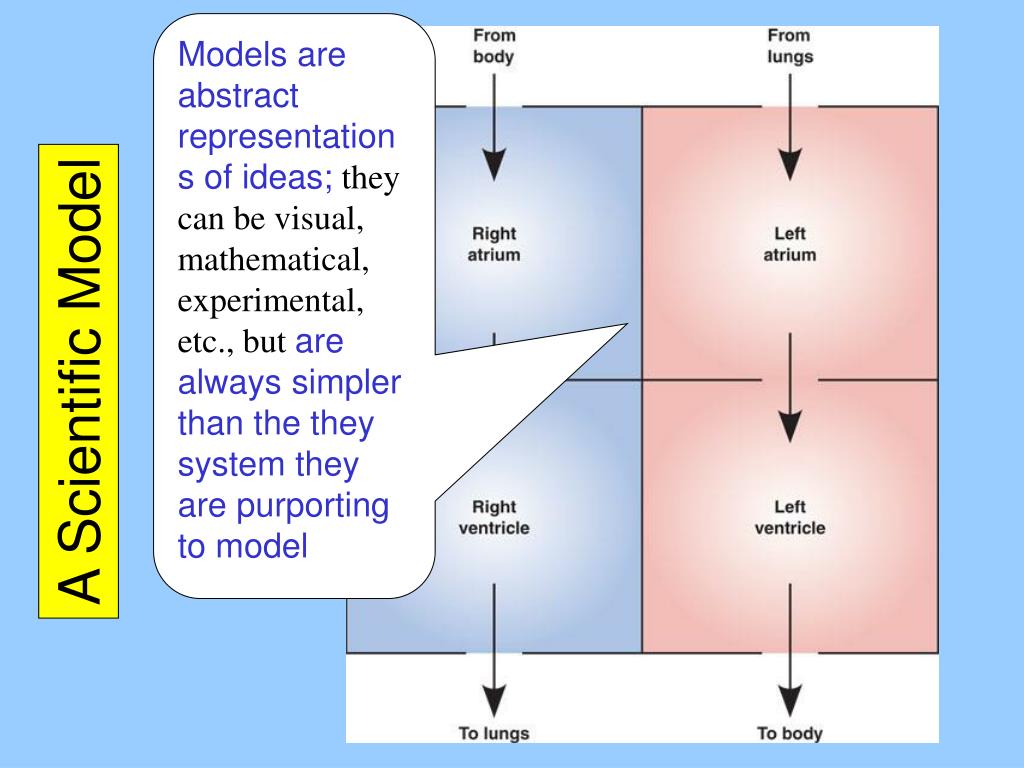
A scientific model is an abstraction that captures selected features of a phenomenon while deliberately ignoring others. That selection process is where most of the work happens. When I built my first kinetic model for that enzyme project, I assumed Michaelis-Menten behavior because the literature suggested it. I spent weeks fitting data to the standard hyperbolic curve before I realized the enzyme was exhibiting cooperative binding. The model wasn't wrong. I was just applying the wrong abstraction. Switching to the Hill equation changed everything, and the residuals dropped from ±18% to about ±3%. That's the kind of thing textbooks don't mention because it sounds like failure when it's really just iteration. Models exist on a spectrum from conceptual to mathematical to computational. A conceptual model might be a diagram showing how carbon moves through atmosphere, ocean, and biosphere. A mathematical model would be a system of differential equations quantifying those fluxes. A computational model would be code running those equations across spatial grids and time steps. Most real research uses all three simultaneously, moving between them as needed. You sketch the concept, formalize it mathematically, then implement it computationally and compare predictions against data. The model that survives gets used. The others get revised or discarded. The counter-intuitive part most beginners miss is that model quality doesn't correlate with complexity. A simple exponential decay model often outperforms a complicated mechanistic model when data is noisy, because the extra parameters just fit the noise. This is the bias-variance tradeoff, and it applies everywhere from pharmacokinetics to climate modeling. I've seen PhD students spend months building elaborate models that couldn't reproduce their own control experiments, while a five-line linear regression did the job and was actually useful. Parsimony isn't laziness. It's a constraint that forces you to identify what actually matters.
Another thing that isn't obvious: models are almost never validated in the way people think. Validation usually means comparing model output against independent data, but independent data in science is rare. More often you get verification, which checks that the model implements the equations correctly, and calibration, which adjusts parameters to fit available data. True validation requires data the model hasn't seen, collected under conditions different from what was used to build it. Most published models stop at calibration. That doesn't make them useless. It just means their predictive scope is limited to conditions similar to what was observed. Here's a practical detail that trips people up. When building a model, decide what you're trying to predict before you decide how detailed it should be. If your goal is to forecast reaction rates under slightly different temperatures, an Arrhenius-type model with two parameters might be sufficient. If your goal is to understand the catalytic mechanism at the molecular level, you need something more mechanistic, possibly quantum mechanical. The same phenomenon, different models, different purposes. Confusing the two leads to overfitting or under-specifying depending on which direction you err. I encountered a specific edge case during that enzyme project that illustrates this well. My data showed apparent substrate inhibition at high concentrations, which the standard model couldn't explain. The obvious fix would have been to add an inhibition term and call it done. Instead, I checked whether the inhibitor was actually the product accumulating over time. It was. The model wasn't wrong about the kinetics. The experimental setup was creating a secondary reaction that the model didn't account for. Adding a product inhibition term fixed the fit, but the better model would have separated the two reactions entirely. I ended up doing both: a simple empirical model for prediction and a more mechanistic one for understanding. Different tools for different questions.
Get the Full Details
Building Models That Actually Work
The workflow I settled on, and I've seen it work repeatedly in adjacent fields, starts with defining the prediction task precisely. What variable do you need? Over what range? With what acceptable error? This sounds trivial until you realize most model failures come from ambiguous goals. A modeler might optimize for R-squared while the application actually needs accurate prediction at the tails of the distribution. High overall fit doesn't guarantee useful predictions everywhere. After defining the task, you select a model class based on domain knowledge, not convenience. Structural equation models for correlated latent variables. State-space models for time series with observation error. Agent-based models when emergence matters. Choosing based on what software is easiest to use is how you get models that fit but don't generalize. I've reviewed papers where the authors used neural networks for small datasets with clear mechanistic structure, and the results were worse than a linear model because the network memorized rather than learned. Parameter estimation is where most practical problems occur. Maximum likelihood works when assumptions hold. Bayesian methods handle uncertainty better but require priors, and bad priors dominate weak data. I prefer Bayesian estimation for small datasets because it forces you to be explicit about assumptions, but it also makes it easy to hide mistakes in prior specification. Always check sensitivity to priors. Run the analysis with several reasonable prior distributions and see if conclusions change. If they do, you don't have enough data to answer the question yet, and that's useful information in itself.
Cross-validation is standard practice but often misapplied. K-fold cross-validation assumes data points are independent. They rarely are in scientific data. Time series have autocorrelation. Spatial data has clustering. Biological replicates share genetic background. Ignoring these dependencies inflates performance estimates. I use blocked or grouped cross-validation where possible, splitting on experimental batches or subjects rather than individual observations. It gives more realistic estimates and usually lower ones, which is exactly what you want when you're about to claim a model is good. Model comparison is another area with subtleties. Akaike Information Criterion and Bayesian Information Criterion serve different purposes. AIC estimates predictive accuracy and favors slightly more complex models. BIC favors simpler models and is consistent in selecting the true model given enough data. Use AIC when prediction is the goal. Use BIC when identifying the underlying mechanism matters more. Neither is universally correct. They encode different assumptions about what you're optimizing for. Here's something I wish I'd understood earlier. A model is never complete. It always has blind spots. The question isn't whether the model is right but whether it's wrong in ways that matter for your application. If you're predicting drug dosing and the model underestimates peak concentration by 10%, that might be clinically irrelevant. If you're predicting dose for a narrow therapeutic index drug, that 10% could be dangerous. Context determines what errors matter. Always specify error tolerance before building the model, and evaluate against that tolerance rather than abstract goodness-of-fit metrics.
Computational models introduce additional considerations. Numerical integration schemes have stability constraints. Explicit methods are simple but require small time steps. Implicit methods allow larger steps but need matrix inversion at each step. For stiff systems, which are common in chemistry and biology, implicit or semistrict methods are necessary. I've wasted hours debugging models that were actually working fine numerically but hit stability issues I didn't recognize because I was using an explicit solver for a stiff system. Switching to a variable-step implicit method like CVODE or the BDF family resolved it immediately. Uncertainty quantification is often neglected but critical. Point estimates from models are misleading without confidence intervals or credible intervals. Parameters are uncertain. Initial conditions are uncertain. Structural assumptions are uncertain. Propagating all of these gives you a fuller picture than any single prediction. I use Monte Carlo sampling through the model with parameter distributions from the estimation step. It's computationally expensive but straightforward to implement, and it reveals things like parameter correlations that point estimates hide. Sometimes two parameters are nearly perfectly correlated, meaning you can't identify them individually even though their combination is well-constrained. That's valuable information for experimental design. The limitations of scientific models are worth stating bluntly. They simplify reality, sometimes drastically. They depend on data quality, and garbage in remains garbage out regardless of how sophisticated the model is. They can't predict black swan events because those aren't in the training distribution. They're only as good as the assumptions they encode, and hidden assumptions are the most dangerous kind. I've seen models fail spectacularly when applied outside their validation domain, producing confident but wrong predictions. This happens in epidemiology, climate science, and economics equally. The models weren't wrong in their original domain. They were just being used where they hadn't been validated.
When models fail, the failure itself is informative. A poor fit tells you something about the system you didn't know. The trick is distinguishing between model failure and implementation failure. Before revising the model structure, verify that the code implements what you think it implements. I've caught errors by adding synthetic data with known properties and checking that the model recovered them correctly. If it didn't, the bug was in the implementation, not the theory. This simple check saves enormous debugging time. Documentation matters more than most researchers admit. A model without clear assumptions, scope, and limitations is just someone's opinion in equations. I keep a model specification document alongside every project: what the model represents, what it omits, what data it was calibrated against, what predictions it has validated, and what it shouldn't be used for. This document evolves with the model. Six months after finishing a project, I can look at it and immediately understand what I was trying to do and why certain choices were made. Models are hard enough to build without adding amnesia to the difficulties. For practical implementation, I recommend starting simple and adding complexity only when justified by improved predictive performance. A one-parameter model that predicts within tolerance is better than a ten-parameter model that fits training data perfectly but fails on new observations. The improvement from each added parameter should exceed the cost in degrees of freedom. If you can't articulate why a parameter is needed, it probably isn't. This principle extends beyond statistical models to conceptual frameworks and computational simulations.
Peer review of models is underdeveloped compared to peer review of papers. Journals publish results but rarely the models themselves. Reproducibility suffers because readers can't examine model structure, only summary statistics. I make a habit of publishing model code alongside papers when possible, or at minimum providing enough detail that another group could implement the same model. The scientific model isn't valuable because it's authoritative. It's valuable because it's testable and improvable. Keeping it accessible serves both purposes. There's no single correct scientific model for any phenomenon. There are only models that are useful for specific purposes under specific conditions. The art is in matching model to question, knowing when a model has served its purpose, and having the humility to replace it when it doesn't. That's what the process actually looks like, separate from the sanitized version you see in methodology chapters.