The Basics Nobody Thinks to Ask
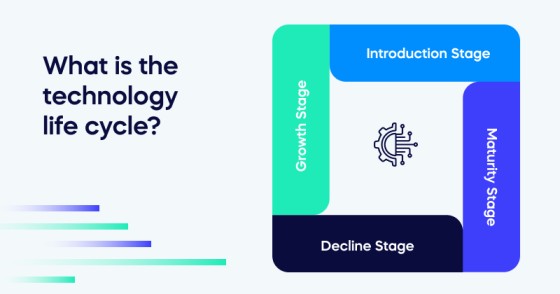
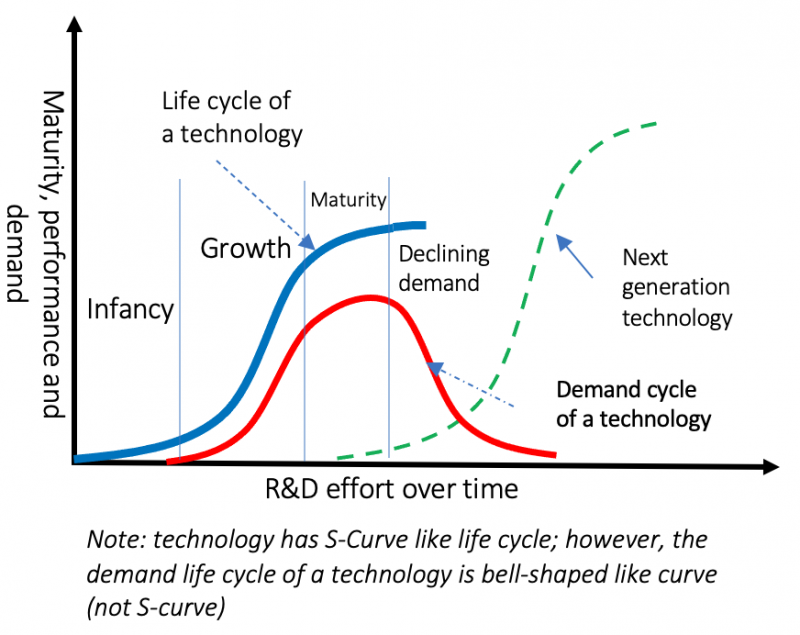
The technology life cycle is just a framework for tracking when something gets built, used, and eventually abandoned. It comes in a few flavors depending on who you ask. Some people break it into four stages: introduction, growth, maturity, decline. Others add a research and development phase at the front, making it five or six stages. The concept itself is simple enough, but the practical application is where most teams get it wrong. I spent years watching engineering groups try to map these cycles onto real products, and almost everyone treats it like a straight line. Real technology doesn't move in a straight line. It loops, stalls, and occasionally jumps back into the introduction stage because a competitor forced a reset. That said, knowing the model helps you predict funding cuts, staffing changes, and procurement decisions before they hit your desk.
What Is The Technology Life Cycle
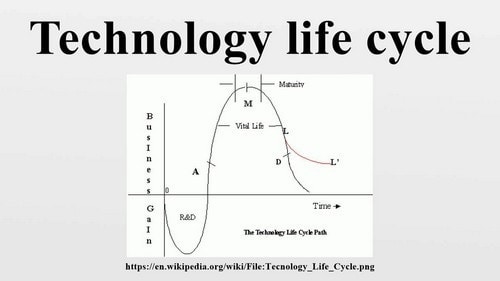
At its core, the technology life cycle describes how a particular tool, platform, or system moves from initial creation through active use and into eventual retirement. The standard stages are development, introduction, growth, maturity, and decline. But here's what most guides don't mention: each stage has different owners, different risk profiles, and different budget priorities. When you're in the development stage, you're burning capital with no revenue expectation. By maturity, the system generates steady returns but demands patches and maintenance rather than innovation. The shift between stages is rarely announced officially. You spot it in the data. I once worked with a team that kept treating a system in its decline phase as if it were still in growth. The platform was a legacy internal analytics tool. Performance had plateaued two years prior, the engineering team had been reassigned to newer projects, and security patches were arriving six months late. Nobody formally declared the system dead. It was just running on habit. I wrote a migration plan to a modern alternative and got it approved by framing it as a risk reduction exercise rather than a replacement. The old system was generating about four support tickets a week, mostly around integration failures. The new platform cut that to near zero within three months. The whole transition took about eight weeks of focused work.
How to Actually Map a Life Cycle
You don't need a consulting firm to figure out where your technology sits. Grab your ticketing data, your deployment logs, and your procurement records. Look for inflection points. A sudden drop in new feature requests usually means you've hit maturity. A spike in bug reports paired with stagnant feature velocity often signals the decline phase is starting. These patterns show up in your existing tools if you know where to look. One thing beginners consistently miss is that the introduction and growth phases look identical on the surface. Both involve rapid development, frequent deployments, and high energy. The difference is adoption rate. In introduction, you're proving it works. In growth, you're scaling it to more users. If you can't tell which one you're in, check your user acquisition curve. A flat line during what should be a growth phase means you're still in introduction and haven't cracked product-market fit yet. That's a much riskier position than you'd think. Another common blind spot is assuming decline is inevitable for everything. It isn't. Some technologies maintain a long maturity plateau. Legacy enterprise systems in banking and government often sit at maturity for decades because regulatory requirements and integration complexity prevent retirement. Meanwhile, consumer-facing tools can burn through their entire cycle in eighteen months. Context matters more than the model itself.
Get the Full Details
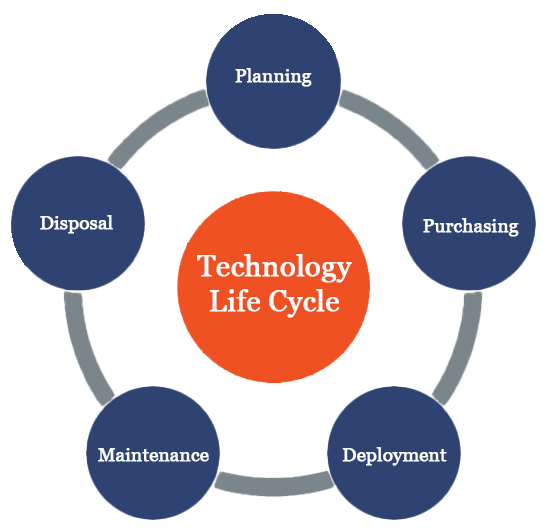
Where the Model Breaks Down
The technology life cycle assumes a single coherent trajectory for a given piece of technology. That assumption fails whenever a system has multiple sub-components that age at different rates. A web application might have a frontend framework in decline while its database layer is still in maturity. Your content management system could be mature while the authentication service it depends on has already moved to decline. Treating the whole stack as one unit in one stage gives you a false sense of clarity. I ran into this exact problem when managing a SaaS platform. The monolith had been together since the early growth phase. By the time we tried to assess the overall lifecycle, every team had their own interpretation of where things stood. Engineering said maturity. Product said decline. Sales insisted we were still in growth because revenue hadn't dropped. The truth was the architecture was modular enough that different pieces were in different stages simultaneously. What actually helped was breaking the system into service boundaries and mapping each one separately. That took about two weeks of audit work but gave us a realistic view instead of a misleading aggregate number. There's also the question of whether the model even applies to AI systems. Modern machine learning models don't really have a hardware component that degrades. Their performance can improve over time with better training data. But their relevance to specific tasks decays as alternatives emerge. The lifecycle here is more about utility decay than technological deterioration, which means the traditional stage markers don't map cleanly. You can still use the framework as a rough guide, but you'll need to adjust your signals. Model drift metrics and benchmark performance over time serve better as indicators than ticket volume or feature request counts.
Practical Steps You Can Take Now
If you want to apply this to something real, start by inventorying your current systems. List every technology your organization relies on. For each one, note when it was introduced, what stage it currently appears to be in, and what evidence supports that classification. Use concrete metrics rather than gut feelings. Deployment frequency, mean time to recovery, security vulnerability counts, and user engagement numbers all feed into a stage assessment. Once you have that baseline, identify which systems are approaching maturity or decline and plan ahead. Don't wait for a crisis to force a decision. A mature system gives you a window to migrate gradually. A declined system that you keep operating without a plan becomes an emergency replacement six months from now, usually under tighter constraints and higher cost. Budget for these transitions at least a year in advance. Typical migration timelines for mid-complexity systems range from three to six months of active work, plus another two to three months for validation and rollback testing. Track the cycle periodically rather than setting it and forgetting it. Quarterly reviews are reasonable. At that interval, you'll catch stage transitions before they become operational problems. A system that looks stable in January might be showing clear decline signals by April if you're looking at the right data points. The goal isn't perfect prediction. It's staying ahead of the curve just enough to make rational decisions instead of reactive ones.