Proteins Are Long Chains of Amino Acids
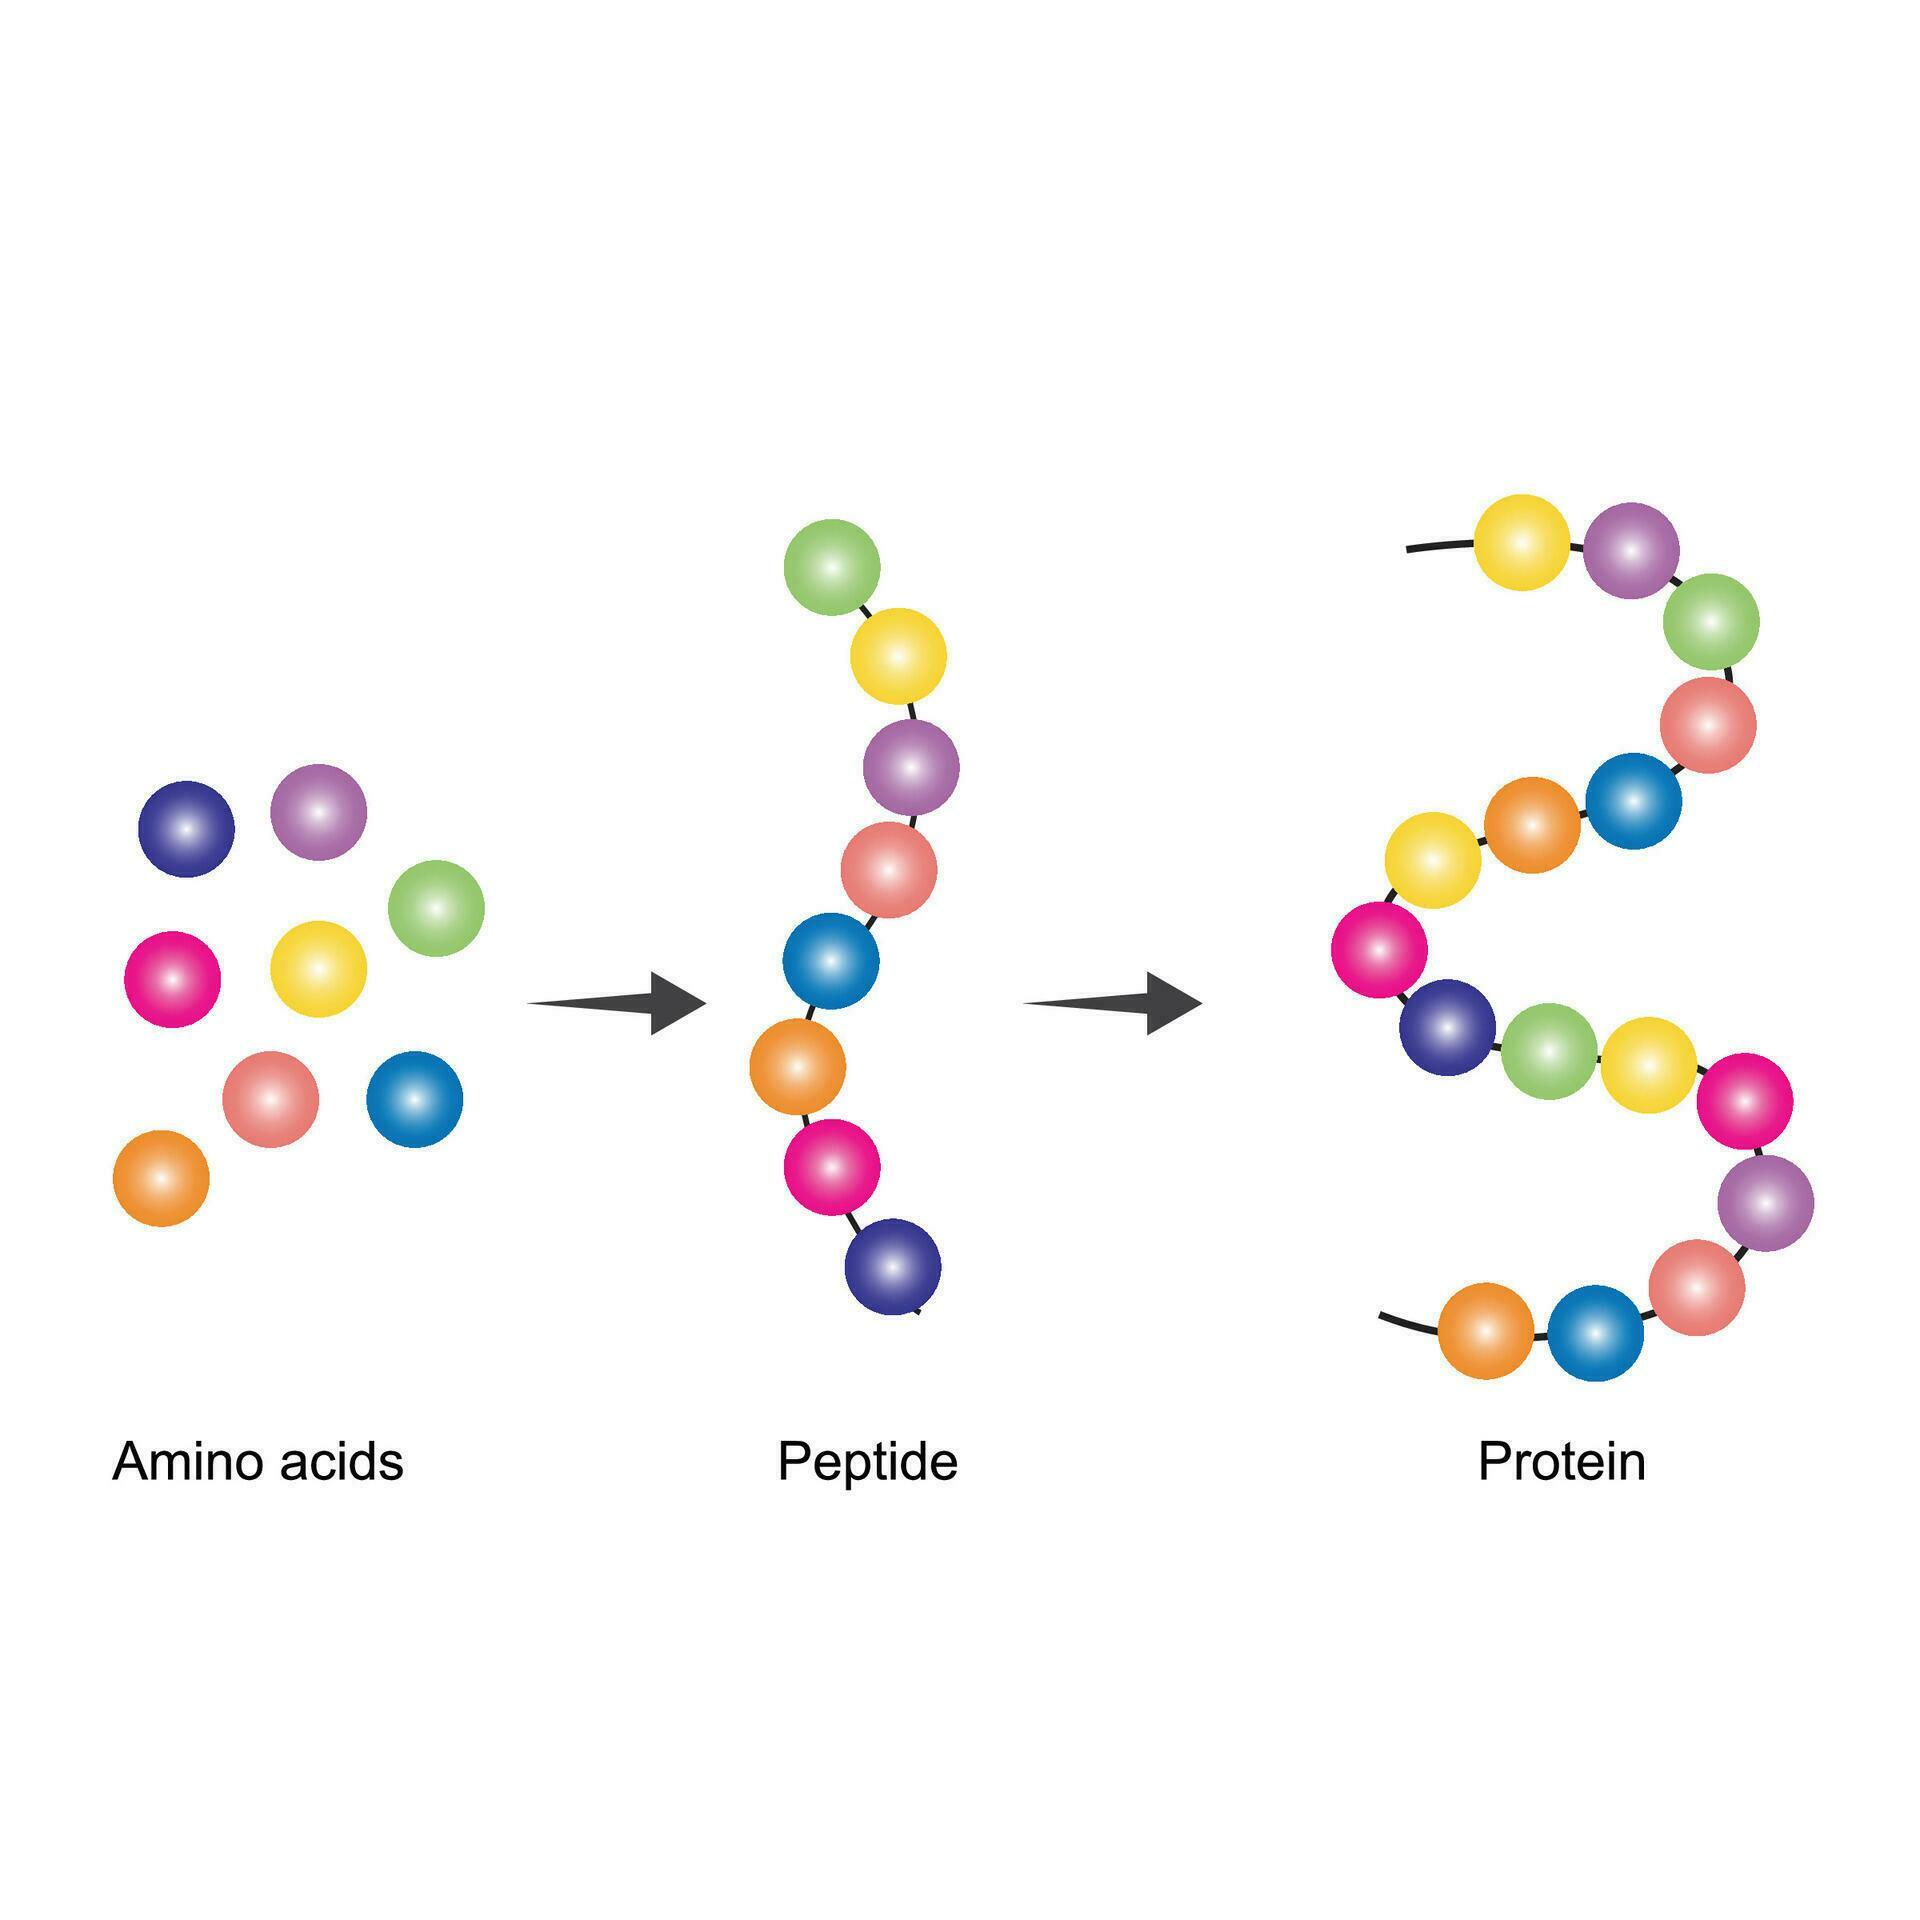
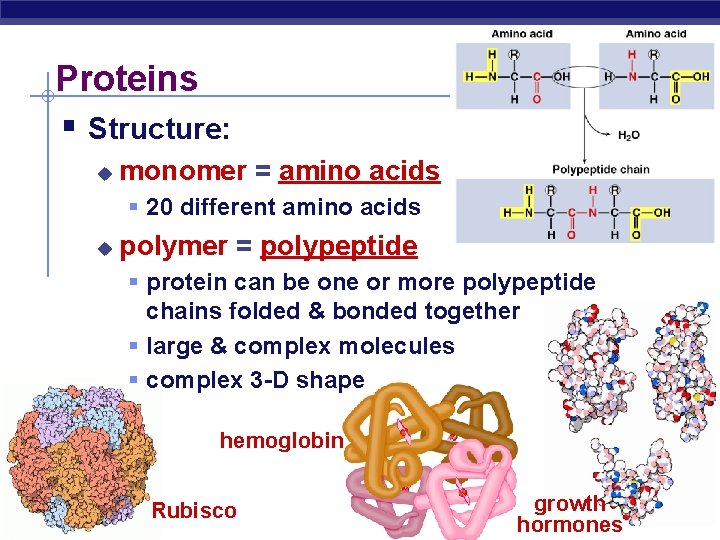
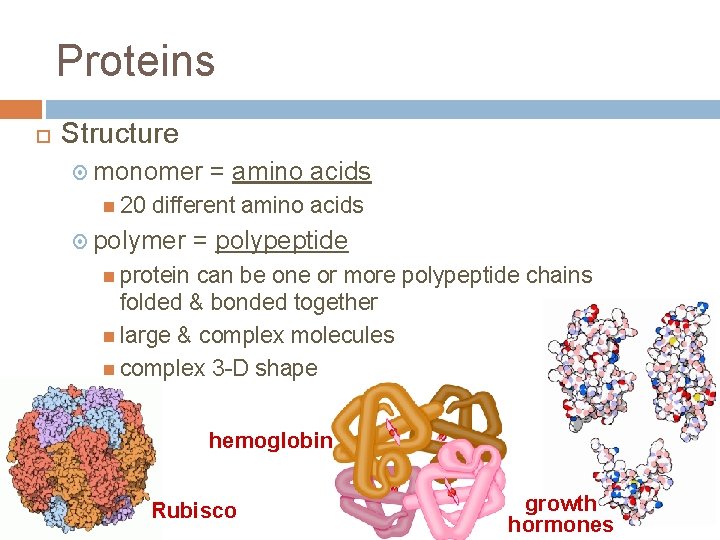
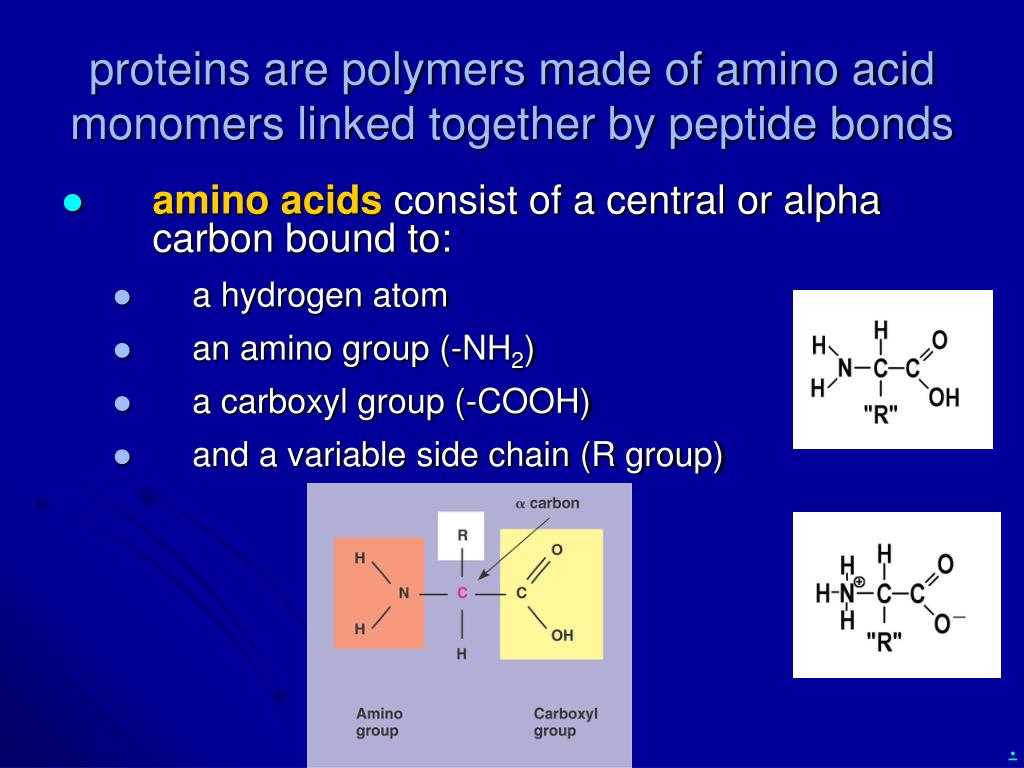
The monomers that make up proteins are amino acids. Not some rare or exotic compound, just twenty standard ones linked together by peptide bonds. You probably learned this in high school biology and then forgot most of it. That's normal. The chemistry is straightforward; the biological implications are where things get messy. There are twenty standard amino acids encoded by the human genome. Each one shares the same basic structure: an amino group, a carboxyl group, a hydrogen atom, and a variable side chain all attached to a central alpha carbon. The side chain is what makes each amino acid different. Glycine has just a hydrogen for its side chain. Tryptophan has this bulky indole ring that sticks out everywhere. That structural simplicity is why they polymerize so easily. The peptide bond forms through a condensation reaction where the carboxyl group of one amino acid reacts with the amino group of another, releasing water. This happens repeatedly during translation on the ribosome. The resulting chain is called a polypeptide. One polypeptide can be anywhere from roughly fifty to over three thousand amino acids long, depending on the protein.
I spent way too many hours in grad school dealing with recombinant protein expression, and the thing nobody tells you upfront is that just because you know the amino acid sequence doesn't mean the protein will fold correctly. I once spent three weeks troubleshooting a protein that kept forming inclusion bodies. The sequence was fine. The E. coli expression system was fine. The protein just had a region rich in charged residues that caused it to aggregate before it could properly fold. Switching to a slower expression temperature and adding a chaperone co-expression plasmid fixed it. Standard workaround. Here's something people often miss: the twenty amino acids aren't evenly distributed across all proteins. Some amino acids like leucine and alanine show up constantly because their hydrophobic side chains drive protein folding. Others like tryptophan and cysteine are rare. Cysteine matters disproportionately though because it forms disulfide bridges that lock tertiary structure in place. A protein missing even one critical cysteine can be completely nonfunctional, while swapping out several leucines might not matter at all.
Post-Translational Modifications Complicate the Picture
The twenty-amino-acid answer is technically correct but practically incomplete. After a protein is synthesized, it often gets modified. Phosphorylation adds phosphate groups to serine, threonine, or tyrosine. Glycosylation attaches sugar chains. Methylation, acetylation, ubiquitination — the list goes on. These modifications can change what the protein does without changing the underlying amino acid sequence at all. I remember working with a kinase assay where the antibody we were using couldn't distinguish between the phosphorylated and unphosphorylated forms of the target protein. We ended up having to use a phospho-specific antibody instead. Not a huge problem, but it costs extra money and adds another step to the protocol. These kinds of issues come up constantly when you're actually working with proteins rather than just reading about them. There are also non-standard amino acids that occasionally show up. Selenocysteine is sometimes incorporated into proteins at stop codons when a specific SECIS element is present in the mRNA. Pyrrolysine exists in some methanogenic archaea. These are exceptions and shouldn't distract you from the main point, but they do show that the "twenty amino acids" framework is a simplification even for textbook purposes.
Get the Full Details
Parsing the Chemistry Without Getting Lost
The actual mechanism of peptide bond formation is template-driven. Messenger RNA provides the sequence information, transfer RNA brings the correct amino acid to the ribosome, and the ribosome catalyzes the bond formation. The energy for this process comes from GTP hydrolysis and from the high-energy aminoacyl-tRNA bonds that were formed earlier by aminoacyl-tRNA synthetases. Those synthetases are the real quality control checkpoint — each one is specific to one amino acid and its corresponding tRNA. A mistake there means the wrong amino acid gets incorporated, and there's no proofreading mechanism to fix it once it's in the chain. Side note on synthesis speed: in E. coli, translation proceeds at roughly fifteen to amino acids per second. In eukaryotic cells it's slower, maybe five to fifteen per second. If you're expressing a large protein like titin, which has roughly thirty-four thousand amino acids, the synthesis alone takes considerable time even before you account for folding and modification.
Practical Considerations When Working with Proteins
If you're doing this work in a lab setting, here are the things that actually matter day to day. Protein concentration measurements by absorbance at 280 nanometers rely on tryptophan and tyrosine content. If your protein lacks both, the standard calculation gives you garbage results. You'll need to use a Bradford or BCA assay instead. I learned this the hard way with a synthetic peptide that had zero aromatic residues. Purification via affinity chromatography works beautifully when your protein has the right tag, but tags can interfere with folding or function. His-tags are convenient but small. FLAG or HA tags are larger and sometimes cause problems. Removing the tag with a protease like TEV is standard practice, but TEV itself needs to be removed afterward, and incomplete cleavage leaves you with a mixture that's annoying to deal with. Storage is another area where people make mistakes. Most proteins degrade at room temperature within hours. Aliquot your samples so you're not freeze-thawing the same tube repeatedly. Freeze-thaw cycles cause aggregation in many proteins, and once a protein aggregates you can't really undo it. Ten percent glycerol or sucrose helps with stability during freezing, but it can interfere with certain assays downstream. Just pick an approach and be consistent about it.
The bottom line is that amino acids are simple molecules, but proteins made from them are complicated. Understanding the monomers is necessary but not sufficient for understanding the proteins. The side chains determine everything: solubility, folding, interaction surfaces, catalytic activity, regulatory sites. That's the part that takes time to internalize through actual experience rather than textbook reading.