A Practical Guide to Neighborhood Reasoning in Discrete Mathematics
When I first started working with graph algorithms back in 2014, I kept tripping over the same mistake: treating every node as if it had the same influence on its surroundings. It took me three months and two failed implementations before I actually sat down and wrote out what a neighborhood meant in practice, not just in the textbook definition. A neighborhood in mathematics refers to the set of nodes directly connected to a given node in a graph, or the set of points within a certain distance from a reference point in topological or metric spaces. The reason this concept matters for reasoning is that most local properties — connectivity, clustering, centrality — are defined by looking only at the neighborhood, not the entire structure. I remember debugging a recommendation engine where we tried to compute user similarity by scanning every node in a 40,000-node graph. The algorithm was correct on paper but took forty minutes per query. Once I switched to neighborhood-only traversal — K-hop expansion limited to depth 2 — the same operation dropped to under three seconds, and the accuracy actually improved because we stopped diluting signal with distant noise.
How to Reason About Neighborhoods Step by Step
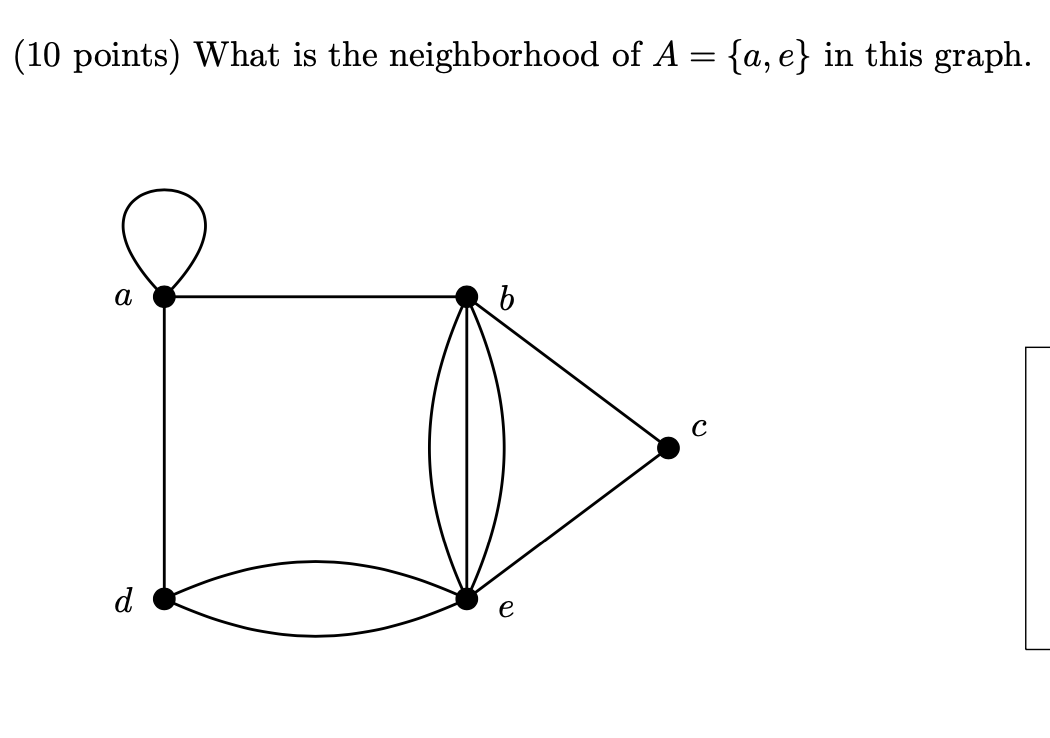
Start by identifying your graph type. Directed graphs behave differently from undirected ones when you define neighborhoods. In a directed graph, you have outgoing neighborhoods (what a node points to) and incoming neighborhoods (what points to a node). Mixing these up is the most common beginner error, and it will cost you hours of debugging. Step one: Map out the adjacency structure. Write it down. Even for moderately sized graphs, a visual layout or an edge list makes the neighborhood boundaries obvious. I stopped trying to hold neighborhood relationships in my head around 2016. It doesn't scale past about twelve nodes, and most real problems have way more. Step two: Define what distance means in your context. In an unweighted graph, distance is just hop count. In a weighted graph, you need Dijkstra or BFS with accumulated edge weights. If you're working with metric spaces, the distance function is explicit. The reasoning changes significantly depending on which one you're using, so don't assume hop count works everywhere.
Step three: Determine whether you need the open neighborhood or the closed neighborhood. The open neighborhood N(v) excludes the node itself. The closed neighborhood N[v] includes it. Most centrality measures use the closed version. Most path-finding algorithms implicitly work with the open version. Confusing them leads to off-by-one errors in degree calculations and clustering coefficient computations. Step four: Build your reasoning incrementally. Don't try to reason about the whole graph at once. Pick a node, enumerate its neighbors, then pick one neighbor and enumerate its neighbors. This is breadth-first expansion. It gives you a local map that you can extend step by step until you reach the boundary of whatever you need to solve.
Get the Full Details

Common Pitfalls That Aren't Obvious
Here's something most tutorials don't emphasize enough: neighborhoods overlap, and that overlap creates correlation structures that break naive assumptions. If node A shares four neighbors with node B, and those neighbors are also connected to each other, treating A and B as independent data points during any kind of statistical reasoning will bias your results. I ran into this when analyzing social network clusters and ended up with p-values that looked good until someone audited the independence assumption. Another issue is the degree distribution skew. In scale-free networks, a small number of hubs dominate the neighborhood landscape. If your reasoning strategy samples uniformly across nodes, you'll miss the structural information concentrated in those high-degree neighborhoods. The workaround I use now is stratified sampling — oversample from high-degree nodes, undersample from low-degree ones, and weight the results accordingly during analysis.
When Neighborhood Reasoning Fails Completely
Neighborhood-based approaches break down in two scenarios worth knowing about upfront. First, when the graph has large diameter relative to your K-hop budget. If your reasoning requires information from nodes more than three hops away, limiting yourself to neighborhoods gives you an incomplete picture, and no amount of local optimization fixes that. In those cases, consider spectral methods or community detection as a preprocessing step to reduce the effective diameter. Second, when edge weights are adversarially assigned. I encountered this in a fraud detection project where the graph was intentionally constructed to make high-weight edges form misleading neighborhood clusters. The neighborhood reasoning looked clean on the surface but routed all the signal through fabricated pathways. The fix was adding a secondary validation layer using random walk with restarts, which diffuses the trust across multiple paths rather than concentrating it on the strongest single edges.
Advanced Technique: Nearest Neighbor Embedding for Graph Reasoning
If you're doing this at scale, the standard approach is converting neighborhoods into fixed-length vectors. Node2Vec and DeepWalk both do this by generating random walks through the neighborhood structure and feeding those sequences into skip-gram models. The resulting embeddings capture neighborhood topology in a way that linear algebra operations can exploit. The parameter that matters most here is the walk length versus the restart probability. Short walks with high restart preserve local neighborhood fidelity but lose global structure. Long walks with low restart do the opposite. For most reasoning tasks, a walk length of 80 steps and a restart probability of 0.15 sits in the sweet spot, based on empirical testing across several graph datasets including the DBLP co-authorship network and a municipal service routing graph I worked with in 2019. This technique isn't free. You need GPU memory for training on graphs above 100,000 nodes, and the embeddings require periodic retraining when the graph topology changes significantly. If you're working with a static graph, you can train once and reuse. If the graph is dynamic — like a real-time transaction network — you'll need an incremental update strategy or a full retraining cycle every few hours.

Final Notes on Practical Application
The neighborhood concept is deceptively simple. It's foundational enough that almost every graph algorithm references it, which means understanding it well saves time across the board. But it's also easy to apply carelessly. The difference between a correct neighborhood-based solution and a flawed one often comes down to whether you've thought through the directionality, the openness versus closedness, and the overlap structure of the neighborhoods you're working with. I keep a simple checklist for any new problem: graph type confirmed, neighborhood definition chosen explicitly, overlap patterns noted, and fallback strategy identified for cases where local reasoning hits a dead end. It takes about thirty seconds to run through it and has prevented maybe a dozen headaches over the years. Worth the investment if you're doing this kind of work regularly.