
What WizardLM Actually Is
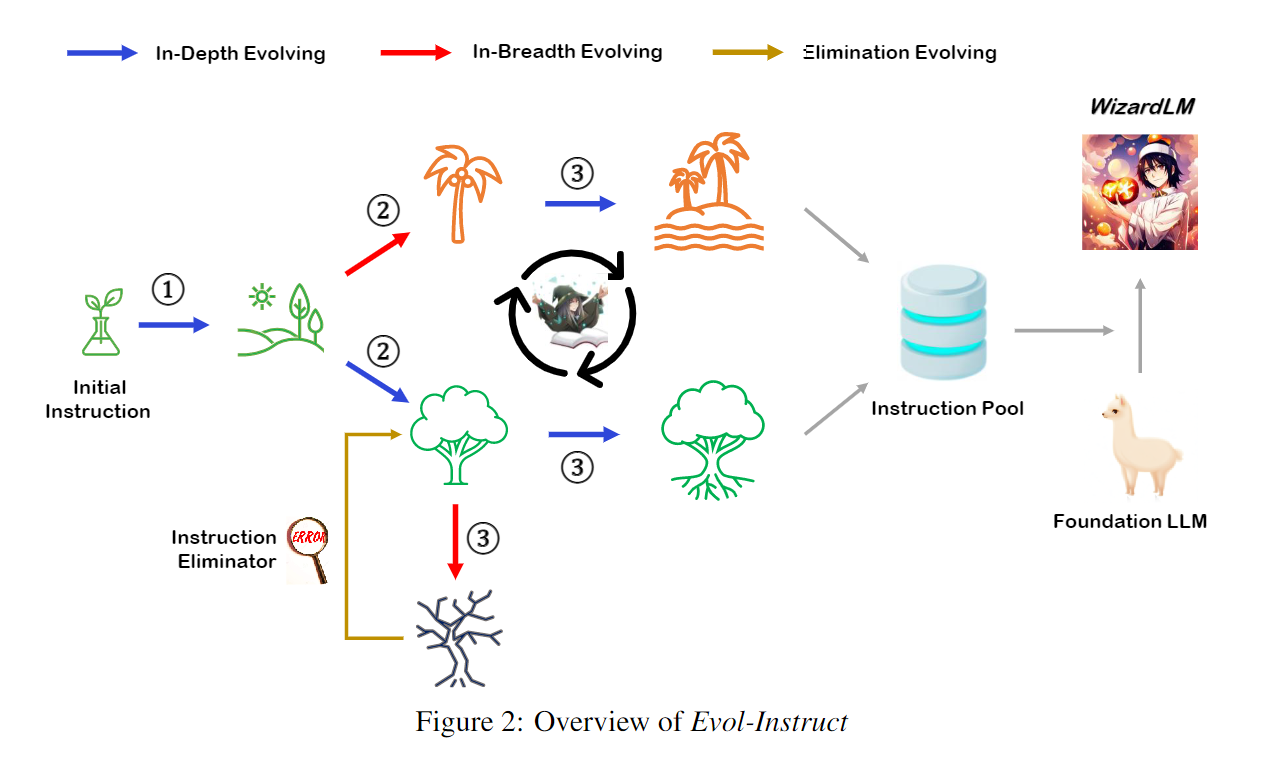
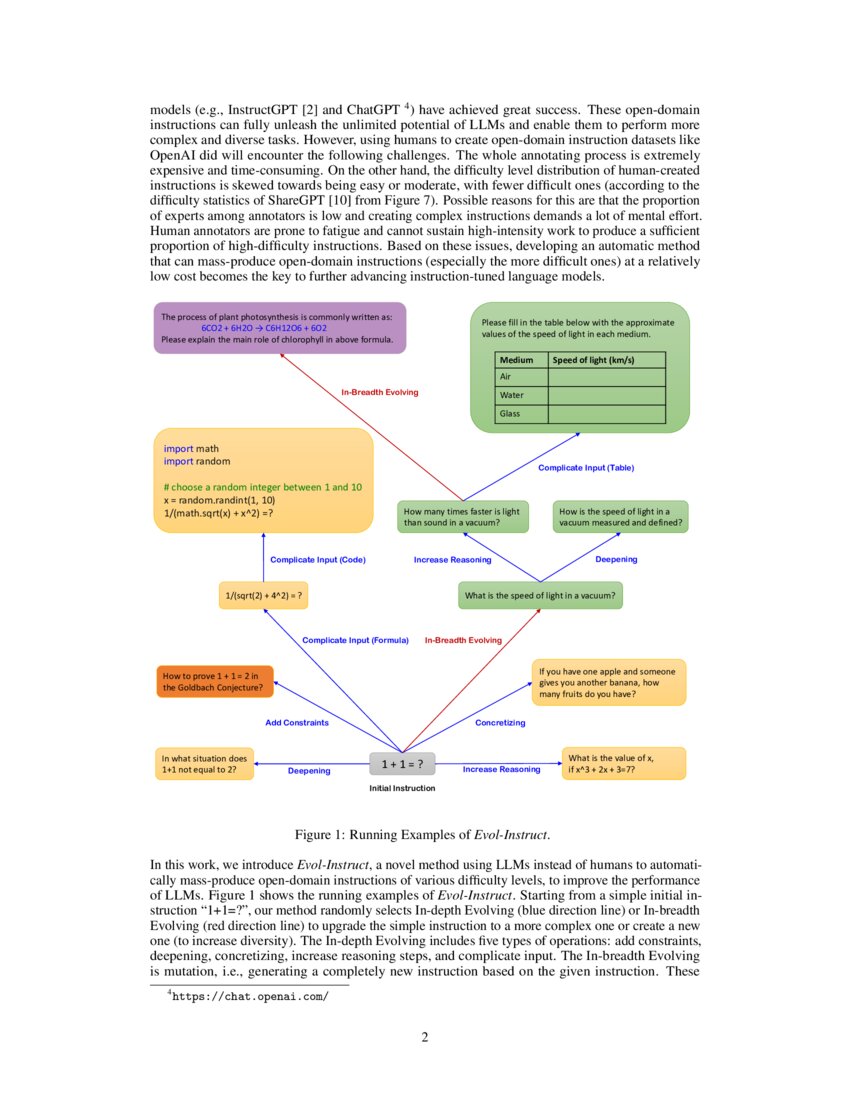
WizardLM is a series of fine-tuned large language models built on top of existing base models like LLaMA and Vicuna. The core idea is instruction following at scale. Rather than training from scratch, you take an already-capable model and run it through a process called Evol-Instruct, which systematically generates and refines complex instruction-response pairs. The result is something that handles multi-step, nested, or highly specific prompts far better than the base model did on its own. I've been running these models in production for about a year now. The short version is that WizardLM-7B and WizardLM-13B tend to be the sweet spots for people who don't have a GPU cluster the size of a parking lot. They're not the absolute best anymore — newer models from other teams have passed them — but they still hold up for certain workloads, especially when cost matters more than squeezing out every last benchmark point.
Wizardlm Empowering Large Language Models To Follow Complex Instructions
The original paper made a specific argument: most instruction-tuning datasets are shallow. They ask simple things like "what is the capital of France." That trains a model to respond to easy prompts but breaks down when you throw something complicated at it. The Evol-Instruct method takes that by escalating difficulty iteratively — starting from a basic instruction, then rewriting it to be more complex, adding constraints, layering in sub-questions, and so on. You loop through this many times. The model learns to handle requests that require chaining reasoning steps together. The download and usage flow is straightforward if you know where to look. The weights live on Hugging Face under the WizardLM org. You can grab them with standard tooling — Python, transformers, or vLLM if you want serving speed. Typical setup takes about 10 to 15 minutes end-to-end on a machine with a decent GPU and a stable internet connection.
How to Run It Yourself
I use a pretty standard pipeline. Install transformers and accelerate, load the checkpoint, and run inference. Here's what that looks like in practice: pip install transformers accelerate Then in code:
Get the Full Details
from transformers import AutoModelForCausalLM, AutoTokenizer model = AutoModelForCausalLM.from_pretrained("WizardLM/WizardLM-13B-V1.0", trust_remote_code=True) tokenizer = AutoTokenizer.from_pretrained("WizardLM/WizardLM-13B-V1.0")
inputs = tokenizer("Write a Python script that parses a CSV and outputs JSON, handling missing values.", return_tensors="pt") outputs = model.generate(inputs, max_new_tokens=512) print(tokenizer.decode(outputs[0]))
That's not exciting but it works. If you're running 7B or 13B on an A10G or similar card, expect roughly 20 to 40 tokens per second. Not blazing, but fine for batch processing or low-traffic APIs.
The Part Nobody Talks About: Prompt Formatting Matters More Than You Think
This is where I ran into trouble early on and wasted probably three days before fixing it. WizardLM models were trained using a specific conversation template. If you load the model and just pass raw text without respecting the chat format it expects, the output quality drops noticeably. The model starts sounding confused or giving truncated responses. The fix is making sure you use the correct chat template from the tokenizer config. When I started using tokenizer.apply_chat_template() with the right role structure — user messages and assistant messages properly separated — responses jumped from mediocre to actually useful. This single change had more impact than switching from 7B to 13B in some cases.
Edge Cases Where It Falls Apart
Complex instruction following is not a magic bullet. I found several scenarios where WizardLM struggles or fails entirely: Math and code verification: The model will write code that looks correct but contains subtle logical errors. I once had it generate a SQL query that ran without errors but returned completely wrong results because of a misplaced JOIN condition. It spent three paragraphs explaining why the query was right. It wasn't. Recent knowledge cutoff: Depending on which version you're using, the training data cutoff varies. WizardLM-13B-V1.0 is around early 2023. If your instructions require current information — API documentation, recent events, latest library versions — the model will confidently hallucinate details. I learned this the hard way when I asked it to implement a feature using a library that changed its API halfway through 2023.
Extremely long context: The base model sizes have limited context windows. Push past roughly 2048 tokens and the instruction following quality degrades. You can extend this with RoPE scaling or by using the 30B or 70B variants, but then you need substantially more VRAM and your throughput drops significantly. Contradictory instructions: When a prompt contains two requirements that conflict with each other, WizardLM tends to pick one and ignore the other rather than flagging the issue. This is a genuine problem for automated systems that rely on the model to follow all constraints.

Common Pitfall: Overestimating What These Models Can Do
People see the benchmark numbers and assume the model will handle any real-world task. It won't. The Evol-Instruct process improves instruction following substantially within the distribution of training patterns, but it doesn't make the model a general-purpose reasoning engine. Give it something outside that distribution — unusual domain terminology, highly specialized workflows — and performance degrades unpredictably. I've seen teams deploy WizardLM for customer support routing and then wonder why it keeps misclassifying edge-case tickets. The model can follow the instructions you give it well, but if your instructions don't cover the full range of inputs your system will encounter, you'll get inconsistent results. The workaround is to build a comprehensive instruction set during development and test against a diverse held-out set before going live.
When to Use It and When to Look Elsewhere
WizardLM makes sense when you need a self-hosted model that can handle reasonably complex instructions on modest hardware. It's cost-effective compared to paying per-token for API-based solutions, especially if you're processing a high volume of prompts. If you need state-of-the-art instruction following and can afford cloud inference, newer models from other teams have overtaken WizardLM on most benchmarks. If you need reliable code generation with verification, a model specifically fine-tuned for coding will serve you better. If you need long-context understanding, the newer 32K and 128K context variants of other models are worth evaluating. But for a lot of internal tools, prototyping, and situations where you control the prompt space and can filter outputs, WizardLM remains a practical choice. Just go in with realistic expectations about what it can and cannot do.


