Wizz Spreader is a data distribution tool used mainly in analytics workflows where you need to take a single processing unit and fan it out across multiple downstream systems or nodes. It handles load balancing, parallel processing, and sometimes batch splitting depending on how it is configured. People use it when they have a pipeline that becomes a bottleneck and cannot move forward fast enough on a single thread.
Working Through the Wizz Spreader Manual
Most people skip the manual until something breaks. That is a bad habit. The Wizz Spreader Manual covers configuration syntax, environment variable overrides, retry logic, and partitioning strategies. Reading it takes about forty-five minutes if you go section by section. I spent three weeks debugging a deployment issue before I realized the manual had a whole subsection on sticky sessions and session affinity timeouts. It was there the whole time.
Here is the basic setup sequence. You install the runtime package, set your environment variables for cluster discovery, define a routing policy in the config file, and point the spreader at your source data stream. That part is straightforward. The hard part is tuning.
Configuration files are YAML by default. The routing algorithm selection matters more than most people realize. Hash-based spreading distributes evenly but can create hot partitions if your keys are not uniformly distributed. Least-connection spreading adapts dynamically but adds latency overhead on each request because it needs to probe node health before routing.
I had a job that was supposed to fan out 10,000 records per minute across eight worker nodes. It was choking at around 3,200 records per minute. The Wizz Spreader manual had a section on backpressure handling that I completely overlooked. The issue was not throughput capacity. It was that the spreader was filling its internal buffer faster than workers could drain it, and the buffer was silently dropping records past a certain threshold. The fix was setting the backpressure_policy to reject instead of drop, which exposed the real bottleneck downstream. The workers were not crashing. They were just too slow to catch up.
Common Setup Mistakes
The most common mistake is assuming the spreader handles data validation. It does not. It routes what you give it. If you send malformed records, they get routed correctly and then fail downstream where you have less visibility into what went wrong. Always add a validation layer before the spreader, not after.
Another frequent error is misconfiguring the heartbeat timeout. The spreader uses heartbeats to detect dead nodes. If your timeout is set too low, healthy nodes get marked as unreachable during brief network hiccups and requests get rerouted unnecessarily. This causes cascading failures in tight clusters. I have seen production jobs restart six times in an hour because the heartbeat interval was set to two seconds in a high-latency network environment. Setting it to fifteen seconds solved it immediately.
Advanced Partitioning Strategies
When your dataset has uneven key distribution, default spreading will concentrate traffic on a subset of nodes. This is called partition skew and it is the number one reason spreaders appear to underperform. You can mitigate it with consistent hashing or by introducing a salting mechanism to your keys. Salting means appending a random suffix to your key before hashing, which forces distribution across more partitions even when the base keys are clustered.
There is also the option of using adaptive partitioning, which the manual describes in the scaling section. The spreader monitors partition sizes and dynamically reassigns ownership. It works well for workloads with shifting data patterns. It does not work well when the shifting is rapid, because the rebalancing overhead can exceed the benefit. I ran a benchmark comparing static versus adaptive partitioning on a dataset with hourly traffic spikes. Static partitioning maintained steady throughput while adaptive partitioning caused thirty percent variance during rebalancing windows.
Known Limitations
Wizz Spreader does not guarantee exactly-once delivery. At-least-once is the closest you get, and that assumes your downstream systems handle idempotency correctly. If they do not, you will see duplicate records in your data stores. There is no built-in deduplication. You have to implement it yourself or pipe through a separate stage.
The tool also struggles with very large single-partition workloads. If you are trying to spread a dataset larger than ten gigabytes in a single job, the memory footprint of the spreader itself becomes a concern. The manual recommends chunking these jobs into smaller batches of roughly two to four gigabytes each. This is not an optimization. It is a requirement if you want stable performance.
For streaming workloads with strict ordering requirements, Wizz Spreader is not the right tool. It processes independently per partition and does not maintain global ordering across partitions. If your use case requires sequential ordering, look at a message queue with partition-local ordering guarantees instead.
Practical Troubleshooting Steps
When the spreader seems to stall, check the buffer utilization metrics first. They are available in the logs by default. If buffer usage is above eighty percent consistently, you have either a downstream bottleneck or an upstream overload. Check worker node health next. You can query the status endpoint on port 8081 by default. The response shows active connections, last heartbeat timestamp, and processing rate per node.
If all nodes show healthy status but throughput is low, the issue is usually in the routing policy. Switch to a simpler strategy temporarily to rule out complexity-related overhead. If throughput improves, your routing configuration needs simplification. If it does not improve, the problem is elsewhere in the pipeline.
The Wizz Spreader manual includes a diagnostic mode that traces each record from ingestion to dispatch. It adds overhead, so use it only in staging environments. I found it useful once when tracking down intermittent delays that only appeared under load. The traces revealed that certain key ranges were hitting a different routing branch due to a boundary condition in the hash function. That detail was not obvious from any metric dashboard.
Gallery Wizz Spreader Manual
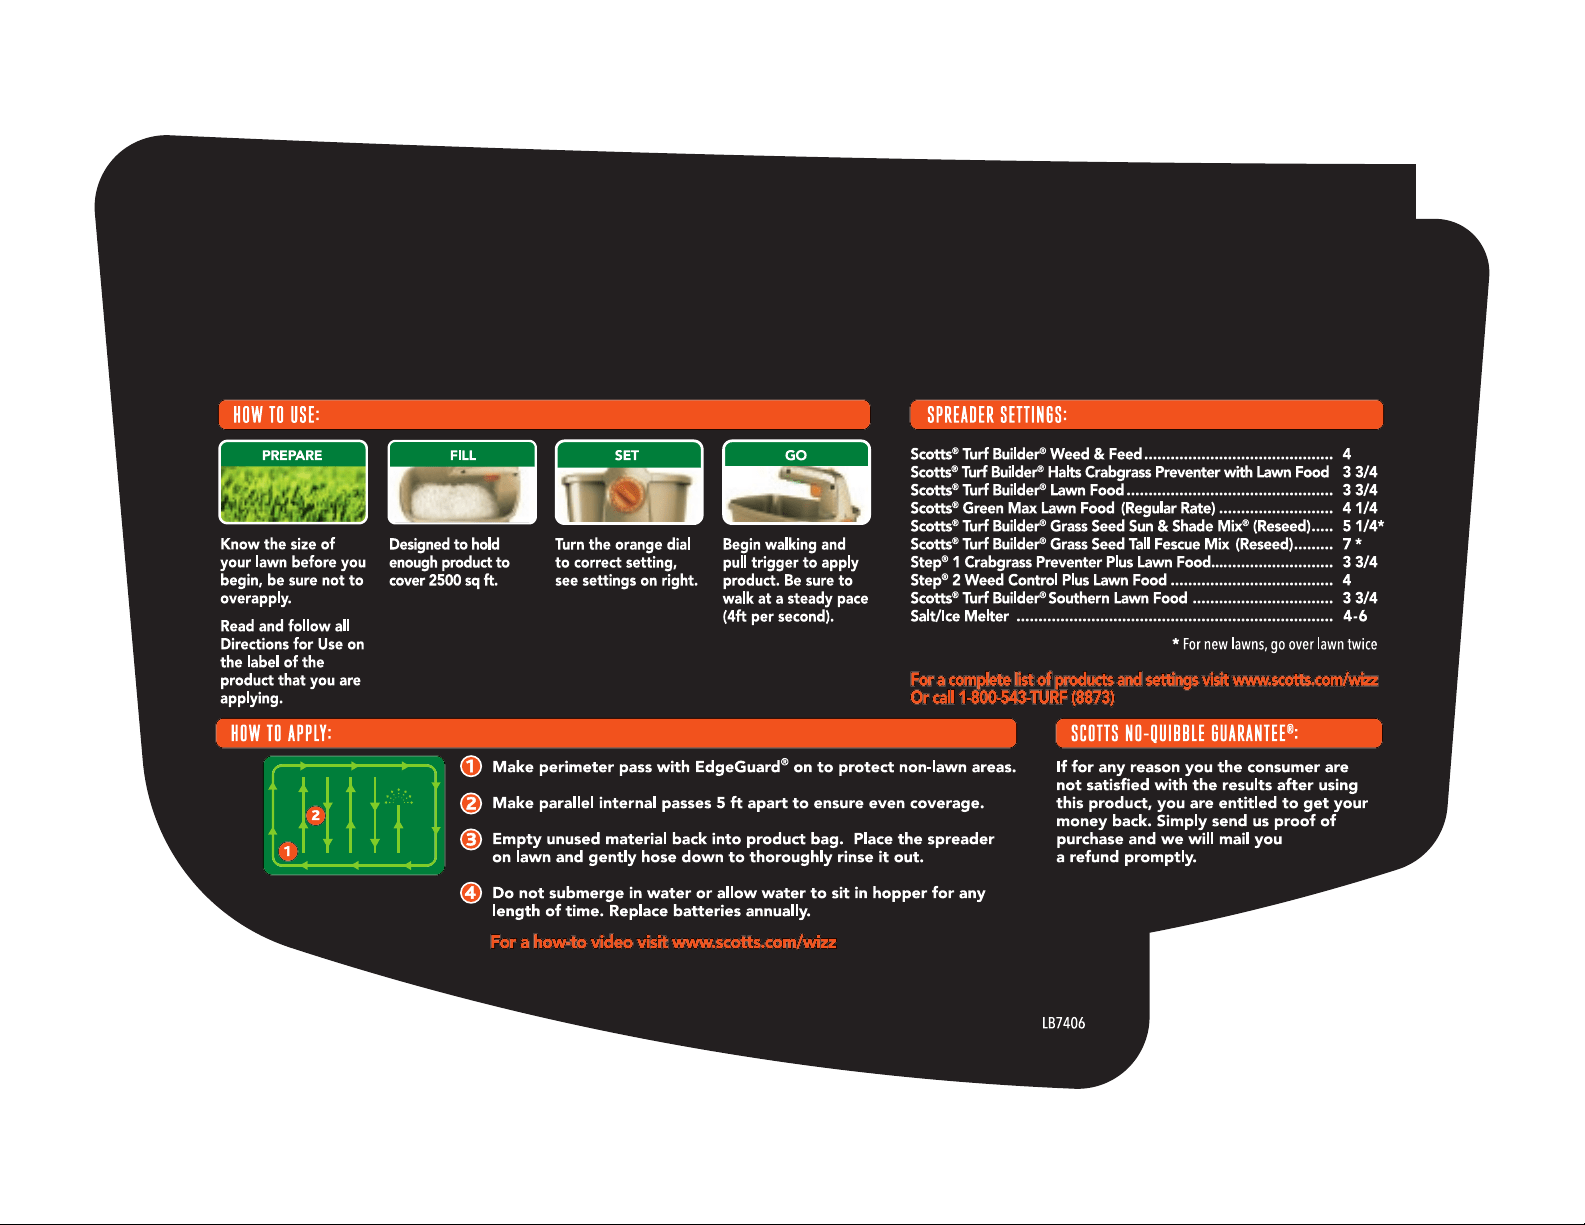
Scotts Wizz Hand-Held Spreader User Manual
Scotts 71131 Wizz Spreader - Handheld Power Spreader, Use User Manual
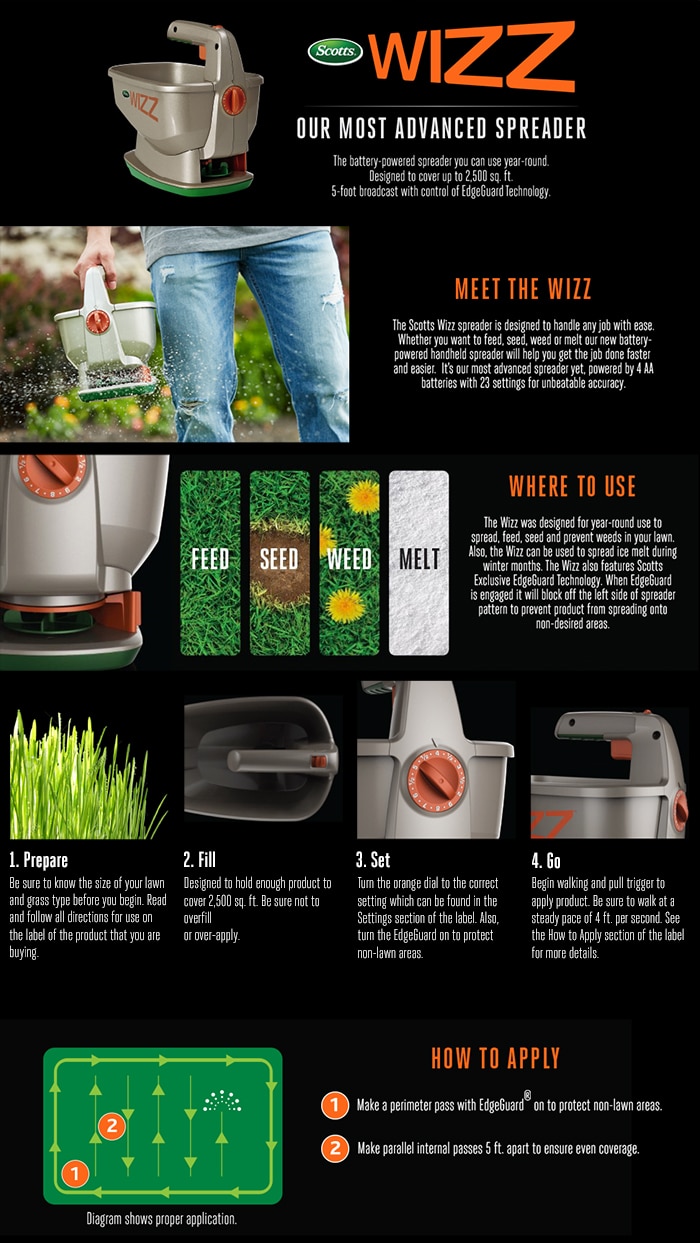
Scotts Wizz Spreader Holds up to 2,500 sq. ft. of Product, Handheld Spreader for Grass Seed ...
Scotts Wizz Hand-Held Spreader
Scotts Wizz Spreader for Grass Seed, Fertilizer, Salt and Ice Melt, Handheld Spreader Holds up ...