What actually makes a statistics workbook useful in practice
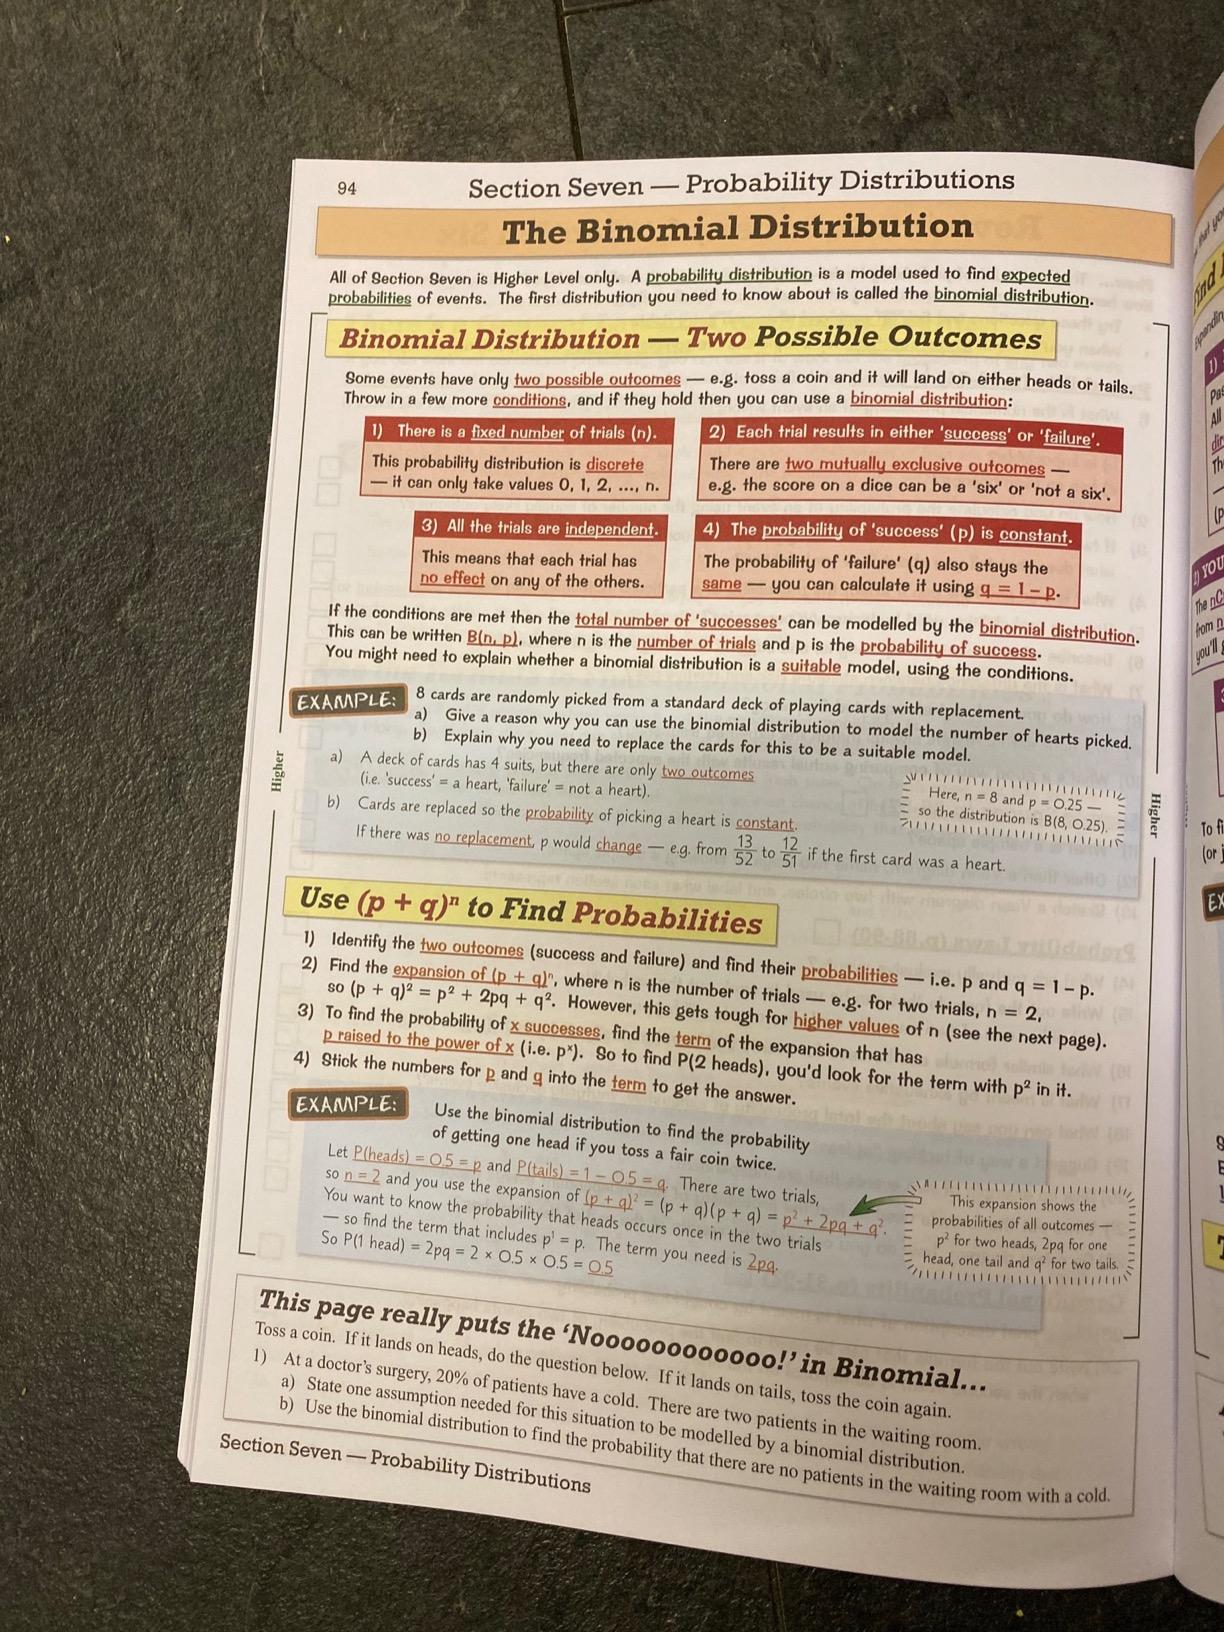
A lot of people buy a Workbook For Statistics 2026 expecting it to carry them through a semester on its own. That is not how it works. The workbook is a tool for drilling procedures until they stop feeling foreign. The actual learning happens when you sit down with a blank sheet of paper and try to reproduce the solution without looking at the worked example. I have watched students bounce between five different workbooks before picking one and sticking with it. The ones that survive are not the prettiest. They are the ones that match your course's actual notation, use the same distribution tables, and present problems that resemble what your professor will put on an exam rather than what some author thinks statistics should look like.
How I found the right Workbook For Statistics 2026 for my own needs
My first problem came up during an intermediate probability course that required using Laplace transforms on transform pairs. Most of the workbooks I scanned either skipped transforms entirely or buried them in an appendix with no worked examples. I spent two weeks wrestling with a problem involving a convolution integral before I realized the workbook was the weak link, not my understanding of the math. The workaround was simple. I bought the workbook strictly as a supplementary problem set and kept the main textbook open on the left page. That split layout saved me from re-reading three chapters just to find the notation the workbook used. If your course relies on a specific textbook, check whether the workbook's chapter order aligns. Mismatched sequencing is the fastest way to waste an evening. When you download or purchase a Workbook For Statistics 2026, skip the promotional videos and look at the table of contents. Cross-reference it against your syllabus before you invest any time. A workbook that covers bootstrapping and resampling methods is useless if your course stops at confidence intervals for means.
What a solid statistics workbook actually teaches you
It teaches procedural fluency. That means the ability to open a problem, identify the test or estimator being asked for, set up the hypothesis, compute the statistic, and interpret the result without second-guessing every step. Most beginners conflate understanding with recognition. You can follow a worked solution and still freeze when you see a new problem on an exam. The counter-intuitive part: working through more examples does not always improve your performance. What improves performance is deliberately mixing problem types. Do one hypothesis test for a proportion, then immediately do one for a difference of proportions, then jump to a chi-square goodness-of-fit. Your brain starts mapping the structural differences between similar-looking procedures instead of treating every problem as a template to fill in. Here is another nuance most people miss. The workbook will teach you how to calculate a t-statistic. It will not always teach you when not to use the t-test. I once helped a student who applied a paired t-test to data with four extreme outliers. The p-value came out significant at 0.03. The data violated the normality assumption badly enough that the result was essentially noise. A Wilcoxon signed-rank test would have been the appropriate move, and the workbook did not flag that scenario at all.
Get the Full Details

How to use the workbook without wasting time
Start each chapter by attempting one problem blind. Do not look at the example first. This takes longer and feels uncomfortable. It also reveals exactly what you do not know before you read the solution. Reading a worked example before trying it yourself creates a false sense of competence. You nod along and think you understand because the steps look logical in hindsight. When you get stuck, trace back to the exact step where your reasoning diverged. Write down the point of failure. Most students just skip ahead to the answer and move on. That habit compounds. By the third chapter you are confused about everything, and by the exam you have no actual recovery strategy. If your workbook includes appendices with answers, cover them. If the answers include only final numbers and no steps, that is a red flag. A workbook that does not walk through the setup and interpretation is doing you a disservice. You need to see how the author justifies each decision, not just verify that your arithmetic matches.
I keep a running list of my own errors in a separate notebook. I categorize them by type: formula misapplication, wrong distribution choice, arithmetic error, misreading the question. After two weeks of this, the categories stop being random. You start noticing patterns. For me it was always misreading the question. I would solve the right problem but for the wrong parameters. Writing that down three times in a row made me slow down on every problem afterward.
Limitations you should expect
No single workbook covers everything. A Workbook For Statistics 2026 will likely address the core undergraduate curriculum well enough. It will not cover advanced multivariate methods, Bayesian computation with MCMC, or modern machine-learning-adjacent statistics unless it is specifically labeled for that level. If your course goes beyond the standard material, plan to supplement with lecture notes or a reference text. Another limitation is the cost of self-study. Workbooks are cheap compared to tutoring, but they do not answer questions in real time. If you hit a wall at 11 PM and there is no one to ask, you will either stare at the problem for an hour or give up. Having a discussion group or office hours list is practically required. The workbook alone will not carry you through every obstacle. Sometimes the problems are too sanitized. Textbook datasets produce clean p-values and neat distributions. Real data is messy, incomplete, and often forces you into decisions the workbook never prepares you for. I dealt with a dataset once where half the responses were missing and the variable was ordinal. The workbook's approach for nominal data did not apply, and the nearest approximation for ordinal analysis introduced bias that I had to correct manually. The workbook never mentioned that edge case.
If you need something more application-heavy, pair the workbook with a software tutorial. R or Python exercises that replicate the workbook's problems will teach you how the same procedure looks outside the printed page. The transition from hand calculation to code usually takes about ten minutes per problem once you know the syntax, and it reinforces the theory in a way that pure paper work does not.