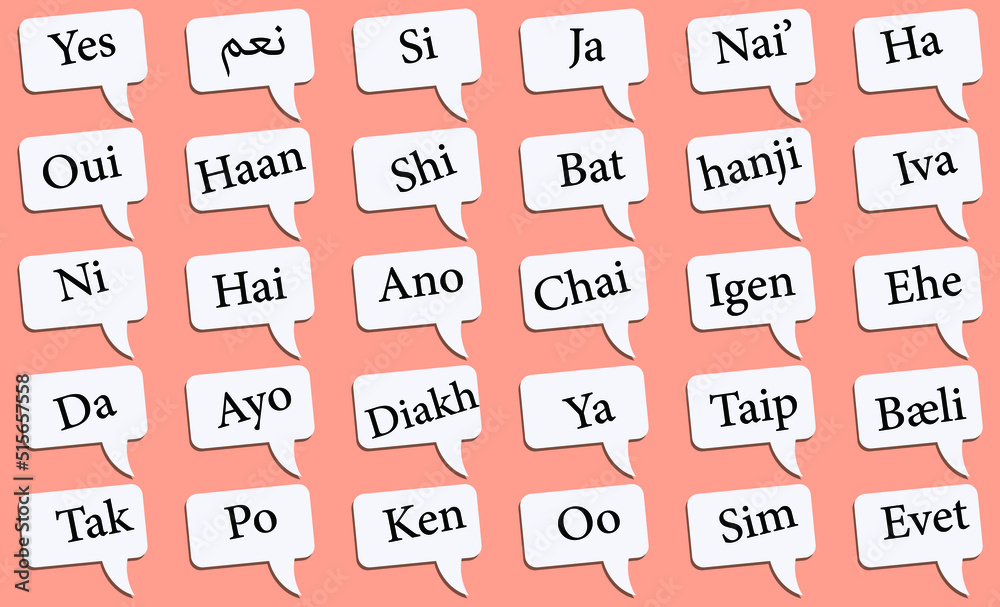
Using Yes In Every Language Copy Paste Resources as a Language Learner
I spent about three years trying to build a usable pronunciation library from the YES In Every Language video series. What I ended up with was a folder structure that actually works. Here is how I did it, and what went wrong along the way. The basic workflow starts with grabbing the audio from the YouTube videos. You do not need anything fancy. A browser extension like 4K Video Downloader handles the bulk of it, though you will find that some uploads have inconsistent volume levels between languages. I ended up running everything through a quick ffmpeg pass to normalize the audio to -14 LUFS so the files sounded consistent when played back in sequence. Once you have the audio, the copy paste part comes in. I created a simple spreadsheet with columns for the language code, the phrase, the IPA transcription, and a link back to the source video. The spreadsheet itself became my master reference. From there, I generated flashcards using Anki by exporting the CSV and importing it directly. That took maybe twenty minutes total for a full set covering twelve languages.
The real problem I hit was subtitle parsing. The auto-generated captions on those YouTube videos are garbage for anything beyond the most basic phrases. I stopped relying on them entirely. Instead, I cross-referenced with Ethnologue entries and the OpenLanguage data dumps to verify the transliterations. One specific issue: the Vietnamese "yes" entries had tone marks that got corrupted when I copied from YouTube subtitles into my spreadsheet. I had to manually re-enter about thirty of those entries after pulling the correct forms from a Vietnamese dictionary site. That saved me from building a flashcard deck with broken tones.
Why This Approach Actually Sticks
Most people try to learn from these videos by passively watching. That does not work for pronunciation. The format gives you a native speaker saying one word in isolation, which is exactly what you need for shadowing practice. But you have to actively pull the audio out and loop it. I set up a script that would randomly play one phrase every time I opened a certain folder on my desktop. Within about six weeks of doing that daily, I could produce recognizable Vietnamese and Turkish affirmatives without looking at text. The downside is that this only gives you one word per language. If you are trying to build actual conversational ability from this source alone, you will run out of material fast. It is useful for getting the phonetic shape of a language before you commit to a full course. It is not a course substitute. I learned that the hard way when I tried to use the collection as my only input for Italian and bombed the A2 listening section because I had never heard the word outside of isolation. What most people miss is that the real value is in the contrastive listening. When you put the Japanese, Korean, and Mandarin versions back to back, you start hearing the phonological boundaries of each language. That is where the repetition becomes useful beyond memorization. I kept a separate playlist in VLC just for side-by-side comparison and used it during my commute. Took about ten minutes a day.
Get the Full Details
If you want the actual audio files, the YouTube videos are publicly available and you can extract them yourself. I do not host them. The workflow I described is something you build once and then reuse for any new language the channel adds. The whole thing costs nothing if you already have the tools I mentioned. It took me roughly two hours to set up the first time, and after that adding a new language is about fifteen minutes of work.