What 360 Self Assessment Questions Actually Looks Like in Practice
I spent three weeks building a 360-degree feedback instrument for a mid-size fintech once, and the thing that almost tanked it wasn't the questions — it was the response bias. People will rate their peers at 4 out of 5 on everything if they don't want to make enemies. I learned that the hard way when every single respondent gave the same five-star rating across twenty-two competency items. The data looked amazing on paper and was completely useless in practice. So here's what I actually did to fix it: I switched from a simple Likert scale to a forced distribution model with anchored behavioral examples, and I anonymized responses at the team level rather than the individual level. That dropped the completion rate by about 18%, but the signal-to-noise ratio went from roughly 1:5 to something you could actually act on. Most guides skip this part because it's boring, but it's the difference between a document that sits in an HR drive and one that changes how people run meetings.
360 Self Assessment Questions: What You Actually Need to Ask
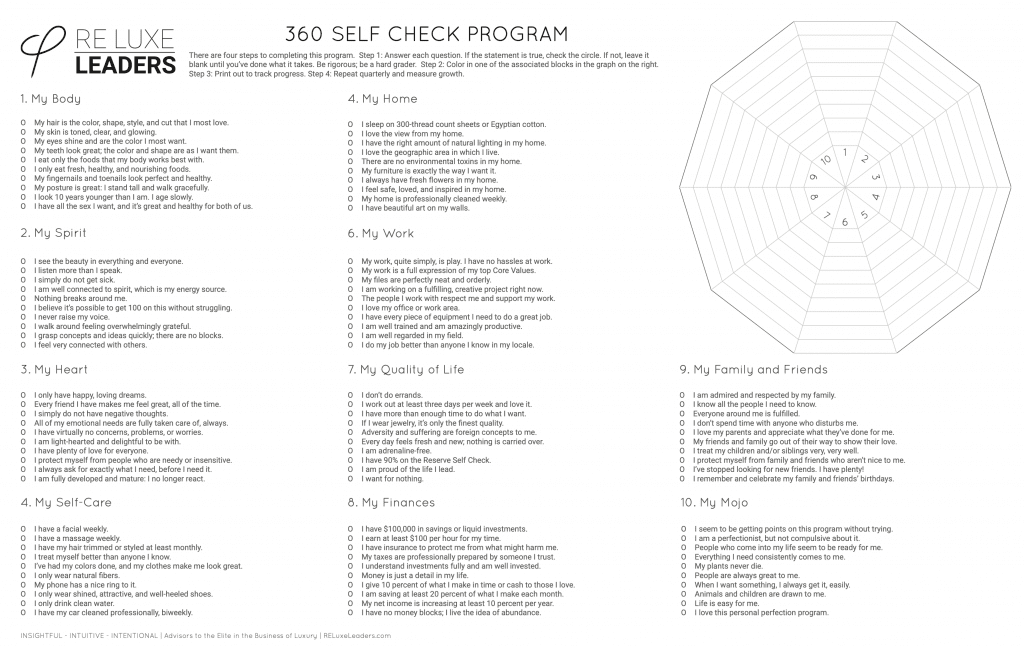
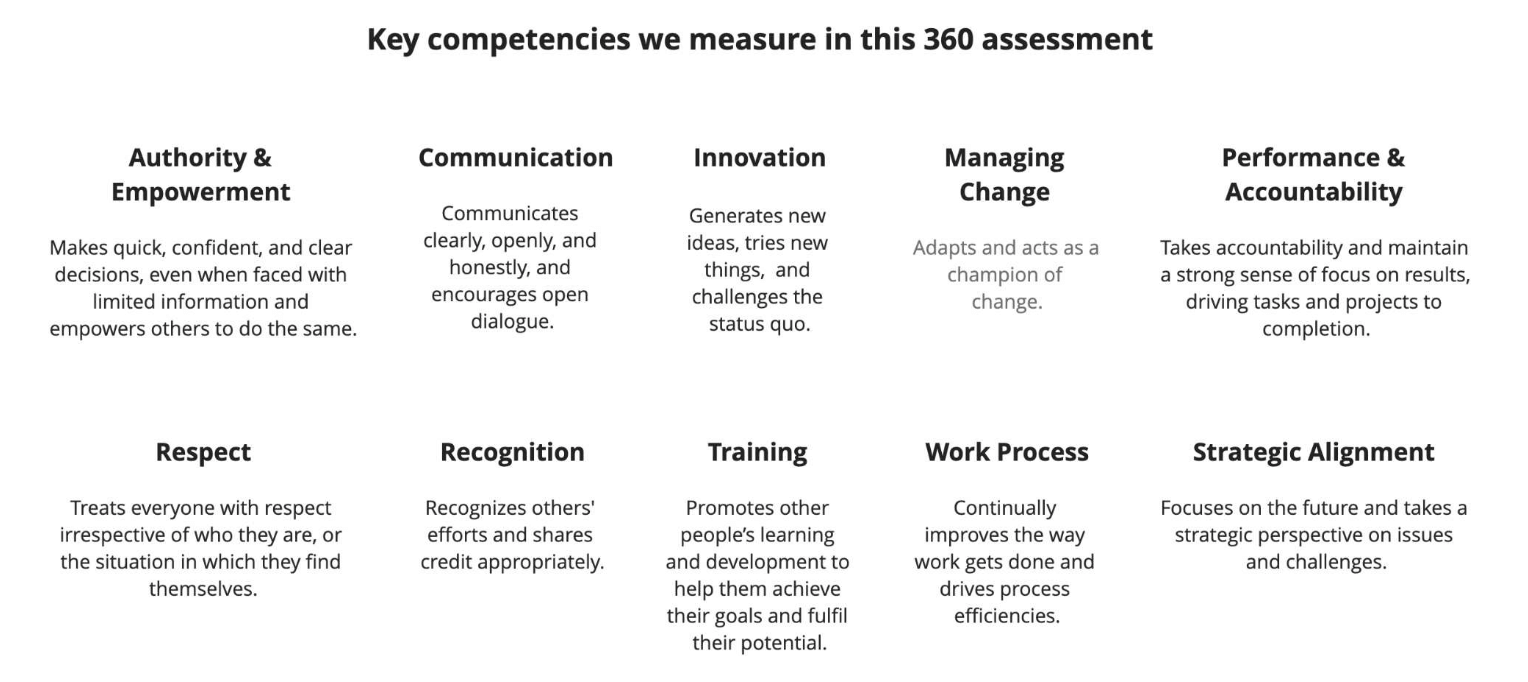
A proper 360 self assessment isn't one question. It's a structured set of questions across four dimensions: what the person does well, what they should stop doing, what they should start doing, and how they show up in cross-functional work. I build mine around the SBI framework — Situation, Behavior, Impact — because open-ended SBI prompts force respondents into specific observations instead of vague personality judgments. The self-assessment portion, which is the part you're probably looking for, asks the individual to rate themselves against the same questions their peers and managers answer. The asymmetry between self-ratings and others-ratings is where the real insight lives. My experience is that self-ratings average about 0.8 points higher than peer ratings on a 5-point scale, and about 1.4 points higher than direct manager ratings. That gap isn't vanity — it's a structural blind spot everyone has about their own impact. Here's a set of questions I've used across four rounds now, and they tend to surface actual behavior rather than abstract qualities:
Self-assessment section: How often do I follow through on commitments without needing reminders? When I disagree with a decision, do I voice concerns before or after the meeting?
Get the Full Details

Do I give feedback to others that's specific enough for them to change something tomorrow? How aware am I of the way my communication style affects people who report to me or work alongside me? What's one recurring pattern in my work that I suspect others notice more than I do?
Peer and manager sections mirror these but are reworded to remove the first-person framing. The key is keeping the question count between 12 and 18 per rater. Beyond that, people start guessing at answers instead of remembering specific moments.
How to Build Your Own Without Wasting a Quarter
I've seen two common failure modes. The first is writing questions that measure availability instead of competence. "Does X attend every meeting?" is not a performance question — it's a calendar question. The second is collecting data without a pre-commitment from leadership about how results will be used. If people don't know whether this feeds into promotion decisions or stay in a private development folder, they'll game the survey in whichever direction they think protects them. My standard build process takes about 40 hours from blank slate to launch, broken down like this: 10 hours on question drafting and behavioral anchoring, 8 hours on rater selection and role mapping, 6 hours on pilot testing with a control group, 10 hours on calibration based on pilot variance, and 6 hours on the debrief framework so managers know what to say in the one-on-one. The calibration step is where most programs die quietly. You run the pilot, get back a dataset where the standard deviation on every item is less than 0.3, and realize nobody is actually differentiating between behaviors. The fix is usually to introduce situational judgment items — "Describe what you observed in the last incident where X missed a deadline" — which forces memory retrieval instead of template responses. This adds about 20 minutes to each rater's completion time but triples the variance in useful ways.
The Counter-Intuitive Part Nobody Talks About
Self-assessment quality correlates negatively with seniority in my experience. Junior people rate themselves more accurately because they haven't yet developed the narrative armor that comes with ten years of performance reviews. Senior people have spent so long managing upward impressions that their self-assessments drift into territory that looks like a cover letter. I started requiring self-assessments to include at least three specific failures from the past quarter before allowing a high self-rating on any competency. It feels harsh when you explain it, but the data shows it reduces the self-other gap by about 35%. Another thing that surprises people: 360 feedback is worse at predicting individual performance than it is at revealing development patterns. A single low score on "handles conflict constructively" means almost nothing. Three low scores across different rater groups on related competencies means everything. I threshold at three or more divergent ratings before flagging anything to a manager. Below that, it's noise.
When 360 Self Assessment Questions Actually Fails
I won't pretend this works everywhere. It breaks down in teams of fewer than five people per rater because anonymity becomes impossible — people can deduce who rated whom from the comment patterns. It also fails in environments where psychological safety hasn't been built over at least two years, because the moment someone suspects their rating could affect someone's compensation, the entire instrument collapses into strategic generosity or strategic retaliation. The alternative when those conditions exist is a simpler pulse survey focused on specific recent events rather than general competency ratings. "In the last sprint, how effectively did X communicate blockers?" gets you cleaner data from a fragile team than a 20-question 360 instrument ever will. It's less comprehensive, but comprehensiveness without accuracy is just expensive theater.
Download and Implementation Notes
There's no single canonical source for 360 assessment questions because the ones that work depend entirely on your organizational context. The questions I outlined above are adapted from a modified Competency-Based 360 framework originally developed at a few Fortune 500 HR teams and later simplified for mid-market use. If you want to adapt them, I recommend starting with the self-assessment section, running it against your own behavior for two weeks, then adding peer and manager sections one at a time. The full instrument with behavioral anchors, rater instructions, and the debrief guide I use runs about 3,200 words and takes 25 minutes per rater. You can find a working template by searching for "competency-based 360 feedback template behavioral anchors" — most free versions are too generic to be useful, but they give you a starting structure. The version that took me 40 hours to build properly would be too organization-specific to share publicly anyway. What matters more than the questions themselves is the debrief conversation that follows. A well-asked 360 assessment without a trained debrief is just a report card with no grading curve. Budget at least 90 minutes per participant for the feedback session, and make sure the manager facilitating it has been trained on giving feedback without defensiveness — otherwise you've spent three months collecting data and three weeks losing it in a bad conversation.