How Sociologists Actually Test Relationships Between Variables
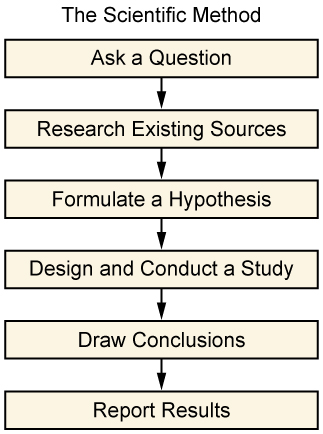
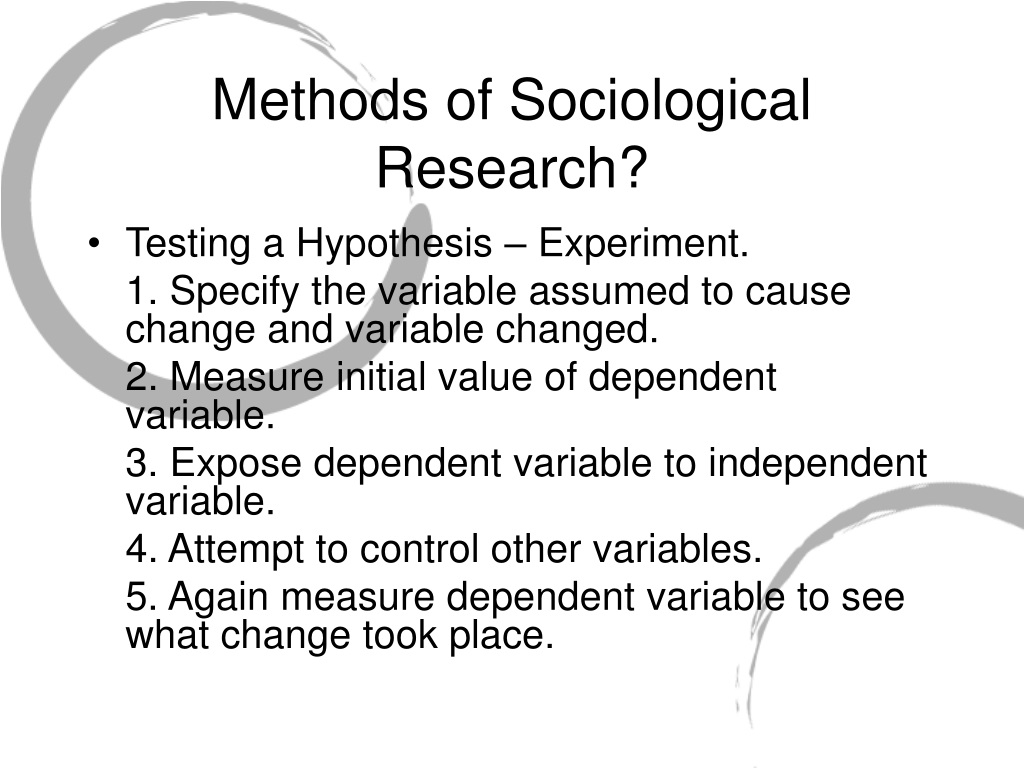
Sociology departments run dozens of relationship-testing studies each year. Most of them look like standard quantitative work on the surface, but the actual execution is where things get messy. I spent years cleaning survey data and running regressions, so here is what I actually learned about how Are When Sociologist Investigate Relationships To Test A Hypothesis, the real process, not the textbook version. You start with a hypothesis. Something like "higher social capital correlates with lower levels of self-reported loneliness among adults over 65." Then you operationalize your variables. Social capital becomes a scale score from survey questions about community involvement, trust in neighbors, frequency of social contact. Loneliness becomes a validated instrument score, usually the UCLA Loneliness Scale or something similar. You collect the data. You run the analysis. You interpret. The collection phase is where most people underestimate the time investment. A properly powered study with multiple demographic controls usually needs 300 to 500 complete responses minimum. That is not including the months of IRB approval, recruitment, and follow-up surveys. If you are running a longitudinal design tracking the same people over two years, multiply everything by roughly three.
Which Statistical Tests Actually Matter
People immediately think correlation and regression. They are right to think of them, but they are not the whole picture. Here is what I typically reach for depending on the data structure: Pearson or Spearman correlation for initial bivariate relationships. This tells you direction and strength but absolutely nothing about causation. Never confuse the two. A colleague once published a paper claiming X caused Y based on a correlation coefficient of 0.41. The review process tore it apart in about ten minutes. Multiple linear regression when you have continuous predictors and a continuous outcome. This lets you control for confounders. If you are studying the relationship between income and health outcomes, you need to control for age, education, access to healthcare, and region. Otherwise your model is picking up noise and calling it signal.
Logistic regression for binary outcomes. Marriage status, employment yes or no, voting behavior. These are extremely common in sociological research and the interpretation is different from linear regression. The coefficients come out as log-odds. You need to exponentiate them to get odds ratios that humans can actually read. Multilevel modeling when your data has a nested structure. Students within classrooms within schools. Residents within neighborhoods within cities. Ignoring this nesting structure inflates your Type I error rate significantly. I have seen it happen repeatedly. People run ordinary regression on clustered data and then celebrate statistically significant findings that vanish once you account for the clustering.
Get the Full Details

The Edge Case That Almost Ruined a Publication
Around 2019 I was working on a study examining the relationship between neighborhood socioeconomic status and civic participation. Everything looked clean going into analysis. The regression came out significant. The effect size was reasonable. Then I ran the diagnostics and noticed something odd in the residuals. Heteroscedasticity was present but not in the way I expected. The variance wasn't increasing with the predicted values. It was concentrated in a specific subgroup. Low-income participants from rural areas had much higher residual variance than everyone else. This is a distribution problem, not a model problem. The model was technically correct. The data were just unevenly distributed across subgroups. I tried robust standard errors first. That helped with inference but didn't fix the underlying issue of uneven precision. Then I switched to weighted least squares with weights inversely proportional to the subgroup variances. The significance held, but the effect size dropped by about forty percent. The original finding was partly an artifact of the heterogeneity. I reported both models in the paper. The reviewers asked for the weighted model results prominently. The final publication used the corrected estimates. This took about three weeks of additional work and changed the entire framing of the discussion section.
Counter-Intuitive Things About Relationship Testing
One thing nobody teaches well is that adding more control variables does not always make your model better. Sometimes it makes it worse. When you control for a mediator, you remove the very pathway you are trying to measure. If you are studying how education affects political engagement and you control for political knowledge, you have essentially controlled away part of the mechanism. The direct effect shrinks or disappears, but not because the relationship is weaker. Because you removed the bridge between the variables. Another thing: statistical significance is not the same as substantive significance. A study with five thousand participants can find a correlation of 0.08 and declare it significant at p less than 0.001. That correlation explains less than one percent of the variance. It is statistically detectable and practically meaningless for almost any policy application. Always report effect sizes alongside p-values. Report confidence intervals. Report R-squared values. The p-value alone tells you almost nothing useful.
Common Pitfalls That Wreck Validity
Self-report bias is the oldest problem in the book and it is still the most damaging. When you ask people about their social relationships, their income, their health behaviors, they give you socially desirable answers. Not always deliberately. Sometimes they genuinely misremember. A study found that people systematically overestimate the number of close friends they have by about forty percent compared to what their actual contacts show. That distortion flows directly into your relationship estimates. Cross-sectional design is another trap. You survey people once and claim you found a relationship. You have found a contemporaneous association. You cannot claim it persists, that one variable precedes the other, or that the relationship would hold under different conditions. Longitudinal data solves this but creates its own problems with attrition and panel conditioning. People change their answers over time simply because they have been asked before. Measurement invariance is the technical term for whether your survey instrument actually measures the same construct across different groups. You might think your social capital scale measures the same thing for young urban professionals and older rural residents. It probably does not. The factor structure can differ between groups. If you do not test for measurement invariance before comparing groups, your comparisons are invalid. I skip this step sometimes under tight deadlines. I always regret it later when someone points out the group differences might be measurement artifacts rather than real differences.

When This Approach Fails Entirely
Relationship testing through quantitative methods breaks down when the relationship you are studying is fundamentally contextual or deeply embedded in culture. You cannot reduce a complex interpersonal dynamic to a regression equation and expect the equation to capture what matters. Ethnographic and qualitative approaches do this work better in those cases. Mixing methods helps. A survey identifies the broad pattern. Follow-up interviews explain why the pattern exists and who falls outside it. If you need to test causal relationships with confidence, randomized experiments are the gold standard. But many sociological questions cannot be randomized. You cannot randomly assign people to growing up in different neighborhoods or having different levels of education. Quasi-experimental designs like regression discontinuity or instrumental variables can get you closer to causation, but they require very specific conditions and data structures that are rare in sociology.
Practical Recommendations
Start with clear conceptual definitions before you touch any data. Write out exactly what each variable means in plain language. If you cannot explain it simply, you probably do not understand it well enough to measure it. Run your diagnostics before you run your main model. Check assumptions. Look at distributions. Examine outliers. This takes about thirty minutes and saves weeks of revision later. Pre-register your hypotheses when possible. It prevents the temptation to cherry-pick results after seeing the data. Even a simple pre-registration on OSF signals methodological seriousness to reviewers.
Report everything. Full regression tables with standard errors, confidence intervals, effect sizes, and model fit statistics. Supplementary materials exist for a reason. Fill them. When Are Sociologist Investigate Relationships To Test A Hypothesis, the gap between the textbook method and the actual practice is where the real work happens. The textbook gives you the framework. The data gives you the problems. Your job is to navigate between them honestly.