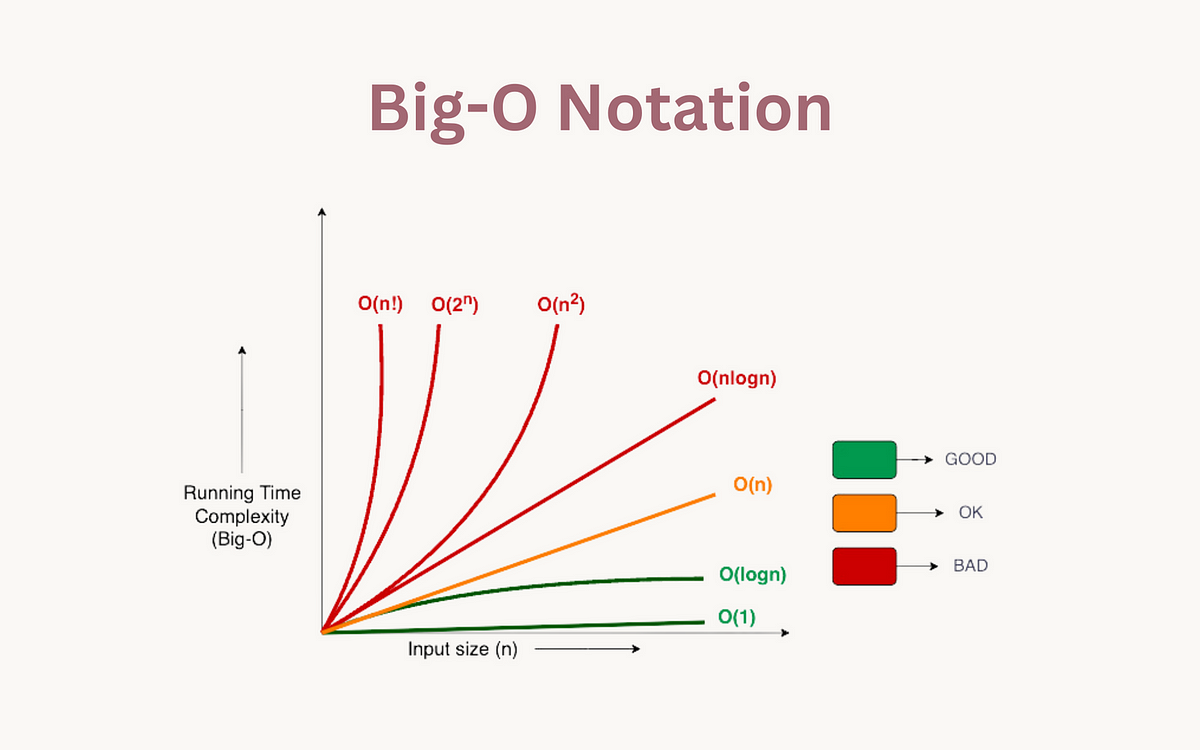
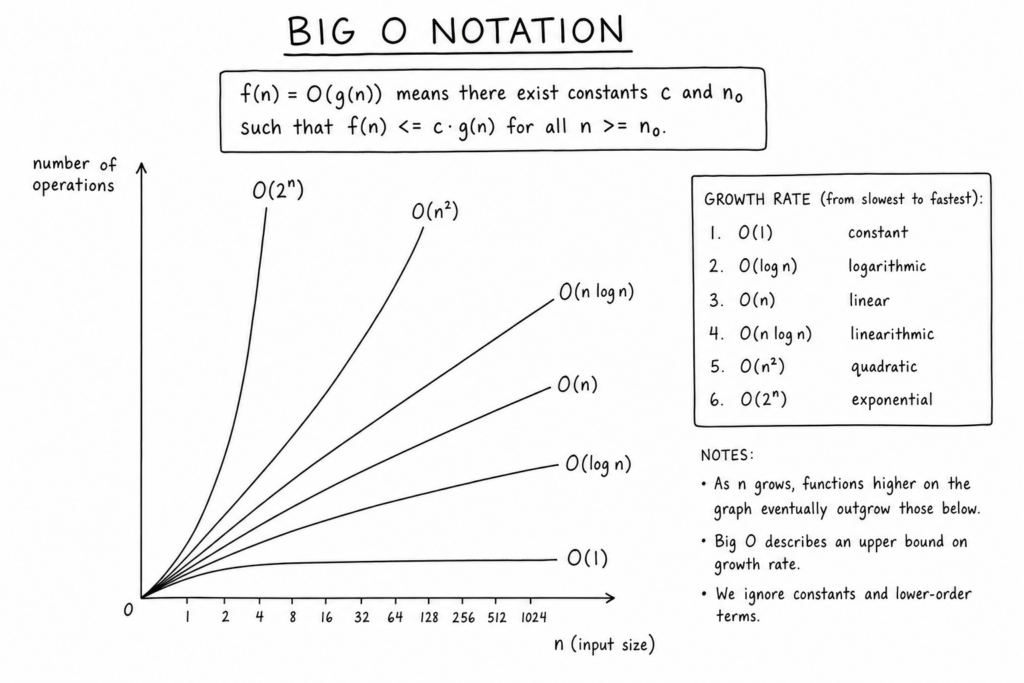
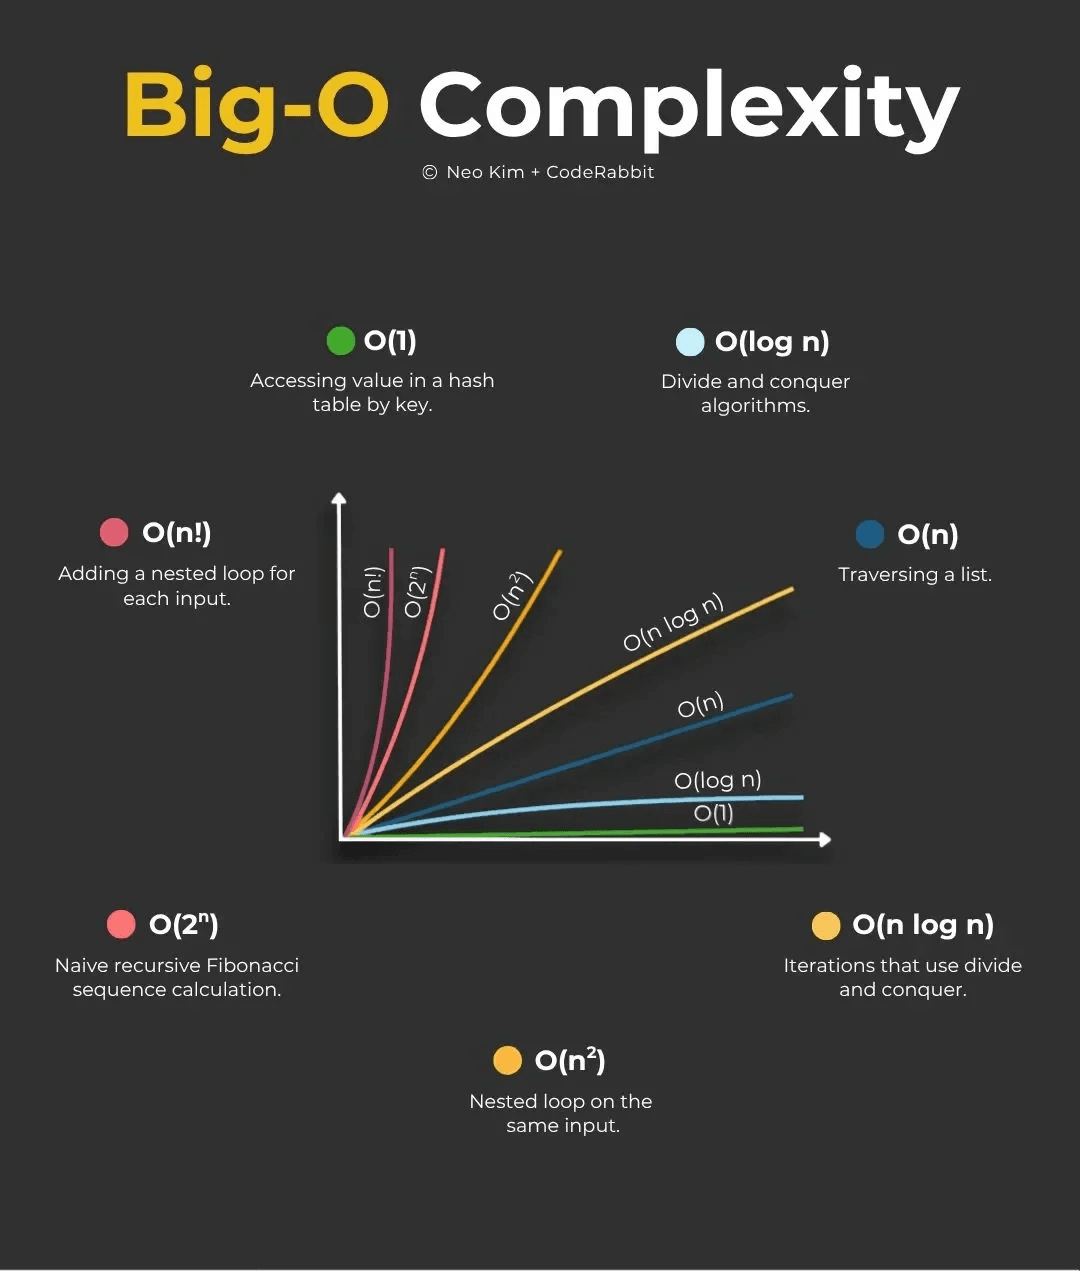
Most people learn Big O notation by memorizing a list of complexity classes and then trying to spot them in code. That approach works fine for introductory courses but falls apart quickly when you're actually reading through a codebase at 11pm before a deployment window. I've seen engineers struggle with real systems because they understood the definitions but couldn't apply them to messy, real-world code. The gap between knowing what O(n log n) means on paper and spotting it in a nested loop that also happens to call an external API is wider than most tutorials admit.
Big O Notation Practice: What Actually Matters
The core idea behind Big O notation is measuring how your algorithm's runtime or space usage scales as the input grows. It's not about counting exact operations. It's about identifying which part of your algorithm becomes the bottleneck when the input gets large enough that smaller terms become irrelevant. Constant factors don't matter here. If you have a function that runs in 3n + 5 time, it's still O(n). The constant factor of 3 disappears because it doesn't change the growth rate.
I want to address something most beginners miss. Big O gives you an upper bound, which means it tells you the worst-case scenario. That's useful, but it's also limited. An algorithm with O(n^2) worst case might run in O(n) time on most of your actual data. I worked on a graph traversal problem a few years ago where the textbook analysis suggested O(V^2) for a dense adjacency matrix implementation, but the actual datasets were sparse. By switching to an adjacency list representation, the effective complexity dropped to O(V + E), and the runtime on production data went from roughly 45 seconds down to under 800 milliseconds on a dataset of about 12,000 nodes. The textbook answer was technically correct but completely misleading for the problem at hand.
How to Analyze Code Step by Step
Start by looking at the outermost loop or recursion. A single loop that iterates through an array of size n is O(n). If you nest another loop inside it that also iterates through the same size n, you get O(n^2). Simple rule, but it gets more complicated fast.
Sometimes loops don't iterate through the full input. A binary search loop divides the problem in half each iteration, giving you O(log n). A loop that increments by a constant factor like i = i * 2 also gives logarithmic time. When loops are sequential rather than nested, you add the complexities instead of multiplying them. Two separate O(n) loops in a row give O(n), not O(2n), because constants drop out.
Recursion is where things get tricky. Every recursive call adds a new frame to the call stack, so you need to account for both the work done at each level and the depth of the recursion tree. A simple recursive factorial is O(n) time and O(n) space because each call waits for the next one to return before it can complete its multiplication. The space complexity matters here, and people often forget to track it.
Space complexity is the other half of Big O that beginners routinely ignore. It tracks memory usage, not just time. A function that creates a new array of size n inside a loop is O(n) space per iteration, but if it's not holding onto all of them simultaneously, the peak space might be lower. Auxiliary space refers to the extra memory beyond the input itself. When someone asks for the space complexity of an algorithm, they usually mean auxiliary space unless they specify otherwise.
I ran into a situation recently where a sorting function appeared to use O(1) space because it was sorting in place, but it was internally calling a recursive helper that allocated temporary arrays at each level. The actual space complexity was O(n log n), not O(1). The in-place sorting was a red herring because the temporary allocations weren't obvious from a surface-level read of the code.
Common Pitfalls That Waste Time
One mistake I see constantly is assuming that any loop makes something O(n). If the loop variable is being squared, cubed, or transformed in some other way, the relationship to n changes. A loop that runs while i * i < n executes roughly the square root of n times, giving you O(sqrt(n)). That's not O(n).
Another trap is ignoring the difference between the input size and a parameter that's unrelated to the input. If you have a function that takes two parameters, m and n, and one loop goes to m while an inner loop goes to n, the complexity is O(m * n), not O(n^2). Calling it O(n^2) assumes m equals n, which is not always true and can be wildly wrong when m and n are different orders of magnitude.
Data structure choice changes everything. Looking up an element in a hash table is O(1) average case, but looking it up in a linked list is O(n). If you're doing repeated lookups inside a loop, using the wrong data structure can turn an O(n) algorithm into an O(n^2) one without changing a single loop. I've seen this happen in production. A caching layer was originally built with an array for lookups, and adding a simple index or hash map reduced query times from several seconds to under 50 milliseconds on a dataset of about 50,000 records.
There's also the matter of best case, average case, and worst case. QuickSort is O(n log n) on average but O(n^2) in the worst case. That worst case happens when your pivot selection is consistently bad, like always picking the smallest or largest element. Most implementations guard against this with randomized pivots or median-of-three selection, which brings the expected performance back to O(n log n). If you're analyzing an algorithm, you should know which case you're looking at and why it matters for your specific use case.
When Big O Isn't Enough
Big O notation has real limitations. It describes asymptotic behavior, which means it only becomes accurate as the input approaches infinity. For small inputs, constant factors and lower-order terms can dominate, and the Big O classification can be misleading. An O(n^2) algorithm with very small constants can outperform an O(n log n) algorithm with large constants when n is small. Merge sort and insertion sort is a classic example. Insertion sort is O(n^2) but often faster in practice for arrays under a certain size, which is why many production sort implementations switch to insertion sort for small subarrays.
Amortized analysis is another concept that comes up when simple Big O falls short. A dynamic array like a ArrayList in Java or a vector in C++ has O(n) worst-case insertion time when it needs to resize, but the amortized cost per insertion is O(1) because resizing happens infrequently. If you only look at the worst case, you'd think dynamic arrays are slow, but that's not what happens in practice.
I encountered a case where a team was rejecting a hash-based solution because the theoretical worst case was O(n) for lookups due to collisions. They switched to a balanced BST with O(log n) lookups, but the constant factors and cache behavior made the BST solution slower in practice by about 30 percent on their actual workload. The hash table's average case was far more relevant than its worst case for their data distribution. Understanding the collision profile of your data matters more than the theoretical bound.
Big O Notation Practice That Actually Sticks
The best way to get comfortable with this is to analyze real code, not textbook examples. Pick a function from your codebase or an open-source project and walk through it line by line. Identify every loop, every recursive call, and every data structure operation. Track both time and space separately. Don't stop at the first complexity you find. A function might have an O(n) loop and inside it create a data structure that does O(n^2) work. The overall complexity is O(n^2), and the O(n) part is noise.
Another practical exercise is taking an algorithm you know the complexity of and modifying it to make it worse or better. Change a linear scan to a nested scan and see how the complexity shifts. Remove a recursive call and watch the space complexity drop. This hands-on approach builds intuition faster than memorizing charts.
For learning resources, the classic algorithms textbooks like CLRS cover this rigorously, but they're dense. For a more practical angle, watching people derive complexity from real code on video platforms can be more helpful than reading formal proofs. You learn to spot the patterns faster when you see them applied to actual programs rather than abstract pseudocode.
The bottom line is that Big O notation is a tool, not a destination. It helps you reason about performance before you run into it, but it won't replace benchmarking and profiling when you're working with real systems. Know the limits of the notation. Use it to make informed decisions about data structure choices and algorithm design. And when the numbers don't match your analysis, trust the measurements over the theory.
Gallery Big O Notation Practice
Big-O Notation: Definition, Examples & Algorithm Complexity - Gaurav Tiwari
Big O Notation Cheat Sheet Poster | Data structures, Computer science learning, Data science ...
Big O Notation Cheat Sheet | PDF | Computing | Computer Science
EP132: Big O Notation 101: The Secret to Writing Efficient Algorithms
Big O Notation - Hướng Dẫn Từ A-Z | Dat Light's Blog