Why Your First Research Project Falls Apart at Step Two
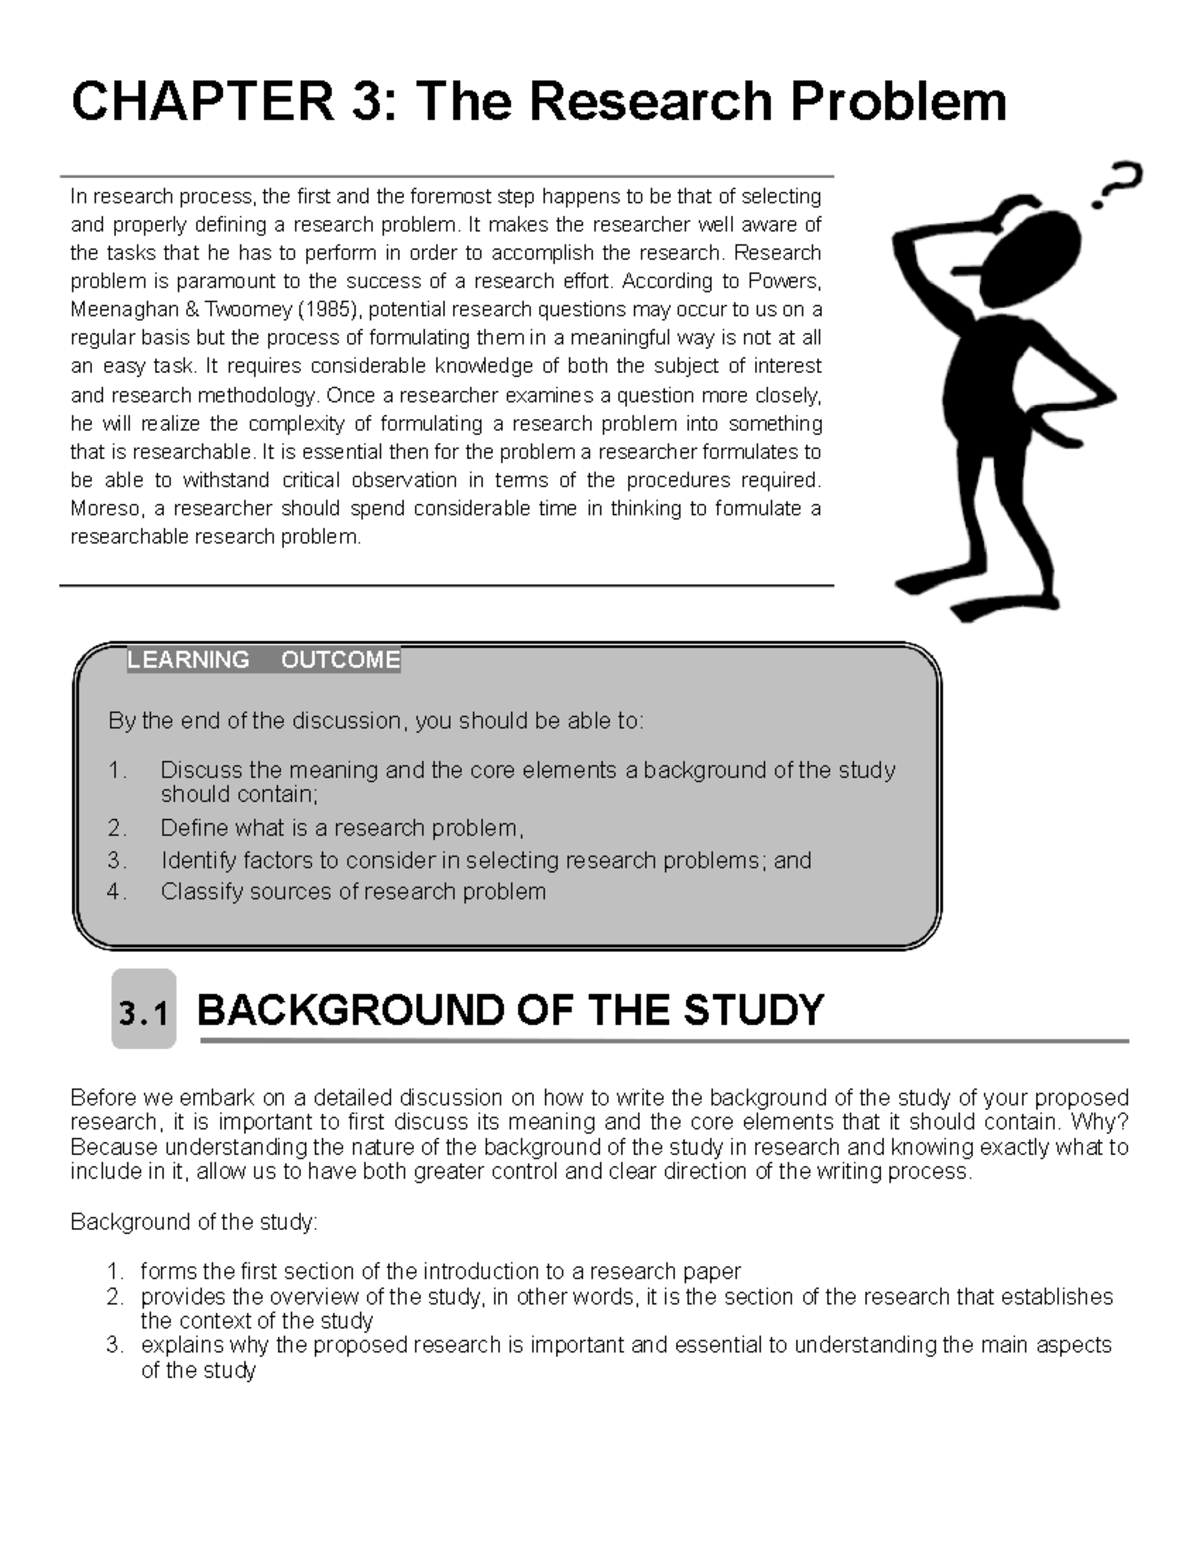
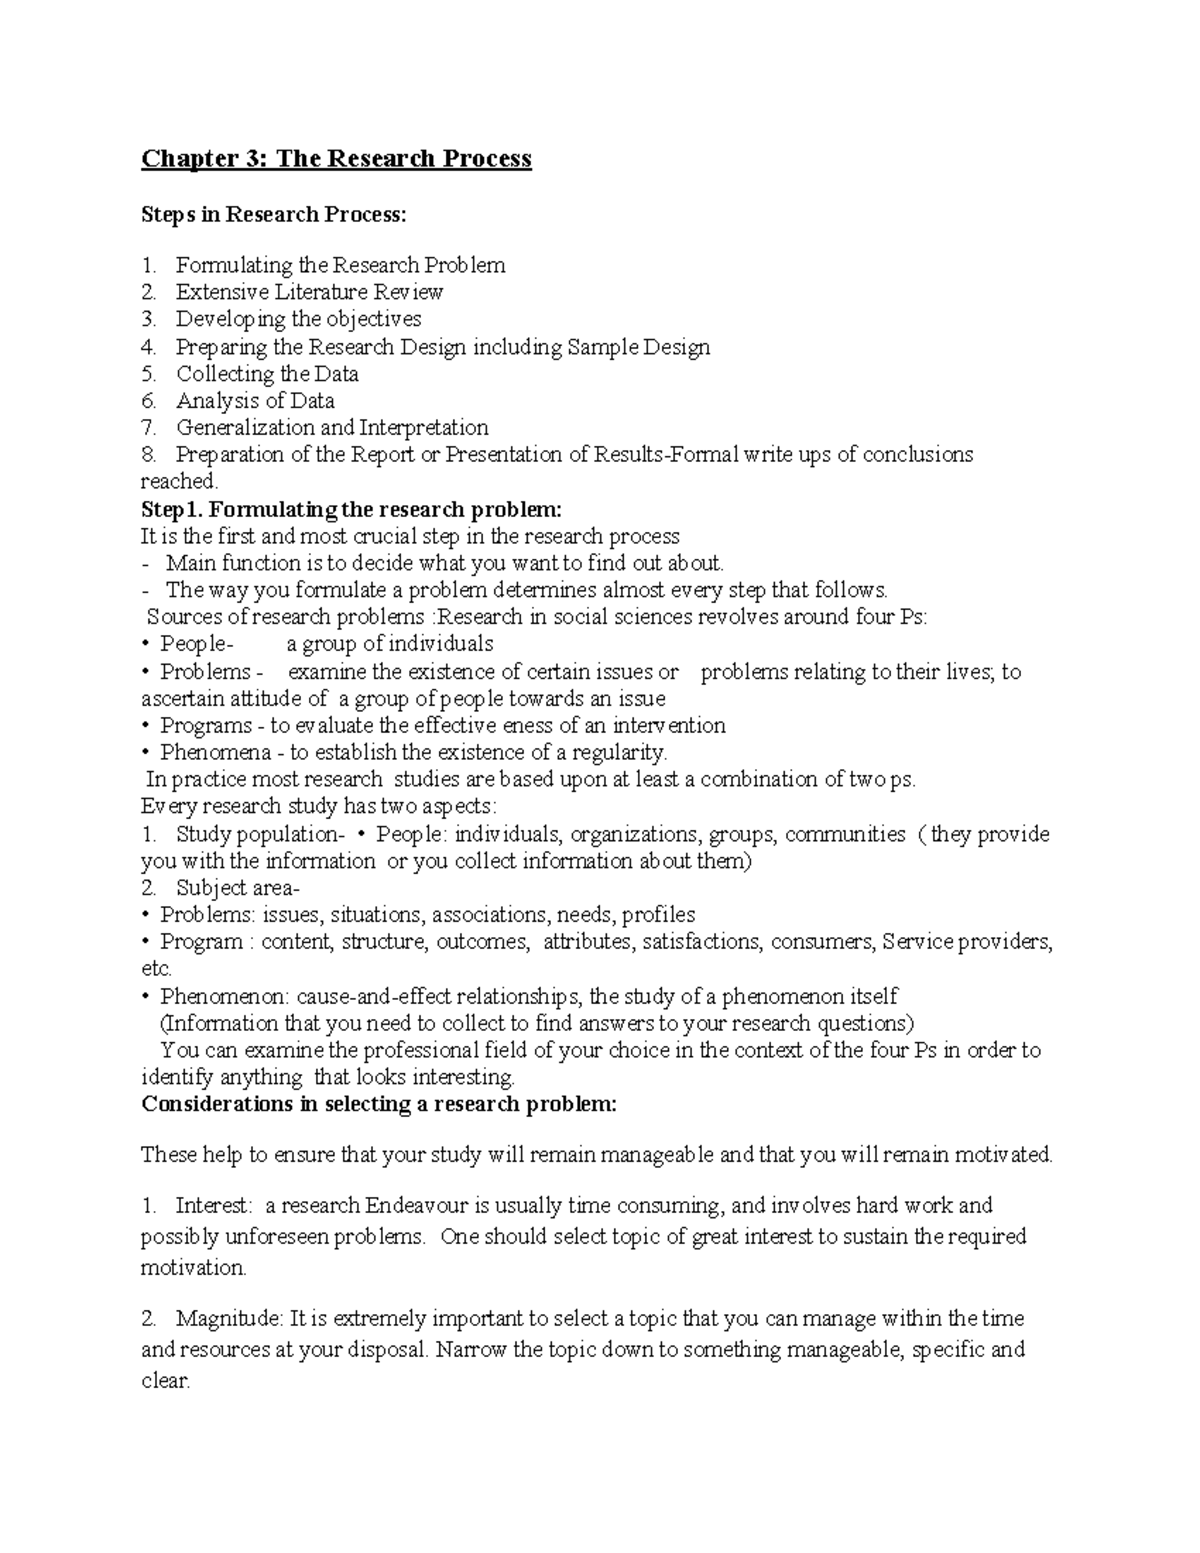
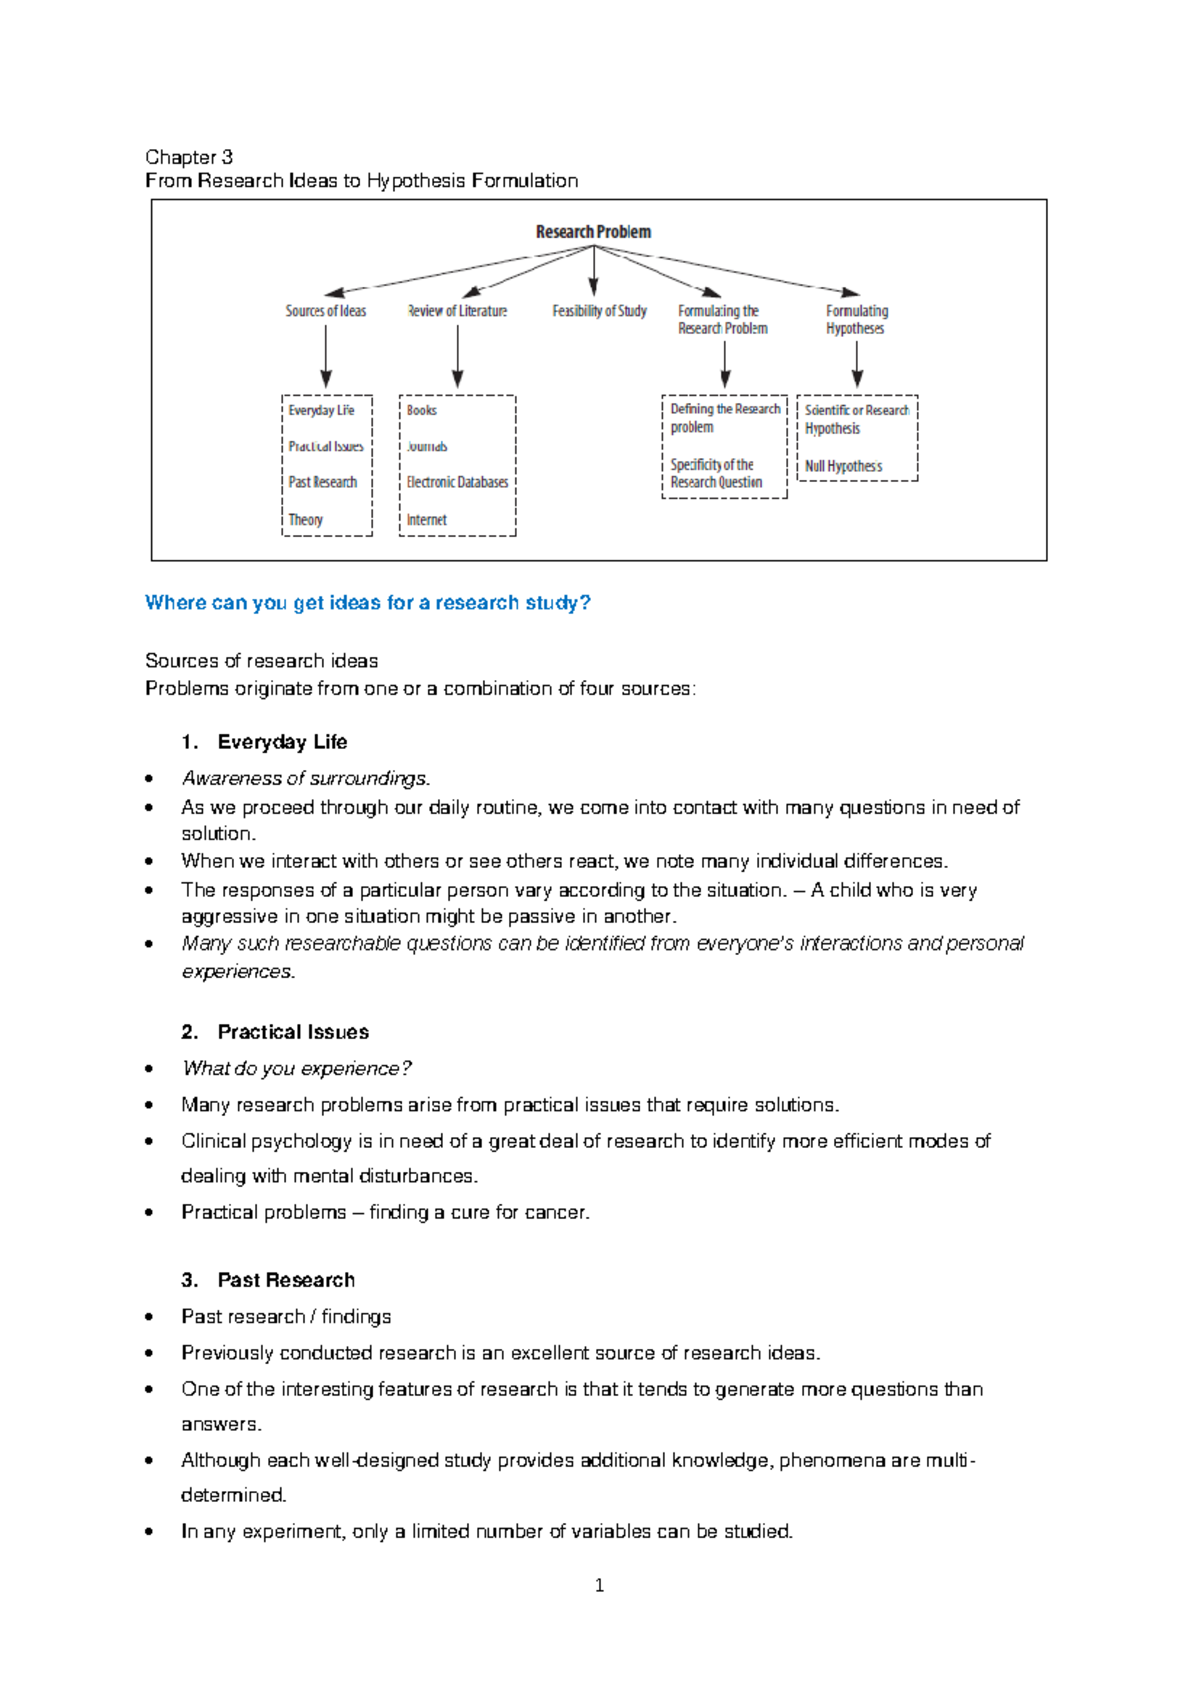
I spent three years trying to build a recommendation engine before I realized I was solving the wrong problem entirely. My initial dataset was clean, my model scored well on standard benchmarks, and then it completely failed when I tried to deploy it. The issue wasn't technical. It was that I had started with an algorithm instead of a pain point. That pivot is what Chapter 3 Starting Research From Real Life Problems is fundamentally about, and honestly, it is the single most undertaught concept in applied research methodology. Most people think research starts with a literature review. It doesn't. It starts with watching someone struggle with something that already exists. Not a hypothetical gap in the literature. A real human being wasting time, money, or cognitive load on an inadequate solution. I learned this the hard way when my graduate advisor made me spend two weeks just shadowing lab technicians who were manually logging sample data because the software interface was unintuitive. That observation directly shaped my dissertation framework and probably saved me from publishing something technically sound but practically useless. Here is the method, stripped of academic jargon. You find a problem. You document its friction points. You trace the causal chain backward until you hit the actual mechanism that causes the failure. Then and only then do you open a single paper. Too many researchers invert this sequence, which is why half the papers published each year solve problems nobody actually cares about.
What most people get wrong
The biggest mistake is assuming the visible symptom is the actual problem. When users complain that a system is "slow," that is not a diagnosis. Slow could mean poor database indexing, inefficient memory allocation, excessive network round trips, or a fundamentally flawed algorithm. I once spent six months optimizing query performance on a system where the actual bottleneck was a single synchronous file write happening on every request. The symptom looked like computational slowness. The reality was an I/O design flaw. If I had followed the surface complaint, I would have optimized nothing and published a paper about query tuning that no one needed. Another pitfall is falling in love with your solution before you properly characterize the problem space. This happens constantly in industry. A team identifies a workflow inefficiency, immediately sketches an app interface, and then spends months building features for problems they assume exist. I have been that team. We built a dashboard that no one opened. The original problem had been solved by a simple spreadsheet script nobody knew about because it was documented nowhere. The lesson is that your first prototype should be the thinnest possible thing that tests whether the problem is real, not whether your solution works.
A specific edge case I ran into
Last year I was researching automated anomaly detection in time-series sensor data for industrial equipment. The literature was saturated with deep learning approaches, and every paper used publicly available datasets like NAB or SWaT. I joined a team deploying models at a mid-sized manufacturing plant, and within the first month I discovered that the public datasets were misleading me. Real industrial sensors produce massive amounts of missing values due to intermittent connectivity, and the anomaly distribution is heavily skewed by seasonal maintenance cycles. The models that performed at 99.2% accuracy on benchmark data dropped to about 61% recall on actual production data within three weeks of deployment. The workaround was to stop treating the missing data as noise and start treating it as a signal. I spent two weeks documenting exactly when and why data dropped off, then built a lightweight imputation layer that flagged missingness patterns before passing anything to the detection model. Recall jumped to 87%. This is not a novel finding in retrospect, but it was a blind spot for me because I had started by reading papers instead of visiting the site.
Get the Full Details
When this approach does not work
Starting from real problems is not universally applicable. Pure mathematical research, theoretical physics, and certain areas of basic science have problem spaces that are not accessible through direct observation. You cannot shadow a quark or watch a prime number factor itself. In those domains, the literature-first approach is still valid. The framework I am describing applies specifically to applied, engineering, design, and systems research where human interaction is part of the problem domain. Another limitation is time. Problem immersion takes weeks or months before you can even frame a research question. Academic timelines rarely accommodate that. Industry timelines sometimes do, but not always. If you are under a three-month deadline, you may need to lean more heavily on existing literature and iterate quickly rather than doing deep observation. Just know that you are accepting a higher risk of solving a weak or mischaracterized problem.
How to actually begin
Pick a domain where you have some access. Workplaces, maker spaces, hobby communities, or even your own repeated frustrations count. Spend one week without trying to solve anything. Just document where people pause, where they make workarounds, where they complain. Then look for patterns across at least five separate observations before formulating a single research question. Write down what you observed, why it matters, and what evidence would convince you that your hypothesis is wrong. That last part is important because confirmation bias is the default state of anyone who has spent time thinking about a problem. Once you have that, read the literature with a purpose. You are no longer exploring. You are hunting for specific gaps, contradictory findings, or methods that could apply to the problem you have actually documented. This usually cuts your reading time from something like forty hours down to eight or ten because you know exactly what you are looking for.
Resources
There is no single canonical text for this approach because it spans multiple disciplines. What I found useful was Design Research Methods by Stephen Dunne and Fiona Raby, The Design of Everyday Things by Don Norman for the observation mindset, and various papers on ethnographic methods in HCI and software engineering. For the technical side, looking into how product teams in companies like Stripe and Linear document customer problems before writing code will give you practical templates. Nothing beats watching someone actually use a broken system for twenty minutes. The insights you gather then are worth more than two weeks of reading. I am not going to claim this method guarantees better research. It just guarantees that whatever you end up researching was worth researching in the first place. That alone is worth the extra time it takes.