What Actually Happens When You Start a Data Science Project
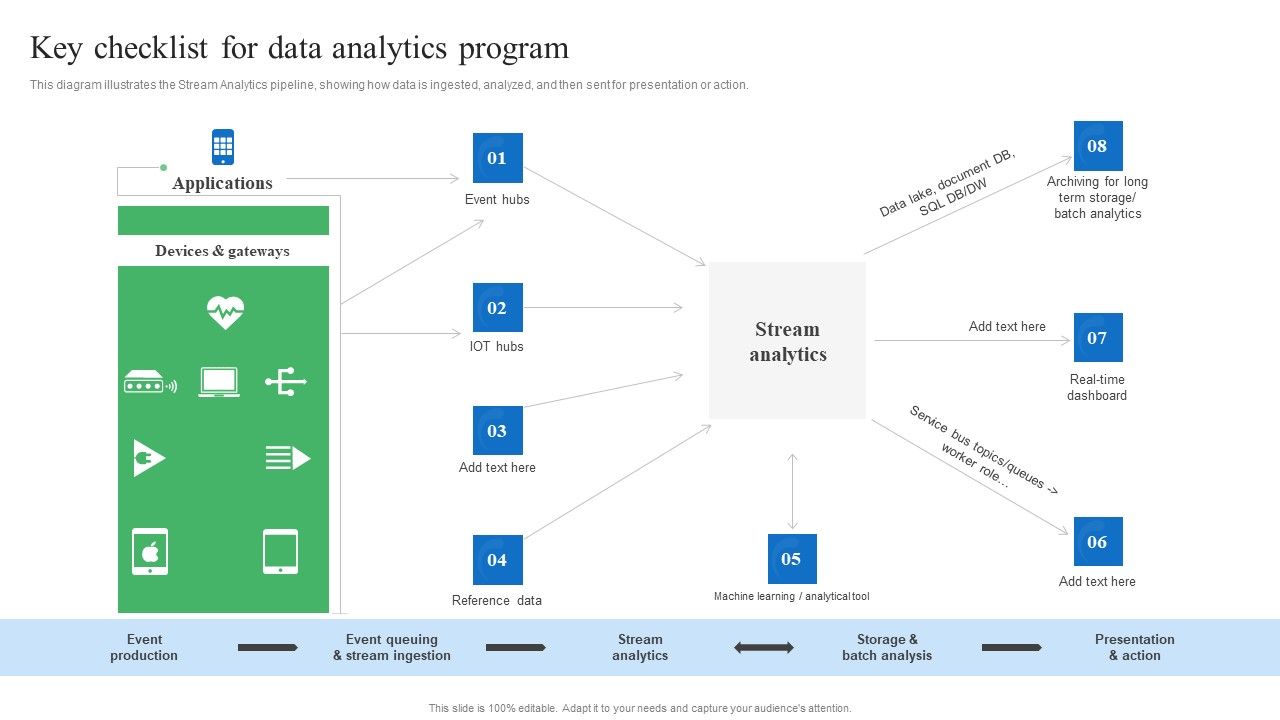
I spent three years watching teams skip the small stuff and then lose two weeks because they didn't. There's a routine that keeps things from falling apart. People call it a Checklist For Data Science Daily and most of them don't bother writing one down properly. The first thing I learned is that data science work is never just about the model. It's about the mess before and after the model. If you're starting a project cold without a structured approach, you will revisit the same decisions at least four times and waste a lot of time doing it.
Building Your Checklist For Data Science Daily
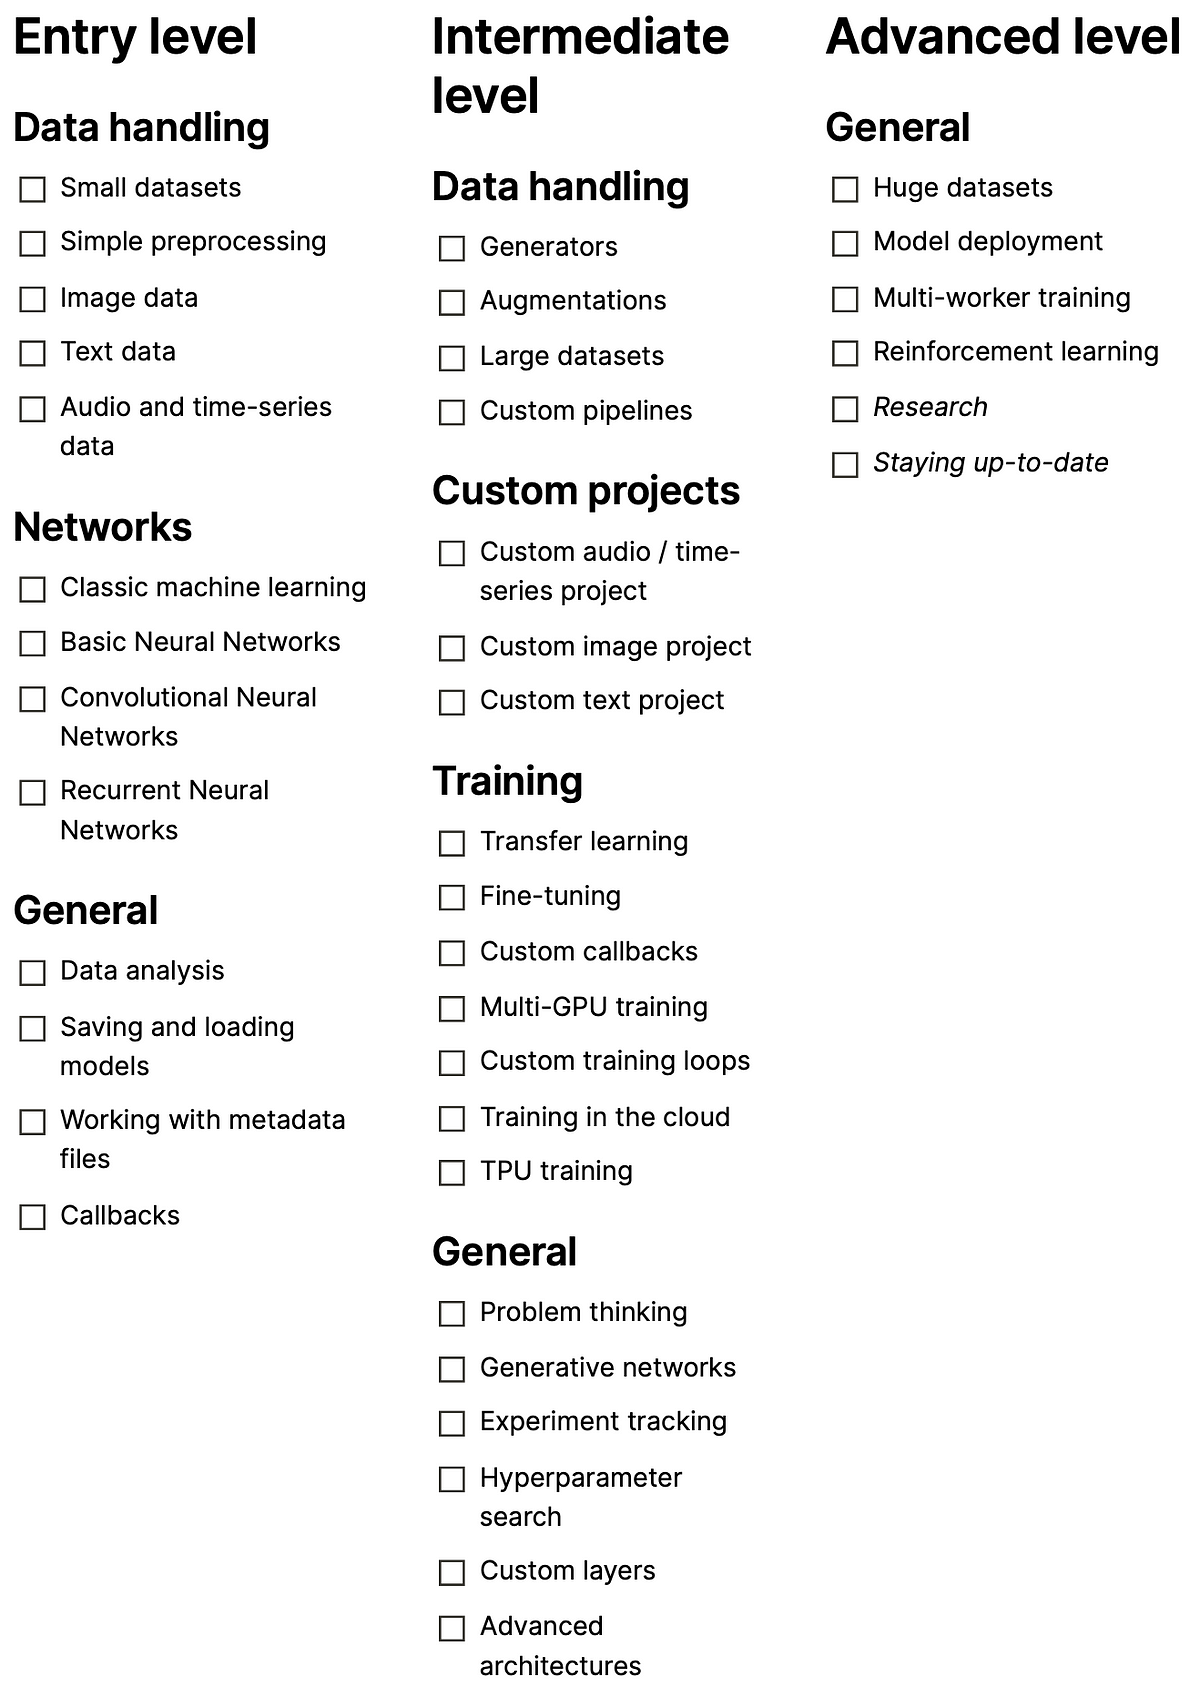
Here's how I set mine up. It lives in a markdown file in my project repo. Every project gets its own copy with sections pre-filled. The checklist isn't long. It's maybe 40-50 items total across phases, and you only hit a fraction of them each day. Start every session by confirming your data is what you think it is. I check these things: This takes maybe 10 minutes. The alternative is discovering at model evaluation time that your datetime column got parsed with the wrong timezone because someone updated an API field and nobody noticed. I've seen that happen. It costs a full day to trace.
Before any transformation goes into the pipeline, verify the output shape and dtypes. Log the before and after for every step. This matters more than people think because you can't debug a transformation later if you didn't capture what happened at each stage. I once spent six hours finding a data leak where an imputation step was using the test set mean because the train-test split happened after the preprocessing instead of before. The checklist would have caught that in thirty seconds on the first run. Document the random seed. Log hyperparameters. Record the exact version of every library. I know this sounds obvious but most people don't do it until they need to reproduce a result they already forgot how they got. Every training run should include a baseline model first. A simple logistic regression or decision tree. If your complex model can't beat the baseline, something is wrong before you even get to tuning. This saves hours of dead-end experimentation. I usually see this save my team about three to five hours per project cycle.
Get the Full Details
Evaluation Standards
Pick your metrics before you look at the results. Not after. This is where most projects go sideways. You train a model, look at accuracy, notice it's decent, then realize you're solving an imbalanced classification problem where accuracy means nothing. My checklist requires me to document precision, recall, F1, and the confusion matrix before I touch any ROC curves or feature importance plots. It adds maybe five minutes and prevents the embarrassment of presenting a model to stakeholders that performs worse than random on the minority class.
Deployment Readiness
This is the part nobody checks properly. Before anything goes to production I verify: I had a model deployed to production that silently started returning incorrect predictions because the upstream data format shifted by one field. The model accepted it without complaint. We lost about two weeks of dirty data before anyone noticed. Now my checklist has an explicit input schema validation step before any batch inference runs. It feels like overhead at first. You're in a flow state and you want to code, not fill out boxes. But the cost of skipping it compounds faster than filling it out. I used to treat it as a one-time setup. That stopped working when I started managing multiple projects simultaneously. The checklist only pays off when it's consistent, not when it's occasional.
There's also the problem of checklists becoming stale. I've had team members add items to their checklist and then never use them for months. The item list grew to sixty-something and nobody remembered half of them. The solution was cutting it back to the items I actually use daily and moving the rest to a reference document. Now it's maybe thirty-five items and I go through it in about fifteen minutes each morning.
The Practical Setup
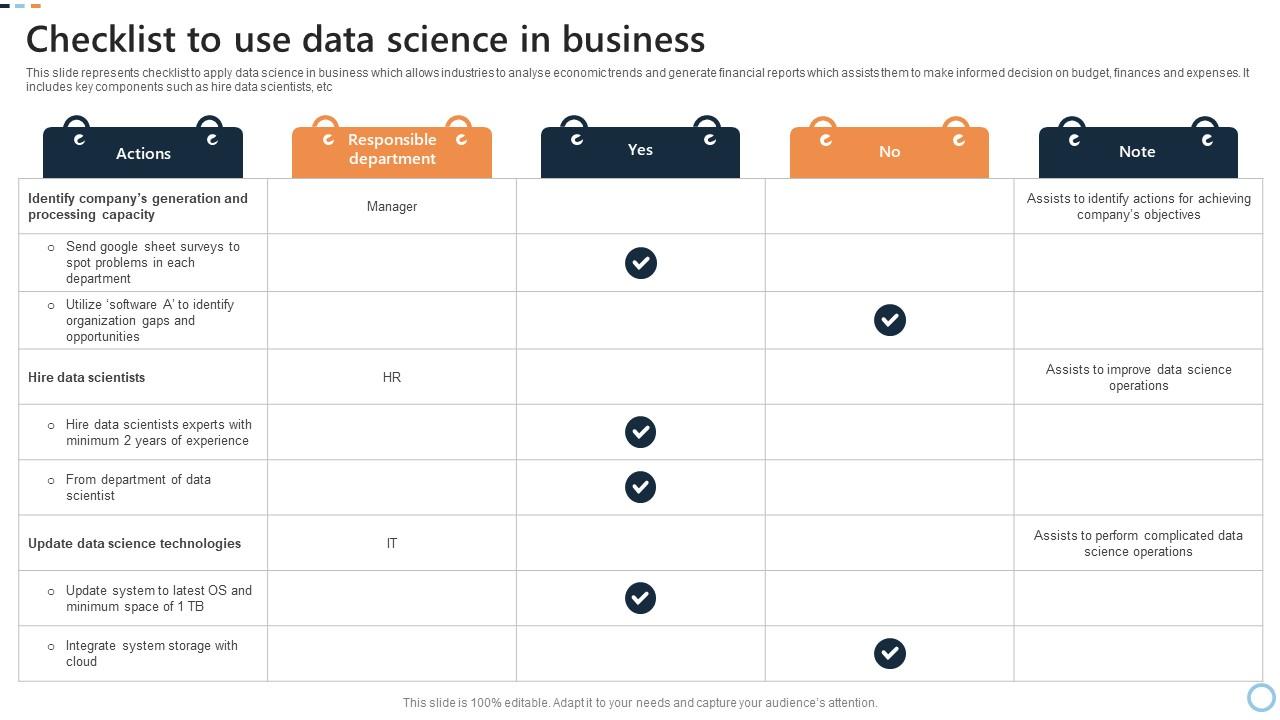
The easiest way to start is with a simple template in your project directory. Don't overthink it. Use something like this structure: Phase 1: Data Understanding Source verified. Quality issues logged. EDA plan written.
Phase 2: Preprocessing Features defined. Split strategy chosen. Pipeline built and tested on holdout. Phase 3: Modeling
Baseline established. Model trained. Metrics recorded. Phase 4: Deployment Model packaged. API endpoint validated. Monitoring active.
That's it. You add detail as the project demands. The template gives you the skeleton so you're not starting from zero every time. I copy mine into new projects and spend about five minutes customizing it rather than building from scratch.
Common Mistakes to Avoid
Don't make the checklist a formality where you tick boxes without actually doing the work. I've seen people rush through the validation steps and miss obvious corruption in the dataset. The checklist is meant to slow you down at the right moments, not speed through everything. Don't make it so detailed that you can't finish it. A checklist that takes two hours to complete is not a checklist, it's a document. Keep it scannable and actionable. One line per item. Verbs, not descriptions. Don't keep items that don't apply. If you're only doing exploratory analysis and never deploying, you don't need deployment readiness items. Tailor it to what you're actually doing. I've trimmed mine down significantly as my work shifted from research projects to production systems and back again.
Tools That Help
I use plain markdown files alongside a Makefile that runs validation checks automatically. The checklist items that require manual verification stay in the markdown. The ones that can be automated run as scripts. This hybrid approach keeps the checklist honest because you're not marking something complete until the automated check passes too. If you want something more structured there are tools like MLflow for experiment tracking and great expectations for data validation, but those add complexity. Start simple. The checklist itself is the tool. Everything else is optional. I keep a public template somewhere on GitHub if you want to grab one and modify it. Most of what I've described above is in there. It's not perfect but it's been through more projects than I care to count and it still catches things I'd otherwise miss.


