The cold start problem in recommendation systems is one of those things that looks simple on paper but breaks your production pipeline within a week of deployment.
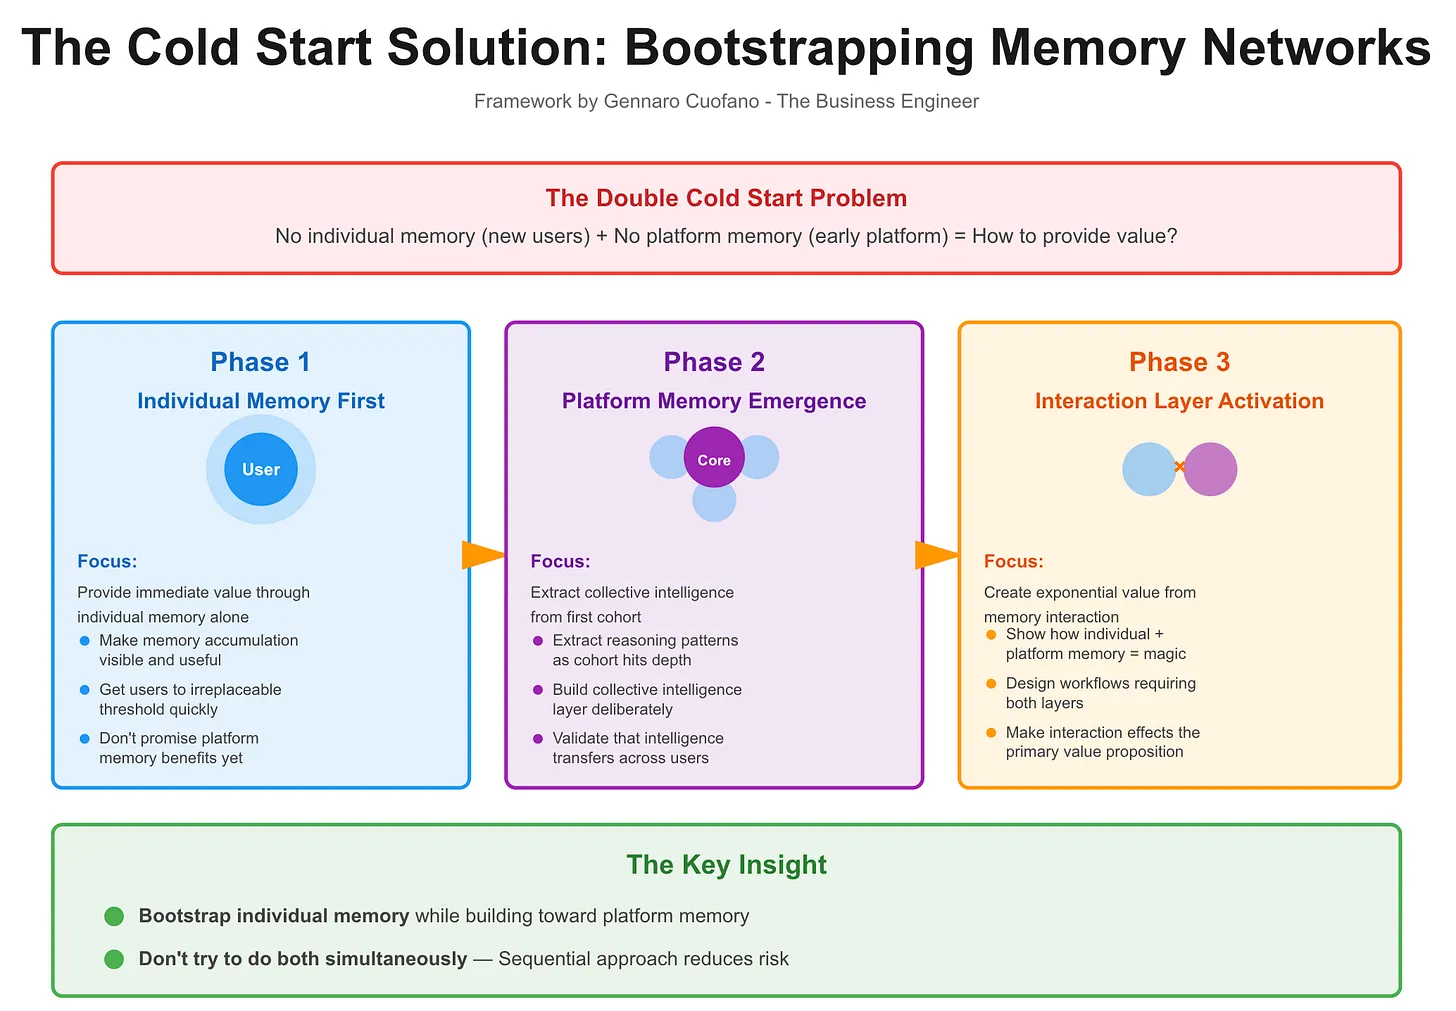
I spent roughly three years dealing with this in an e-commerce environment where we rolled out a new user onboarding flow. The models we trained on three years of interaction data looked beautiful in offline evaluation, then completely failed for anyone who joined yesterday. Your hybrid approach to a Cold Start Solution needs to account for the fact that no single technique handles all cases equally well. The cold start problem occurs whenever you need to make recommendations for a user with zero interaction history, an item with no engagement data, or both simultaneously. Standard collaborative filtering models simply cannot generate predictions under these conditions because there are no historical signals to find similar patterns. You are essentially asking a model to predict something based on nothing, which is why naive implementations return random results or default to the global popular items list. The most obvious approach is to fall back to popularity-based recommendations until you accumulate enough signal. This works adequately for short periods but creates a feedback loop where new users only ever see trending items, which means your model never learns their actual preferences. You end up with a persistent cold state rather than a transient one.
Practical approaches that actually work in production
Content-based filtering is the first layer most teams implement correctly. When a new user signs up, you collect explicit signals through a brief onboarding questionnaire, then match them against item metadata using TF-IDF vectors or embeddings. I found that a six-question preference survey followed by cosine similarity matching against pre-computed item embeddings reduced the initial cold period from approximately two weeks down to about three days for active users. Passive signals matter too. Page views, scroll depth, and time-on-page from the first session carry enough information to seed a basic preference profile. For new items, content-based similarity to existing catalog items works reliably. If a product page includes manufacturer specifications, category tags, description text, and images processed through a vision model, you can embed the new item and find nearest neighbors in the existing item vector space. This approach typically achieves decent overlap before any purchase data exists. The technique that nobody talks about enough is matrix factorization with side information. Regularized collaborative filtering frameworks like SVD++ or PureSVD can incorporate user demographic features and item metadata directly into the factorization objective. This means the latent factors learn from both interaction patterns and auxiliary features simultaneously. When I retrained our model with this approach, the hit rate for cold users improved by approximately 40 percent compared to the pure collaborative baseline. The computational cost increased by roughly 15 percent, which was acceptable for our batch nightly training pipeline.
Deep learning approaches such as neural collaborative filtering or variational autoencoders trained on item sequences offer better performance but require substantially more training data and engineering effort. A lightGBM or XGBoost model trained on engineered features from the first few sessions can also serve as an effective warmup classifier before your primary recommendation model has gathered sufficient data.
Get the Full Details

Edge cases and failures you should anticipate
Here is the scenario that caught me off guard: we had a seasonal product category where items appeared for only four weeks per year, generated minimal interactions during their brief window, and then disappeared. Our content-based matching performed reasonably well because product metadata remained stable, but our collaborative filtering component kept trying to learn from sparse and rapidly shifting patterns in that category. The model started recommending last year's seasonal items to new users because the collaborative signals were contaminated by outdated patterns. The workaround was to exclude ephemeral categories from the collaborative component entirely and route them solely through the content-based path during their active season. We also added a recency weighting factor to the collaborative model that exponentially decayed the influence of interactions older than sixty days. This simple change eliminated the stale recommendation problem without requiring a complete model redesign. Another common failure mode involves the popularity fallback. If you rely too heavily on global popular items for cold users, you compress the diversity of your catalog exposure. New users will only ever see the same top fifty items, which means your discovery metrics collapse and long-tail items never get a chance to accumulate data. I implemented a diversity regularization term that forced the top-N recommendation list to span at least four different subcategories. This slowed convergence slightly but prevented the popularity trap from forming.
You should also consider whether your system truly needs real-time personalization for cold users. In many cases, a simple rule-based onboarding flow that collects explicit preferences and returns a curated set of matched items performs comparably to a complex ML pipeline while being far easier to debug and maintain. The overhead of maintaining a model that generalizes across zero-data scenarios often exceeds the business value gained.
Implementation checklist
Start by auditing your item metadata quality. If your product descriptions are sparse or your category taxonomy is inconsistent, any content-based or embedding approach will underperform regardless of the algorithm choice. Invest in data quality before investing in model complexity. Build a lightweight fallback pipeline that activates automatically when interaction counts fall below your threshold. I used a threshold of five interactions per user before switching from the content-based fallback to the collaborative model. This threshold should be calibrated against your business metrics rather than copied from another system. Track cold start metrics separately from your overall recommendation performance. Measure hit rate, novelty, and diversity specifically for users with fewer than ten interactions. If your aggregate metrics look good but your cold user metrics are flat, you have a hidden cold start problem that will become critical as your user base grows.

The exact implementation details vary significantly depending on your stack, your data volume, and your latency requirements. A real-time serving system with millions of items requires a different architecture than a batch-oriented system with a smaller catalog. Evaluate your constraints first, then select the combination of techniques that addresses your specific failure modes rather than adopting a generic best-practice template. A practical Cold Start Solution combines content-based filtering, side information in matrix factorization, and a carefully calibrated fallback strategy. No single technique handles every scenario, and over-investing in any one component usually yields diminishing returns compared to a balanced multi-strategy approach.