How I Actually Use Scatter Graphs for Correlation (and Where It Goes Wrong)
Most people learn correlation in statistics class and then never think about it again until they're staring at a spreadsheet of customer data at 11pm trying to figure out why Q3 revenue dropped. The problem isn't understanding the concept. The problem is knowing what to do when the visual doesn't match the number, when you have three variables swirling around each other, and when your boss says "just show us the relationship" before you've even cleaned the data. I used to build scatter plots in Excel the old way — dragged points manually, added trendlines, slapped an r-squared value in a text box. That worked fine for class projects and basic presentations. It falls apart fast once you start working with actual business data that has outliers, missing values, and points scattered so densely you can't see individual dots anymore. I switched to Python a few years ago. It's not glamorous but it handles edge cases better and produces consistent output.
Correlation In Scatter Graphs
The Basics Without the Textbook Version
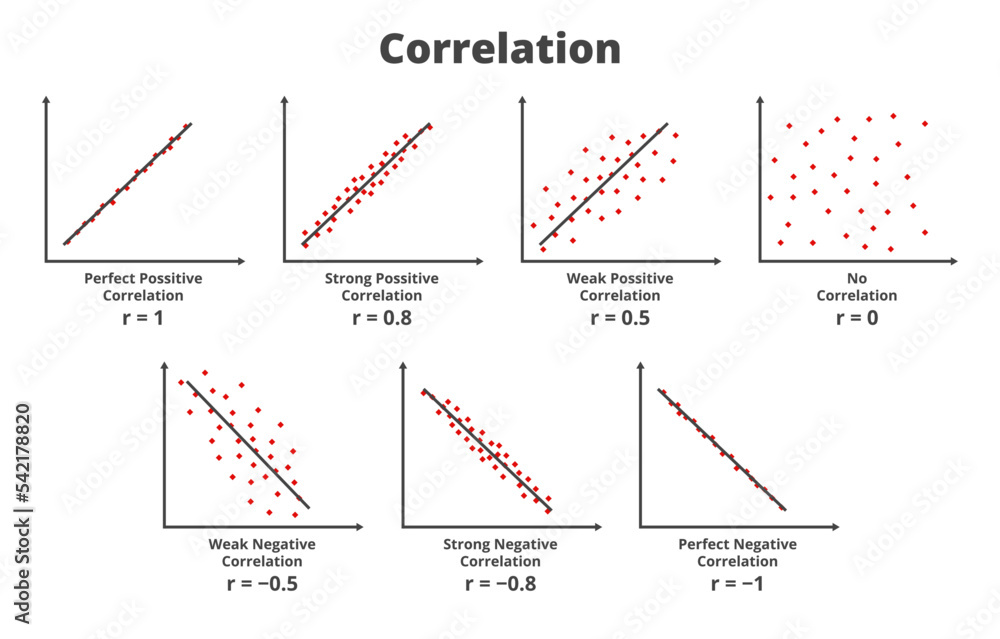
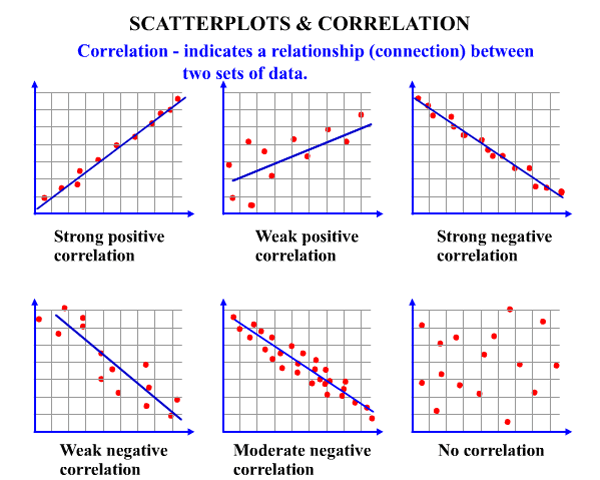
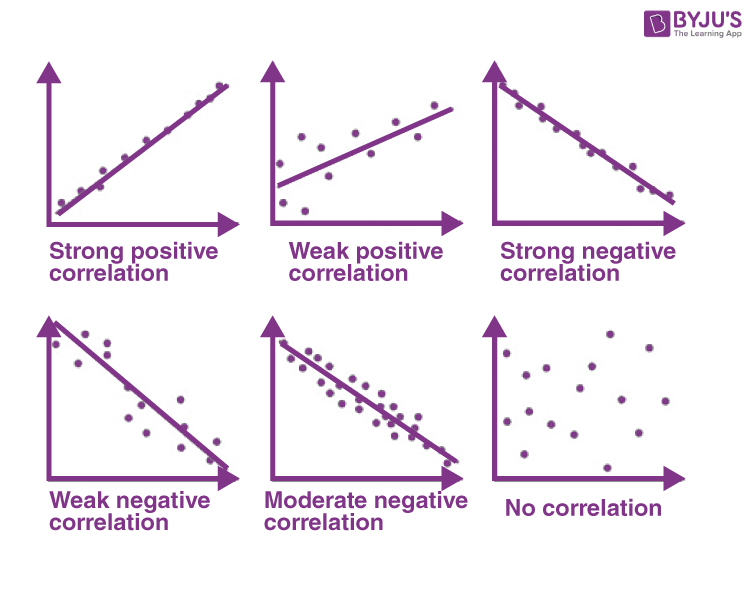
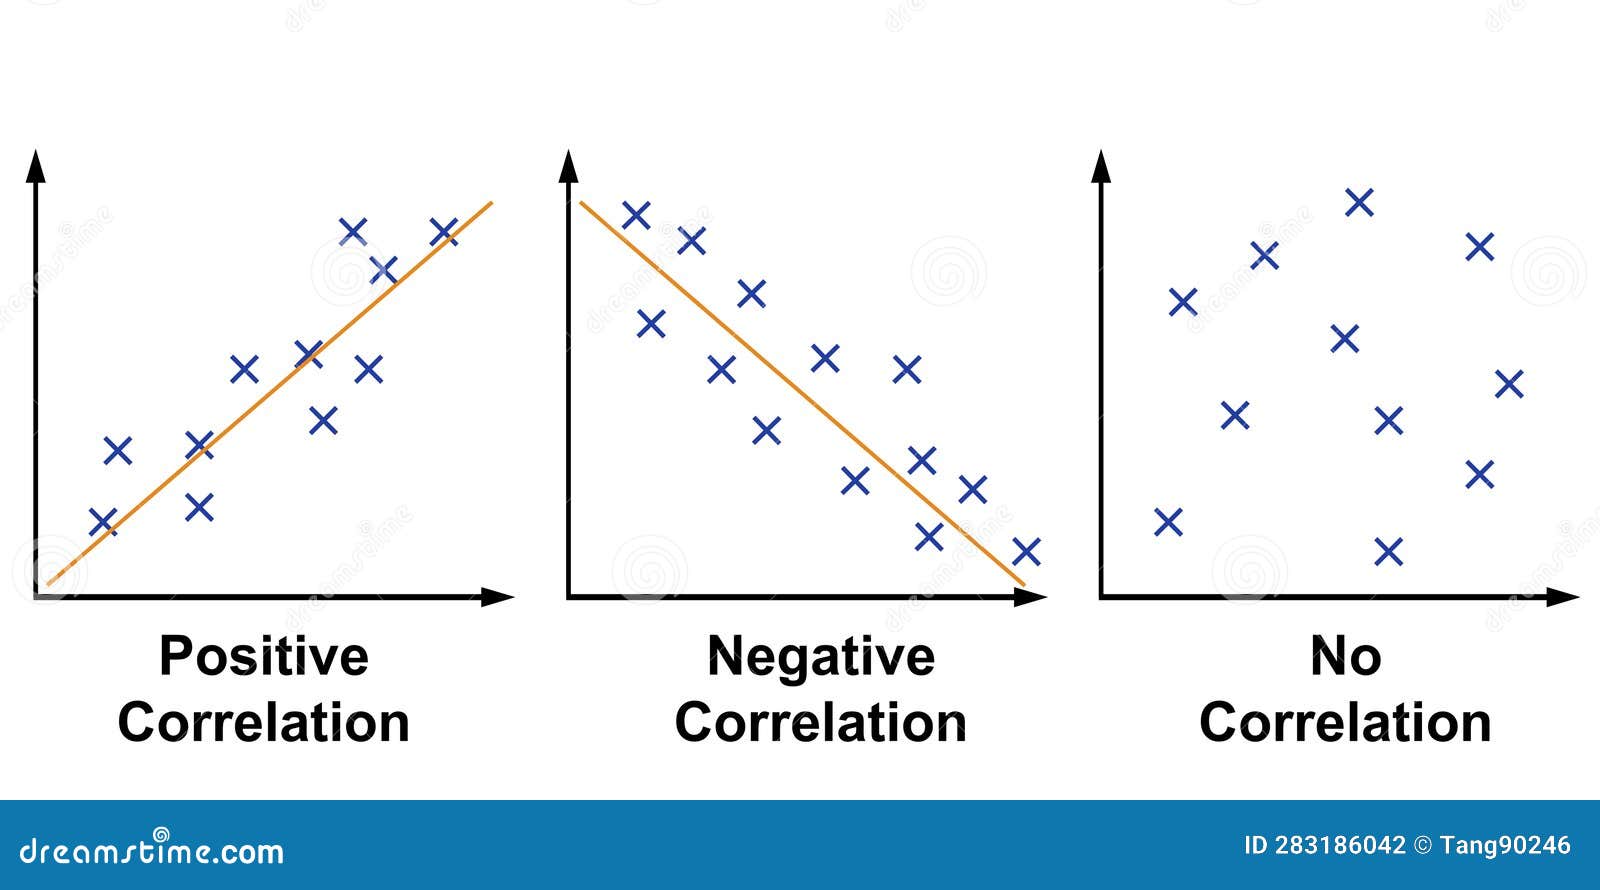
A scatter plot shows the relationship between two continuous variables by plotting individual data points on x and y axes. Correlation measures the strength and direction of that relationship. Pearson correlation coefficient gives you a number between -1 and 1. Positive values mean as one variable increases the other tends to increase. Negative values mean as one goes up the other goes down. Values near zero suggest no linear relationship, though that doesn't mean no relationship at all — just no linear relationship. The coefficient alone is useless without the plot. I've seen analysts report r = 0.12 and call it "negligible," then later find the actual relationship was a strong parabolic curve they missed because they stopped at the number. The visual does the work the number can't.
Building It in Python
If you're working with real data, here's the approach I use now. It handles overlapping points, adds the regression line, and prints the correlation with a confidence interval so you know whether the number is stable or just noise from a small sample. Start with pandas and numpy for the data manipulation, seaborn and matplotlib for the visualization. Here's a minimal working example: import pandas as pd
import numpy as np
import seaborn as sns
import matplotlib.pyplot as plt
from scipy import stats
Get the Full Details

df = pd.read_csv('your_data.csv')
x = df['variable_a']
y = df['variable_b'] corr, pval = stats.pearsonr(x, y)
print(f'Pearson r: {corr:.3f}, p-value: {pval:.4f}')
print(f'95% CI: {stats.bootstrap((x, y), stat="pearsonr", n_resamples=2000).confidence_interval}') sns.set_theme(style='whitegrid')
plt.figure(figsize=(8, 6))
sns.scatterplot(data=df, x='variable_a', y='variable_b', alpha=0.6, s=40)
z = np.polyfit(x, y, 1)
p = np.poly1d(z)
plt.plot(x, p(x), 'r--', linewidth=2, label=f'r={corr:.2f}')
plt.xlabel('Variable A')
plt.ylabel('Variable B')
plt.legend()
plt.tight_layout()
plt.savefig('scatter_corr.png', dpi=150)
This produces a plot you can actually use in a report. The alpha value controls point transparency so overlapping clusters become visible. The bootstrap confidence interval tells you whether your correlation is statistically robust or just happens to exist in this particular sample.
The Problem I Faced and What Worked
Last year I was analyzing campaign spend versus conversion rate across 200 markets. The scatter plot looked like a solid positive correlation — more spend, more conversions. The Pearson r was 0.71, which looks genuinely strong. I presented it to the marketing team and they immediately pushed back, and they were right. The issue was an lurking variable: market size. Large markets naturally had both higher absolute spend and higher absolute conversions, while small markets had low numbers on both axes. The correlation wasn't between spend and efficiency — it was between spend and market scale. When I broke the data into terciles by market size and plotted each group with a different color, the within-group correlations dropped to near zero. The overall correlation was a classic example of Simpson's paradox, where a trend appears in the combined data but disappears when you look at the subgroups. The fix wasn't a better chart. It was adding a third dimension — either through color-coding by market segment or switching to a partial correlation analysis that controls for market size. I ended up using statsmodels for the partial correlation and the results matched what the segmented scatter plot showed. The takeaway was simple enough: always check whether a third variable might be driving the relationship before you trust a bivariate correlation.
What People Miss
Here are the things I wish someone had told me earlier. Outliers don't just distort the line, they distort the coefficient disproportionately. One extreme point can swing a correlation from 0.3 to 0.8 or reverse the direction entirely. I learned this when a single data entry error — someone typed 10,000 instead of 1,000 for a monthly budget — made a flat relationship look strongly negative. Always inspect the plot before you inspect the number. Non-linear relationships look like no relationship on a standard scatter plot. A U-shaped curve will give you a correlation near zero. If the scatter plot doesn't show a clear linear pattern, don't assume there's nothing there. Try adding a LOWESS smooth line with seaborn's regplot, which fits a non-parametric regression and reveals curved relationships the Pearson coefficient hides.
Correlation has no units, but it also has no causality. This gets repeated so often it becomes background noise, but people still act surprised when their correlation turns out to mean something completely different than they intended. The strongest warning I can give: if your correlation depends on a single dataset collected under specific conditions, it may not generalize anywhere near as far as you think it will.
When Scatter Plots Fail
There are scenarios where this approach breaks down and you need something else. When you have thousands of overlapping points, the plot becomes an unreadable blob. Solutions exist — hexbin plots, 2D density contours, or simply subsampling — but they require additional steps. When one or both variables are categorical rather than continuous, a scatter plot is the wrong tool regardless of what the correlation says. When the relationship changes across the range of the data (heteroscedasticity), a single correlation coefficient misrepresents the whole picture. For dense data, try sns.jointplot with kind='hex'. For categorical comparisons, switch to box plots or violin plots. For changing relationships, fit local regressions or split the data into ranges and compute correlations separately.
A Note on Tools
I used to rely on Tableau for quick exploratory work. It's fast for dragging and dropping but the underlying calculations are opaque and it doesn't expose confidence intervals without custom formulas. For anything that needs to go into a paper or a formal report, Python with scipy gives you the numbers and the reproducibility. R is equally valid if that's your workflow. The tool doesn't matter as much as understanding what the plot is actually showing you. If you want to experiment, start with a dataset you understand well — something with obvious patterns and a few known outliers. Build the plot, check the correlation, remove the outliers, rebuild, and compare. That exercise alone teaches you more than any textbook example about how fragile these numbers can be.