The Practical Ways to Remove Pages From a PDF
PDFs don't work like regular documents. Deleting a page sounds trivial until you've tried it five different ways and half of them break bookmarks, leave ghost objects, or produce a file that's somehow larger than the original. I've spent years cleaning up PDFs for clients and building automated pipelines, so I've learned to expect the frustrating edge cases rather than be surprised by them. The fastest approach I use, especially when dealing with batches, is qpdf or pdftk from the terminal. qpdf is my default because it preserves the linearization of the source PDF, which means the page still opens quickly in browsers even after manipulation. A typical command looks like this: qpdf --pages input.pdf 1-3 5-end -- output.pdf
This removes page 4 from a six-page document. The syntax is explicit: you list the page ranges you want to keep, not the ones you want gone. Beginners often get tripped up there and end up deleting the wrong pages because they think in terms of exclusion rather than inclusion. pdftk works similarly but has different syntax: pdftk input.pdf cat 1-3 5-end output output.pdf
The main downside with pdftk is that it does not handle encrypted PDFs well unless you pass the password flag, and it tends to recreate the entire file structure rather than doing an incremental save. That can add noticeable time on large files and occasionally corrupt custom annotations.
Get the Full Details

What Actually Happens When You Delete a Page
A PDF is essentially a linked list of objects stored in a binary format. Every page is a dictionary entry that points to content streams, font descriptors, image XObjects, and sometimes embedded JavaScript. When a tool deletes a page, it either rewrites the entire object graph from scratch or drops the page reference from the page tree and sets those objects as orphaned. The latter is what causes inflated file sizes after deletion — the objects are no longer referenced but they're still in the file. This is one of the things most people miss. You delete a page and the file only shrank by fifty bytes. That happens because ghost images, fonts, and metadata are still lingering inside. qpdf's --linearize flag after deletion usually cleans this up. PyPDF2 and pypdf do not, unless you explicitly call a cleanup method.
Using Python to Delete a Page From a Pdf
When I need something scriptable, I reach for pypdf, which is the maintained successor to PyPDF2. The code is straightforward: from pypdf import PdfReader, PdfWriter
reader = PdfReader("input.pdf")
writer = PdfWriter()
for i, page in enumerate(reader.pages):
if i not in [3]: writer.add_page(page)
with open("output.pdf", "wb") as f:
writer.write(f) That removes page index 3, which is the fourth page since Python uses zero-based indexing. Simple enough until you hit a PDF where the pages contain form fields or embedded JavaScript actions tied to specific page indices. After deletion, the field references point to non-existent pages and Acrobat throws errors when you open the file. I ran into this exact problem last year with a government procurement PDF that had twelve pages of forms with script triggers. Deleting page 7 broke every subsequent form field. My workaround was to renumber the page labels in the PDF structure after deletion by modifying the /Names dictionary directly, which is tedious to do by hand but automated in the pypdf library through the out_lines attribute.
GUI Options and Their Trade-offs
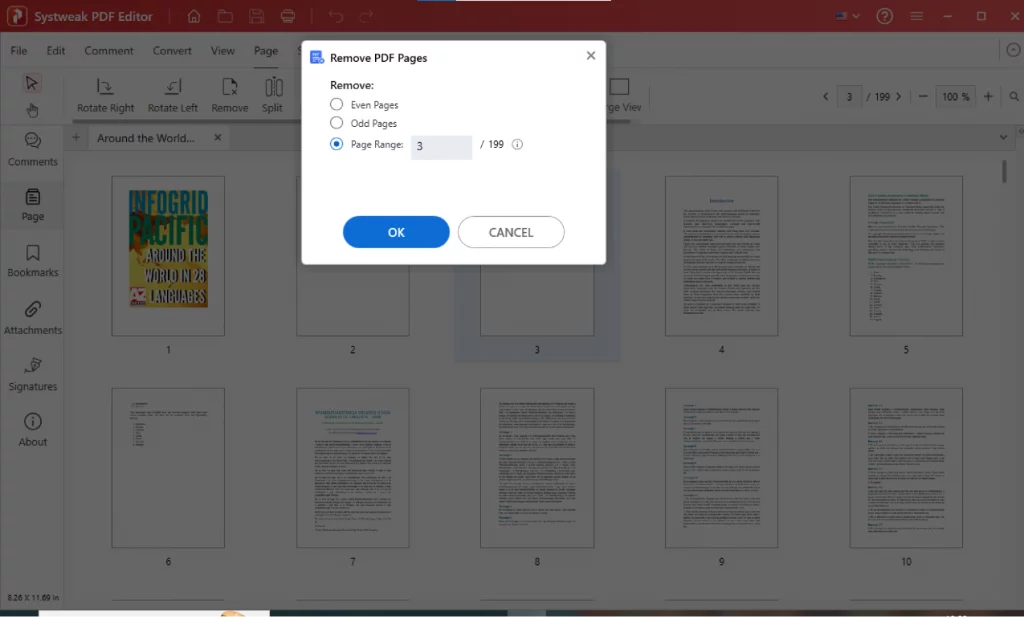
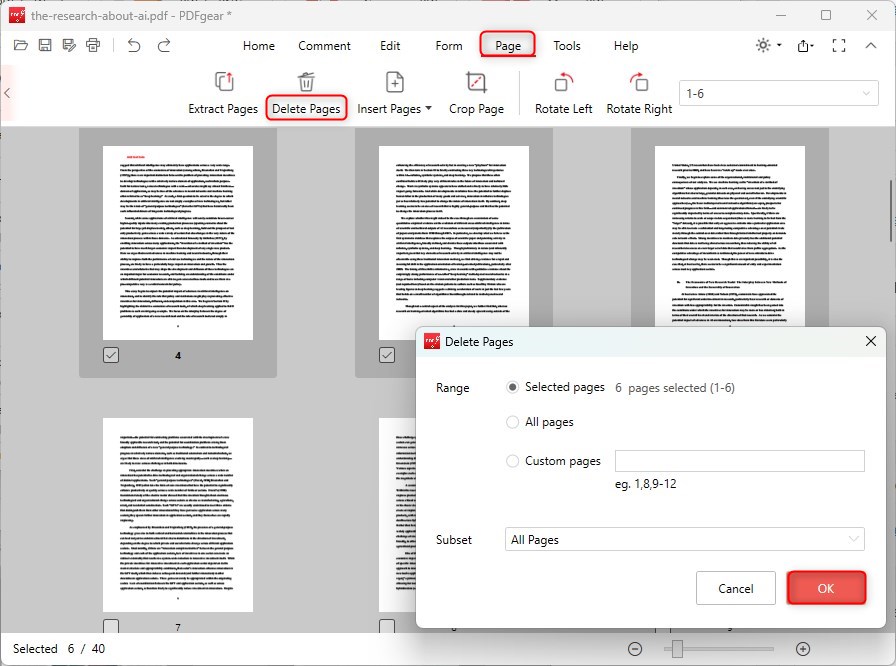
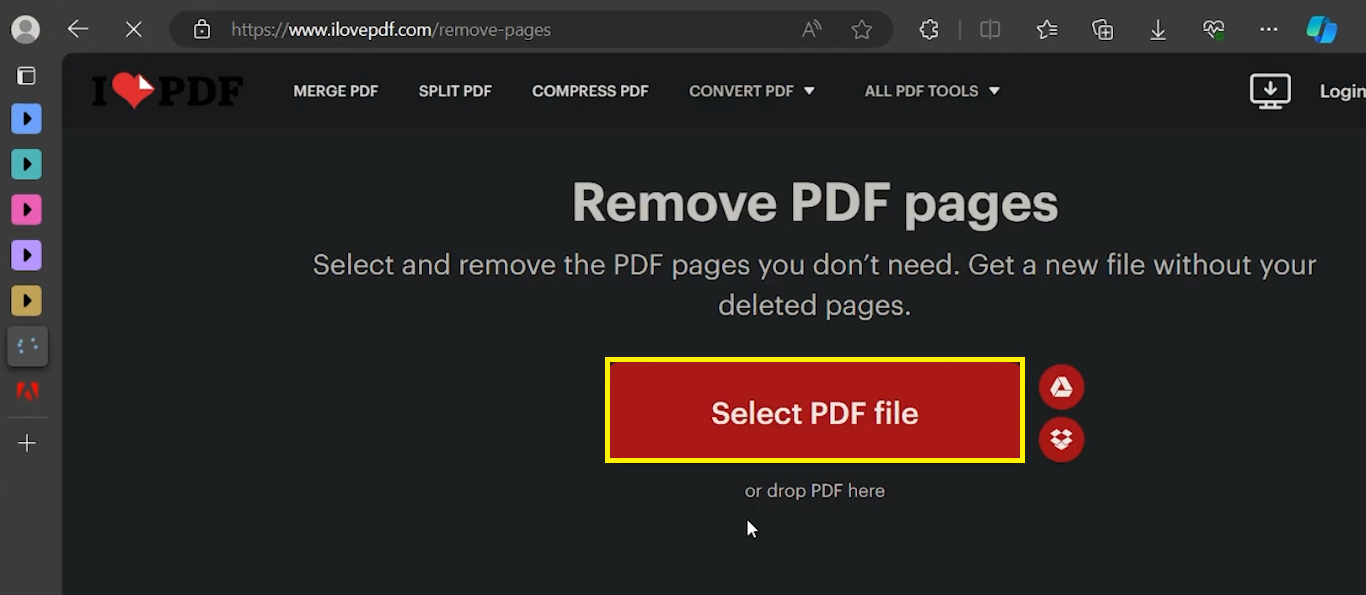
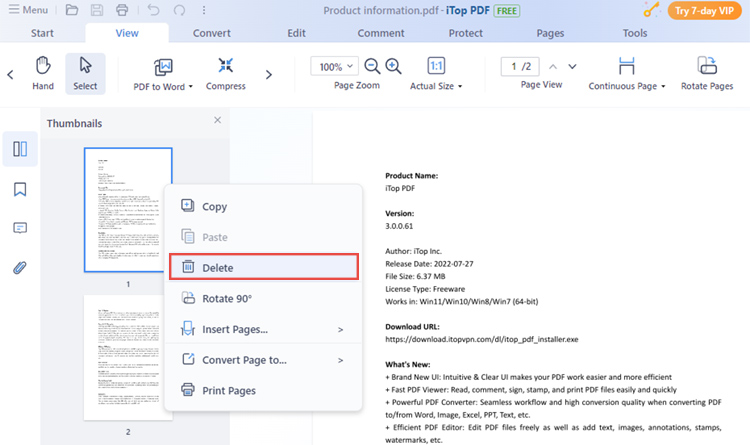
Adobe Acrobat Pro handles page deletion cleanly. It reconstructs the object graph properly and keeps the linearization intact. The cost is the subscription price, and honestly it's overkill if you're just removing a page occasionally. macOS Preview can delete pages too — you open the PDF, show the thumbnail sidebar, select a page, and press delete. It works fine for quick jobs on light files but it strips interactive elements like bookmarks and form fields silently, which you won't notice until later. Online tools like iLovePDF or Smallpdf will let you Delete Page From Pdf through a browser interface. They're convenient but they upload your document to a third-party server. I avoid using them for anything containing sensitive information, personal data, or client contracts. There have been several public incidents where these services retained uploaded documents beyond the stated retention period. The technology itself is adequate, but the trust calculation is not worth making for any document you'd rather keep private.
Scanned PDFs and Image-Based Pages
This is where things get messy. If your PDF is a scan — every page is essentially a bitmap image — then page deletion is technically simple but the resulting file may not behave the way you expect. Many scanning utilities embed each page as a full-page image without OCR text. Deleting a page from that PDF removes the image container but leaves the document metadata inconsistent. Some viewers will skip a blank gap where the deleted page was, others will display a corrupted thumbnail. The safest approach with scanned PDFs is to use a tool that rebuilds the page tree rather than simply dropping references. qpdf handles this well because it reconstructs the cross-reference table from scratch.
Password-Protected PDFs
You cannot delete pages from a PDF that has owner-level encryption without the password. User-level passwords that only restrict printing are different — many tools will strip those. But if the document is encrypted with a valid owner password and you don't have it, no tool will help you. I've seen people try to bypass this by converting the PDF to images and back, which is a roundabout process that degrades quality significantly and still doesn't guarantee removal of all encrypted content streams.
Bottom Line
If you need a reliable method and already have a development environment, qpdf is the tool I recommend. It's fast, it preserves structure, and it handles edge cases better than most GUI alternatives. For one-off deletions on non-sensitive documents, Preview or any online tool is acceptable. Just be aware that "acceptable" doesn't mean clean — ghost objects, broken annotations, and metadata drift are all common side effects that most users never notice until they're trying to merge the result with another document.