The mess most IT teams walk into
I watched a team at a logistics company spend six weeks building a dashboard that nobody used. The database was solid. The API worked. The UI looked fine. The reason it failed is the kind of thing that does not show up in any textbook. Developing information systems is less about the technology than it is about the boundary between how work actually happens and how people pretend it happens when they fill out a requirement form. You will get further by mapping the second one first and ignoring the first one for a few days until you know which part is lying.
Getting Started With Developing Information Systems Practical Guidance For IT Professionals
Here is what I actually do when a new project comes in. I do not write architecture diagrams first. I sit with two or three people who do the job the system will replace and I ask them to show me their most recent problem. Not their routine work. The problem. The one where they had to email someone, wait for a reply, attach a spreadsheet, and hope nobody changed the numbers while they were looking away. That pain point becomes the first milestone. Everything else follows from it. If you cannot describe the pain in one sentence that a non-technical person would recognize, you are not ready to design anything yet.
What the term actually means in practice
People treat "information systems" like a synonym for software. It is not. An information system is the whole chain: the data coming in, the rules that decide what happens to it, the people who make exceptions, the reports that get printed or emailed every Friday at 4pm, and the audit trail someone eventually demands when the numbers do not match. Build only the software part and you have built a very expensive toy. I learned this the hard way on a hospital inventory project around 2021. The team delivered a perfectly normal ERP module for tracking IV bags. It had user roles, approval workflows, and a report generator. The nurses used it for three days. Then they went back to whiteboards and sticky notes because the system could not handle the real exception: a bag that was opened but not fully used, then quarantined because the seal looked suspicious. There is no clean data model for a partially used medical supply item that requires a manual override signed by two people. We spent another two weeks building the exception path and the system finally stuck. That is the counter-intuitive part nobody tells you. The exception path is where the system lives or dies. The happy path is easy. Anyone can build a happy path. The business runs on the exceptions.
Get the Full Details
The method most professionals skip
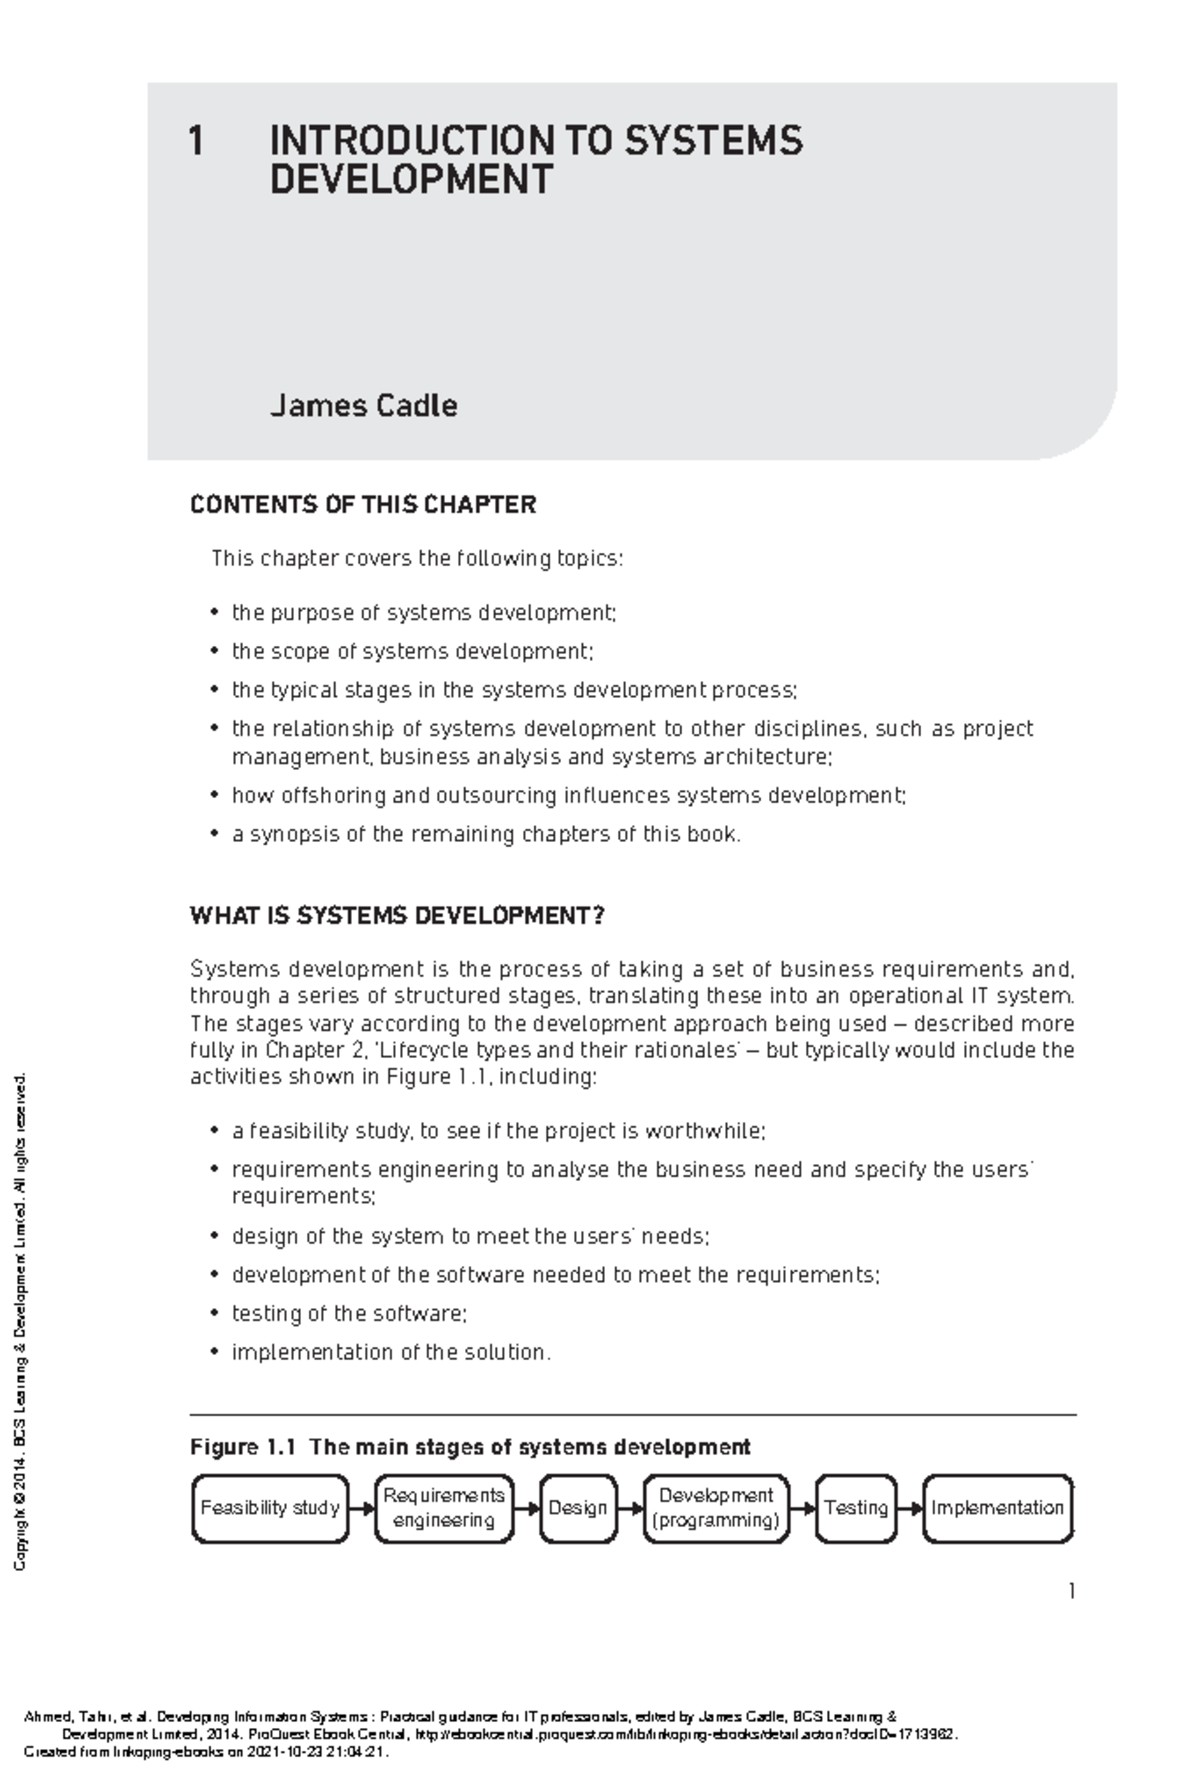
Start with the data contract before you touch a single line of code. Write down every field that will enter the system, every field that will leave it, and every field that will change between entry and exit. For each field note the source, the format, the tolerance for being wrong, and who decides when it is wrong. This takes about an hour per module and it saves roughly four days of rework later. I have seen teams cut two-month estimation errors down to about three weeks by doing this first. Next, draw the state transitions. Every record in an information system moves through states. A purchase order goes from draft to approved to ordered to received to invoiced. A patient admission goes from triage to admitted to observed to discharged. The states are not decorative. They are the actual skeleton of the system. If you can list all the valid transitions and all the invalid ones that someone will inevitably try to force through, you already have 70 percent of the backend logic written in your head. Then build the audit trail. Not the nice version. The version that survives an external audit. Every create, update, and delete must be logged with a timestamp, the actor, the old value, and the new value. If you do not do this from day one, you will add it later when someone asks for it and everything will break because your ORM does not support historical snapshots and your developers will convince you that point-in-time restores are good enough. They are not.
Common pitfalls that beginners keep repeating
The first pitfall is requirement gathering that listens to what people say instead of what they do. I had a client in manufacturing tell me their quality inspectors needed a real-time mobile app. They did not. What they actually needed was a paper form that survived being dropped in a puddle, with a scanner at the end of the line that batch-uploaded everything at shift change. The mobile app idea cost forty thousand dollars and two months. The paper-plus-scan approach cost twelve hundred and two weeks. Both solved the same problem. The second pitfall is building for scale that does not exist. Your system will handle ten thousand concurrent users next year, or maybe not. The infrastructure decision at month one should be based on what you can verify, not what a salesperson convinced you to fear. Start with a single application server and a managed database. Add horizontal scaling when the numbers force you to. I have watched three teams waste months on Kubernetes clusters for applications that never moved past fifty daily active users. The third pitfall is treating documentation as a separate phase. It is not. Documentation is the system's interface to the future maintenance team, which might be you six months from now when you have forgotten why the currency conversion uses a fixed multiplier of 1.047 instead of the live rate. Write the docs as you build. Not after. The after phase never comes.
When the method breaks down
This approach assumes you have at least some access to the actual workflow. If you are building a system for a regulated industry where the stakeholders are legal teams and the real users are completely invisible to you, the method produces beautiful designs for problems you do not understand. In those cases, the workaround is simpler than people want to admit: get a contractor who has done this exact job before and pay them two weeks to shadow the real work. The cost is usually less than one month of your own wasted effort. Another scenario where this fails is greenfield platforms with no domain experts. Consumer apps, social networks, content platforms. These are not information systems in the traditional sense. They are distribution engines. The methodology I described above is overkill for them and may actively slow you down. Ship fast, measure, iterate. The rules are different when the product is the audience, not the process.
A specific edge case that almost cost us the project
About two years ago I was working on a logistics tracking system for a regional freight company. The requirement was straightforward: track containers from pickup to delivery with status updates at each checkpoint. We built it. It worked. Then a customs inspector in a secondary port demanded a paper manifest with a wet signature because the digital version had been altered twice after initial entry and there was no immutable record of who changed what and when. We did not have an immutable record. We had a standard audit log stored in a relational table that anyone with database access could delete. The workaround was brutal. We implemented a write-once append table using a simple hash chain. Each new log entry contained the hash of the previous entry. If anyone modified an old record, the chain broke and the system flagged it. It added about three hours of development time and required a small migration script. It also saved us from losing the contract two months later when the client faced a regulatory fine. The lesson was not new. It was just the first time I saw it happen to my own work instead of reading about it in someone else's postmortem.
Tools that actually help versus tools that look helpful
For data modeling, use a proper ER tool. Not a whiteboard. Not a Word document. Something that enforces normalization constraints and generates DDL you can actually run. I use dbdiagram.io for quick sketches and PostgreSQL with a migration framework for anything that goes to production. The migration part matters more than the modeling part. A model without migrations is a drawing. For version control, use Git. This is not controversial. What is controversial is the branch strategy. I recommend a simple trunk-based approach with short-lived feature branches for projects under six months. Long-lived feature branches create merge hell that no amount of CI automation can fix cleanly. For longer projects, a release branch model works if you commit to cutting releases on a schedule. Anything in between is where most teams drift into chaos. For monitoring, install it before you deploy, not after. I once joined a project where the production system had zero observability. The first incident took four hours to diagnose because nobody knew whether the slowness was the database, the network, the application, or the load balancer. Adding Prometheus and Grafana after the fact is possible but painful. Adding it during development takes about half a day and pays for itself on the first incident.
Putting It Together: Developing Information Systems Practical Guidance For IT Professionals
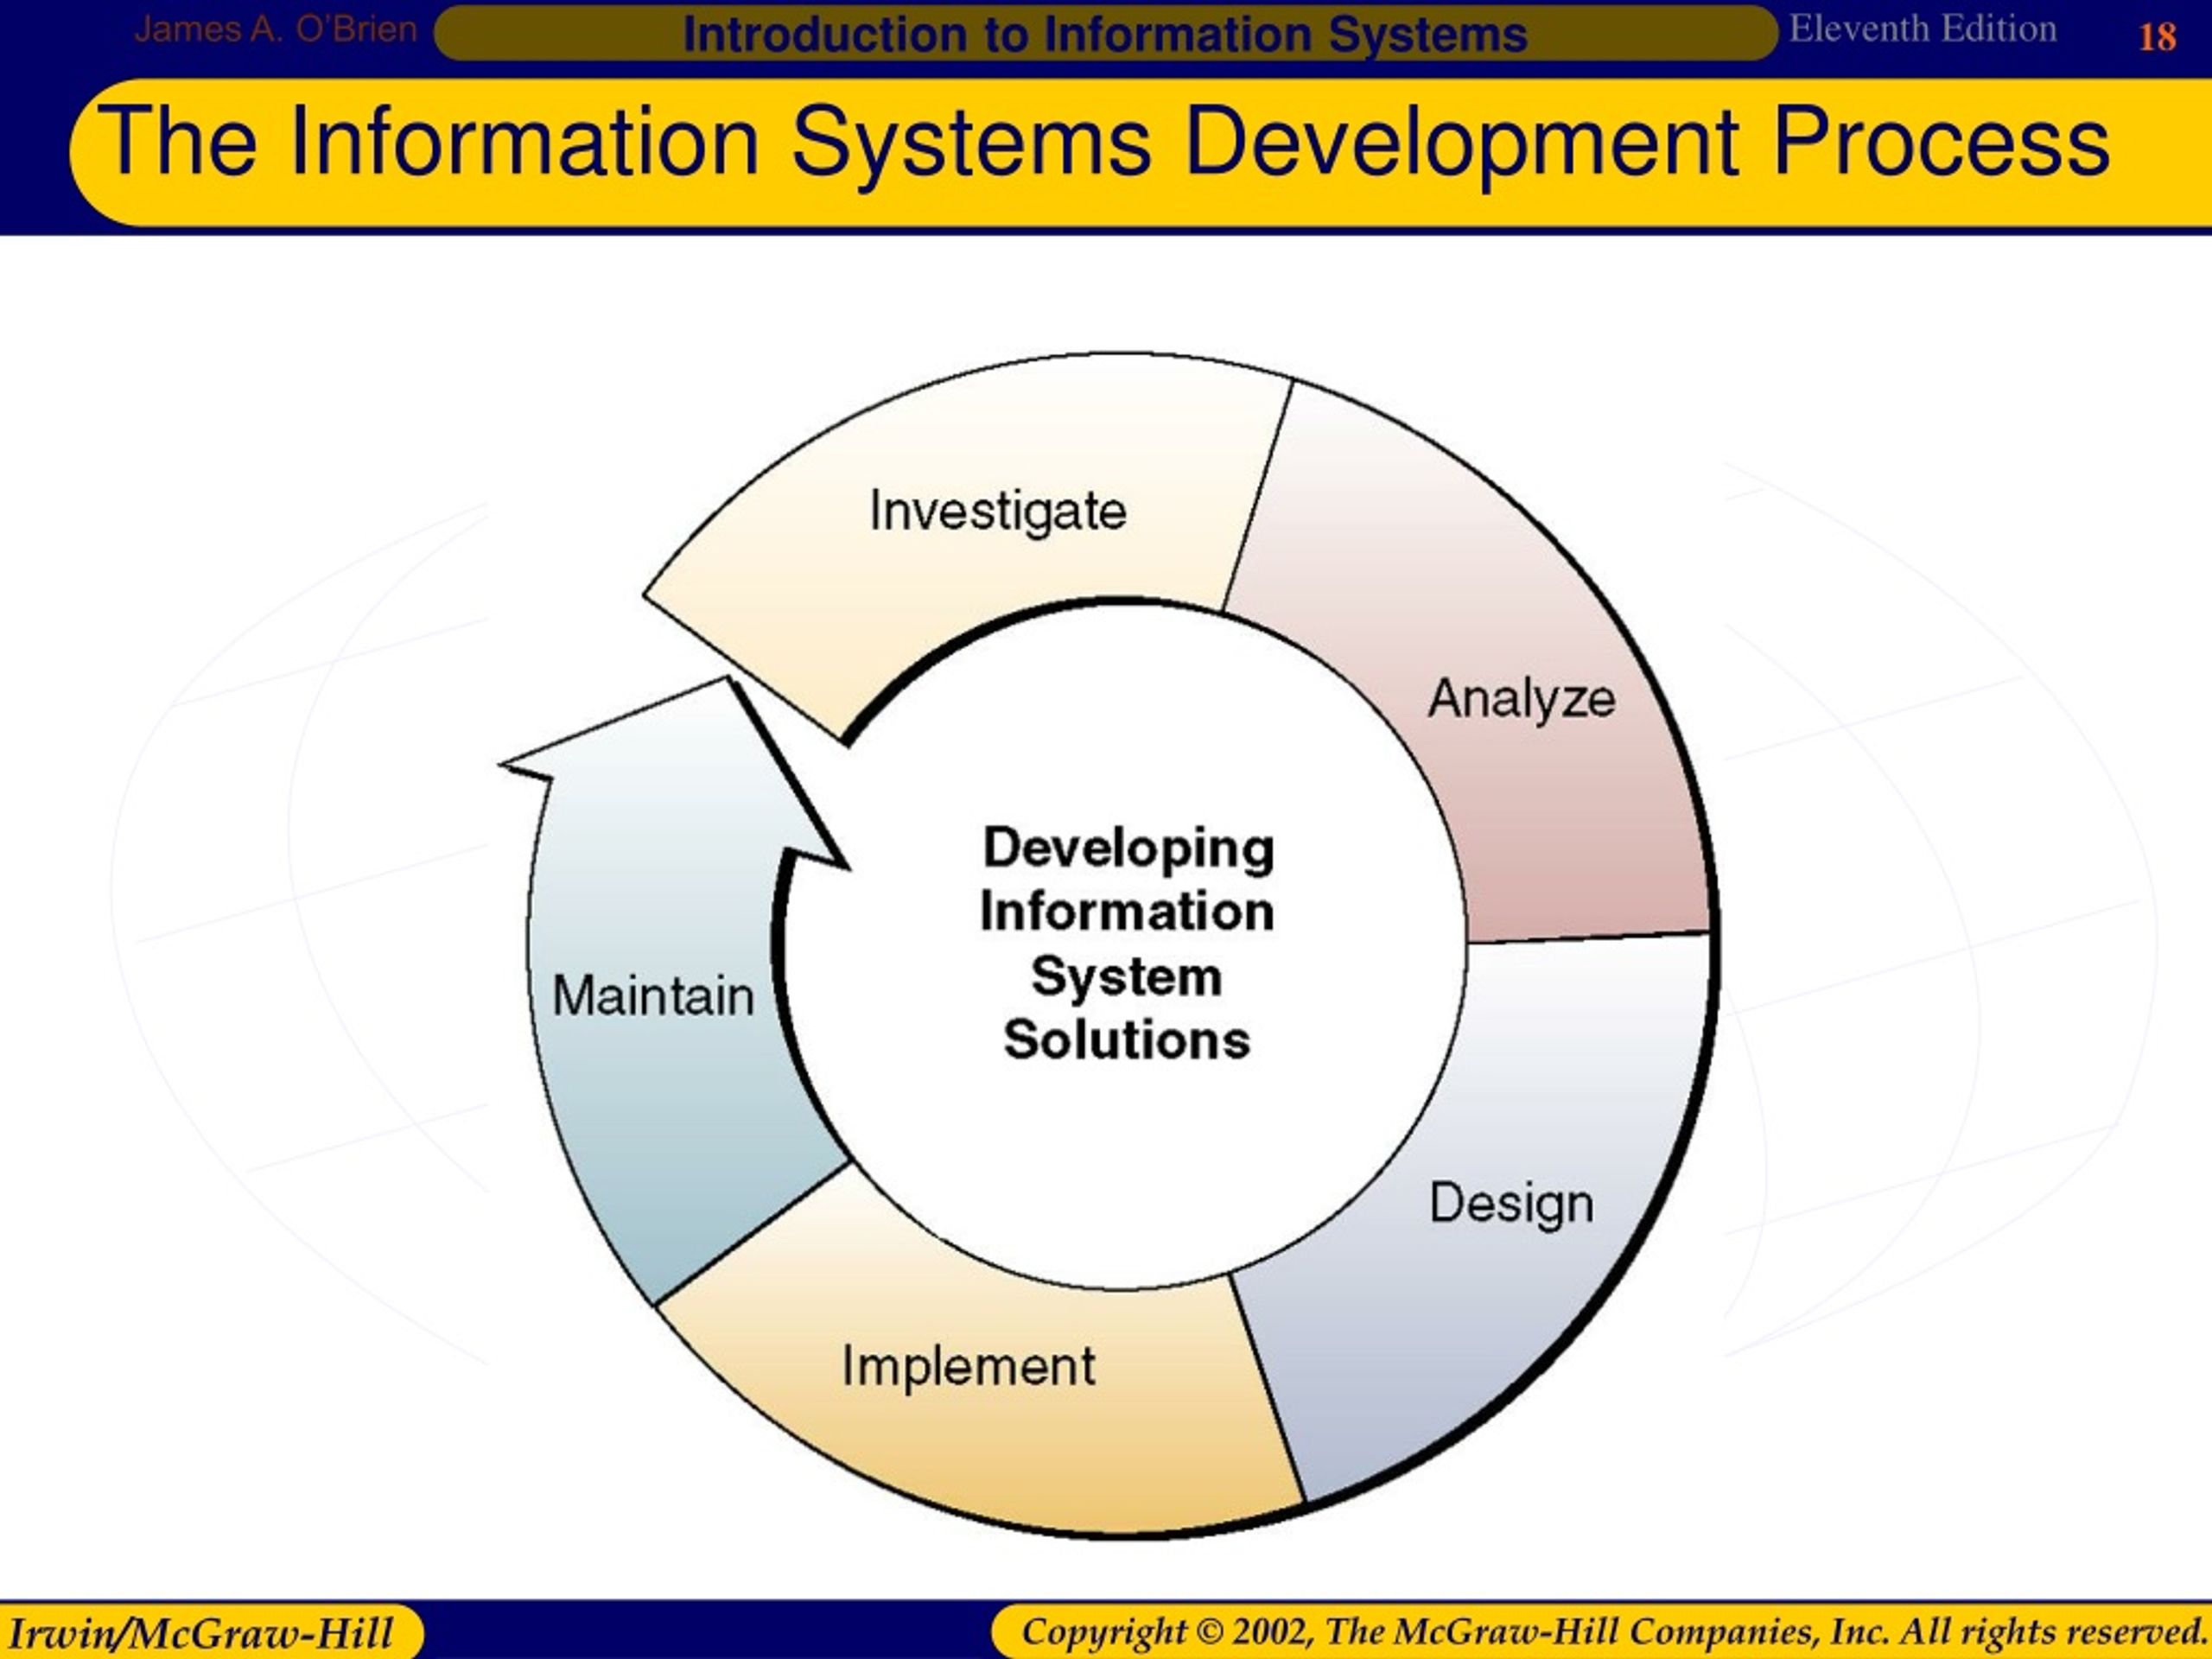
The core loop is simpler than it sounds. Identify the real pain. Map the data. Define the states. Build the exception paths. Log everything. Test the audit trail. Ship the smallest thing that solves the pain. Then repeat. Do not skip steps. Do not add steps that feel impressive. The best information systems are the ones that disappear into the background and let people do their jobs without thinking about them. If users are talking about your system instead of using it to do something else, you have built the wrong thing or built it for the wrong reason. The metrics that matter are not download counts or feature completeness. They are time-to-completion for the core task, error rate on the exception path, and the number of workarounds people have built outside the system. If the workaround count is higher than the feature count, the system is a net negative and you should consider shutting it down rather than patching it further.