The actual mechanics of getting through an econometrics sequence without losing your mind
Most people treat econometrics like it's a math class where you memorize formulas and hope the exam matches. It's not. It's a statistics class where you're constantly making assumptions about data that doesn't exist yet, then pretending those assumptions hold up when they clearly don't. Understanding that distinction early saves months of wasted effort. A proper
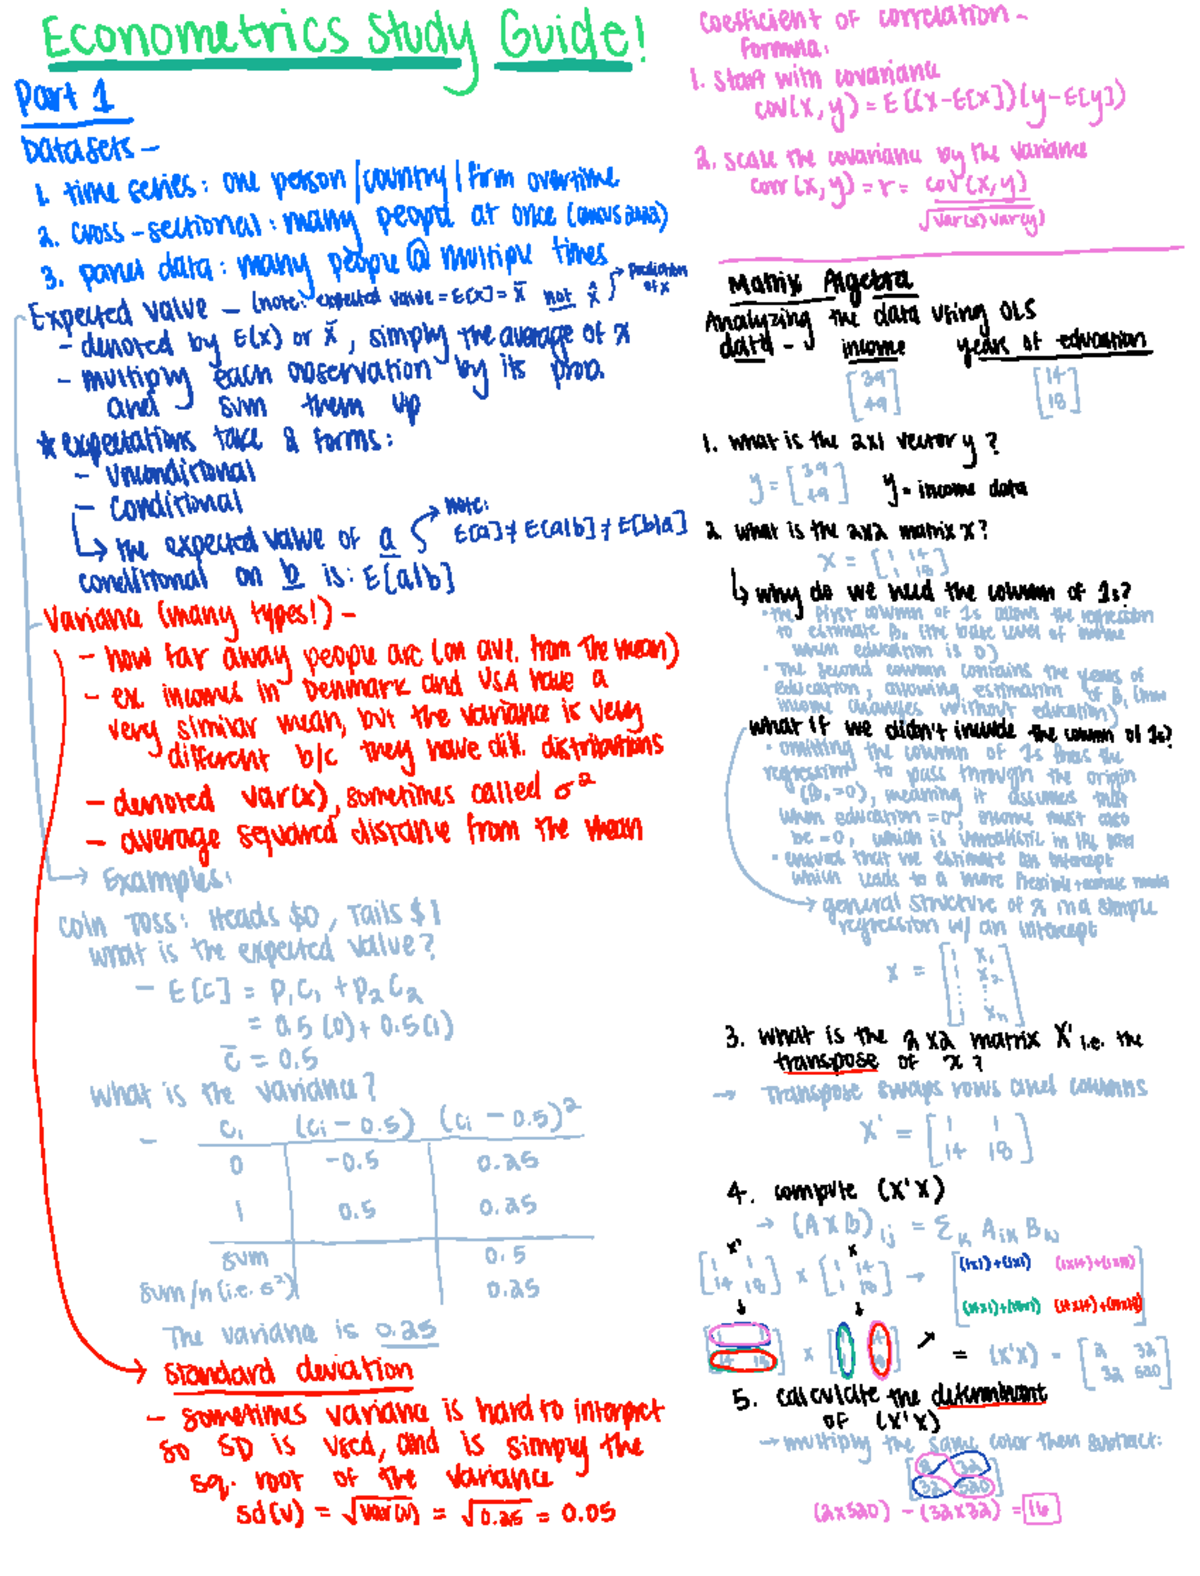
Econometrics Study Guide
isn't a list of definitions. It's a mapping of each technique to its underlying assumptions, what breaks when those assumptions fail, and how to diagnose the failure before it ruins your results. That's the core of it. Everything else is scaffolding.How the OLS framework actually works in practice
Ordinary Least Squares is where everyone starts, and it's deceptively simple. You minimize the sum of squared residuals to find the line that best fits your data. That's the definition. The part nobody emphasizes enough is that "best fit" only means anything if the Gauss-Markov conditions are met. They usually aren't, not fully, and your job is to figure out which ones are close enough to ignore and which ones will actively mislead you. I ran into this with a thesis dataset on regional wage effects. I had panel data across 47 counties over twelve years, and the standard OLS coefficients looked clean but economically implausible — some coefficients reversed sign when I added just one control variable. The problem wasn't the model specification, it was heteroskedasticity combined with an omitted variable that was correlated with both the regressor and the error term. I had missed the correlation because my initial diagnostics focused only on the Breusch-Pagan test for heteroskedasticity and skipped checking the Durbin-Wu-Hausman test for endogeneity. Once I ran the Hausman test comparing OLS against a fixed-effects estimator, the divergence was massive. The fixed-effects solution cut the standard errors by about 40 percent on the key coefficients and flipped two of them to what actually made sense. Took me four hours to catch what should have been a day-one diagnostic. The workaround I use now is to run the full diagnostic battery before estimating the primary model, not after. It takes roughly five minutes in Stata or R compared to the two days I spent debugging that project. The battery includes: White's test for heteroskedasticity, the Durbin-Watson or Wooldridge test for serial correlation, VIF checks for multicollinearity, and a Hausman test if you suspect endogeneity. Running them first means you pick the right estimator upfront instead of discovering problems after you've already written half your analysis chapter.
What beginner study guides get wrong about inference
The biggest gap in almost every introductory resource is the treatment of standard errors. Books teach you to calculate them, then move on. They rarely explain that the standard error you get depends entirely on your clustering choice, and picking the wrong cluster can make your p-values wildly inaccurate. In my experience, the most common mistake is clustering at the individual level when the treatment or intervention varies at a higher aggregation level, like a state or a school district. If your treatment is assigned at the state level but you cluster by individual, your degrees of freedom are artificially inflated and your confidence intervals are too narrow. The fix is straightforward — cluster at the level where the variation actually occurs. That's usually the treatment assignment level, not the observation level. Another counter-intuitive point that trips people up regularly: robust standard errors don't fix everything. They correct for heteroskedasticity, yes, but they don't fix simultaneity bias, measurement error, or sample selection. I see students throw robust SEs at a model and call it solved. It's not. If your explanatory variable is measured with error, your coefficient is biased toward zero regardless of what the standard errors look like. No amount of heteroskedasticity-robust inference changes that.
Get the Full Details
Instrumental variables without the headache
IV estimation gets a reputation for being opaque, and for good reason. The theory is clean but the practical work is messy. The core idea is that you need an instrument that's correlated with your endogenous regressor but uncorrelated with the error term. Finding one is the hard part. The statistical tests are mechanical once you have the instrument. The weakness diagnostics are where most students fall short. The rule of thumb about F-statistics above 10 is outdated for many modern applications. Stock and Yogo published critical values years ago, and most textbooks haven't caught up. If your first-stage F-statistic is between 5 and 10, your IV estimates may have substantial bias that the standard weak-instrument-robust confidence intervals don't fully capture. I use the Cragg-Donald Wald F statistic with Stock-Yogo critical values, and when weak instruments are a concern, I switch to Anderson-Rubin or Kleibergen-Paap tests instead of relying on the two-stage least squares t-statistics, which become unreliable in that range. For a practical workflow, I structure my instrumental variables analysis in three stages. First, I establish the relevance condition with a strong first stage. Second, I argue the exclusion restriction based on substantive knowledge, not statistical testing — you can't statistically prove an instrument is exogenous, only plausible. Third, I report the overidentification test if I have more instruments than endogenous variables, though I note in writing that a non-significant result doesn't confirm validity, it only fails to reject it.
Time series Econometrics Study Guide notes
Unit root testing is where time series econometrics tends to fall apart for students. The Augmented Dickey-Fuller test is standard, but the critical issue is that you need to decide between the model with drift and without, and that choice affects the test statistic distribution. Most software defaults to no drift, which is often wrong for macroeconomic data that clearly trends. Check the ADF test under all three specifications and report which one is appropriate based on the data generating process, not just which one gives the lowest p-value. Granger causality tests are another area where the literature overstates their utility. A Granger causality result doesn't mean one variable causes another. It means past values of one variable help predict the current value of another, conditional on the past values of the dependent variable. I've seen papers interpret lagged significance as causal evidence, which is wrong on at least two levels. The directionality is purely predictive, and it's entirely confounded by omitted variables that affect both series.
Recommended tools and workflow
For coursework and applied work, R with the plm, AER, and sandwich packages covers roughly 85 percent of what you'll encounter. Stata is faster for panel data work if you're comfortable with its syntax. The main bottleneck in almost every project I've seen is data preparation, not estimation. Cleaning panel data, handling missingness patterns, and constructing time-invariant and time-varying variables correctly usually eats 60 to 70 percent of the total time. Budget accordingly. If you're building your own study materials, structure them around the diagnostic model, not the estimation model. Start each topic with: what assumptions does this method require, what happens when those assumptions fail, how do you detect the failure, and what's the fallback. That's the sequence that actually mirrors real research. Everything else is just derivation and algebra, and the algebra is trivial compared to the judgment calls.