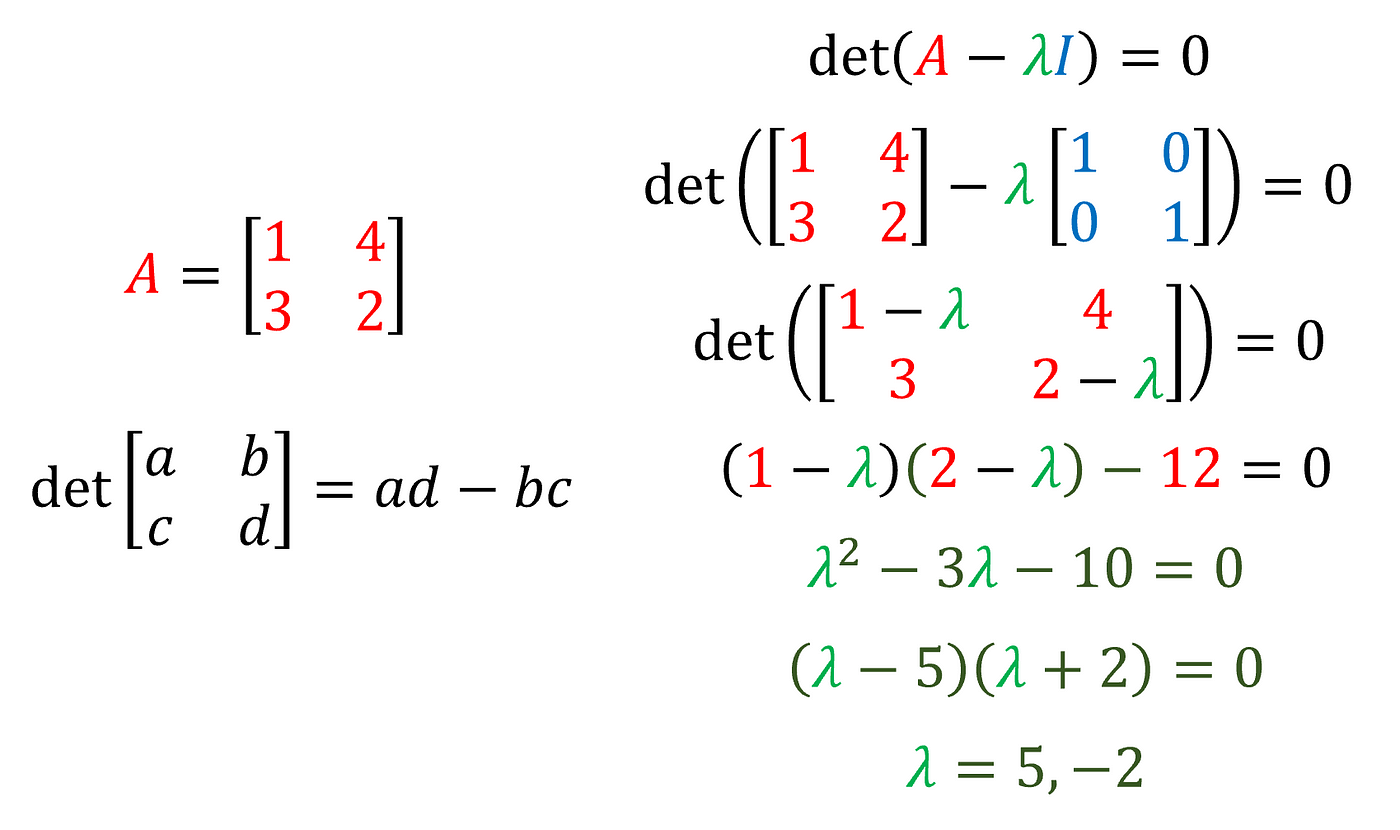
Computing Eigenvalues Without Losing Your Mind
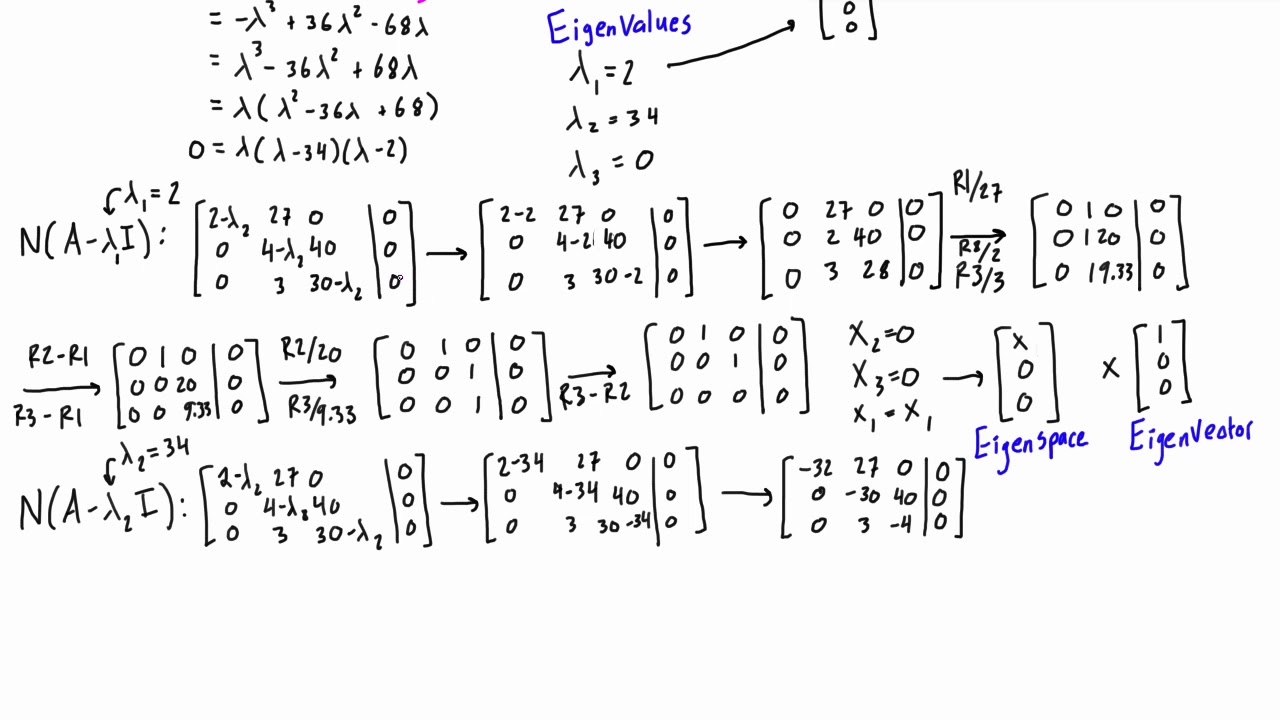
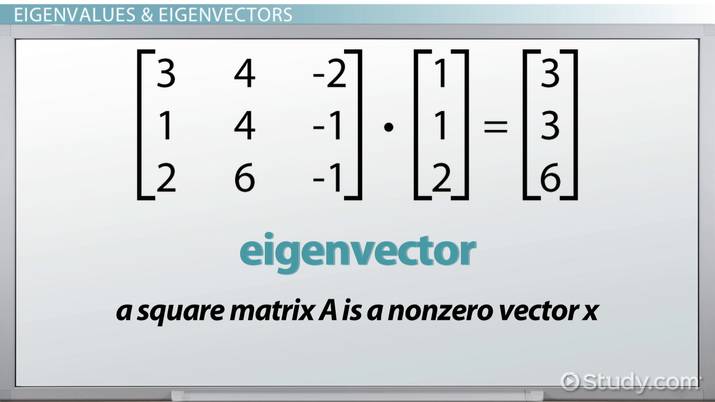
Most people learn eigenvalues through a characteristic polynomial: set det(A - I) = 0 and solve. That works fine for 2x2 matrices. It becomes numerically unstable past 3x3, and it's essentially useless for anything larger if you're doing this by hand or with standard floating-point arithmetic. I ran into this exact problem when I was working on a modal analysis routine for a finite element model of a bridge deck. The stiffness matrix was 847x847. Running the symbolic determinant approach would have taken hours and produced garbage results because of roundoff error at that scale. What actually worked was using a divide-and-conquer QR algorithm through LAPACK's DSYEV routine. The core idea is simple enough. An eigenvalue of a square matrix A is a scalar where Ax = x for some nonzero vector x. That vector x is the eigenvector. The collection of all eigenvalues is the spectrum of A. But the practical question is how to extract them reliably, not how to define them.
Practical Approaches To Eigen Values Of A Matrix
For a dense symmetric or Hermitian matrix, the gold standard is the QR algorithm with shifts. Here's why it works and why you should understand it before blindly calling a library. The basic QR iteration takes A and computes its QR factorization, then forms A = RQ. This new matrix is similar to the original, so it shares the same eigenvalues. Repeat the process and the matrix progressively approaches upper triangular form. The diagonal entries converge to the eigenvalues. Adding a shift — subtracting a scalar from the diagonal before factoring, then adding it back after — dramatically speeds up convergence because it targets the eigenvalue closest to each iteration. If your matrix is sparse, which most real-world systems are, you don't use the full QR algorithm. You use implicitly restarted Arnoldi methods instead. ARPACK, implemented in Fortran and wrapped by just about every scientific computing library, is the standard tool here. It finds a small number of eigenvalues near a target value without touching the full matrix. For a 10,000x10,000 sparse matrix where you only need the ten largest eigenvalues, this typically runs in under a minute on a modern machine. Full QR would take twenty minutes and probably fail due to memory constraints. I once had a project where a colleague tried to compute eigenvalues of a covariance matrix generated from sensor data with missing entries. The interpolated matrix had slightly asymmetric rounding errors that made it non-symmetric to within machine precision. Using a symmetric solver on it produced eigenvalues that looked right but had subtle phase errors in the eigenvectors, which completely wrecked the subsequent principal component analysis. The fix was to symmetrize the matrix explicitly by computing (A + A)/2 before passing it to the solver. The eigenvalues barely changed, but the eigenvectors became stable again.
Common Pitfalls That Are Not Obvious
First, eigenvalues are not continuous functions of matrix entries in a way that helps you. A small perturbation to a matrix with distinct eigenvalues produces a proportionally small change in those eigenvalues. But if your matrix has repeated eigenvalues or is nearly defective — meaning it has a Jordan block structure close to a repeated eigenvalue — then tiny perturbations can cause eigenvalues to move arbitrarily far. This is called eigenvalue ill-conditioning. The condition number of an individual eigenvalue depends on the angle between its left and right eigenvectors. When those eigenvectors become nearly parallel, the eigenvalue is poorly conditioned and numerical algorithms will struggle. I spent an afternoon tracking down why a stability analysis of a control system kept producing different results across different solvers. The issue was a near-defective mode at frequency = 3.72 where the left and right eigenvectors had an inner product magnitude of about 0.0003. No algorithm could resolve that cleanly in double precision. Second, computing eigenvectors is qualitatively harder than computing eigenvalues. Many people overlook this. Libraries will give you both, but the eigenvector computation amplifies numerical error significantly more. If you only need eigenvalues for a stability check or a spectral radius estimation, skip the eigenvector extraction entirely. Most modern libraries let you request eigenvalues only, which cuts runtime roughly in half for dense problems and reduces memory usage proportionally. A third issue that trips people up regularly is the difference between algebraic and geometric multiplicity. The algebraic multiplicity is the multiplicity of as a root of the characteristic polynomial. The geometric multiplicity is the dimension of the null space of (A - I). These are always equal for symmetric matrices, but for general matrices they can differ. When the geometric multiplicity is less than the algebraic multiplicity, the matrix is defective and cannot be diagonalized. You'll encounter this when dealing with matrices that have nilpotent components. A classic example is a Jordan block like [[2, 1], [0, 2]]. The eigenvalue 2 has algebraic multiplicity two but geometric multiplicity one. Numerical routines handle this gracefully by returning a Schur decomposition instead of a diagonalization, but if your downstream code expects a diagonal matrix PDP¹, it will break silently or crash depending on how you've written it.
Get the Full Details
When Eigenvalue Computation Fails Completely
Non-normal matrices are the worst case. A matrix is normal if AA = AA. Normal matrices have orthogonal eigenvectors, which makes everything numerically stable. Non-normal matrices do not, and their eigenvalues can be extremely sensitive to perturbations. There's no workaround that eliminates this sensitivity — it's a fundamental property of the problem. In my experience, when I encounter a highly non-normal matrix with badly conditioned eigenvalues, the practical move is to switch from eigenvalue analysis to singular value decomposition. The SVD is always numerically stable regardless of normality, and it gives you information about the matrix's action that's often more useful than eigenvalues anyway. You lose the direct eigenvalue information, but you gain reliability. If you genuinely need eigenvalues of a badly behaved non-normal matrix, the best approach is to use a high-precision library like MPFR with arbitrary precision arithmetic. It's slower, often an order of magnitude or more, but it can resolve eigenvalues that double precision simply cannot distinguish. For large sparse problems where you need interior eigenvalues — say, eigenvalues near a specific value in the middle of the spectrum rather than the extremal ones — standard ARPACK won't help because it targets only the largest or smallest magnitude eigenvalues. In that case, contour integral methods like FEAST or rational Krylov subspace techniques are the right tools. They work by integrating the resolvent around a closed contour in the complex plane that encloses the desired eigenvalues. This is more computationally expensive per eigenvalue but it's the only reliable way to target interior spectrum for matrices larger than a few thousand dimensions. The takeaway isn't that eigenvalues are complicated. They're conceptually straightforward. The complications come from numerical analysis, conditioning, sparsity patterns, and what you actually need the result for. Pick the right algorithm for your matrix structure and your actual output requirements instead of reaching for the first function that computes eigenvalues and hoping for the best.