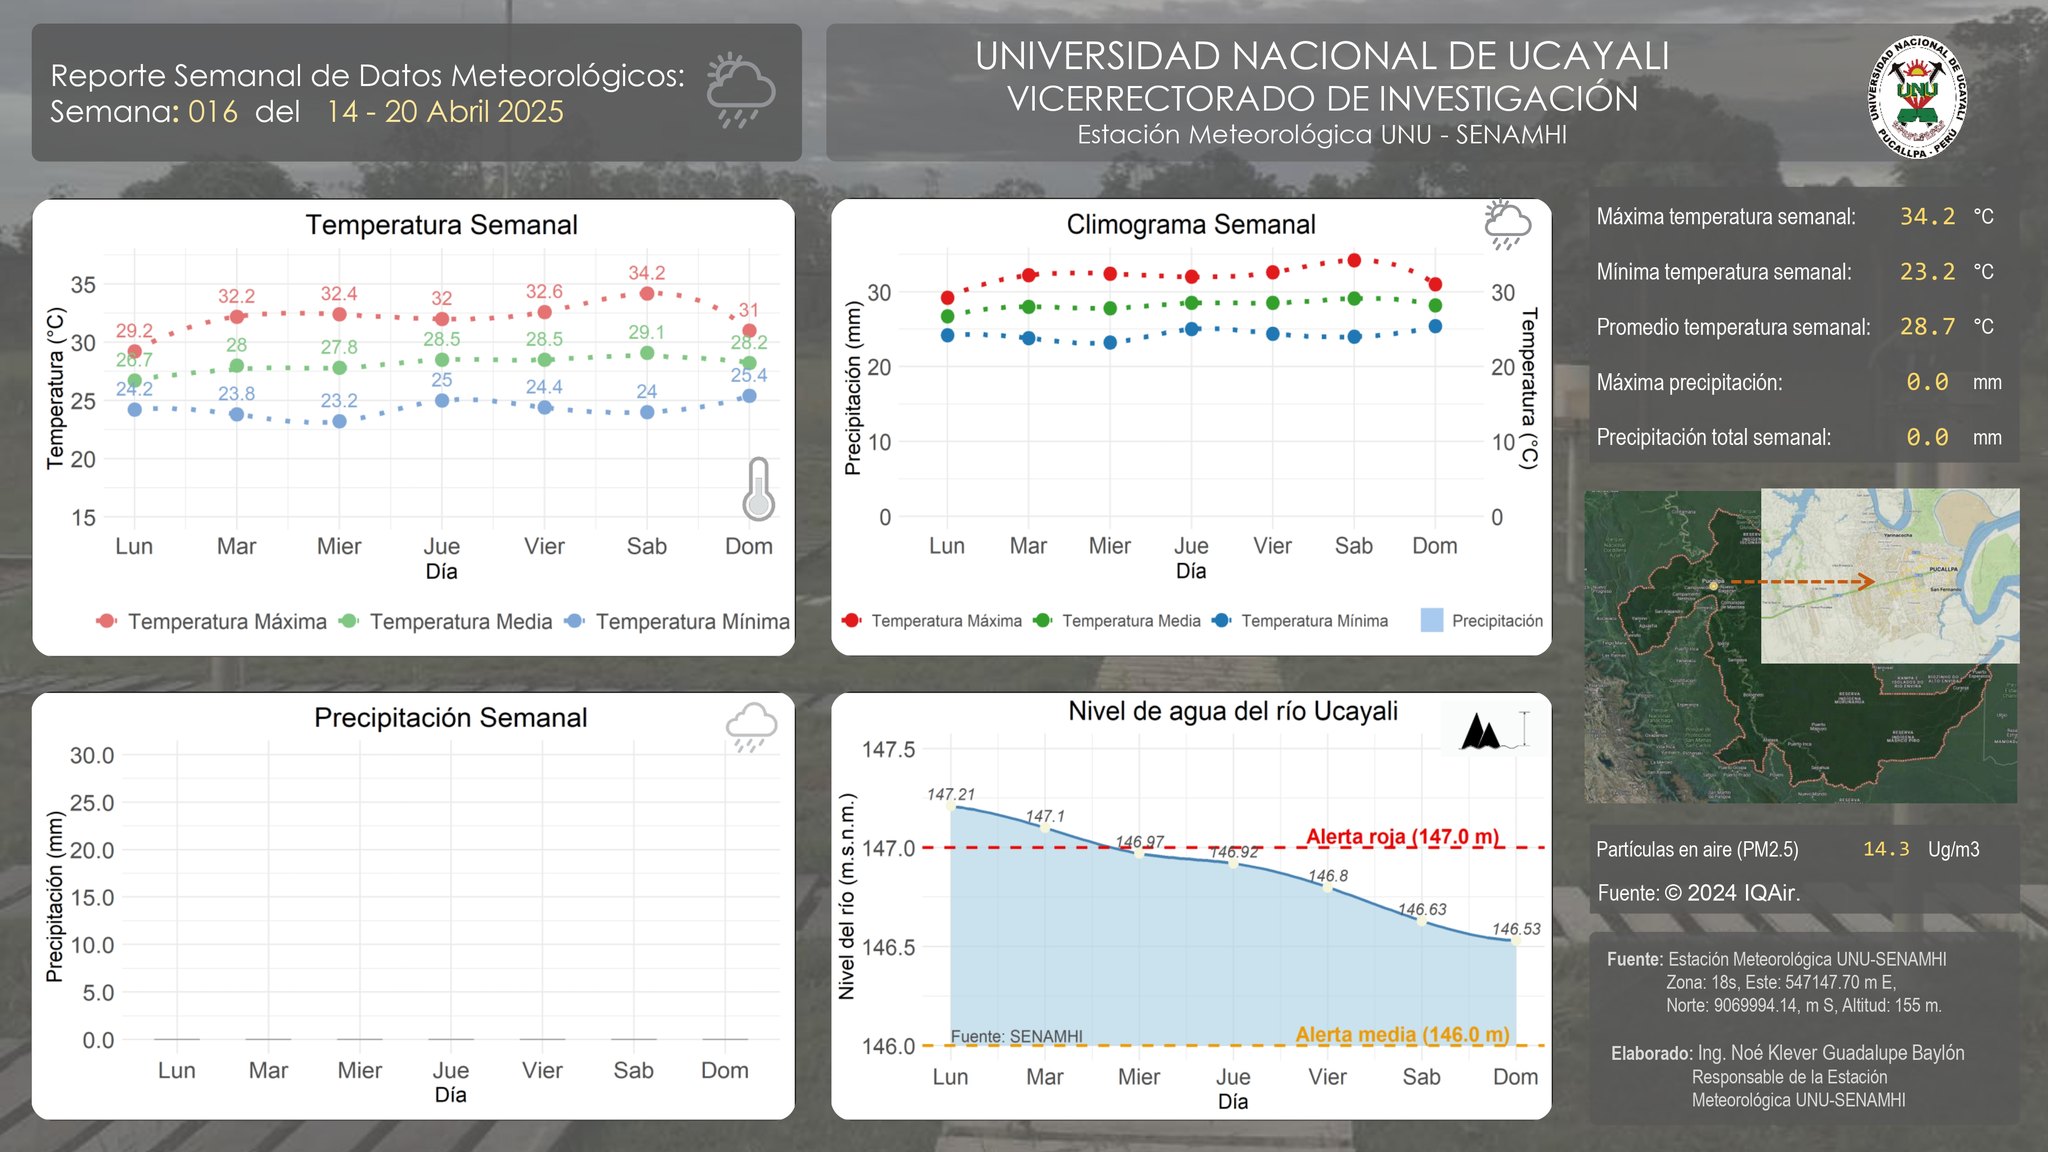
Writing a Meteorological Report: What It Actually Looks Like
The structure of a standard meteorological report follows an international format established by the World Meteorological Organization. You take observations from a weather station, compile them into a structured message, and broadcast it on the designated frequency or network. That's the whole thing in plain terms. I spent years working with automated weather station data at an agricultural research facility, and let me tell you—the report itself is straightforward. The hard part is cleaning the raw sensor data before it even gets formatted. I once had a temperature sensor drift by 3.2 degrees over a weekend because a calibration resistor failed silently. The report came out looking perfectly valid because the formatting software doesn't validate physical plausibility. You have to do that yourself with simple sanity checks: is the temperature within historical bounds for this location? Does the wind speed match the pressure tendency?
Data Collection and Encoding
A typical synoptic report—what we call a METAR in aviation or a SYNOP for surface observations—follows WMO manual No. 306. You gather temperature, dew point, atmospheric pressure, wind speed and direction, visibility, cloud layers, and present weather phenomena. Each element gets encoded into a standardized string. For example, wind is reported as direction in tens of degrees followed by speed in knots. A wind of 270 degrees at 15 knots becomes 27015. That's not arbitrary; it's been the convention since the 1930s because early radio operators needed compact messages that wouldn't get corrupted by static. Visibility is the trickiest field. Automated stations report prevailing visibility, which means the maximum distance objects can be seen over at least half the horizon. During a light drizzle event I was monitoring in the Pacific Northwest, the automated station reported 10 kilometers visibility because the rain wasn't uniform across the sensor field. A human observer on site would have noted 6 kilometers. This discrepancy matters for aviation briefings. My workaround was running a simple algorithm that cross-referenced visibility with relative humidity and precipitation intensity from the same timestamp. When RH exceeded 95 percent and rain was detected but visibility stayed at maximum, I flagged the report for manual review. It caught maybe 4 percent of reports, but those 4 percent were the ones that would have confused a pilot.
Cloud Layer Encoding
Clouds are reported in layers, each with height and type. Height comes from ceilometer readings or pressure-based estimation. Type uses standard abbreviations: FEW, SCT, BKN, OVC. I learned the hard way that the difference between SCT and BKN isn't just semantic—it determines whether a pilot needs IFR clearance. A scattered layer at 3,000 feet means visual meteorological conditions may still apply. Broken at the same altitude flips the calculation entirely. Getting this wrong once during a flight service briefing nearly caused someone to file an unnecessary instrument flight plan. We catch these errors now with a validation script that compares cloud ceiling against runway visual range and published approach minimums. The weather group is where most encoding errors happen. The WMO code table has over 80 weather codes, ranging from plain fog to volcanic ash. Automated systems typically handle the common ones—rain, snow, drizzle—but they miss things like dust storms or blowing snow until the particle counter triggers. I remember a situation in the Southwest where haboobs moved through faster than the update cycle. By the time the station logged significant dust, the previous report was already hours old. We switched to a hybrid reporting mode where nearby pilot reports triggered immediate updates to the synoptic network. It added maybe 20 percent more workload for the operators, but the data quality for that region improved noticeably. You don't need special equipment to read meteorological reports. The United States National Weather Service publishes current and historical data at weather.gov, and the global archive is available through NOAA's National Centers for Environmental Information. For raw observational data, the Integrated Surface Database holds decades of hourly records. If you're building something that consumes these reports programmatically, the API endpoints are documented and free for non-commercial use.
Get the Full Details

The European Centre for Medium-Range Weather Forecasts offers a different format that some international researchers prefer. Their reports include additional parameters like soil temperature and radiation measurements that standard surface reports omit. I've seen agricultural models fail because someone fed them US-format METAR data expecting European-level granularity. Always check the source documentation before assuming compatibility.
Common Pitfalls
Time zone confusion is the number one error I see. Reports use UTC by convention, but many public-facing weather services convert to local time in their displays. If you're parsing raw report data and the timestamps look off by six or twelve hours, check whether you're reading the encoded hour or a converted display value. The encoding itself is always UTC—Zulu time, as pilots call it. I lost two days debugging a dataset once because the CSV export had timezone conversion applied inconsistently across columns. Some fields stayed in UTC while others shifted to EST depending on when the export ran. Another issue is automated versus manual observation codes. In the metadata, there's a flag indicating whether the report was generated by instrument or human observer. Automated reports tend to overestimate visibility in marginal conditions and underestimate cloud base height. When I build datasets for research, I separate these two sources and apply different quality control thresholds to each. Treating them as interchangeable introduces systematic bias that shows up clearly in long-term trend analysis. Historical reports have their own problems. Older stations used different instruments with different accuracies. A station that reported wind at 10-meter height in 1985 might have been using an older anemometer model with higher friction thresholds. The official adjustments are documented in station metadata, but you have to look them up individually. There's no blanket correction factor you can apply across a whole network. I've seen analysts skip this step and wonder why their trend lines showed artificial jumps coinciding with station upgrades.