Understanding the Formula Of Coefficient Variation
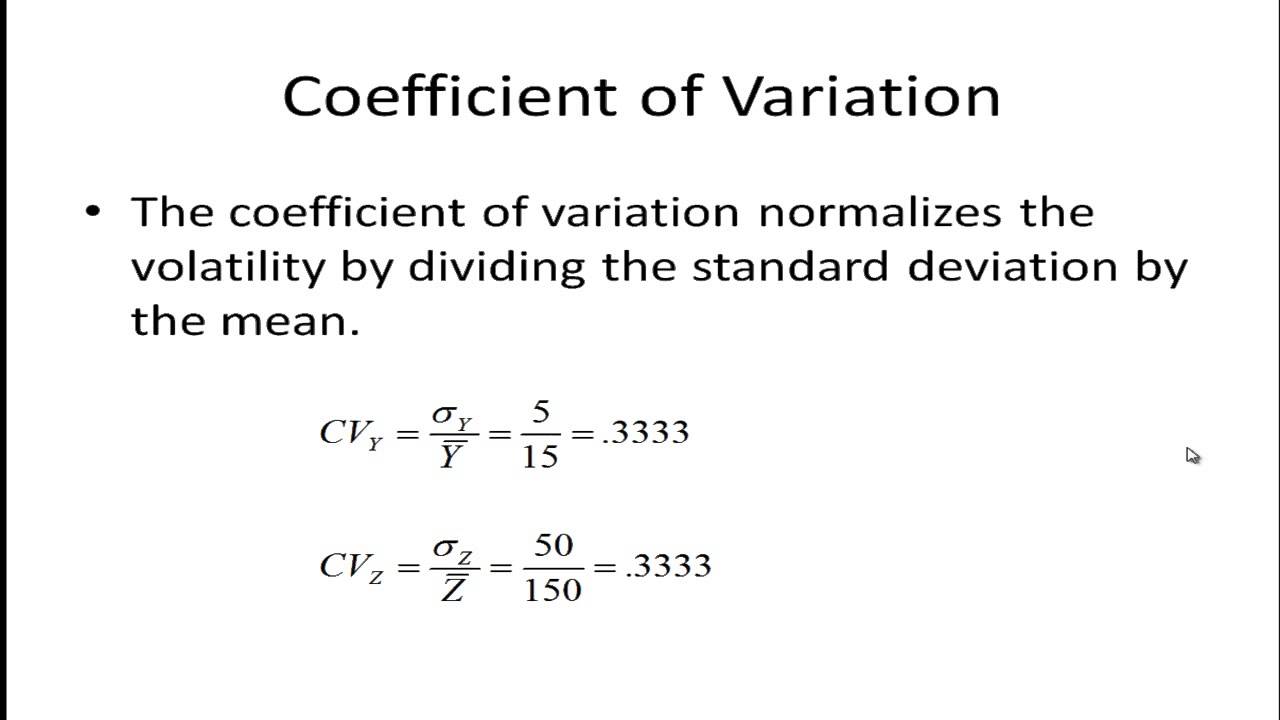
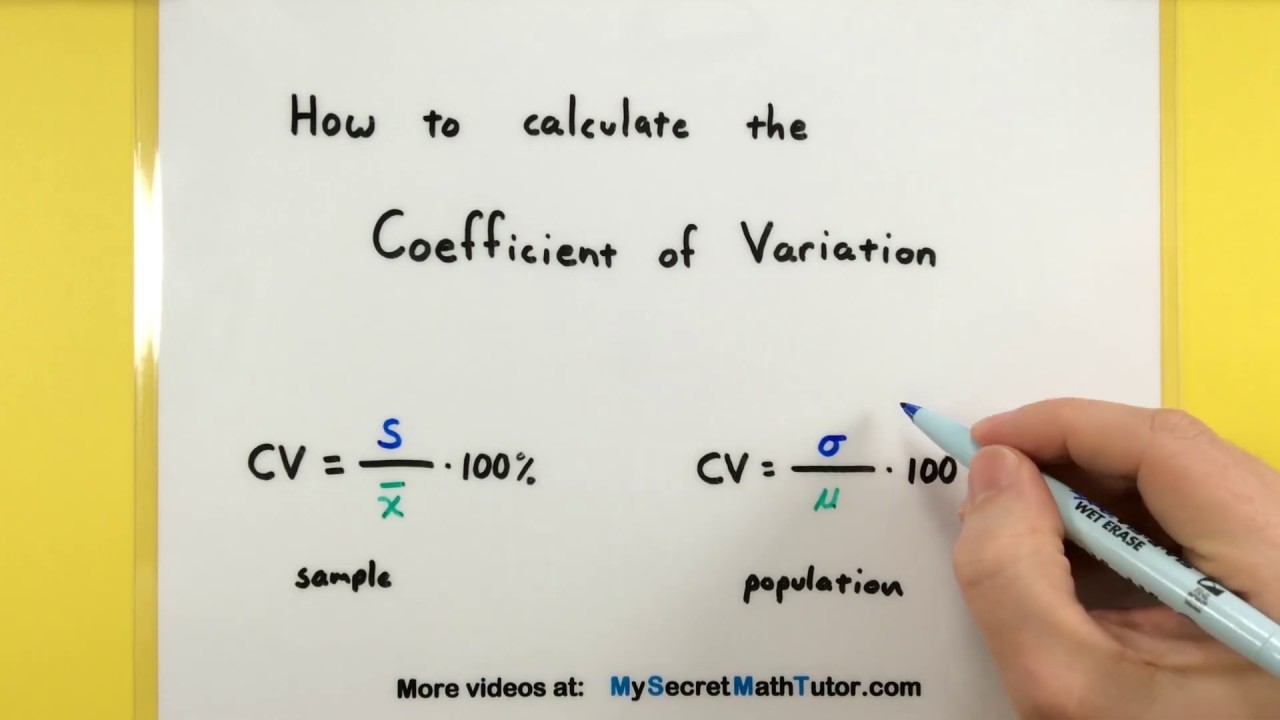
The coefficient of variation is a way to express the dispersion of data relative to its mean. You take the standard deviation, divide it by the average, and you get a unitless number that lets you compare spread across datasets that use different scales. That is the entire idea. The calculation is straightforward: CV = ( / ) × 100
Where is the standard deviation and is the population mean. For a sample, you use s instead of and x instead of . The result is typically expressed as a percentage, though some fields leave it as a decimal ratio. Both are used, and mixing them up without noticing will give you numbers that are off by a factor of 100. I calculate this by hand at least once a month. Most people reach for Excel or R. Either way works. The math does not change.
How it actually behaves in real data
Here is where people get tripped up. The CV assumes you are working with ratio-scale data where zero is a true absence. If you use Celsius temperatures, the CV is meaningless. A mean of 10°C with a standard deviation of 2 gives a CV of 20%. Shift everything to Kelvin and you get a CV of about 7%. The underlying data has not changed at all. The formula has. This came up in a project I was running a few years back. We were comparing variability in sensor readings across two manufacturing lines. One line produced parts with dimensions centered around 0.02mm, and the other around 50mm. The raw standard deviations were similar in magnitude, but the CV made the comparison workable. However, one batch on the precision line had a mean drift to nearly zero due to a calibration fault. The CV for that batch spiked to over 400%. I had to flag it as invalid rather than treat it as a real finding. The formula does not know when your data is garbage. You have to.
Get the Full Details

Bias in small samples
The sample CV is a biased estimator of the population CV. This is rarely mentioned in introductory materials but it matters when your sample size drops below about 30. The bias correction factor is roughly 1 + 1/(4n). So with n = 10, your CV is understated by about 2.5%. With n = 5, it is understated by nearly 5%. Not huge, but enough to skew conclusions in quality control work where you are comparing against tight tolerance limits. I started applying a simple correction in my own work after a client pointed out that our within-batch CV estimates were consistently lower than the between-batch values they had from prior audits. The discrepancy traced back entirely to small sample sizes on our end. Once I adjusted, the numbers aligned.
When the mean is near zero
Division by a small mean is the most common failure mode of this metric. I have seen people report CVs in the thousands for data where the mean is essentially noise. The number looks dramatic but says nothing useful. My workaround depends on context. If the data are strictly positive and the near-zero mean is a real phenomenon, I log-transform the data first, compute the CV on the transformed scale, and interpret accordingly. If the near-zero mean is an artifact of outliers or a bad measurement, I clean the data before calculating. Neither approach is perfect, but reporting the uncorrected CV in these situations is worse.
Practical pitfalls to watch for
One thing I see constantly is people comparing CVs across groups where the variances are proportional to the mean in a non-linear way. In that case, the CV is not constant across the range, and a single summary number misrepresents the data. You need to check whether the relationship between mean and standard deviation is approximately linear before relying on the CV as a comparison tool. Another issue is using the CV with negatively skewed distributions where the mean can approach zero from the positive side. The metric becomes unstable. I switch to median-based dispersion measures like the median absolute deviation divided by the median, which gives a similar relative measure without the division-by-near-zero problem.
Quick reference for common use cases
In finance, the CV of portfolio returns is used as a rough risk-adjusted metric, though Sharpe ratios are more standard. In analytical chemistry, it is the go-to for method precision, and instruments often have a CV threshold of under 5% built into their acceptance criteria. In ecology, researchers use it to compare trait variability across species. In each field, the formula is the same but the interpretation standards differ significantly. The math itself takes about five seconds. Understanding when not to use it takes considerably longer.