
First, Let's Talk About Why Your Schema Keeps Breaking
I spent three weeks tracking down why a reporting query kept returning duplicate customer records. The answer was a many-to-many relationship masquerading as a one-to-many because nobody bothered to add a junction table. This is the kind of thing that happens when you design for what you think you need today instead of what the data actually demands tomorrow. Fundamentals Of Relational Database Design isn't about memorizing normalization forms. It's about understanding the consequences of every relationship you declare and making sure they hold up when something changes six months down the line. The people who skip this end up with schemas that require application-level workarounds for basic queries.
The Core Concept: Relationships, Not Tables
Most beginners think database design is about creating tables. It's not. It's about declaring relationships between entities and enforcing them at the database level where they belong. Tables are just containers. The schema is the contract. When I design a new system, I start with a few questions that most tutorials skip entirely. What operations need to happen? What queries will be read-heavy versus write-heavy? What are the cardinality constraints, and more importantly, which ones are soft versus hard? A transaction cannot exist without a customer — that's a hard constraint, enforce it with a foreign key. A product may or may not have a category — that's soft, allow nulls. The common mistake I see repeatedly is treating every relationship the same way. Foreign keys are not optional decorations. They are the primary enforcement mechanism for data integrity. When I've had to choose between adding a foreign key and letting the application validate relationships, I pick the foreign key every time. Applications lie. Databases don't — unless you tell them not to enforce the constraints.
One thing people don't tell you about foreign keys: they have a performance cost on writes. Every insert or update on a child table checks the parent. This is usually fine until you're doing bulk loads. I once had to load 4 million rows into a production database and every foreign key check added roughly 8 milliseconds per row. We disabled the constraints temporarily, loaded the data, then re-enabled them with WITH NOCHECK for existing rows and full enforcement going forward. That cut our load time from about 45 minutes to roughly 12 minutes.
Get the Full Details

Normalization Is a Scale, Not a Rulebook
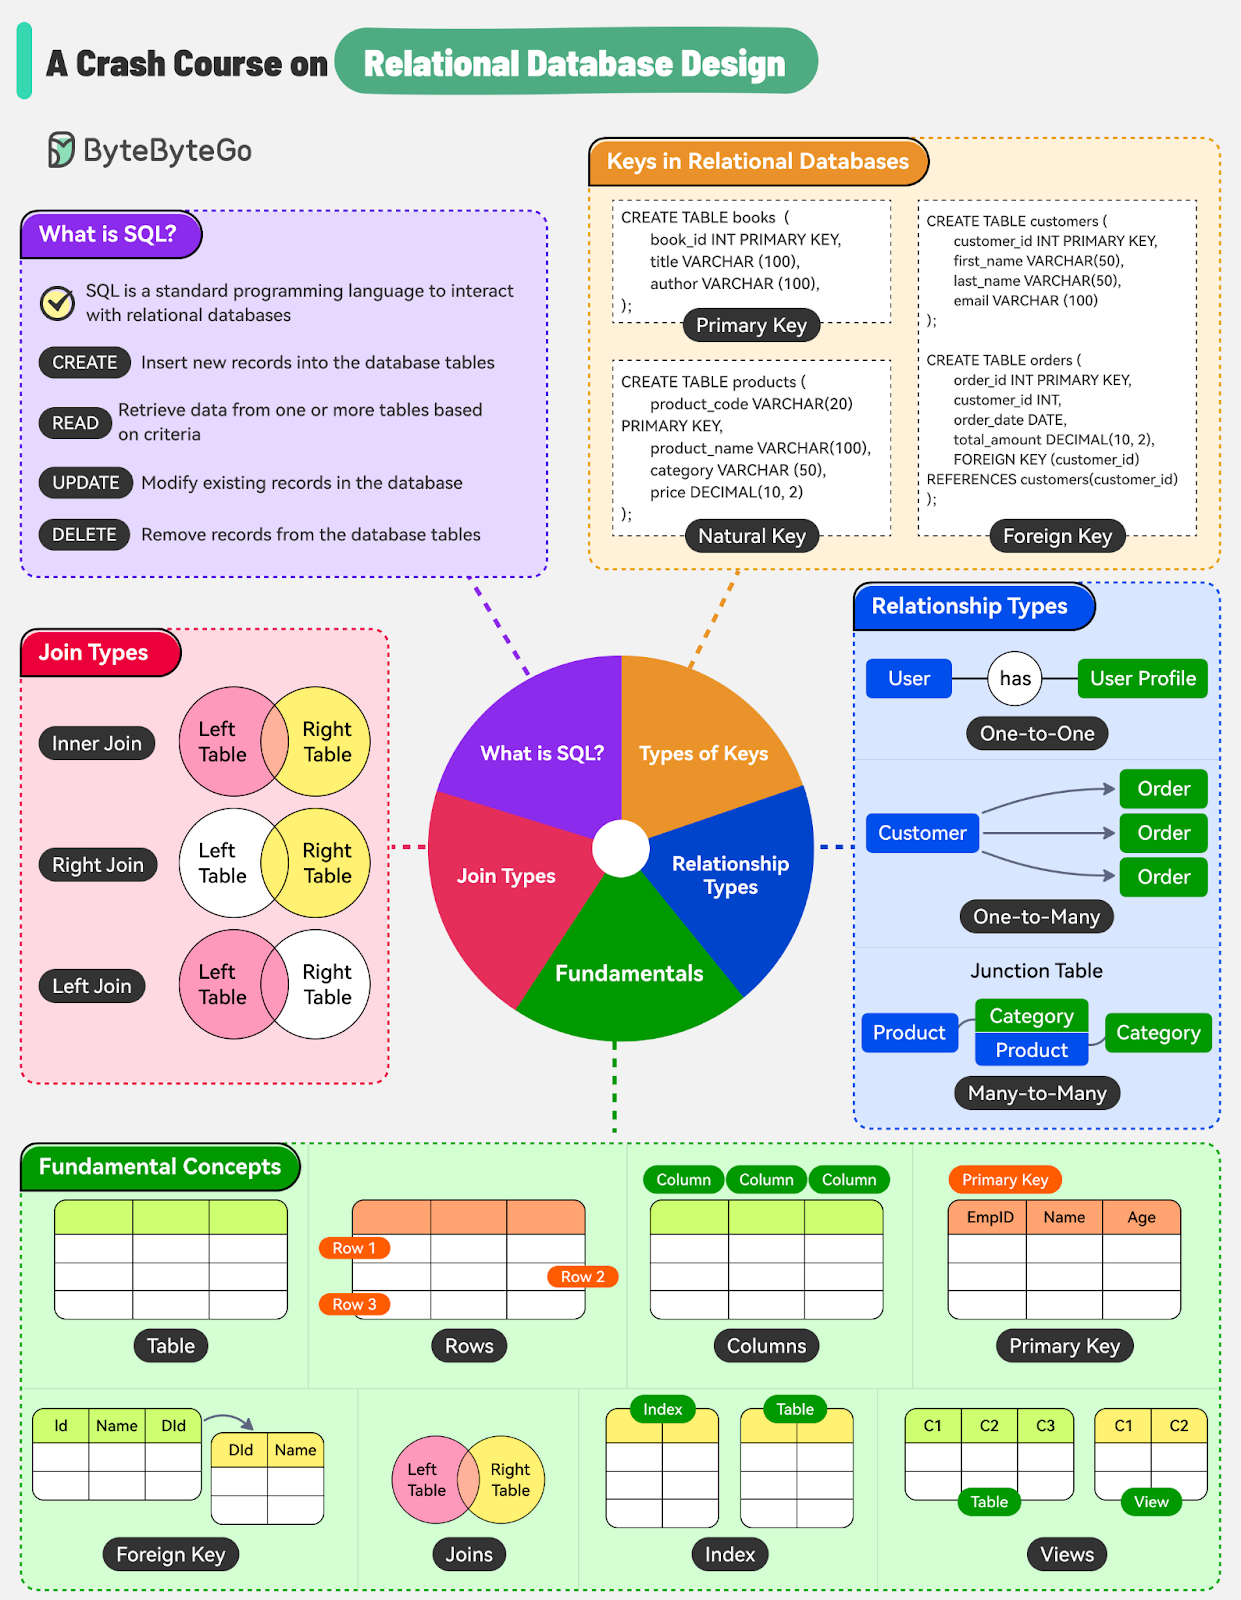
You will hear people insist on third normal form. You will also hear people say normalization kills performance. Both are right, and both are wrong, depending on which part of the scale you're on. First normal form means no repeating groups. Each cell contains a single value. This is non-negotiable. I once saw a schema where a "phone_numbers" column stored semicolon-delimited lists like "555-0100;555-0101;555-0102". Queries against that column were nightmares, indexes were useless, and adding a new phone number required parsing strings in the application layer. The fix was a separate PhoneNumbers table linked by a foreign key. Took two hours of refactoring that saved about six months of accumulated technical debt. Second normal form eliminates partial dependencies. If you have a composite primary key, every non-key column must depend on the entire key, not just part of it. This is where most real-world schemas fail. Order details are the classic example — order_id plus product_id as a composite key, with columns like product_name that depend only on product_id. Move product_name to the Products table.
Third normal form removes transitive dependencies. Column C depends on B, and B depends on A, so C shouldn't be in the same table as A. Customer tables that store city and state when those values already exist in a Locations table are doing this wrong. The state can change — what was once one state might split into two, as Arizona and Texas both dealt with during various boundary discussions over the years. If you're storing state names in your customer table and a state name changes, you've got a consistency problem. But here's the counter-intuitive part: denormalization is often the correct answer for read-heavy workloads. I designed a reporting database for a logistics company where we deliberately kept country_name denormalized into the Shipments table despite it violating third normal form. The Countries table had maybe 300 rows and the Shipments table had hundreds of millions. Joining against Countries on every query was unnecessary overhead. We accepted the minor write amplification and gained query performance that mattered more. The trade-off was worth it because country names don't change frequently enough to cause real inconsistency problems.
Choosing Keys: The Decisions That Haunt You Later
Primary keys determine how data is indexed, how relationships are expressed, and how queries perform. This is where I see the most lasting damage from rushed decisions. Natural keys use existing business values — a social security number, a product SKU, an email address. They make intuitive sense but they cause problems when those values change or when they're long. A UUID is 16 bytes. An email-based foreign key might be 50 bytes. Multiply that by every index and every join in your database, and you're paying a noticeable storage and performance tax. Surrogate keys solve this with auto-incrementing integers or UUIDs. They have no business meaning. They're stable. They're compact. The downside is that they feel wrong to people who want their database to reflect business reality. They're also harder to debug — looking at order_id 847291 tells you nothing, while looking at SKU-2024-8847 tells you exactly which product was ordered.

I use surrogate keys for most tables and natural keys only when there's a genuine operational reason. The one exception I consistently make is audit tables where the natural key provides traceability. If someone needs to track which employee made a change, including their username in the audit record alongside an integer ID is actually useful. The integer ID still handles the relationships efficiently. Composite keys are another area where people get comfortable too quickly. A composite primary key on (user_id, created_at) for an activity log table sounds reasonable. But when you need to join that table from five different places, every foreign key becomes a composite foreign key too. Every index on that table is wider. Queries become more complex. I prefer a simple integer surrogate key and a unique constraint on (user_id, created_at) instead. Same uniqueness guarantee, cleaner relationships.
Relationship Modeling: The Part Where Most People Go Wrong
One-to-many relationships are straightforward. Add a foreign key to the child table pointing to the parent. Everyone gets this right initially. Many-to-many relationships require junction tables. This is where I see the most variation in quality. A junction table for orders and products needs order_id, product_id, and at minimum a quantity field. That quantity field makes it more than just a relationship table — it becomes its own entity with properties. The temptation is to skip it and store quantities as columns on the products table, but that breaks when a single order contains multiple products. Optional relationships — where the foreign key can be null — need careful handling. A blog post might have zero or one featured image, but it always has an author. Making the image_id nullable is correct here. Making author_id nullable would mean accepting posts without authors, which violates your business rules. The database should enforce that distinction.
Cascading deletes are convenient but dangerous. Setting ON DELETE CASCADE on a foreign key means deleting a customer also deletes their orders, their reviews, their support tickets. Six months later you'll be restoring data because someone deleted a customer record without realizing it wiped three years of transaction history. I use cascading deletes sparingly — mostly on audit trails and temporary session data where deletion is intentional. For anything with historical value, I use ON DELETE RESTRICT or handle the cascade in application code where I can add confirmation logic.

Indexing: Not Just "Add an Index" Without Thinking
Indexes speed up reads but slow down writes. Every index on a table adds overhead to every insert, update, and delete. This is the fundamental trade-off that most tutorials mention in one sentence and never come back to. Composite indexes follow leftmost-prefix matching. An index on (last_name, first_name, email) can serve queries filtering on last_name alone, last_name plus first_name, or all three columns. It cannot serve a query filtering on first_name alone because first_name is not the leading column. I've seen developers create separate indexes for every column combination they can think of, which bloats the schema and degrades write performance. Create one well-designed composite index and test it against your actual query patterns. Covering indexes store all the columns a query needs directly in the index structure. When the database can satisfy a query from the index alone without touching the table, that's a covering index. This requires careful analysis of your most frequent queries. I built a covering index for a query that ran 40,000 times per hour by including the three filter columns and the two selected columns. It eliminated table lookups entirely for that query and reduced its execution time from about 3 milliseconds to under 0.2 milliseconds.
But covering indexes have a cost. They're wider, they consume more storage, and they slow down writes more than narrow indexes. A covering index on a table with 10 million rows that gets 5,000 writes per minute can add noticeable latency to every write operation. The question is whether your read performance gain justifies the write degradation. In my experience, it does for query-heavy tables but not for tables where writes dominate.
Common Pitfalls I See in Production Code
Storing dates as strings. I've inherited databases where date fields were varchar(255) because someone couldn't decide between formats or because an ORM generated the schema automatically. Sorting, filtering, and calculating age differences against string dates is painful and error-prone. Cast them properly or migrate them before you build features on top of them. Treating NULL the same as empty string. In SQL, NULL means unknown. Empty string means known to be empty. They behave differently in queries, constraints, and aggregations. A column with a UNIQUE constraint treats two NULLs as distinct values in most databases, which means you can have multiple NULLs in a "unique" column. This trips up people who expect NULL to behave like a regular value. If you need to enforce uniqueness including NULLs, some databases offer partial indexes or exclusion constraints that handle this correctly. Overusing generic timestamp columns. I once encountered a table with created_at, updated_at, deleted_at, archived_at, and reviewed_at all as timestamps. Five timestamp columns for one entity. Most of them were null most of the time. The solution was to collapse archived_at into updated_at with a separate status column and remove reviewed_at entirely — that information lived in a separate audit table anyway. Fewer columns means narrower indexes, faster queries, and less confusion about which timestamp actually matters for a given operation.
One specific edge case that took me weeks to resolve: a multi-tenant application where each tenant's data lived in tables with identical schemas but different tenant_id foreign keys. The application needed to query across all tenants for administrative reports, but regular users should only see their own data. I implemented row-level security policies at the database level instead of filtering in the application. This was more complex to set up initially — about a day of configuration — but it prevented any possibility of a developer forgetting to add the tenant filter to a new query. Application-level filtering failed about once per quarter when someone wrote a new endpoint and missed the constraint. Database-level filtering never has that problem.
Practical Steps for Fundamentals Of Relational Database Design
Start with entities, not tables. Write down the nouns in your system — customer, order, product, payment. Identify the relationships between them before you write a single CREATE TABLE statement. A piece of paper is faster than a tool for this. I've used physical whiteboards and sticky notes for early schema design because dragging boxes around on a screen feels productive but doesn't force you to think through the relationships as carefully. Write your queries first. Before creating the schema, write the five most important queries your application will run. Look at what columns, joins, and filters they need. Design the schema to serve those queries efficiently. This reverses the typical workflow where people design tables and then figure out how to query them. Query-first design catches missing indexes and poor normalization decisions before they're baked in. Test with realistic data volume early. A schema that works fine with 100 rows per table might fall apart at 100,000. I create a test database with synthetic data matching expected production volumes and run your query patterns against it. This usually reveals index gaps and join issues within a few hours of testing, which is dramatically cheaper than fixing them after deployment.
Document your constraints explicitly. A foreign key constraint in the schema definition is good. A comment explaining why it exists is better. "This foreign key prevents orphaned orders" is worth more than the constraint alone because six months from now when someone modifies the schema, they'll understand the consequence of removing it. I've seen developers remove foreign keys they considered "redundant" because they didn't understand the business rule the constraint was enforcing. Review your schema quarterly. Systems evolve and schemas drift. A constraint that made sense when you designed it might be outdated. A denormalized column might no longer provide meaningful performance benefit if your query patterns changed. I schedule schema review sessions every three months where I examine slow query logs, check for unused indexes, and verify that constraints still match current business rules. This takes about two hours per session and prevents the kind of schema decay that makes later migrations expensive. Not everything benefits from a relational database. If your data is inherently hierarchical, graph-based, or document-oriented, a relational model might fight you at every turn. I switched a content management system from PostgreSQL to a document store because the entity relationships were too fluid — pages could have any number of nested sub-pages with no fixed depth. Trying to model that with adjacency lists or closure tables in a relational database was adding complexity without gaining anything. Know when the tool doesn't fit the job.
The fundamentals aren't complicated. They're just easy to overlook when you're focused on getting features shipped. A clean schema with proper constraints, appropriate normalization, and thoughtful indexing will save you months of debugging and refactoring. It won't prevent every problem — there will always be edge cases and changing requirements — but it will give you a foundation where the edge cases are manageable rather than catastrophic.
