Getting Your Data Clean Before Anything Else
I spent three weeks debugging a facility location model that kept returning identical scores for every alternative. The issue wasn't the algorithm. It was the input matrix. When experts rated seven different criteria on near-identical triangular fuzzy numbers, the ranking engine couldn't distinguish between options because the membership functions overlapped almost completely. We ended up switching to a simpler weighted sum on crisp values, but it took two weeks to realize the fuzzy approach was drowning in noise. The core problem with Fuzzy Multiple Attribute Decision Making (FMADM) isn't theoretical. It's that people don't give you clean fuzzy data. They give you vague recollections dressed up as confidence intervals. Your first job is filtering out responses where the lower bound, middle, and upper value of a triangular fuzzy number cluster within a range so tight that fuzziness becomes meaningless. If your triangle spans less than 0.05 on a normalized scale, treat it as a crisp number instead. The computational overhead of handling it as fuzzy adds nothing.
What Fuzzy Multiple Attribute Decision Making Actually Handles
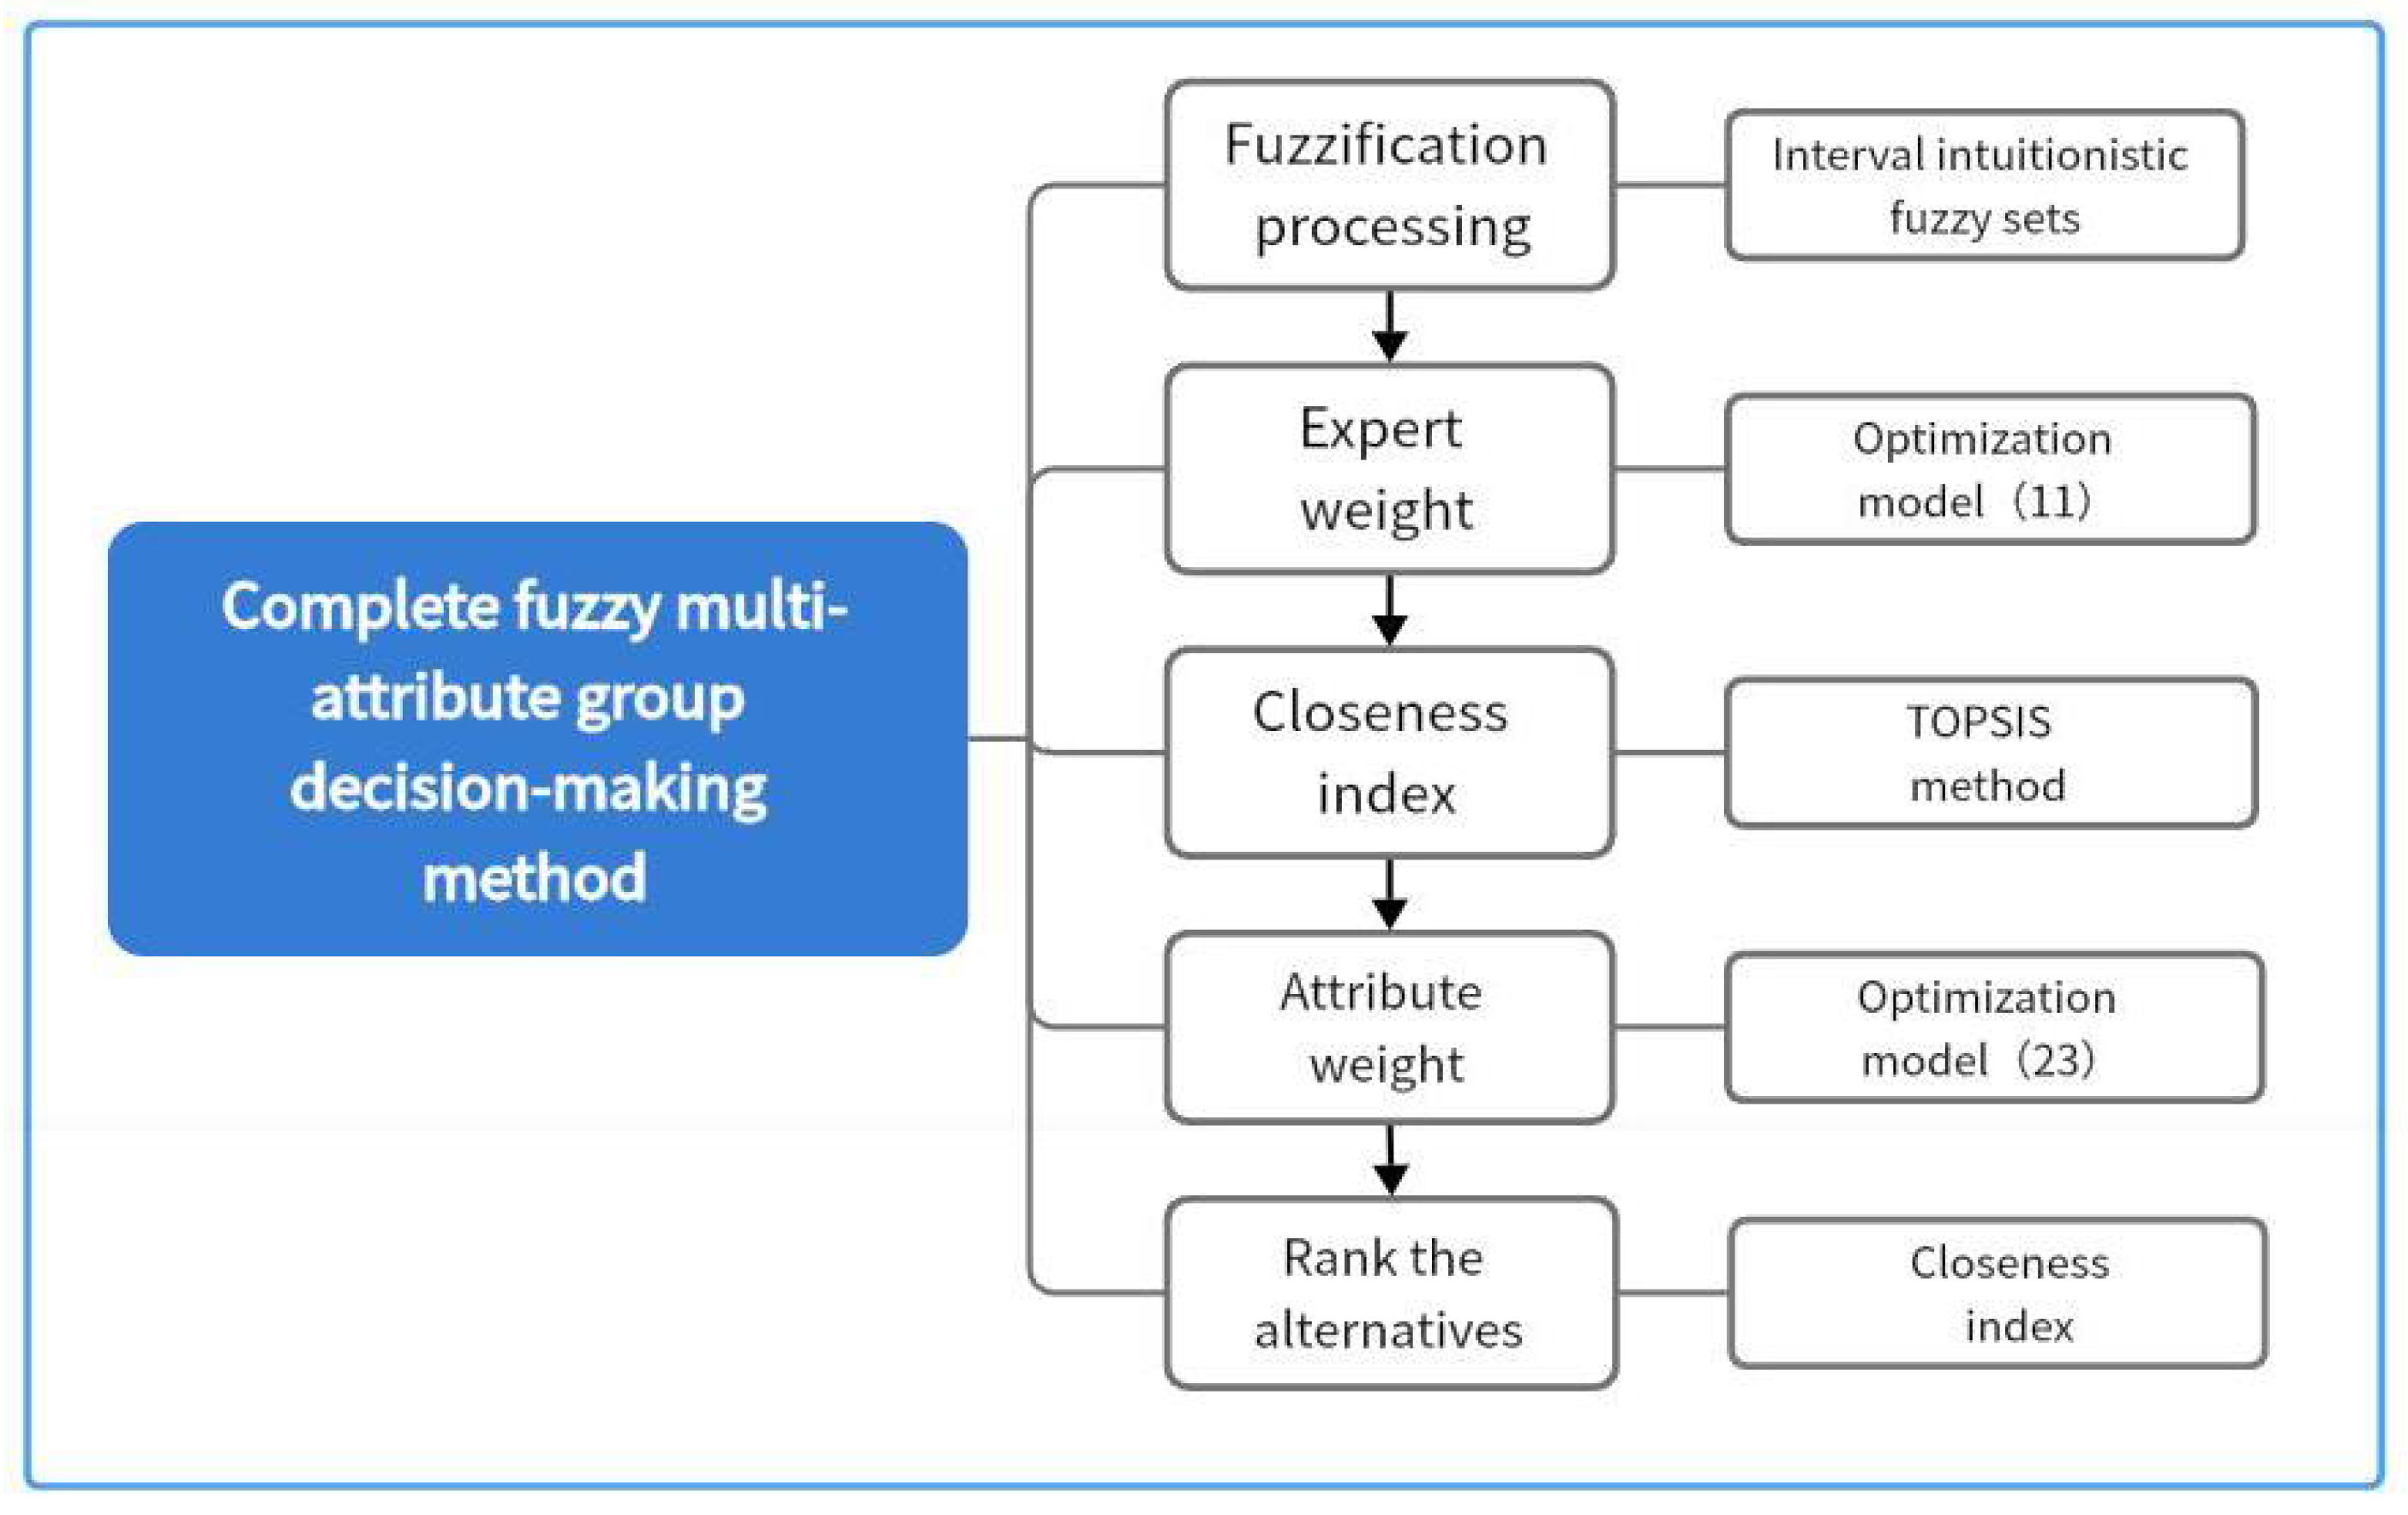
At its foundation, FMADM deals with decisions where both the attribute values and sometimes the decision maker's preferences carry uncertainty. Classic MADM methods like TOPSIS or VIKOR assume you have precise numerical ratings. Real-world evaluation rarely works that way. An engineer assessing supplier reliability doesn't know the exact defect rate. She knows it's probably around 2%, maybe as high as 5%, and she'd be surprised if it dropped below 1%. That's a triangular fuzzy number (1, 2, 5) expressed in percentage terms, and FMADM frameworks are built to process exactly this kind of imprecise input across multiple competing criteria. The typical workflow involves several stages. You define your decision alternatives and evaluation criteria first. Then you collect fuzzy ratings from experts or historical data, assigning each alternative a fuzzy score on each criterion. Next comes normalization, which is where most people go wrong. For benefit criteria, you divide by the maximum fuzzy value across alternatives. For cost criteria, you invert. The arithmetic here uses fuzzy number operations rather than standard division. After normalization, you weight the criteria using either entropy methods, AHP-derived weights, or direct expert assignment. Finally, you aggregate the weighted normalized fuzzy ratings and rank alternatives using a score function or defuzzification technique.
The Aggregation Step Is Where Things Get Messy
I've seen implementations use simple arithmetic mean for aggregation and others use the weighted geometric mean. The difference matters more than most practitioners admit. Geometric mean tends to penalize alternatives that perform poorly on any single criterion, which aligns with compensatory versus non-compensatory decision logic. If you're evaluating safety-critical systems where one bad score should hurt significantly, geometric aggregation makes more sense. For routine procurement decisions where trade-offs are expected, arithmetic weighting is fine and easier to explain to stakeholders who don't have a math background. The defuzzification step also deserves attention. Common approaches include the centroid method, graded mean integration, and the sign distance method. Centroid is the most cited but also the most computationally expensive for large-scale problems. Graded mean integration, which Ching-Tzong Cheng proposed in 1998, gives you a single crisp value from a triangular fuzzy number using the formula (a + 4b + c) / 6 where a, b, and c are the lower, middle, and upper bounds. It's fast, it's deterministic, and it preserves the shape information of the original fuzzy number well enough for ranking purposes. I use it almost exclusively now. Here's a concrete scenario that illustrates the whole process. A municipal water authority needed to select a treatment technology among three candidates: reverse osmosis, advanced oxidation, and membrane bioreactor. They had five criteria: capital cost, energy consumption, effluent quality, operational complexity, and land requirement. Six engineers provided fuzzy ratings on a linguistic scale mapped to triangular fuzzy numbers. The scale went from very poor (0, 0, 0.2) through poor (0, 0.2, 0.4), fair (0.2, 0.4, 0.6), good (0.4, 0.6, 0.8), to very good (0.6, 0.8, 1). They computed criterion weights using entropy-based fuzzification, which yielded capital cost at 0.23, energy at 0.19, effluent quality at 0.21, operational complexity at 0.18, and land at 0.19. The entropy method detected that capital cost had the highest dispersion across alternatives, making it the most discriminating criterion, while land requirement showed very similar fuzzy ratings for all three technologies and received a correspondingly low weight.
Get the Full Details
After normalization, weighting, and aggregation, they applied graded mean integration to each alternative's score. Reverse osmosis came out ahead primarily because its fuzzy rating on effluent quality was consistently in the good to very good range across all six evaluators. The membrane bioreactor was close but dragged down by a wider spread on operational complexity, indicating disagreement among the engineers about how difficult it would be to run. That spread didn't disappear during defuzzification. It stayed as a meaningful signal that the technology choice carried higher implementation risk, which the ranking alone didn't convey.
Common Mistakes That Break FMADM Models
Inconsistent normalization direction is the most frequent error. Some criteria are benefits where higher is better, others are costs where lower is better. If you normalize cost criteria by dividing by the maximum instead of taking the reciprocal, your rankings will be inverted for those attributes and the final result will be wrong without any obvious warning sign. Always verify that after normalization, all criteria are oriented in the same direction before proceeding to weighting. Another issue is mixing fuzzy numbers with different shapes. Triangular fuzzy numbers work cleanly together. When you introduce trapezoidal or interval-valued fuzzy numbers into the same calculation, standard arithmetic operations become more complex and some published formulas break entirely. I once inherited a model that combined triangular and trapezoidal inputs because different departments used different rating scales. Converting everything to triangular form via area-based equivalence preserved the essential information and restored computational tractability. The biggest blind spot I've encountered is treating FMADM as a substitute for genuine stakeholder engagement. The method produces rankings. It doesn't validate whether your criteria actually matter to the people affected by the decision. In one project, the entropy-derived weights made "environmental impact" the second most important criterion at 0.22, but when we presented the ranking to the community advisory board, they said that criterion was mostly symbolic and their real concern was project timeline, which had received a weight of only 0.07. The fuzzy math was internally consistent. It was just optimizing for the wrong thing because the criteria weights came from a mathematical procedure rather than from the people who would live with the outcome.
When FMADM Doesn't Work Well
Fuzzy multiple attribute decision making struggles in high-dimensional settings. Once you exceed roughly fifteen criteria, the discrimination power of any defuzzification method drops significantly. The aggregated scores tend to cluster together regardless of the underlying data. I've seen it with procurement evaluations that expanded to twenty-two criteria across ten alternatives. The top three ranked options shifted position with every change to the defuzzification formula, which meant the ranking wasn't stable enough to justify a decision. In those cases, moving to a two-stage approach where you first eliminate alternatives that fail hard constraints on critical criteria, then apply FMADM only to the survivors, produces far more actionable results. The method also breaks down when expert judgments are systematically biased. If a group of evaluators all tend toward mid-range scores to avoid controversy, the resulting fuzzy numbers will have narrow spreads and similar centroids across alternatives. The model will produce a ranking that looks precise but is essentially random. There's no mathematical fix for this. You need to detect it during the data collection phase by checking the variance of ratings per criterion across evaluators and flagging criteria where inter-rater agreement is suspiciously low. In those situations, gathering additional independent evaluations or switching to a method that incorporates inconsistency detection, like fuzzy AHP with consistency ratio checks, is worth the extra effort. If you're looking for a starting point to implement this, the R package fuzzyMCDA provides functions for fuzzy TOPSIS, fuzzy VIKOR, and fuzzy weighted aggregation using triangular fuzzy numbers. It's not exhaustive but it covers the most common procedures. For Python, there's no single mature library that handles the full pipeline, so most practitioners build custom implementations using numpy for the fuzzy arithmetic and pandas for the matrix operations. The actual code for a basic fuzzy TOPSIS implementation is under two hundred lines if you stick to triangular fuzzy numbers and graded mean integration for defuzzification.