Getting Points on a Grid Without Losing Your Mind
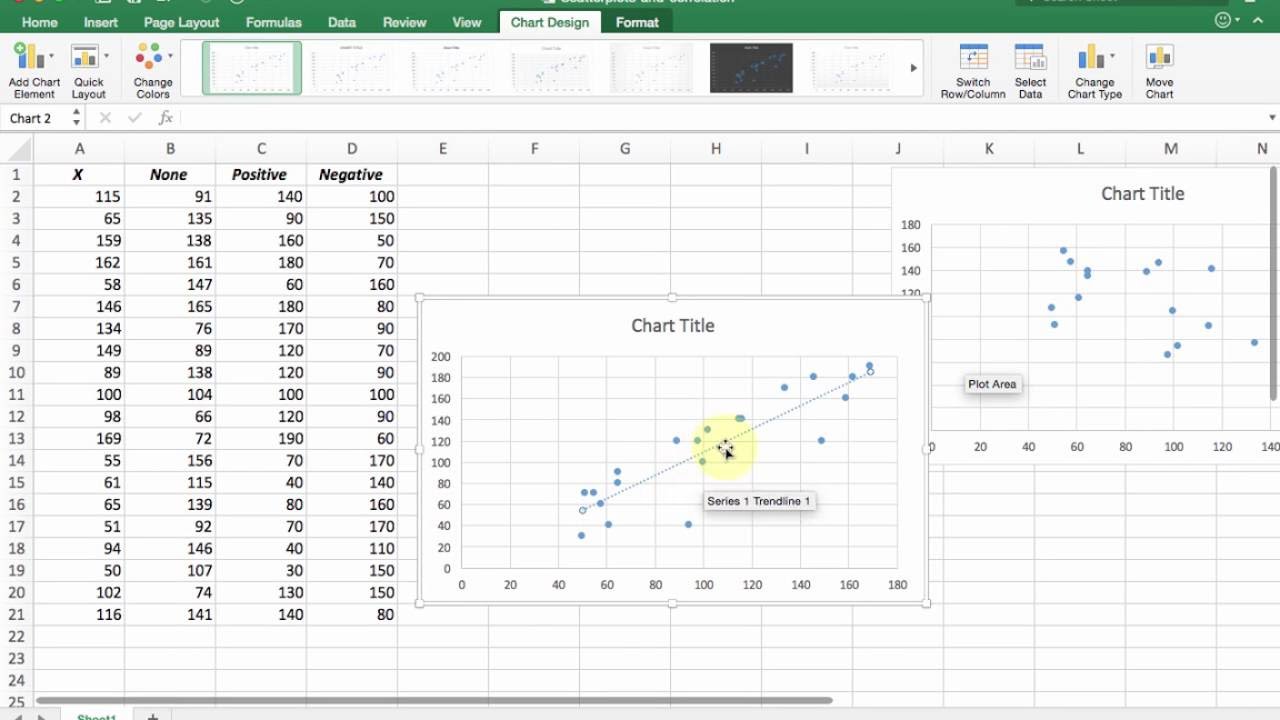
Most people approach this completely backwards. They start by looking up what a scatter plot is instead of just throwing some data at a chart and seeing what happens. The actual workflow is simpler than the documentation makes it sound. You need two columns of numbers—one for the x-axis, one for the y-axis—and a tool that can map them. That is basically the entire requirement. I use Python with matplotlib for pretty much everything involving scatter plots. It is free, it runs on any machine, and the syntax is short enough that you can build a working chart in under a minute if your data is already in a clean format. If your data lives in a CSV file, you load it with pandas, pass the two columns into plt.scatter(), and call plt.show(). Three lines. Here is what that looks like in practice: X-values: [2, 4, 6, 8, 10]
Y-values: [3, 7, 5, 9, 11]
In code, that becomes something like: x = [2, 4, 6, 8, 10]
y = [3, 7, 5, 9, 11]
import matplotlib.pyplot as plt
plt.scatter(x, y)
plt.xlabel('X axis')
plt.ylabel('Y axis')
plt.title('Basic scatter plot')
plt.show() The result is a set of five dots on a coordinate plane. Nothing fancy. The axes auto-scale to fit your data unless you tell it not to. If you want fixed axis ranges, add plt.xlim() and plt.ylim() before you call show().
How To Plot A Scatter Plot in Python With Real Data
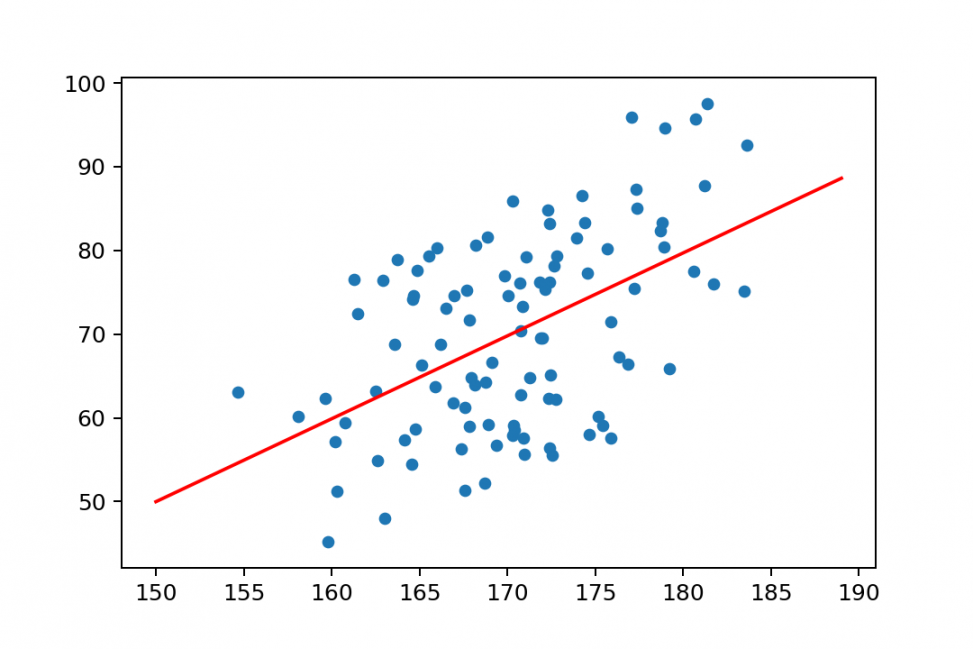
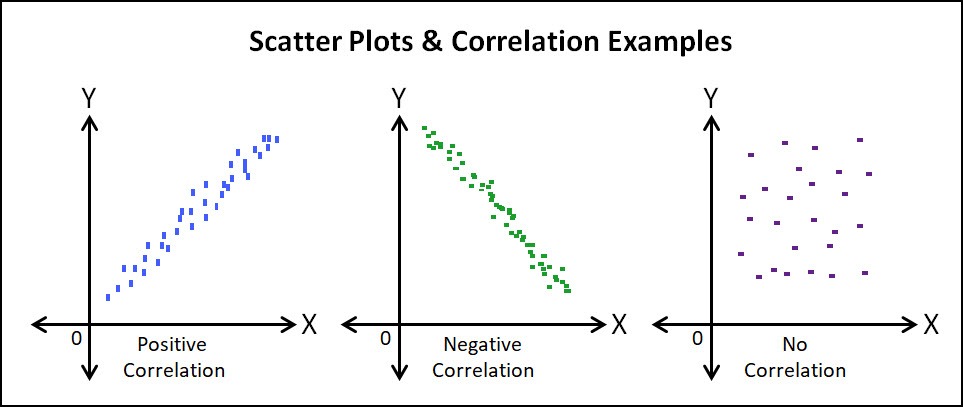
A scatter plot is just a visualization that shows the relationship between two numerical variables. Each point represents one observation, plotted at the intersection of its x and y values. That is the definition. The useful part is figuring out whether those points reveal a correlation, a cluster, or absolutely nothing at all. When I actually have a large dataset—the kind with thousands or tens of thousands of rows—the default plt.scatter() starts to choke. Rendering that many individual point objects slows the display down to a crawl, and overlapping points create messy visual artifacts where you can no longer tell if a dense region has 100 points or 10,000. The workaround I use is switching to plt.plot() with a small marker style like '.' or '+', which renders significantly faster because it uses a different backend path. For datasets over roughly 10,000 points, I also add alpha=0.5 to make the points semi-transparent so density becomes visible without overwhelming the canvas. Another thing most beginners miss is that scatter plots do not handle categorical data well without extra work. If one of your axes represents categories like product types or regions, the numerical mapping will look wrong unless you convert those categories to numeric codes first or use a library like seaborn that has built-in support for that. Seaborn's stripplot() and swarmplot() are built on top of the same machinery and handle the label-to-position conversion automatically. If you are doing this kind of work regularly, just skip matplotlib for the initial exploratory plots and go straight to seaborn. It saves time even though it adds another dependency.
Get the Full Details
Color and size encoding is where these charts actually become useful beyond a basic relationship check. You can map a third variable to point color using the c parameter and a fourth to point size using the s parameter. A common pattern is to plot temperature against humidity with point color representing pressure. This turns a simple bivariate plot into a rough multivariate display. The tradeoff is that it gets hard to read if you have more than three or four variables involved. At that point, a scatter plot matrix or a dimensionality reduction technique like PCA is a better choice. I once worked on a project where we were plotting sensor readings from industrial equipment, and the x-axis values had a tiny range—something like 42.301 to 42.317—while the y-axis ranged from 0 to 1000. The default axis scaling made the x-axis variations completely invisible. All the points collapsed into a vertical line and the pattern we were looking for was hidden. The fix was straightforward: I set the x-axis limits manually with a small margin around the data range and switched the x-axis to a logarithmic scale using plt.xscale('log'). That spread the points out enough to see the actual distribution. This is a problem that does not get mentioned often enough in basic tutorials. Here is the download link for matplotlib if you need to install it: https://matplotlib.org/stable/install/index.html. The pip command is simply pip install matplotlib. For seaborn, it is pip install seaborn. Both work on Python 3.8 and above.
Common Pitfalls That Waste Afternoon Time
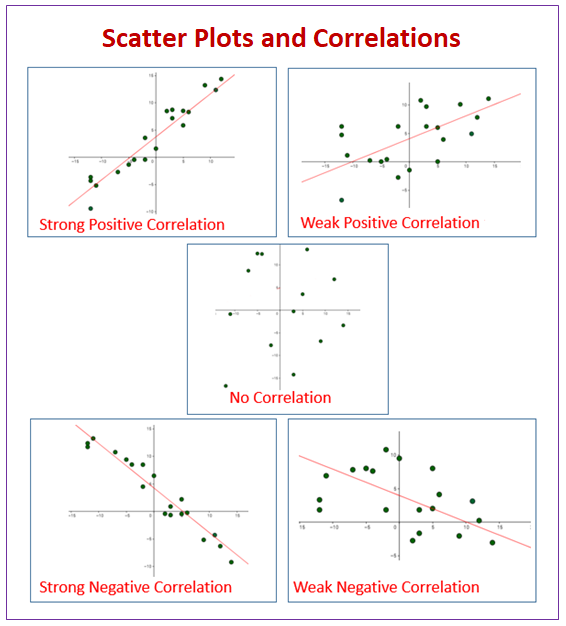
The biggest issue I see people run into is treating the scatter plot as a proof of causation. It is not. Two variables can have a strong visual correlation on a scatter plot and still be completely unrelated in any causal sense. I have seen this mess up presentations more than once. Always check the correlation coefficient and consider a confounding variable before drawing conclusions. Another issue is outlier handling. A single extreme value can stretch an axis so far that the rest of your data clusters into an unreadable pile. I usually run a quick check by plotting the data with and without points beyond the 1st and 99th percentiles. If the pattern changes dramatically, you have outliers dominating the visualization and you need to decide whether to clip them, transform the axis, or use a robust scaling method. For very large datasets, even the alpha and marker-size tricks only go so far. In those cases, I switch to a hexbin plot or a 2D kernel density estimate. Matplotlib has plt.hexbin() built in, and seaborn offers kdeplot() with fill=True. These methods aggregate points into bins or density regions instead of drawing each one individually, which solves both the performance problem and the overplotting problem at the same time.
When a Scatter Plot Is the Wrong Tool
Scatter plots require both axes to be numerical. If either axis is purely categorical with no inherent order, a bar chart or a box plot is usually the right call. There is also the question of time series data. If your x-axis is time and you have many observations per time unit, a scatter plot becomes a vertical forest of points that tells you nothing useful. In that scenario, a line chart or an aggregated time-series plot is more appropriate. I learned this the hard way when I tried to plot hourly stock prices as individual scatter points across a full trading year. The resulting chart was just a solid gray bar with no interpretable detail. The bottom line is that scatter plots are good for quick exploratory analysis on moderate-sized numerical datasets. They are not a general-purpose visualization solution. Know their limits and you will save yourself a lot of frustration.