Understanding Kubernetes Architecture Without the Fluff
The thing most people miss when they first look at a Kubernetes Architecture Diagram Explained is that the diagram itself is almost useless unless you understand what actually happens when things break. I spent about three years fighting production clusters before I realized that staring at Control Plane diagrams doesn't teach you how to keep a cluster alive during a node failure. Here's what the architecture actually looks like in practice, not how the marketing pages describe it.
Kubernetes Architecture Diagram Explained
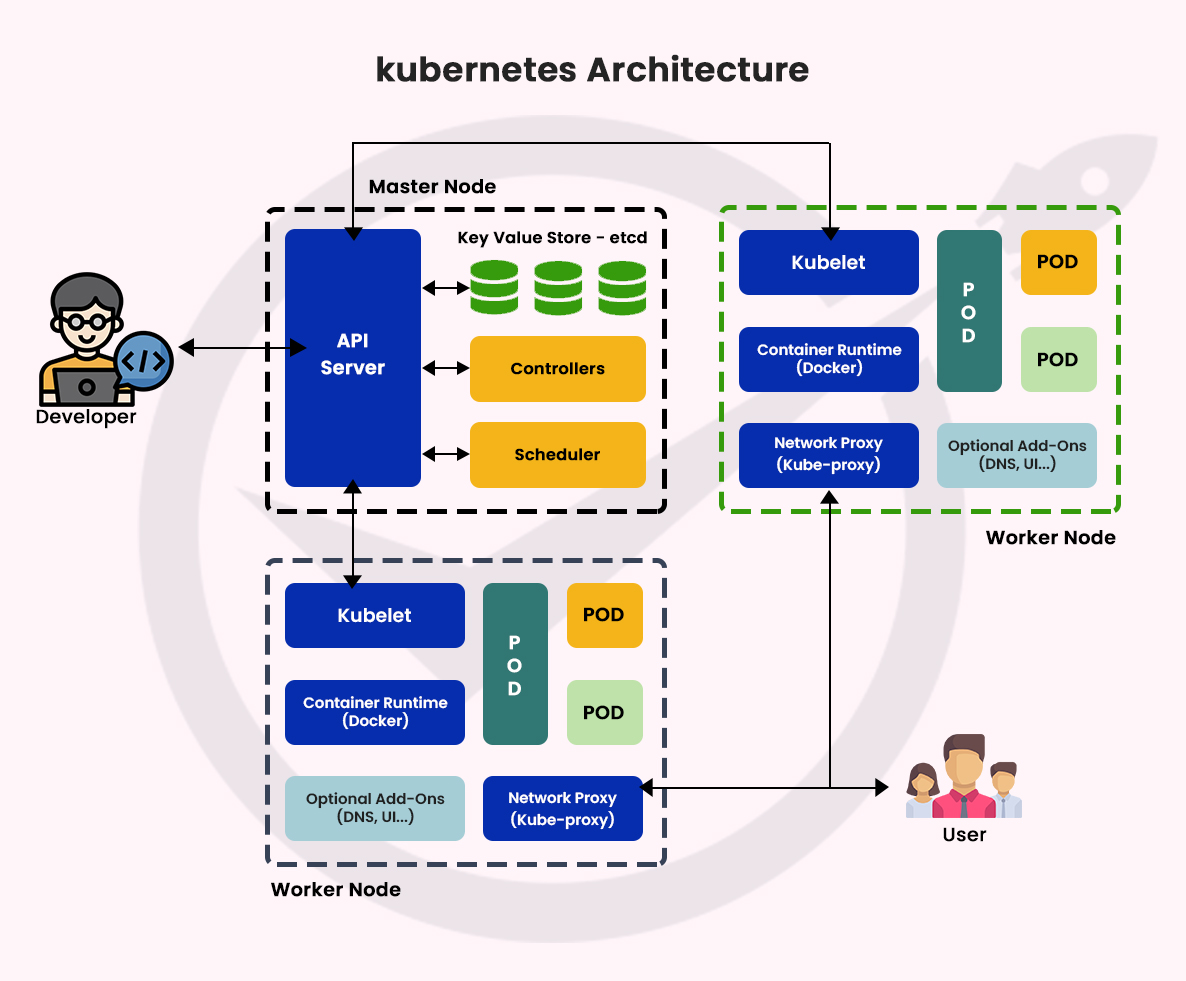
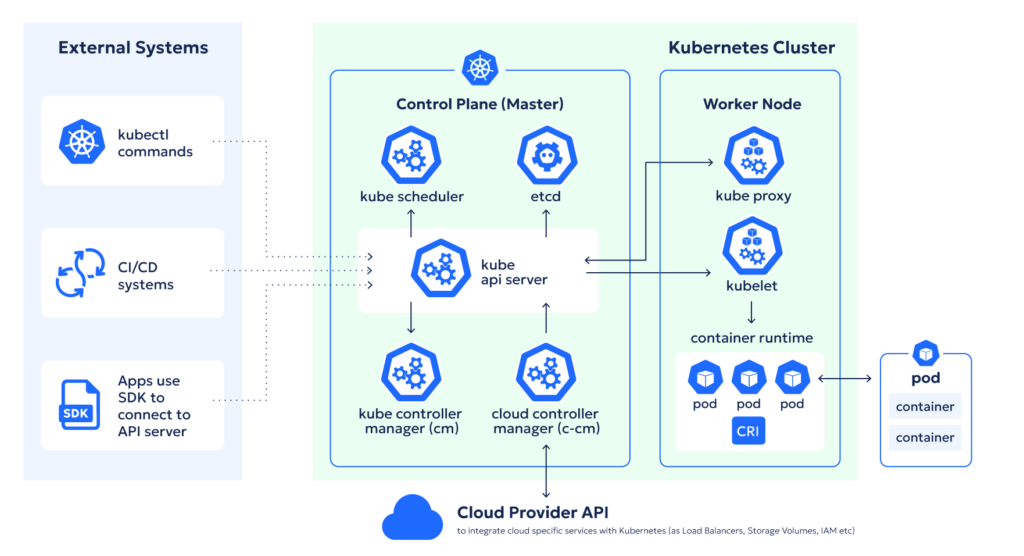
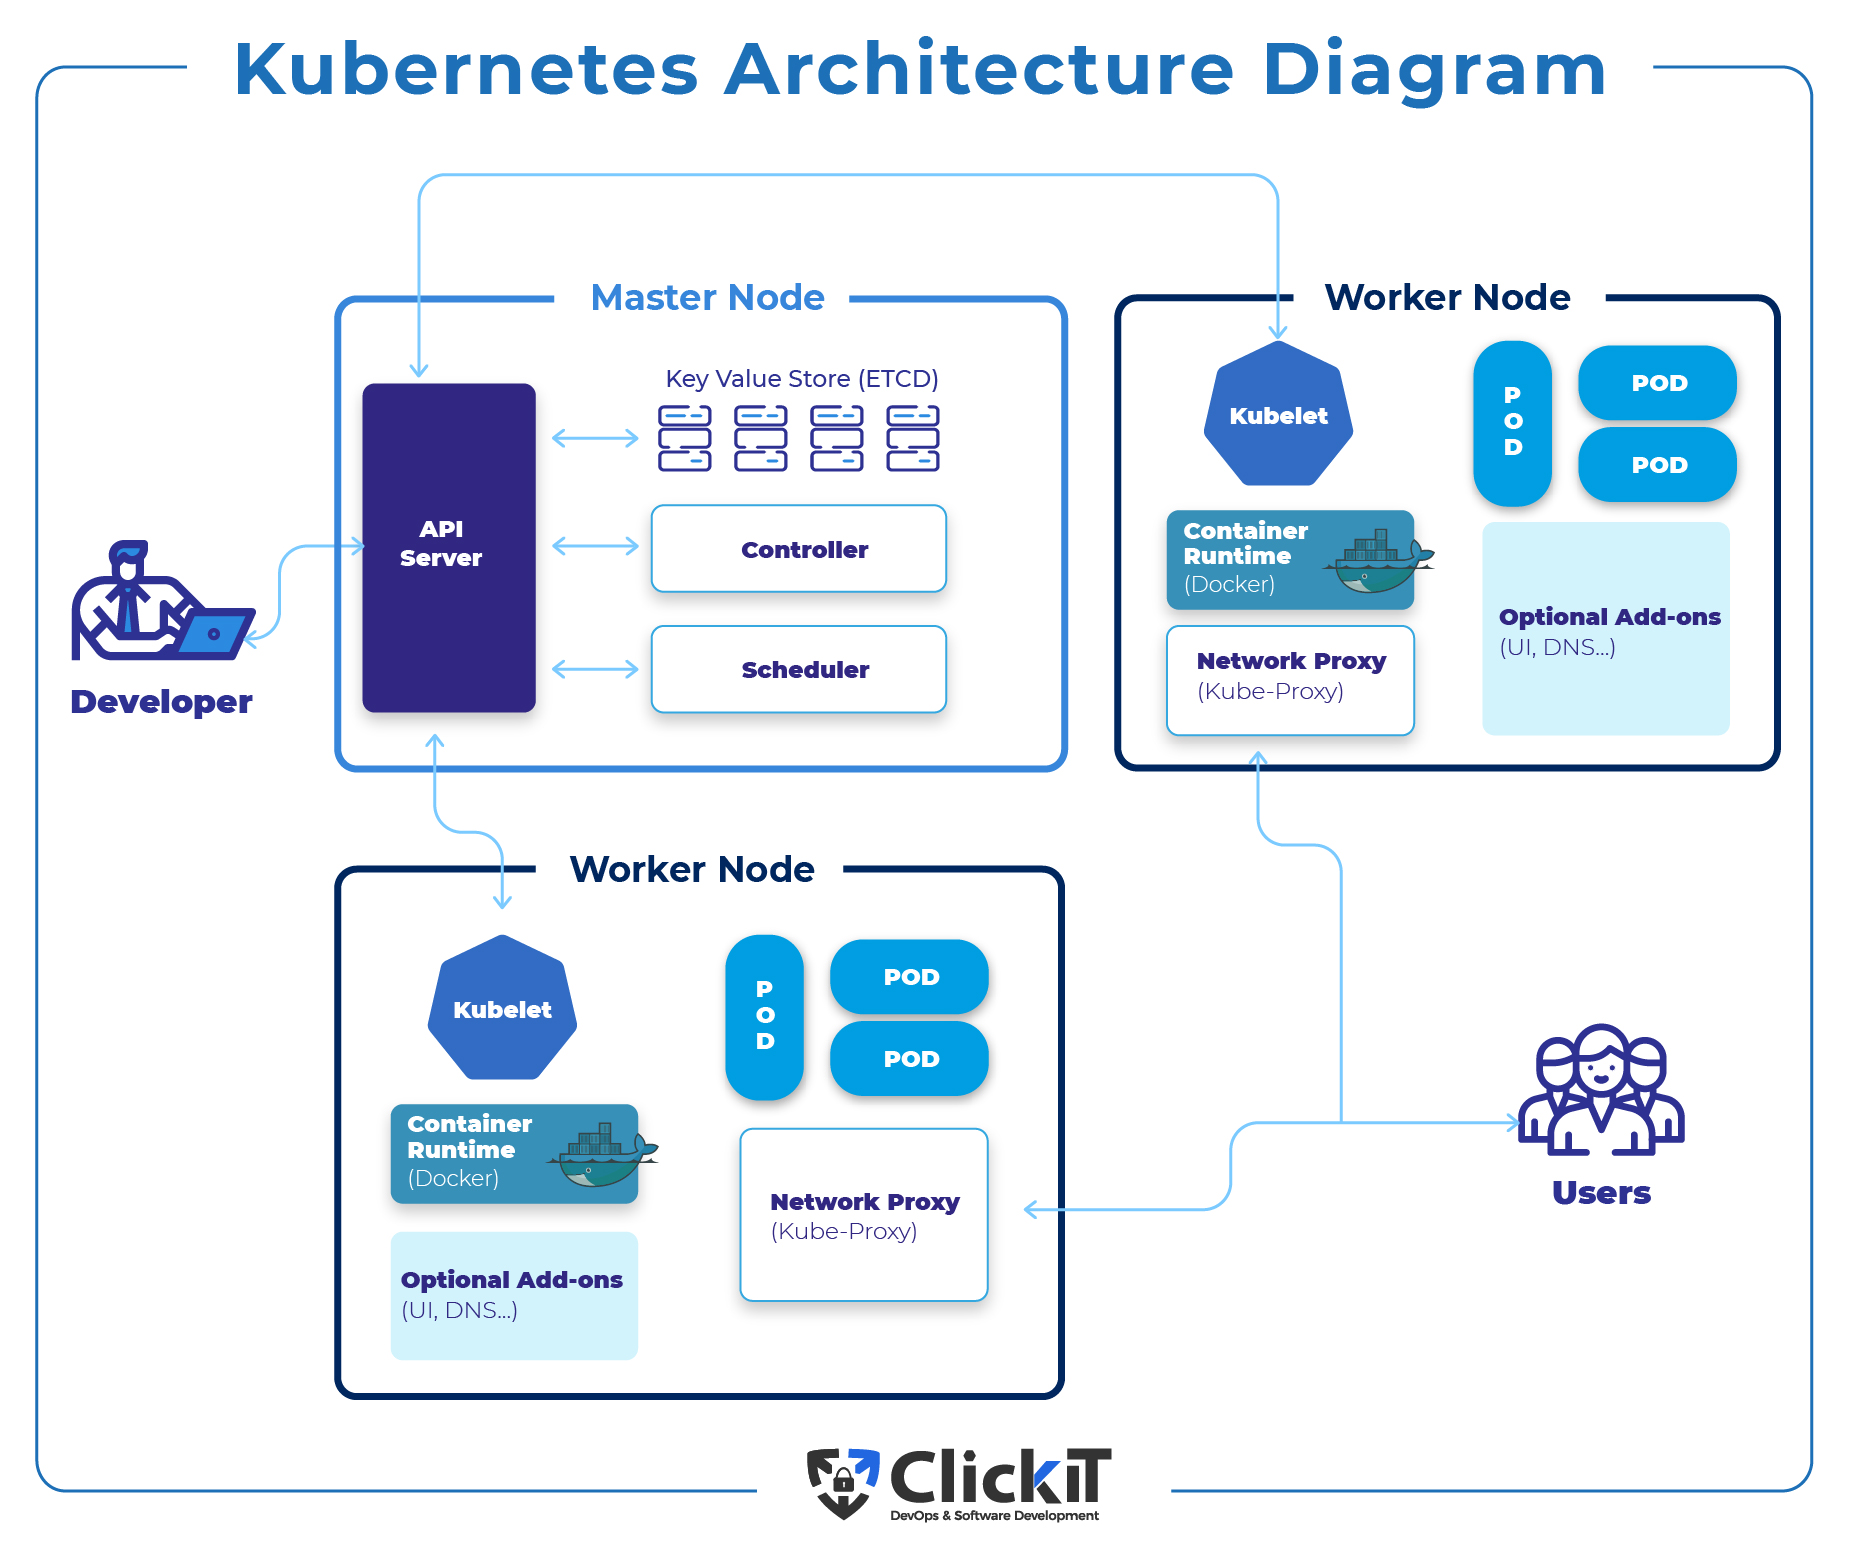
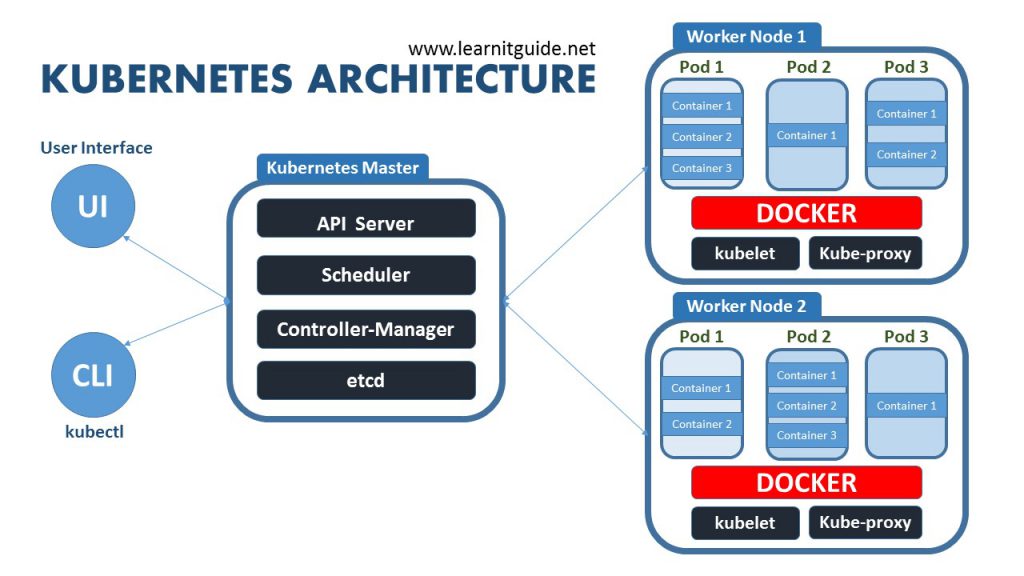
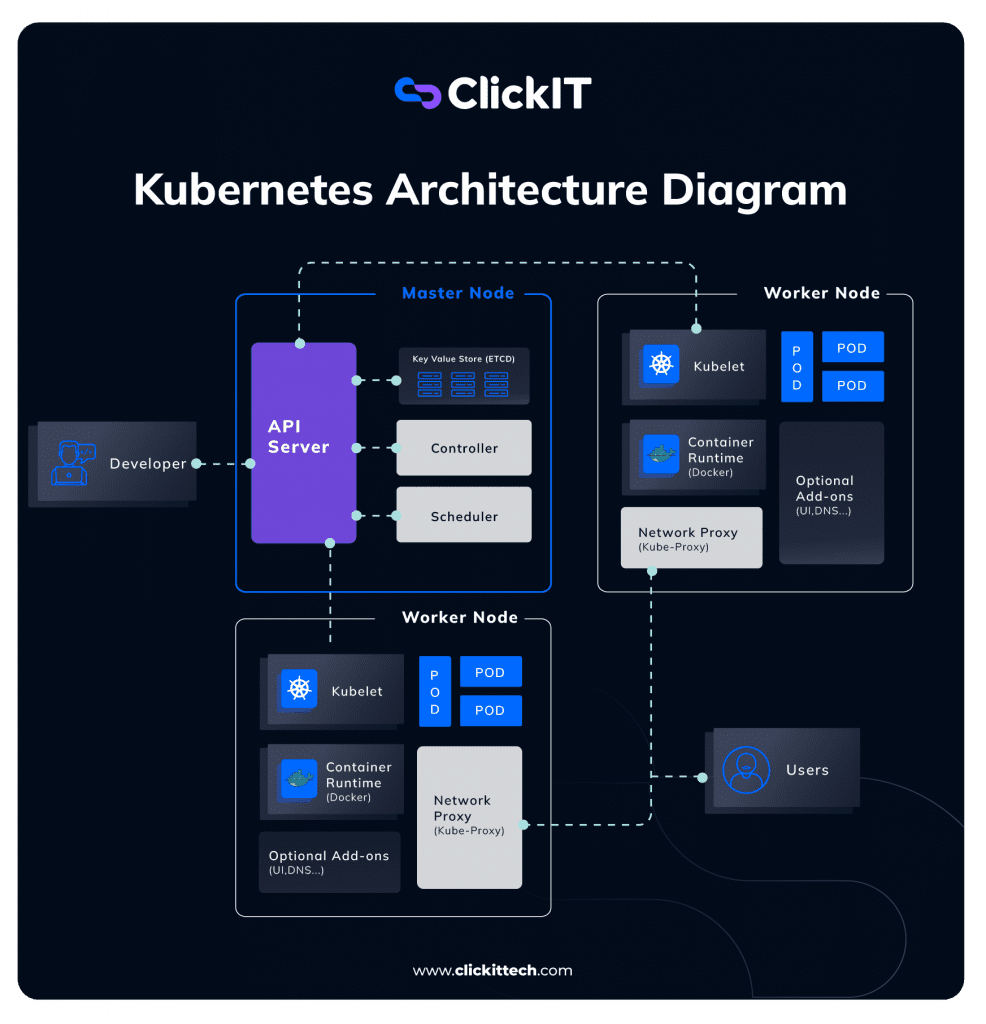
At the highest level, Kubernetes splits into two parts: the Control Plane and the Worker Nodes. That's it. Everything else is implementation detail. The Control Plane runs on a subset of your nodes or a dedicated set of machines, and it maintains the desired state of the cluster. The Worker Nodes are where your containers actually execute. They report back to the Control Plane constantly. The main components you need to know inside the Control Plane are the API Server, the etcd datastore, the Scheduler, and the Controller Manager. The API Server is the front door. Every command you run with kubectl goes through it. It validates requests and updates the state in etcd. If the API Server goes down, your cluster is effectively dead. Users can't interact with it, and the internal components lose their coordination point. etcd is a distributed key-value store. It holds all the cluster state: deployments, pods, services, configmaps, secrets, everything. It uses the Raft consensus algorithm to stay consistent across multiple nodes. I once watched a production cluster lose quorum because someone resized the etcd disk too aggressively after a backup rotation script ate all the old snapshots. We lost about 47 minutes of write availability while we rebuilt the cluster from the last good backup. etcd should never share resources with anything else. Keep it on its own disks. That's the first rule I learned the hard way.
The Scheduler watches for new pods that don't have a node assigned and places them. It considers resource requests, affinity rules, taints, and topology. It doesn't track what happens to the pod after scheduling. Once a pod lands on a node, the Scheduler forgets about it. The Controller Manager runs the replication controllers that make sure the number of running pods matches what you asked for. If a pod dies, the Controller Manager tells the Scheduler to create a replacement. This is a loop, and it runs continuously. On the Worker Node side, you have the kubelet, the container runtime, and the kube-proxy. The kubelet is the agent that runs on every node. It makes sure the containers described in the pod specs are actually running. It reads the API Server's state and acts on it. If the kubelet stops, that node becomes a ghost. The Control Plane thinks pods might still be running on it, but nothing is actually happening there. I've seen this when disk pressure triggered a kubelet eviction storm and it took down the agent itself. The container runtime does the actual work of creating and managing containers. In Kubernetes terms, this is usually containerd or CRI-O now, not Docker directly. The API Server talks to the kubelet using the CRI interface, and the kubelet delegates to the runtime. It's an abstraction layer that lets you swap runtimes without rewriting everything. In practice, switching between containerd and CRI-O after deployment is possible but painful. Don't do it unless you have to.
Get the Full Details
kube-proxy handles networking. It sets up rules so that Services work. When you define a Service with a virtual IP, kube-proxy on each node makes sure traffic to that IP gets routed to the correct backing pods. There are different modes: iptables, ipvs, and eBPF. iptables is the default and it works. ipvs is faster for large clusters but needs manual kernel module loading. eBPF is the new hotness with Cilium and it's genuinely better, but it requires newer kernels and careful tuning. I switched a 200-node cluster from iptables to ipvs and cut service discovery latency from about 800 milliseconds to roughly 50 milliseconds under heavy load. That matters when you're doing rolling updates across hundreds of services simultaneously. Network policies are another piece that doesn't show up clearly in most diagrams. They control traffic flow between pods. By default, everything can talk to everything. You need to explicitly create NetworkPolicy objects to restrict communication. I once had a dev team accidentally expose an internal Redis instance to the entire internet because no network policy existed. They'd deployed a database pod on the same cluster as their public web app and assumed isolation by namespace. It doesn't work that way. Namespaces are logical boundaries, not security boundaries. Storage is equally misunderstood. PersistentVolume and PersistentVolumeClaim decouple storage provisioning from pod lifecycle. PVs are cluster-wide resources. PVCs are user requests for storage. The actual storage backend can be NFS, iSCSI, cloud provider volumes, or something like Rook-Ceph. When you request a PVC, the StorageClass determines whether dynamic provisioning happens or if you need to manually create the PV. Dynamic provisioning is convenient until you need specific storage characteristics that the default StorageClass doesn't support. Then you're stuck debugging why your claim is stuck in Pending state.
The Scheduler doesn't pick nodes randomly. It goes through a predicate phase filtering out ineligible nodes, then a priority phase scoring the remaining ones. Taints and tolerations let you repel pods from certain nodes. Node affinity lets you attract pods to specific nodes. I spent a full day troubleshooting a cluster where pods wouldn't schedule on any node because someone added a taint to a node group and forgot about it. The error message was cryptic enough that I didn't immediately connect it to the taint. kubectl describe pod shows the event log. Read it. It tells you exactly why scheduling failed. There's also the concept of add-ons that live in the kube-system namespace. These aren't part of the core architecture but are essential for operation. CoreDNS handles service discovery. The metrics server provides resource usage data for autoscaling. Container network interfaces like Calico or Flannel handle pod-to-pod networking. Each of these is a separate deployment that runs as regular pods. They're critical infrastructure wearing the disguise of regular workloads. One thing that trips people up is that the Control Plane components aren't magically resilient just because the architecture diagram makes them look like they are. You need to run multiple replicas of the API Server, multiple etcd nodes, and spread them across failure domains. A single-node etcd cluster will lose data on reboot. Two API Server replicas with no load balancer in front will have downtime during rolling updates. The diagram doesn't show you how to deploy this stuff reliably. You have to learn that from experience.
Another nuance that beginners miss: the difference between declarative and imperative approaches matters more than people realize. Kubernetes is fundamentally declarative. You describe what you want, and the system works to achieve it. Imperative commands like kubectl run exist but they're for quick testing. In production, you use manifests or Helm charts or Kustomize. The reconciliation loop is what makes Kubernetes work. The Controllers constantly compare desired state against actual state and take corrective action. This is why you can delete a pod and it comes right back. The Controller detected the deviation and fixed it. The downside of this design is that debugging state drift becomes a game of whack-a-mole. A pod might crash for reasons unrelated to your application code, get replaced, crash again, and you end up chasing your tail. I had a cluster where pods were being OOM-killed because the cgroup memory limit was being enforced differently than expected. The Container Runtime was capping memory at the container level, but the Kubernetes resource limits were set higher. The pod kept restarting in a loop that lasted six hours before I realized the mismatch. kubectl describe pod showed the restart count climbing. I should have looked at the events tab first instead of assuming it was an application issue. If you want to build your own Kubernetes cluster from scratch, you have several options. kubeadm is the official tool and it gives you the most control over what gets installed and where. kind and minikube are for local development. For production, most teams use managed services like EKS, GKE, or AKS because they handle the Control Plane management for you. The tradeoff is that you lose direct access to the Control Plane components and you pay a premium for the convenience. But honestly, managing etcd backups and API Server HA yourself isn't worth it unless you have a specific reason to.
Here's a practical approach to actually learning this architecture: deploy a cluster locally with kubeadm on three VMs. Break it. Delete etcd data. Stop the API Server. Watch what happens. Then fix it. This takes about four hours and teaches you more than any diagram ever will. I've recommended this to junior engineers before, and the ones who actually do it become competent much faster than the ones who just read documentation. The Kubernetes Architecture Diagram Explained on paper makes the system look simple and elegant. In reality, it's a complex distributed system with many moving parts that fail in unpredictable ways. Understanding the architecture means understanding what each component does and how failures propagate through the system. When something breaks, you need to know which component to check first. That comes from experience, not from looking at a picture.