How to Actually Calculate These Four Things
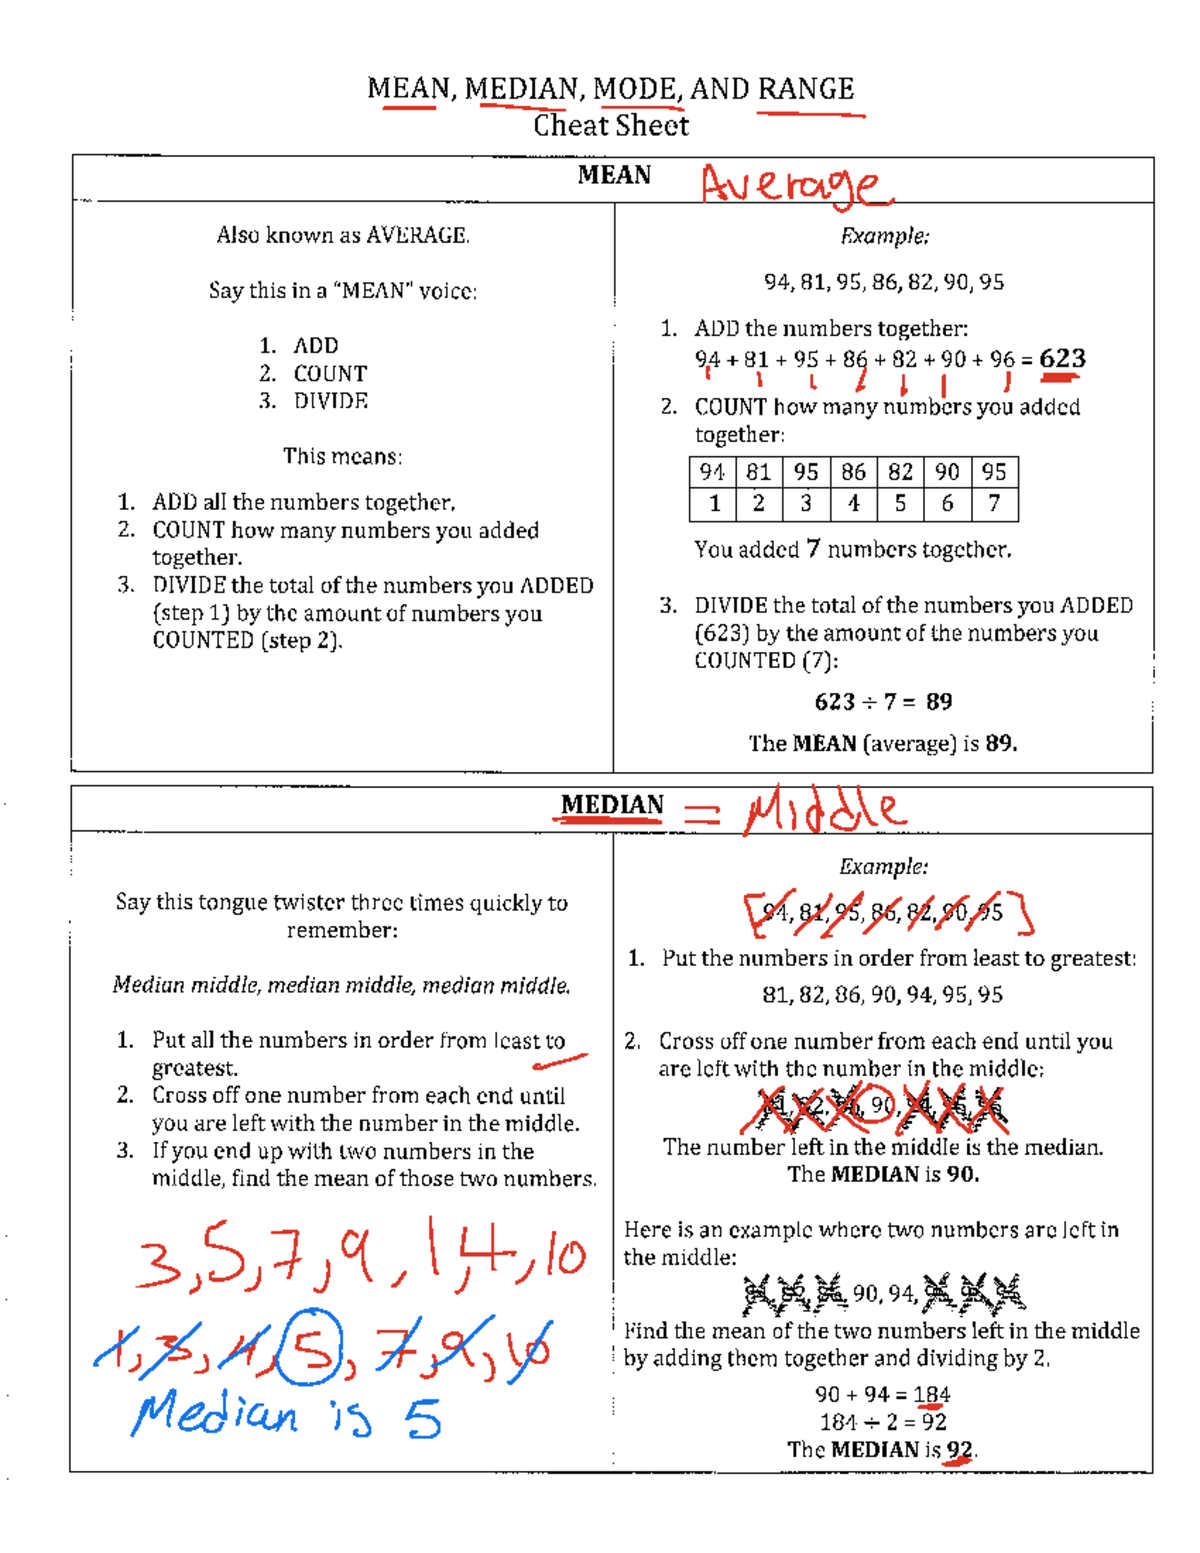
I've been going through spreadsheets and raw data for a long time now, and I see the same mistakes over and over. People mix up mean and median, they ignore what range is actually telling them, and they don't bother learning mode except when a teacher forces them to. Here's how each one works in practice. Mean is the sum divided by the count. That part is straightforward. The problem comes when you have outliers. I had a client once pulling salary data from a company where three executives made over $500k and everyone else was in the $40-60k range. The mean came out to about $89,000, which made it sound like the average worker was doing fine. It wasn't. The median was $52,000. That's the number that actually represents the person in the middle. Always check both. If they're far apart, your data has skew and mean alone is misleading. Median is the middle value when your data is sorted. Odd number of entries? Take the center one. Even number? Average the two center values. Nothing complicated there. What trips people up is forgetting to sort first. I've seen spreadsheets where someone just grabbed the middle cell without sorting, thinking they were calculating median. They weren't. Also, if you're working with grouped data or a frequency table instead of raw numbers, the median gets more involved—you find the cumulative frequency, locate the middle position, and interpolate. Most cheat sheets skip that entirely.
Mode is simply the most frequently occurring value. A dataset can have one mode, multiple modes, or none at all if every value appears once. In a manufacturing setting I worked in, we tracked defect types across production runs. The mode told us immediately which defect was dominant without any calculation. That was way faster than computing means or medians for that particular question. Bimodal distributions—where there are two clear peaks—are worth paying attention to because they usually mean you're looking at two different groups. I saw a dataset of test scores that looked uniform until I plotted it. Turns out there were two separate classes with very different difficulty levels, and the combined mode was meaningless. Range is the difference between the highest and lowest values. It's the simplest measure of spread and also the least informative. A single outlier can blow up your range while everything else stays tightly clustered. In quality control, I've used range as a quick gut check—something is off if the spread looks unreasonable—but I never rely on it for any serious analysis. Standard deviation exists for a reason. Range is useful when you need a fast, rough sense of dispersion, or when working with small datasets where more complex calculations aren't justified. The real value of a Mean Median Mode Range Cheat Sheet isn't the definitions. Anyone can look those up. The value is knowing which one to use when and what each one fails to capture. Mean is sensitive to outliers. Median ignores the shape of the distribution. Mode can be meaningless in continuous data. Range depends entirely on two values and tells you nothing about everything in between. No single statistic answers every question, and pretending otherwise is what leads to bad decisions.
If you're building a reference document, I'd structure it around use cases rather than definitions. Start with "use this when your data has outliers" and point to median. Then "use this when you need a quick measure of spread" and point to range with a warning about its weakness. Most online cheat sheets organize by term, which isn't wrong, but it doesn't help you decide anything when you're actually staring at a messy dataset at 11pm.
Get the Full Details