Monthly Data Science For Beginners: A Practical Guide
I've seen people try to learn data science by dumping themselves into a new topic every month. It's not ideal, but it's how most working professionals actually end up learning it. You don't need a degree. You need a consistent schedule and a few tools that don't fight you. The approach is straightforward. Every month you pick one area of data science and push through it until you can do something real with it. Not watch a video. Not read an article. Actually do the work.Monthly Data Science For Beginners: What It Actually Looks Like
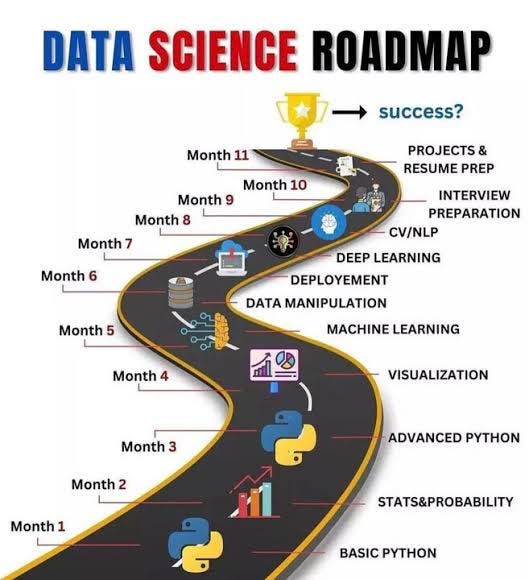
Most beginners treat data science like a subject to consume. It's a craft. You learn by breaking things. Here's the monthly structure I've used with dozens of people who actually got to a point where they could handle a dataset without panicking. Month 1 is Python basics. Not all of Python. Just enough to load a CSV, clean it, and plot something. That's it. Pandas, Matplotlib, NumPy. You spend the rest of the month making ugly graphs until the process stops feeling like a chore. Month 2 is statistics. Descriptive stats first. Mean, median, standard deviation, distributions. Then hypothesis testing. This is where most people quit because the math feels abstract. The workaround is to skip the proofs. Run the tests in code. See the p-values change when you tweak your data. That's when it clicks.
Month 3 gets into machine learning. Start with linear regression. Build a model that predicts something. Then logistic regression. Don't touch neural networks yet. You'll break your brain over something you can't interpret. Scikit-learn is your friend here. It's ugly but it works. Month 4 is feature engineering. This is the part nobody talks about enough. How do you turn raw data into something a model can use? Encoding categorical variables, handling missing values, scaling features. I once spent three weeks debugging a model that was failing silently because I hadn't realized my pipeline was leaking normalization constants from the test set into training. StandardScaler needs to fit on training data only. I learned that the hard way. Month 5 covers evaluation metrics. Accuracy is useless most of the time. You need precision, recall, F1 score, ROC AUC. Understanding why your model looks good on paper but fails in production comes down to knowing which metric actually matters for your specific problem.
Month 6 is deployment. Yeah, deployment. You build a model. Then what? Flask, FastAPI, or Docker. Get it to serve predictions over HTTP. It doesn't need to be elegant. It just needs to work. I had a model that ran fine locally but timed out in production because I forgot to batch predictions. One request at a time through a bottleneck I'd built myself. Switched to vectorized inference and response time dropped from 8 seconds to 40 milliseconds.
Get the Full Details

Tools You Actually Need
VS Code or PyCharm. Jupyter is fine for exploration but don't get stuck there. Git for version control. Kaggle or UCI Repository for datasets. Hugging Face for pre-trained models when you're ready to go beyond scikit-learn. Don't download random ML libraries because they sound impressive. Every extra package adds friction. Start minimal. Add tools only when you hit a wall that requires them.
Common Pitfalls
Overfitting is the obvious one. Everyone learns about it before they see it. The counter-intuitive part is that a simple model on messy data usually beats a complex model on cleaned data. Garbage in, garbage out, but at least garbage is consistent. Data leakage is the silent killer. It happens when information from the test set accidentally influences your training process. Column selection based on the full dataset before splitting. Scaling before train-test split. Any preprocessing step that touches validation data is leakage. I caught mine by comparing training and validation scores. When validation outperformed training, I knew something was wrong. In that case, the model wasn't generalizing. It was memorizing the test set. Split the data first. Then preprocess. Always. Another issue is tutorial hell. You follow along with someone else's project and feel productive. You're not. The difference between following a tutorial and doing the work is the friction you introduce by removing help. Close the video. Try to rebuild it from memory. Stuck? Search. Struggling more? Read the documentation. That's the actual learning.
Where to Get Practice Data
Kaggle.com has structured datasets with community notebooks. UCI Machine Learning Repository is older but cleaner. Real-world data is messier than anything you'll find online. If you want the real experience, scrape something yourself. Or ask a friend if they have boring data at their job. Spreadsheets everyone ignores are goldmines for practice. For the Monthly Data Science For Beginners program, the goal isn't mastery. It's muscle memory. By month six you should be able to take a dirty dataset, build a baseline model, evaluate it properly, and put it somewhere it can be used. That's the floor, not the ceiling. If you fall behind, don't restart. Just adjust the pace. Six months is the target, but four months with real work beats six months of passive consumption. The skill isn't in knowing the tools. It's in knowing when they fail and what to do next.