Getting Your Hands Dirty with MO Calculations
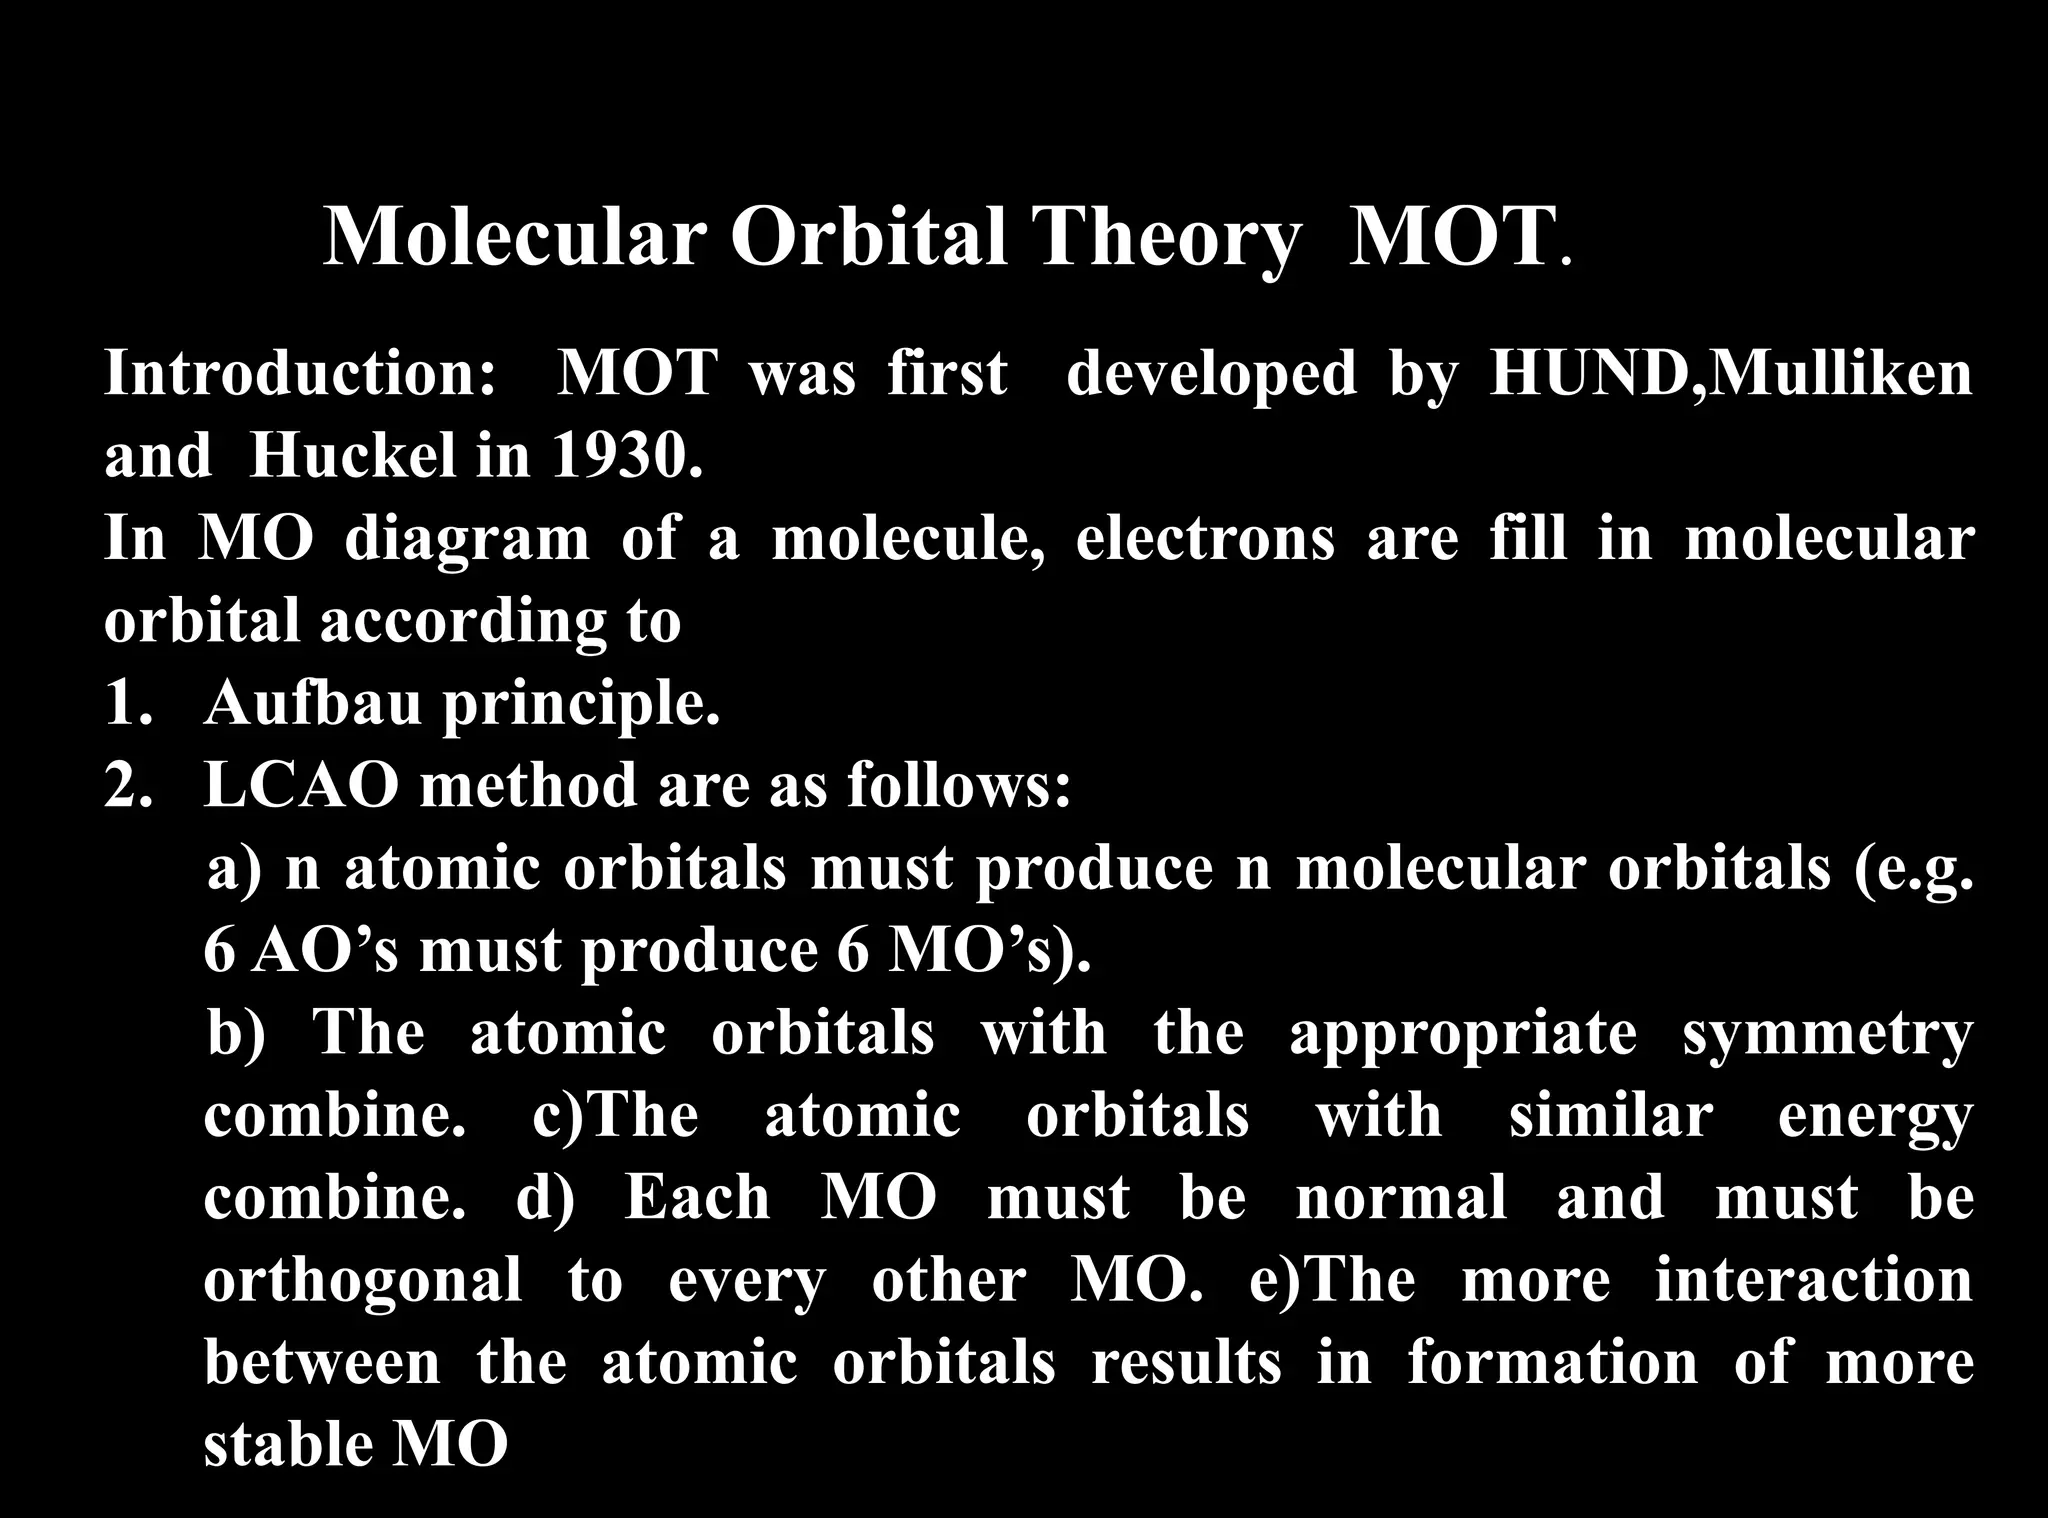
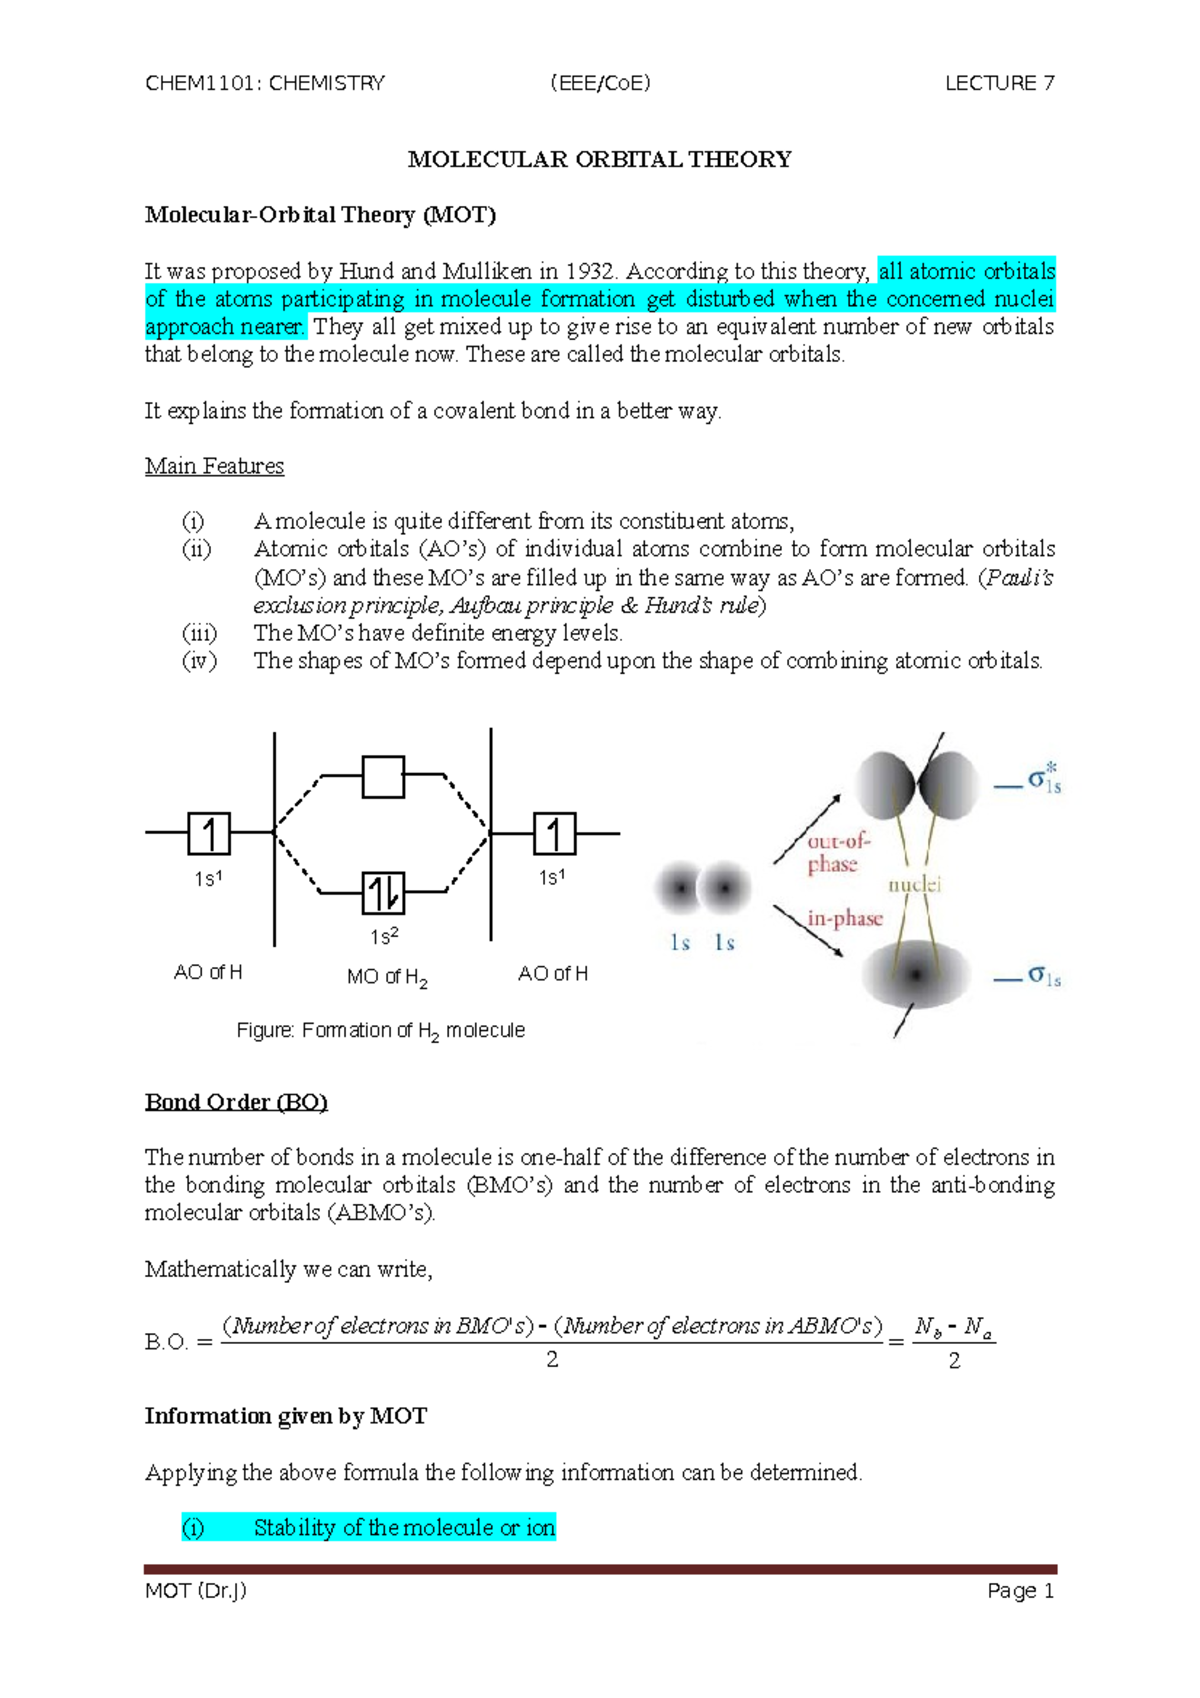
Most people come to molecular orbital theory from the textbook side, which means they already have a romanticized version of what it does before they ever open a computational chemistry package. I spent about eight years trying to make quantum chemistry actually work for organic synthesis problems, and the gap between the cartoon diagrams and what Gaussian or ORCA actually spits out is enormous. Here is how I learned to stop fighting the software and start using it. It is not a prediction engine. It is a way of getting approximate wavefunctions for molecules so you can derive properties from them. The core idea is that electrons in a molecule occupy orbitals that extend over the whole system, not localized bonds between two atoms. Linear combinations of atomic orbitals form molecular orbitals, each with a specific energy, and you fill them according to Aufbau, Pauli, and Hund's rules just like you did for atoms. The part nobody tells you early enough is that the quality of every single number you pull out depends almost entirely on your basis set and your exchange-correlation functional. Pick the wrong combination and your HOMO-LUMO gap will be garbage, your barrier heights will be systematically wrong, and you will have no idea why because the math looks clean on paper. I once ran a B3LYP/6-31G* calculation on a palladium-catalyzed cross-coupling intermediate and got a perfectly reasonable-looking geometry. The next day I switched to a triple-zeta basis set with diffuse functions and the whole electronic structure collapsed into a different spin state. That cost me three weeks of bench work to explain away.
Setting Up a Calculation Without Wasting Your Time
Start by deciding what you actually need to know. This is where most people fail. If you just want to know whether a reaction is thermodynamically favorable, you do not need a high-level coupled-cluster calculation on a molecule with forty heavy atoms. You need a reasonable DFT functional, an appropriate basis set, and a solvation model if your reaction happens in solution. For routine organic molecules in the range of twenty to forty non-hydrogen atoms, wB97X-D with the 6-311+G(d,p) basis set gives you sensible geometries, decent barrier heights, and reasonable thermochemistry without turning your computer into a space heater. For transition metals, you should switch to a functional that handles dispersion and self-interaction errors better, like M06-2X or B3LYP-D3, paired with a def2-SVP or def2-TZVP basis set. The def2 family is cleaner than old-style Pople sets because it was parameterized specifically for DFT. Build your initial geometry from something reliable. Constrained optimizations from a rough structure are acceptable, but if you start from a completely wrong connectivity you will waste time converging to a local minimum that looks plausible. I use Molden or Avogadro to lay out the skeleton, then run a quick semi-empirical pre-optimization with xTB before committing to a full DFT job. That pre-optimization step usually takes under two minutes and saves you from watching a geometry convergence fail after six hours.
Reading the Output Like a Human Instead of a Robot
The output file from a quantum chemistry program is intentionally hostile to beginners. Do not try to read it linearly. Jump to the thermodynamic summary, then to the frontier orbital energies, then to the orbital occupations. If your alpha and beta electron counts are unequal and you did not request a restricted open-shell calculation, your system might have converged to the wrong spin state without any warning in the final lines. Check the SCF convergence history. If the energy is oscillating or drifting toward the end of the cycle, the calculation did not actually converge even if the program prints a success message. I learned this the hard way with a nitroxide radical where the final RMS density was borderline and the orbital energies looked fine. The geometry was slightly wrong because the wavefunction was never properly optimized. Using the SCF=XQC option or switching to a damping protocol usually fixes this without requiring a complete rewrite of the input. When you look at the molecular orbitals, remember that the pictures are representations of a mathematical object, not little electron clouds moving around like planets. An orbital is a one-electron function. The square of its amplitude gives you a probability density, but interpreting every bump and node as a physical feature is a common beginner trap. Frontier orbitals are useful for predicting reactivity patterns, but they are only useful when your calculation is internally consistent. A mismatched basis set or a poorly converged SCF will produce frontier orbitals that look chemically sensible while being numerically wrong.
Get the Full Details

Common Pitfalls That Will Cost You Weeks
The first major pitfall is assuming that DFT is a universal method. It is not. DFT works well for many organic and organometallic systems, but it struggles with systems dominated by strong static correlation, charge-transfer excitations, and certain transition metal complexes with near-degenerate d-orbitals. If you are studying a system where multiple electronic configurations contribute significantly to the ground state, single-reference DFT will give you answers that look precise but are misleading. In those cases you need multireference methods like CASSCF, and those are much more expensive and harder to set up. The second pitfall is ignoring entropy and solvation. A gas-phase DFT calculation will give you a Gibbs free energy that is useless for comparing solution-phase reactions. Add a implicit solvation model like SMD or CPCM, and include thermal corrections from the vibrational frequency analysis. Frequencies also tell you whether your optimized structure is a true minimum or a transition state. If you have one imaginary frequency, you are at a saddle point. If you have more than one, you probably optimized to the wrong stationary point and need to restart with different initial conditions. I encountered a specific problem with a macrocyclic ligand system where the calculated dipole moment varied by a factor of three depending on the initial guess orbitals. The molecule had several near-degenerate occupied orbitals, and the SCF kept landing in different local minima. The workaround was to use the guess=mix option to force a broken-symmetry initial guess, then verify that the final spin contamination was acceptably low by checking the S^2 expectation value. If <S^2> is significantly higher than the theoretical value for your intended spin state, your wavefunction is contaminated and your energies are unreliable.
When to Stop and Use Something Else
There are legitimate scenarios where Mot Molecular Orbital Theory in its standard DFT form is the wrong tool. If you need benchmark-quality reaction energies for a small organic molecule, coupled-cluster methods like CCSD(T) with a large basis set are the gold standard and they are feasible for systems up to roughly fifteen heavy atoms. Beyond that, the computational cost scales as the seventh power of system size and the calculations become impractical on ordinary hardware. If you are studying excited states, standard ground-state DFT orbitals do not directly give you excitation energies. You need time-dependent DFT or a wavefunction-based method like EOM-CCSD. TD-DFT is cheaper and works reasonably well for many vertical excitations, but it has known failures for Rydberg states, charge-transfer states, and systems with significant double-excitation character. There is no single correct answer here. You pick the method that matches your system and your accuracy requirements, validate it against experimental data or a higher-level calculation when possible, and accept that every method has blind spots. The practical reality is that most people doing MO theory in a research setting spend more time troubleshooting convergence issues and validating their methods than they do running production calculations. Learning to read an output file quickly, knowing which functional-basis set pair to reach for by default, and recognizing when a result is suspicious are the skills that actually matter. The theory itself is straightforward. The execution is where everything falls apart.