Getting Your Head Around Parallel Text Review
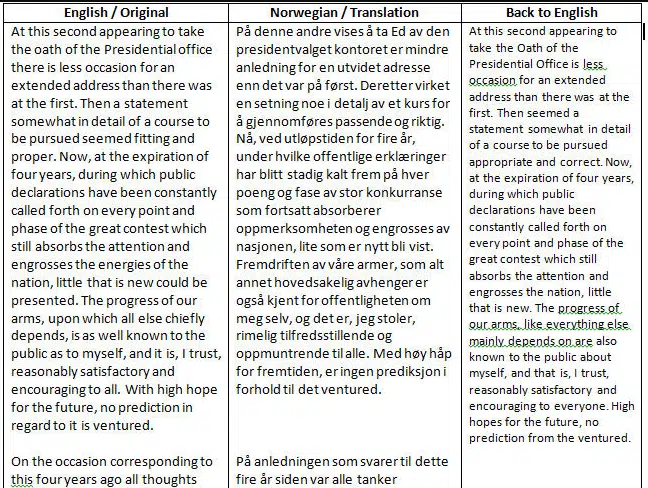
Side by side translation means placing the original text in one column and the translated text in another so you can review them simultaneously. It is the standard workflow in CAT tools, MT post-editing environments, and document comparison workflows. You do not flip back and forth between tabs or windows. You keep both texts visible and flag mismatches as you scroll. Most people assume this is only for final QA. That is wrong. It is actually most useful during the active translation process because it catches gaps in real time instead of making you go back and hunt for them later. I have seen teams cut their revision rounds down from three to one after switching to a true side by side workflow, mostly because omissions stopped being a surprise problem.
Side By Side Translation in Practice
Here is how it works in a typical CAT tool setup. You open an SDLXLIFF or XLIFF file in MemoQ or Trados Studio, turn on the editor pane, and the interface splits the source and target segments. You translate the target segment, save, and move to the next one. The previous source and target remain visible just above or below. You are building a sentence-level alignment as you go. If you are doing MT post-editing, the setup is similar but the source column shows the machine-translated text instead of the original. You are editing that raw output against the source. The side by side view lets you compare meaning without constantly tab-switching. This alone usually cuts PE time by about 20 to 30 percent compared to reading the MT output in isolation. I ran into a real problem last year with a Turkish to English corpus that had heavy code-mixing and embedded German product codes. The tool split segments at the wrong places because the alignment engine treated certain German noun phrases as separate segments due to spacing anomalies. I ended up with fragmented source text that made no sense when displayed alongside its translation. My workaround was to export the alignment as a TMX, open it in a plain text editor, and manually correct the segment boundaries before reimporting. It took about twenty minutes and fixed the entire alignment issue. No amount of UI tweaking would have resolved that because the root cause was the encoding on certain segment breaks, not the tool itself.
Tooling and File Formats
Trados Studio handles side by side natively through its bilingual editor. MemoQ does too and adds a useful comparison feature where you can load two versions of the same file and diff them. Across the pond, Smartcat and Phrase offer web-based alternatives that work reasonably well if you do not want to install desktop software. For quick ad hoc review without any paid tool, two Chrome windows side by side with Dev Tools splitting the viewport does the job, though it is slower than a dedicated CAT environment. The file formats that matter here are XLIFF 1.2 and 2.0, SDLXLIFF, and TMX for translation memory exchange. If your source files are locked in proprietary formats like InDesign IDML or certain SAP export formats, you will often need a pre-processor step to convert them into a segmentable format first. Do not skip that step. Going straight into translation mode on an unprocessed file usually produces misaligned segments and wasted time.
Get the Full Details

What Beginners Get Wrong
The biggest mistake I see is treating the side by side view as a passive reading aid. It is not. You need to actively cross-reference. Read the source segment, then read the target segment, then go back and verify specific elements like numbers, dates, and proper nouns. A single missed decimal place in a financial document will not be obvious unless you deliberately check those fields. Another common error is assuming segment count matches always mean full coverage. They do not. Missing segments, unresolved placeholders, and ignored non-translatable units all hide inside a supposedly complete pass. I once reviewed a batch where the source had 1,247 segments and the target showed 1,247 as well. It looked fine until I ran a filter for untranslated status and found 83 segments were marked complete but actually contained placeholder tags instead of translated text. The count matched because the tool counted segments, not semantic coverage. A counter-intuitive point that most guides skip: side by side translation works poorly for languages with very different structural ordering, such as Japanese into English or Arabic into German, when the source uses long compound sentences. The segment-by-segment view forces you to hold an entire Japanese sentence in working memory while you read its English translation. You lose context faster than you might expect. In those cases, a paragraph-level view or a full-document overview alongside the segment editor performs noticeably better than strict sentence-by-sentence alignment.
Limitations You Should Know About
Side by side translation is not a magic bullet. It does not help with terminology consistency across segments. It does not fix bad source text. It will not catch tone mismatches unless you are already trained to spot them. If your source files contain heavy formatting, tables, or mixed-direction text, the alignment breaks down frequently and requires manual correction afterward. The workflow also assumes a decent baseline of segmentation quality. Poor segmentation means you spend more time fixing breaks than translating. If your project involves legal contracts or medical devices where terminology precision is non-negotiable, side by side is still the best available method, but you should pair it with a terminology management system like TBX or a custom glossary import. Without that, you are guessing on term consistency and the side by side view alone will not save you. For ultra-high volume repeative content where the same segments appear thousands of times across different projects, side by side is fine for the initial pass but becomes inefficient. Translation memories with 100 and 101 percent matches should drive that work, not manual segment review. The tooling supports this, but you have to configure it correctly first. Otherwise you are essentially doing redundant work.