
What a Kindergarten Summative Assessment Actually Looks Like
Most people think summative assessment means a formal test with a grade at the end. In kindergarten, that approach falls apart fast. Kids that age can't sit still for twenty minutes, they don't reliably understand written instructions, and their developmental window is somewhere between twelve and forty minutes depending on the task and the child. A summative assessment in kindergarten is really just a snapshot taken at the end of a unit or term. It tells you whether a student has reached the expected benchmark. That's it. Nothing dramatic about it. The difference between formative and summative at this level is mostly about timing and consequence. Formative assessments happen during instruction and the data stays with the teacher for immediate adjustments. Summative assessments happen after a chunk of learning is complete, and the results often feed into report cards, portfolio reviews, or placement decisions. The actual tools can look similar. A reading fluency probe used formatively becomes summative if you're logging it for a final grade. The distinction lives in the purpose, not the procedure.
Practical Summative Assessment Examples For Kindergarten
Here are the assessments I actually use, the ones that produce usable data without losing my mind in the process. The first one is a phonemic awareness screening. I take kids individually and ask them to identify beginning sounds, count syllables in words, and blend phonemes together. Something like saying "c-a-t" and having the child say the word back. I score each item correct or incorrect. A typical benchmark for end-of-year kindergarten is around 18 out of 20 items correct on the full set. This usually takes me about eight minutes per student. Next is a writing sample collection. At the end of a unit on narrative writing, I give the class a single prompt: "Write about something that happened to you." They have fifteen minutes. I collect every piece. What I'm scoring is not neatness. I'm looking for emergent phonics application, spacing, letter formation consistency, and whether they can sustain a simple sequential idea across multiple invented or standard words. I use a rubric I built myself with four levels: emerging, developing, meeting, and exceeding. A child who writes "I go park play" with recognizable letter-sound relationships is meeting the standard. A child who writes random letter strings is not. I spend about five minutes scoring each sample using a color-coded highlighter system that makes trend spotting faster. The third example is a math fact fluency assessment. I use a timed sheet with twenty addition problems, all within ten. The child works for two minutes. I record how many they get correct. The benchmark I track against is 15 correct within two minutes by end of kindergarten. This is controversial in some circles because timed fluency carries equity concerns, but it remains the most common benchmark across state standards. If a child scores below 8, I flag them for intervention regardless of their classroom performance that term. There is a strong correlation between early fact fluency and later mathematical reasoning.
A fourth example is an oral reading fluency passage. I have a calibrated kindergarten text at approximately 90 to 110 correct words per minute at year's end. I read along with the child, mark errors, and calculate words correct per minute. Self-corrections count as correct. This takes roughly four minutes per student if I'm efficient. The data point matters more than the exact number. A child reading 65 wcpm at end of year kindergarten is a red flag even if their phonics scores look decent.
Get the Full Details

How to Set Up the Assessment Window
The biggest problem with kindergarten summative assessments is not the tool. It's the logistics. A room full of six-year-olds trying to take an assessment simultaneously produces noise, distraction, and unreliable data. The workaround I use is staggered scheduling. I pull students out in groups of four or five, rotating through four stations over two days. Station one is me administering the reading probe. Station two is a peer buddy doing a shape sort with manipulatives. Station three is a tablet-based phonics game that auto-scores. Station four is quiet independent work like coloring or reading a book. This keeps the rest of the class occupied while I collect clean data from small groups. The whole process takes about ninety minutes spread across two mornings instead of dragging out over a full week of disrupted instruction. I learned this the hard way during my first year. I tried doing a full-class summative assessment on fractions and shapes. Half the class needed constant redirection. The other half finished in three minutes and started disrupting everyone. I got maybe thirty percent usable data out of that session and spent the next two days re-teaching concepts that weren't actually misunderstood. The staggered station model cut my data collection time from roughly four hours to under two hours and produced significantly cleaner results. I also started using a quick pre-screen where I identified students who consistently struggled during formative work and scheduled them for reassessment first. This prevented the scenario where I ran out of time before reaching the kids who needed it most.
Scoring and Reporting Without Losing Your Mind
Data entry is where most kindergarten assessment systems break down. I use a simple spreadsheet with tabs for each skill domain: phonemic awareness, alphabet knowledge, reading fluency, writing, and math fact fluency. Each row is a student. Each column is an assessment date and score. Conditional formatting highlights anything below benchmark in yellow and anything at or above in green. This takes about twenty minutes per term to update once all data is collected. The initial setup took me an afternoon, but it pays off every subsequent term. One counter-intuitive thing about scoring kindergarten writing samples is that over-reliance on rubric categories can obscure real ability. A child might score poorly on "mechanical accuracy" because their letter formation is inconsistent, but their idea generation and vocabulary usage might be strong. I learned this when a student consistently scored in the "emerging" band on writing rubrics but could regale me with elaborate story details during oral conferences. The rubric missed the child entirely. My workaround is to score writing in two separate passes. First pass is purely mechanical: letter formation, spacing, directionality. Second pass is purely conceptual: idea clarity, sequencing, vocabulary range. I then average the two scores. This catches kids who are conceptually advanced but mechanically developing, which is a fairly common profile at this age. Another pitfall that beginners miss is treating percentile or benchmark data as absolute truth for individual children. A kindergarten student's performance on any given day can vary by twenty percent based on sleep, hunger, anxiety, or simply whether the adult administering the assessment smiled at them enough times. I always note the conditions alongside the score. If a child scored below benchmark on a particularly chaotic morning, I schedule a re-administration within a week before locking the score into the official record. This happens more often than administrators would like, but it prevents legitimate students from being misplaced into intervention tracks based on bad data days.
What Summative Assessment Misses at This Age
I should be blunt about the limitations. Summative assessments in kindergarten measure a narrow slice of capability. They do not capture executive function, social-emotional regulation, creative problem-solving, or sustained attention. A child who scores below benchmark on phonemic awareness might have excellent auditory processing but a significant attention deficit that makes the testing format impossible for them. The assessment result is accurate for what it measures but meaningless for understanding the child. This is why summative data should always be triangulated with formative observations, portfolio work, and parent input before any instructional decisions are made. The other major blind spot is cultural and linguistic diversity. An oral reading fluency passage scored for words correct per minute tells you almost nothing about an English language learner who is still developing academic English. Their decoding might be phonetically accurate but their comprehension is blocked by vocabulary gaps unrelated to literacy skill. I use a separate comprehension-based speaking assessment for EL students that bypasses written text entirely. They retell a story I read aloud using pictures as prompts. The scoring focuses on narrative structure and recall, not vocabulary complexity. This produces more accurate placement data for multilingual learners than any standardized reading probe I have tried. If you are looking for a complete set of ready-to-use templates covering phonemic awareness screenings, writing rubrics, math fluency trackers, and reading passages with scoring guides, there is a downloadable resource pack available through the Sapiens Education Materials repository. The link is straightforward. Search for "Kindergarten Summative Assessment Packet" in the download section of the Sapiens AI education resources portal. The files are in PDF and Excel formats, compatible with most classroom printing and data management setups. The packet includes the exact scoring rubrics and benchmark thresholds I referenced in this article.
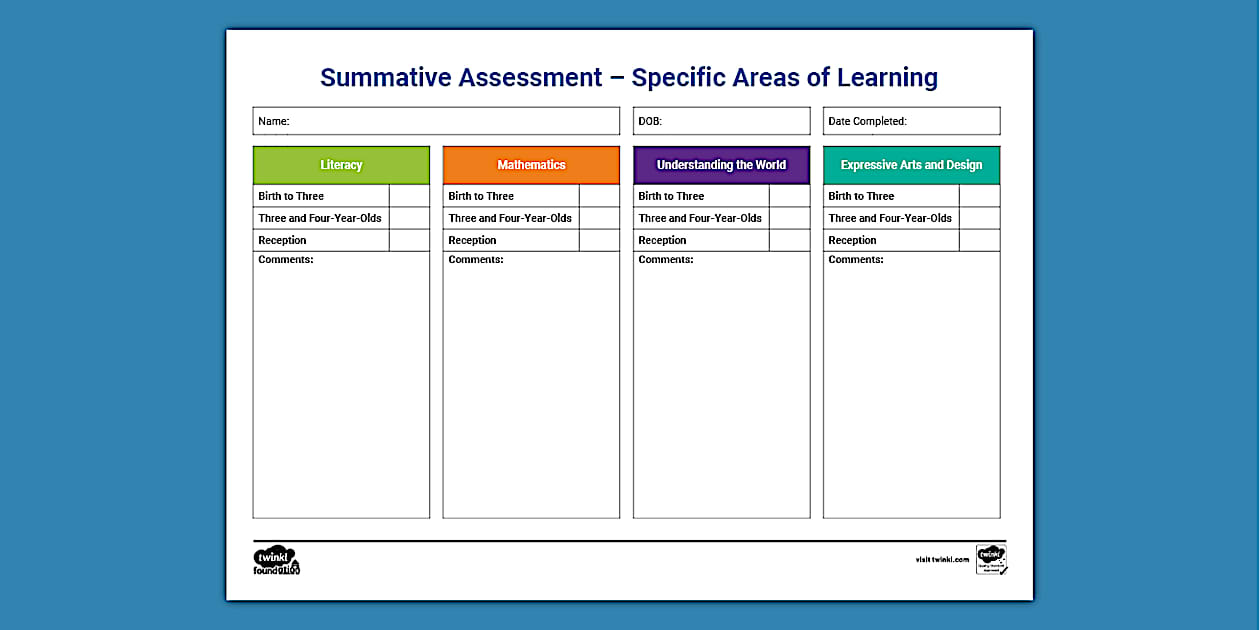
What to Do When Your School District Requires Standardized Summative Tests
Sometimes you do not get to choose your assessment tools. Some districts mandate standardized commercial inventories like DIBELS or DRA2. These tools are generally well-constructed and psychometrically sound. The problem is implementation fidelity. A DIBELS administration that takes twenty minutes per student because the tester reads instructions slowly or gets distracted is not the same as a clean twenty-minute administration. The resulting data is unreliable. I recommend that teachers who must use district-mandated tools keep a parallel informal summative log alongside the official scores. This gives you a backup data source in case the official administration was compromised by external factors. It also provides a more nuanced picture when parent conferences come around and the conversation shifts from "what did the test say?" to "what do you actually see this child doing in the classroom?" The trade-off is time. Maintaining a parallel log adds roughly forty-five minutes per term to your workload across a full classroom. That is not trivial. But the alternative is relying on a single data point from a single administration window, which is a fragile foundation for decisions that affect reading placement, intervention referrals, and parental communications. Forty-five minutes is a small price for that kind of insurance.


