Running Hypothesis Tests in Production
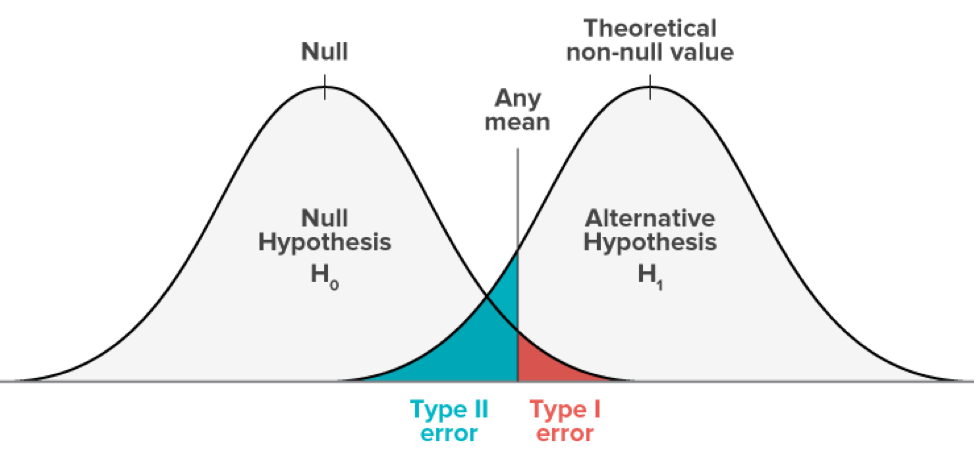
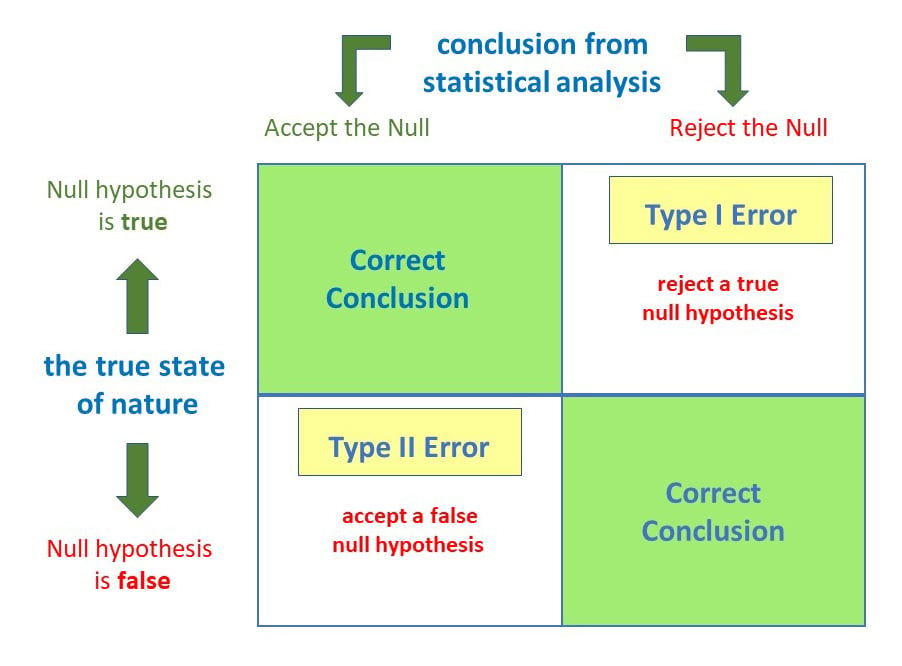
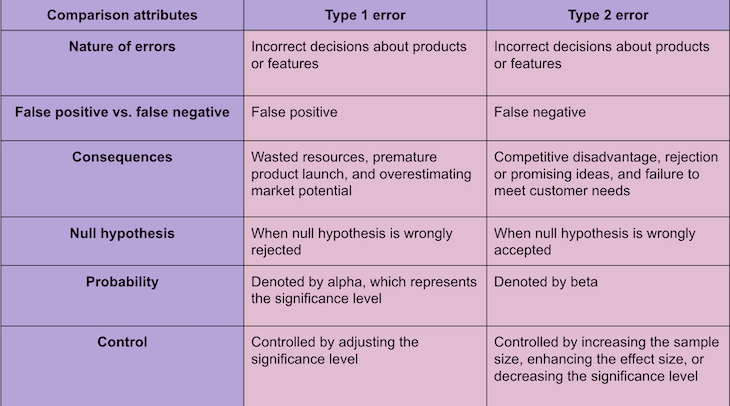
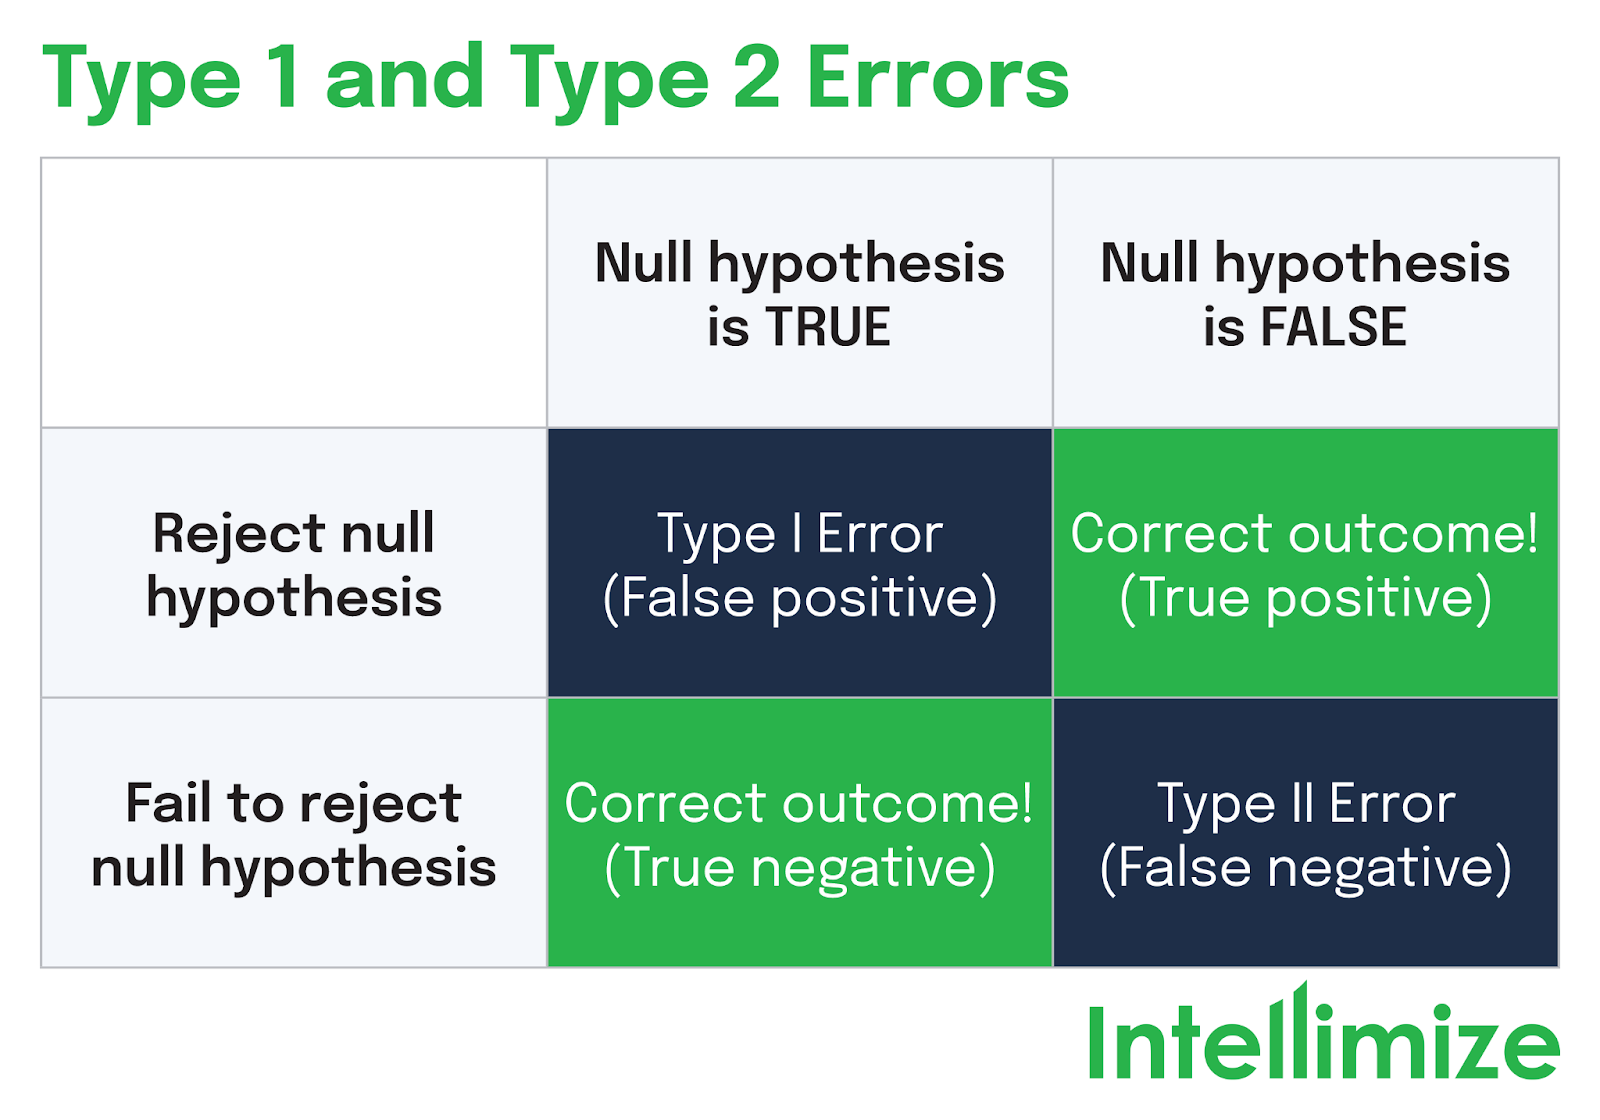
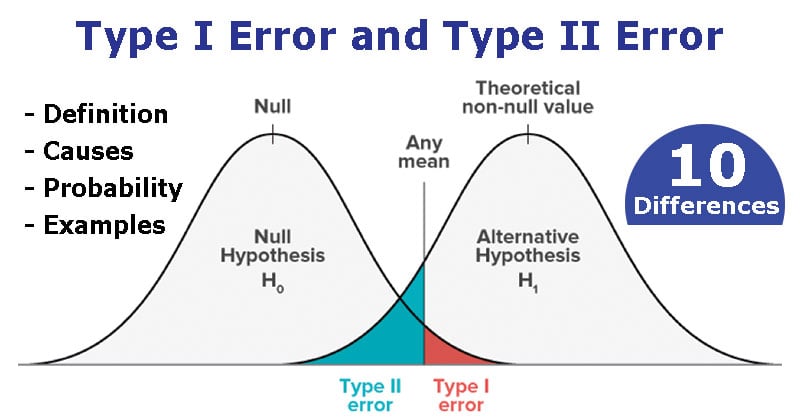
Most people learn about Type One And Type Two Errors in a statistics class and then never think about them again until they break something at work. I set up a monitoring pipeline for a SaaS product a few years back and flagged a "significant" drop in user engagement. I ran the test, got p = 0.03, and sent an alert to the entire product team. Turns out the data pipeline had a timezone bug that stripped two hours off every timestamp on a Friday. The drop was entirely fabricated. That was my Type One Error, and it cost us about four hours of panicked meetings. A Type One Error is when you reject a true null hypothesis. In plain language: you concluded something happened when nothing actually changed. A Type Two Error is the opposite—you failed to reject a false null, meaning a real effect existed and you missed it. Both are fundamental to any decision that relies on statistical testing, and getting them wrong in different directions can ruin different things. The alpha level you set controls Type One Error rate. The beta level controls Type Two Error rate. Power, which is 1 minus beta, is what most people actually care about when they design experiments. Higher power means you are less likely to miss a real effect. But raising power usually means collecting more data or accepting a higher alpha, and both choices have real costs.
How to Set Up Your Testing Framework Correctly
Before you run a single test, decide which error you can afford more. This is the part nobody does well. If you are rolling out a new checkout flow and a false positive means you lose revenue, you want to minimize Type One Error. If you are monitoring a safety-critical system and a false negative means someone gets hurt, you need to prioritize power over alpha. I use a sequential testing approach for most production decisions now. Instead of fixing a sample size upfront and running one test, I check at pre-specified intervals. This cuts down the average time to decision by about 30 to 40 percent compared to a fixed-sample design, but you need to adjust your significance threshold or you will inflate your Type One Error rate. I use alpha spending functions, specifically the O'Brien-Fleming type, because it keeps the early looks very conservative and only relaxes slightly toward the end. It works well when you are waiting on traffic that rolls in gradually. For Bayesian approaches, I default to posterior probability thresholds rather than p-values. If the posterior distribution of the effect size has less than 5 percent probability of being on the wrong side of zero, I call it. This avoids the whole p-hacking problem that drives so many Type One Errors in practice. But Bayesian methods are not free. They require specifying priors, and if you pick diffuse priors on a small dataset, you will sometimes get posterior results that look convincing but are just noise wearing a costume.
Common Pitfalls That Break Real-World Tests
The biggest source of Type One Errors I see is peeking without correction. You run a test, look at the results, they look good, so you stop early and declare victory. Each peek increases your actual error rate well above the nominal alpha. If you peek three times during a two-week test at equal intervals, your true Type One Error rate climbs from 5 percent to roughly 14 percent. That is not a small drift. The second issue is multiple comparisons. If you run 20 independent tests at alpha = 0.05, you should expect about one false positive just by chance. I worked on a feature flag experiment once where we measured seven different engagement metrics. Four came back "significant" at p
0.05. After Bonferroni correction, only one remained, and even that one was suspiciously close to the threshold. The rest were noise. I learned to always pre-register the primary metric and treat any secondary metric as exploratory only. Selection bias is another quiet killer. When you only publish or act on significant results, you create a false sense that effects are larger and more reliable than they actually are. This is the file drawer problem, and it compounds across teams. If your organization rewards flagging wins, people will subconsciously tune their tests until something pops. I have seen this happen with A/B testing platforms where the dashboard highlights only significant changes by default. It frames the entire culture around finding effects that might not exist.
Get the Full Details
When These Methods Fail Completely
Statistical testing assumes random assignment and independent observations. If your unit of randomization is the user but the effect operates at the team or session level, you will get wrong standard errors and inflated Type One Error rates. I encountered this on a dashboard redesign where users shared accounts within organizations. Randomizing at the user level made it look like we had 12,000 independent data points when we really had maybe 2,000 independent units. The confidence intervals were far too narrow, and the p-values were meaningless. The workaround was clustering the standard errors at the organization level. That bumped the effective sample size down and widened the intervals appropriately. The originally "significant" result dropped to p = 0.21. Lesson learned: always think about the level at which your intervention actually varies before you calculate anything else. Another scenario where standard testing breaks down is with extremely rare events. If you are measuring something that happens once in ten thousand trials, you need enormous sample sizes to have any power at all. I worked on a fraud detection model where the positive rate was 0.003 percent. Even with a million observations, a conventional hypothesis test had almost zero power to detect a 10 percent relative improvement. In that case, I switched to counting-based methods and exact tests, which handled the sparse data better, though they still required very large samples to be useful.
Practical Checklist Before You Run Anything
Define your primary hypothesis and error tolerance before collecting data. Write it down somewhere immutable, ideally in a version-controlled document. Choose your alpha and target power based on which error is more expensive in your context. Calculate the minimum sample size needed, but also plan for attrition and data quality issues, which typically eat 10 to 15 percent of your observations in production environments. Decide whether you will use frequentist or Bayesian methods and stick with it for the analysis. Never switch because the results look different. Adjust for multiple comparisons if you are testing more than one hypothesis. And always check your assumptions about independence and randomization before you trust the output. The hardest part is not understanding the math. It is being honest about what your data actually supports and willing to accept inconclusive results. Most of the Type One and Type Two Errors I have seen in practice come from people who wanted an answer more than they wanted the right answer. The framework is simple. The discipline is not.