Understanding R-Squared Without the Hype
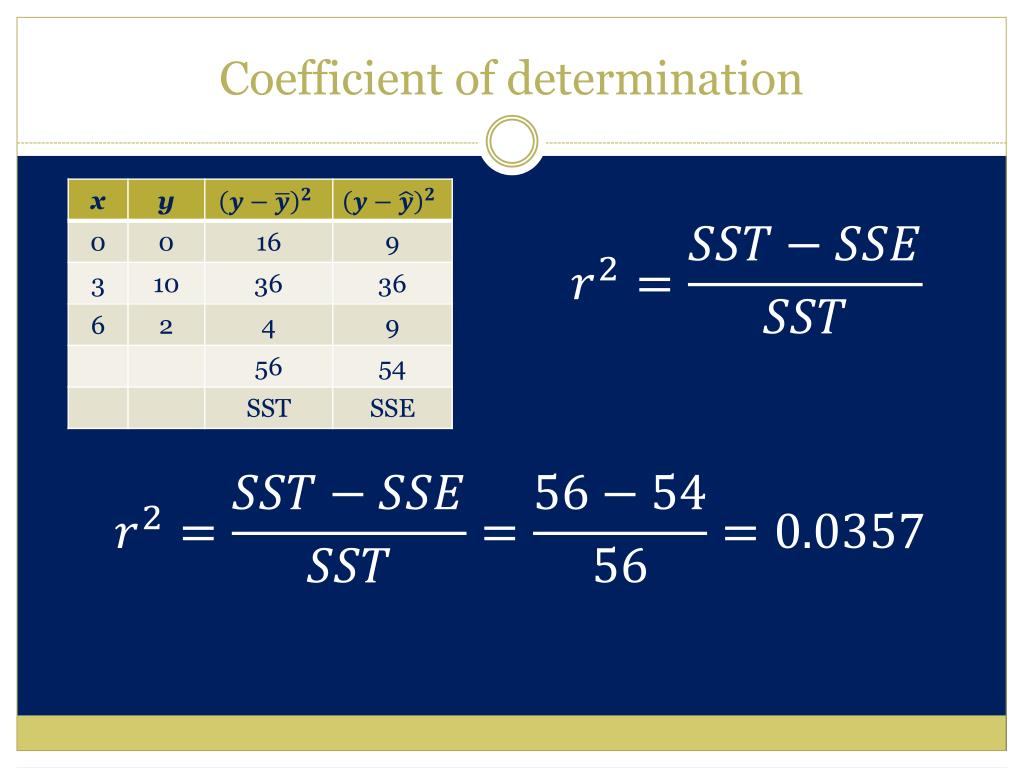
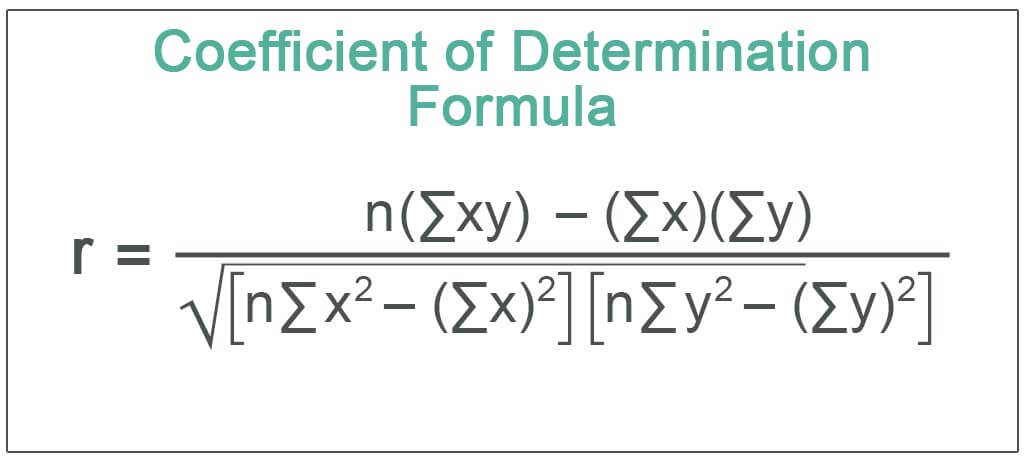
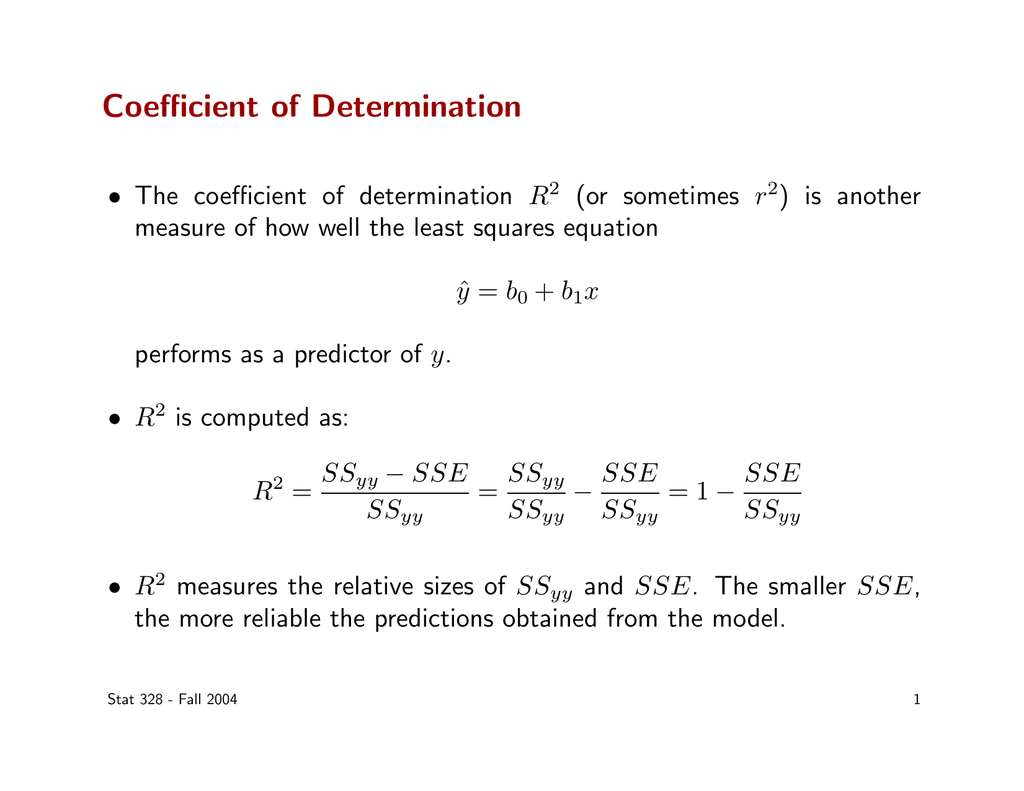
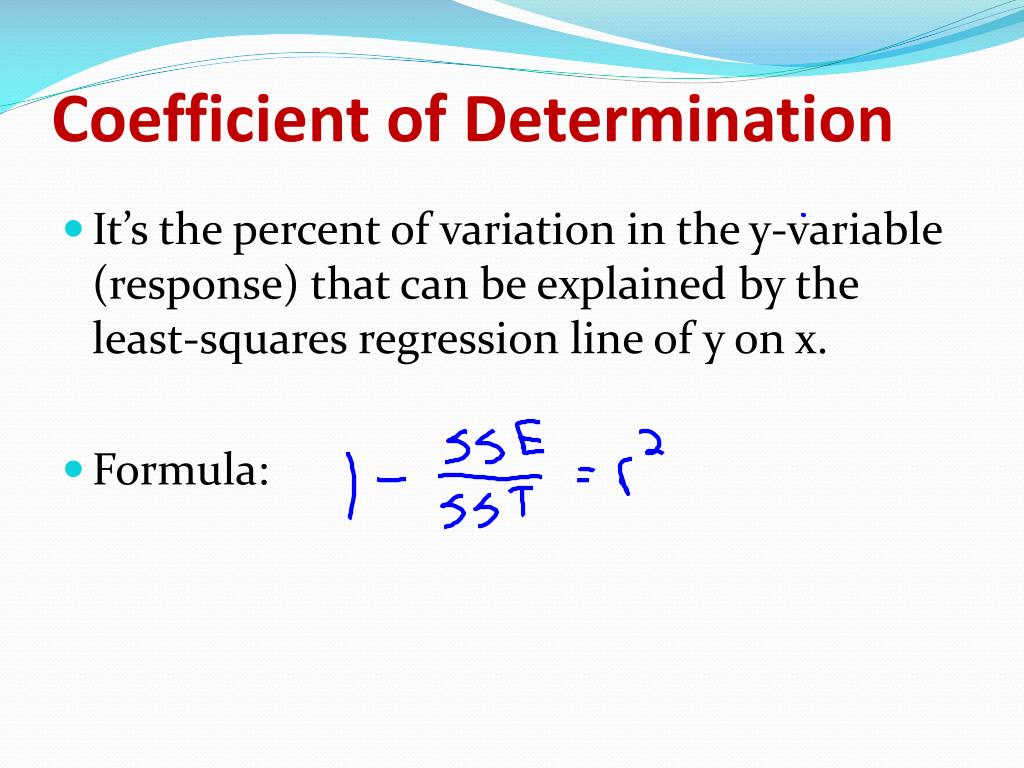
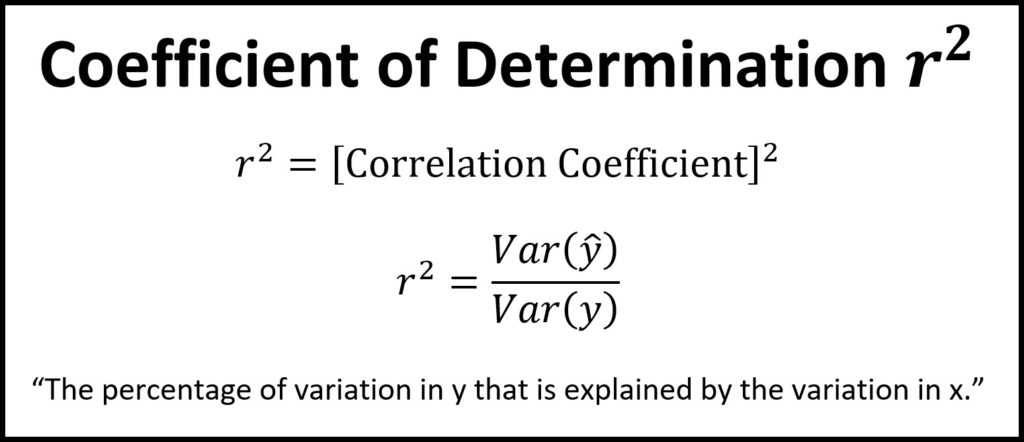
I once spent three days debugging a model that reported an R-squared of 0.94, only to realize the dependent variable had a massive upward trend baked into it. The model wasn't predicting anything useful—it was just riding the same trend line. That's the thing nobody warns you about until you've been burned. At its most basic level, the coefficient of determination (R²) tells you what percentage of the variance in your dependent variable your model explains. The formula is straightforward: R² = 1 - (SSres / SStot), where SSres is the sum of squared residuals and SStot is the total sum of squares around the mean. It ranges from 0 to 1, though it can go negative if your model performs worse than simply predicting the mean of the dependent variable every time. The way I actually use it in practice is less about the number itself and more about comparing models on the same dataset. If Model A gives me 0.72 and Model B gives me 0.75, Model B explains 3% more of the variance. That difference might look small until you scale it to thousands of observations, at which point it's the difference between a model that catches the signal and one that misses it entirely.
One thing beginners consistently get wrong is treating R² as a universal quality metric. It isn't. In fields like finance or social sciences, an R² of 0.20 or 0.30 is often considered acceptable because the phenomena being modeled involve so many uncontrolled variables. Meanwhile, in chemistry or physics lab settings, you'd expect R² values above 0.95 because the systems are tightly controlled. Judging an R² value without context is one of the quickest ways to draw the wrong conclusion about your model. Another pitfall I see constantly: people forget that adding more predictors to a regression model will always increase R², even if those predictors are pure noise. This is why adjusted R² exists. It penalizes you for adding variables that don't meaningfully improve the model. The adjustment formula accounts for the number of predictors relative to the sample size, and it's a much more honest reflection of model quality when you're doing variable selection. I typically use adjusted R² as my primary reporting metric and only mention raw R² for completeness. Here's a scenario that caught me off guard in a recent project. I was building a linear regression to predict housing prices based on square footage, bedroom count, and age of the property. The raw R² was 0.89, which looked solid. But when I plotted the residuals against the predicted values, there was a clear funnel shape—the variance wasn't constant across the range. The model was underpredicting expensive houses and overpredicting cheaper ones. An R² of 0.89 masked a serious heteroscedasticity problem. In that case, I switched to a log-transformed dependent variable, which stabilized the variance and brought the residual plot into a much more acceptable random scatter. The adjusted R² actually dropped slightly to 0.86, but the model was far more reliable afterward.
The other edge case worth noting is when you're working with time series data. R² can be artificially inflated by autocorrelation. If your data points are correlated with their neighbors—a common situation in economic or environmental time series—the model appears to fit well because it's essentially just predicting yesterday's value as today's value. For time series work, I rely more heavily on out-of-sample validation metrics like RMSE on a holdout set rather than trusting R² alone. A proper train-test split or cross-validation approach will give you a much clearer picture of whether the model generalizes or just memorized temporal patterns. When you're comparing multiple models and R² values are close together—say 0.78 versus 0.81—the difference might not be statistically meaningful. You should run an F-test or use information criteria like AIC or BIC to determine whether the improvement is genuine or just the result of additional parameters fitting noise. These tests account for model complexity and give you a more defensible basis for choosing between models than R² alone ever will.
Get the Full Details