Getting Reporting to Work in Ariba Sourcing Through Ariba Connect
The reporting side of Ariba Sourcing is where most procurement teams hit a wall. You can run an RFX, collect bids, compare line items, close out the event, and everything looks fine inside the tool. The moment someone asks for a dashboard, an export with granular data, or a monthly trend report, the whole system turns sluggish. Ariba Connect is supposed to bridge that gap. It pushes transactional data out of Ariba into your warehouse or BI layer so you can build reports without relying on the standard ad-hoc builder. It works. Most of the time.
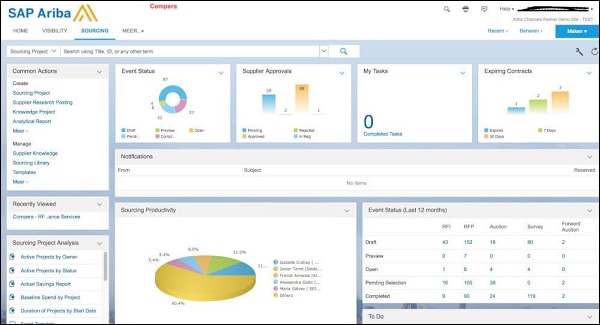
Ariba Sourcing Reporting And Analysis Guide Ariba Connect
I set this up for a mid-size manufacturing client two years ago. They had over sixty sourcing events per month and wanted supplier performance tracked alongside award outcomes. The standard Ariba reports gave them event-level summary data at best. I built an Ariba Connect feed pulling the Sourcing Event header, line items, bid lines, and supplier responses into a simple SQL table, then wrapped it in a Power BI dashboard. The feed ran nightly. We went from pulling manual exports every Friday to having refreshable reports on Monday morning.The first thing you need is a clear understanding of what data is actually available through the Ariba API. Not everything is exposed the way you think it is. Sourcing Event ID, supplier name, item descriptions, bid amounts, and award flags are straightforward. Things like internal comment threads, draft changes, and certain approval audit trails often require additional configuration or don't make it into the standard outbound payload. If your team assumes the full event history is flowing out automatically, you will be disappointed. Setting up Ariba Connect starts in the Ariba Network administration area. You create an integration record, specify the event types you want to push, and define the polling interval. Ariba provides out-of-the-box templates for sourcing events, but those templates are generic. They do not filter by commodity code, cost center, or internal project tag unless you add mapping layers. My typical approach is to use an intermediate staging database rather than pushing directly to a data warehouse. The staging step catches errors, validates timestamps, and lets you reconcile before anything lands in production. One detail people miss is the way bid line updates are handled. Ariba Connect does not always send a full update when a supplier revises their price. It sends delta records. That means if Supplier X changed three line items, you might receive three separate update rows rather than one consolidated revision. If you are aggregating pricing trends without deduplication logic, your numbers will drift. I wrote a simple dedup key using the combination of sourcing event ID, line item ID, and supplier ID with a max timestamp for the revision date. It took me about two days to get right because the documentation describes the field structure but not the practical edge cases around partial submissions and withdrawn bids.
Another common problem is supplier onboarding status. Ariba Connect will sometimes deliver bid data from suppliers who were not fully onboarded at the time of submission. The bid appears in the feed, but the supplier record in your target system may not match. This causes join failures in your reporting models. I solved this by maintaining a lookup table of active Ariba Network supplier IDs and rejecting or flagging any bid line with a missing match. It added about ten percent overhead to the nightly load, but it stopped the silent data corruption that was happening without anyone noticing. If you need deeper analysis than standard reporting allows, you can extend the feed with custom fields. Ariba supports custom project and item attributes that can be included in the outbound payload, but they have to be mapped explicitly during integration setup. I spent a week on a single client where their commodity taxonomy used internal codes that did not exist in the standard template. We created a mapping table in the staging layer and pushed those values through the feed. The result was usable within two weeks after the initial delay. Planning for custom fields early saves you from retrofitting later. There are real limitations to this approach. The standard Ariba Connect polling interval is typically hourly or daily, not real time. If you are running high-volume events with thousands of bids coming in simultaneously, you may see lag between submission and visibility in your report. Ariba has rate limits on API calls. If your event volume spikes, you can hit throttling that delays the entire feed. I saw this happen during a particularly aggressive global procurement round where over four hundred suppliers submitted bids in a three-hour window. The feed slowed to a crawl and we lost several hours of data freshness. The workaround was to switch that specific event to a dedicated integration queue with higher polling priority, which required coordination with the Ariba support team.
Get the Full Details
Scheduling and error handling also deserve attention. Ariba Connect notifications sometimes fail silently. A malformed XML field or an unexpected character in a supplier name can break the feed without generating an obvious alert. You need monitoring in place. I use a simple check that counts the number of records loaded per source event each night. If the count drops below a threshold compared to the event bid total, it triggers a notification. It catches the majority of silent failures within an hour instead of discovering them days later when a stakeholder asks why their report is incomplete. For most teams, the standard Ariba sourcing reporting tools are enough for one-off queries. When you scale beyond ten or twelve sourcing events per month and start needing consistent historical analysis, Ariba Connect becomes necessary. The initial setup takes roughly two to three weeks if you have clean supplier data and defined business requirements. The ongoing maintenance is light, maybe four to six hours per month for validation and exception handling, assuming the integration runs smoothly. If you cannot invest in Ariba Connect, the alternative is manual export and Excel consolidation. That approach works until your event count grows and someone inevitably mislabels a file or duplicates a row. I have seen that exact breakdown happen at three different organizations before they adopted an automated feed. The pain is predictable and usually resolves only after a leadership demand for compliance-ready audit trails forces the issue.
Key takeaways from setting this up repeatedly: Use a staging layer. Do not push directly to your final reporting database. Validate supplier mappings. Deduplicate bid line updates. Build error monitoring. Plan for custom field mapping before the first event goes live. Expect some lag on high-volume days. Coordinate with Ariba support for priority queue adjustments if needed. The system does what it is designed to do. It is not elegant, and it requires careful attention to data quality, but it reliably moves sourcing event data out of Ariba and into a format where actual analysis can happen. Most problems come from incomplete planning, not from the integration itself.