Why You Need a Machine Learning Logbook
Most ML projects fail not because the model is bad but because nobody can reconstruct how the final version was produced. Three months in, you're looking at a folder of saved weights and wondering whether that 87% accuracy came from the corrected preprocessing step or the original buggy pipeline. A proper logbook prevents that. I spent two years building tabular ML systems for industrial clients before I bothered documenting anything. That cost us three weeks of duplicated work on a project where I'd trained six similar models across five environments and couldn't tell which checkpoint matched which data split. After that, every project gets tracked. The learning curve was steep but the payoff is immediate.
Top 10 Machine Learning Logbook
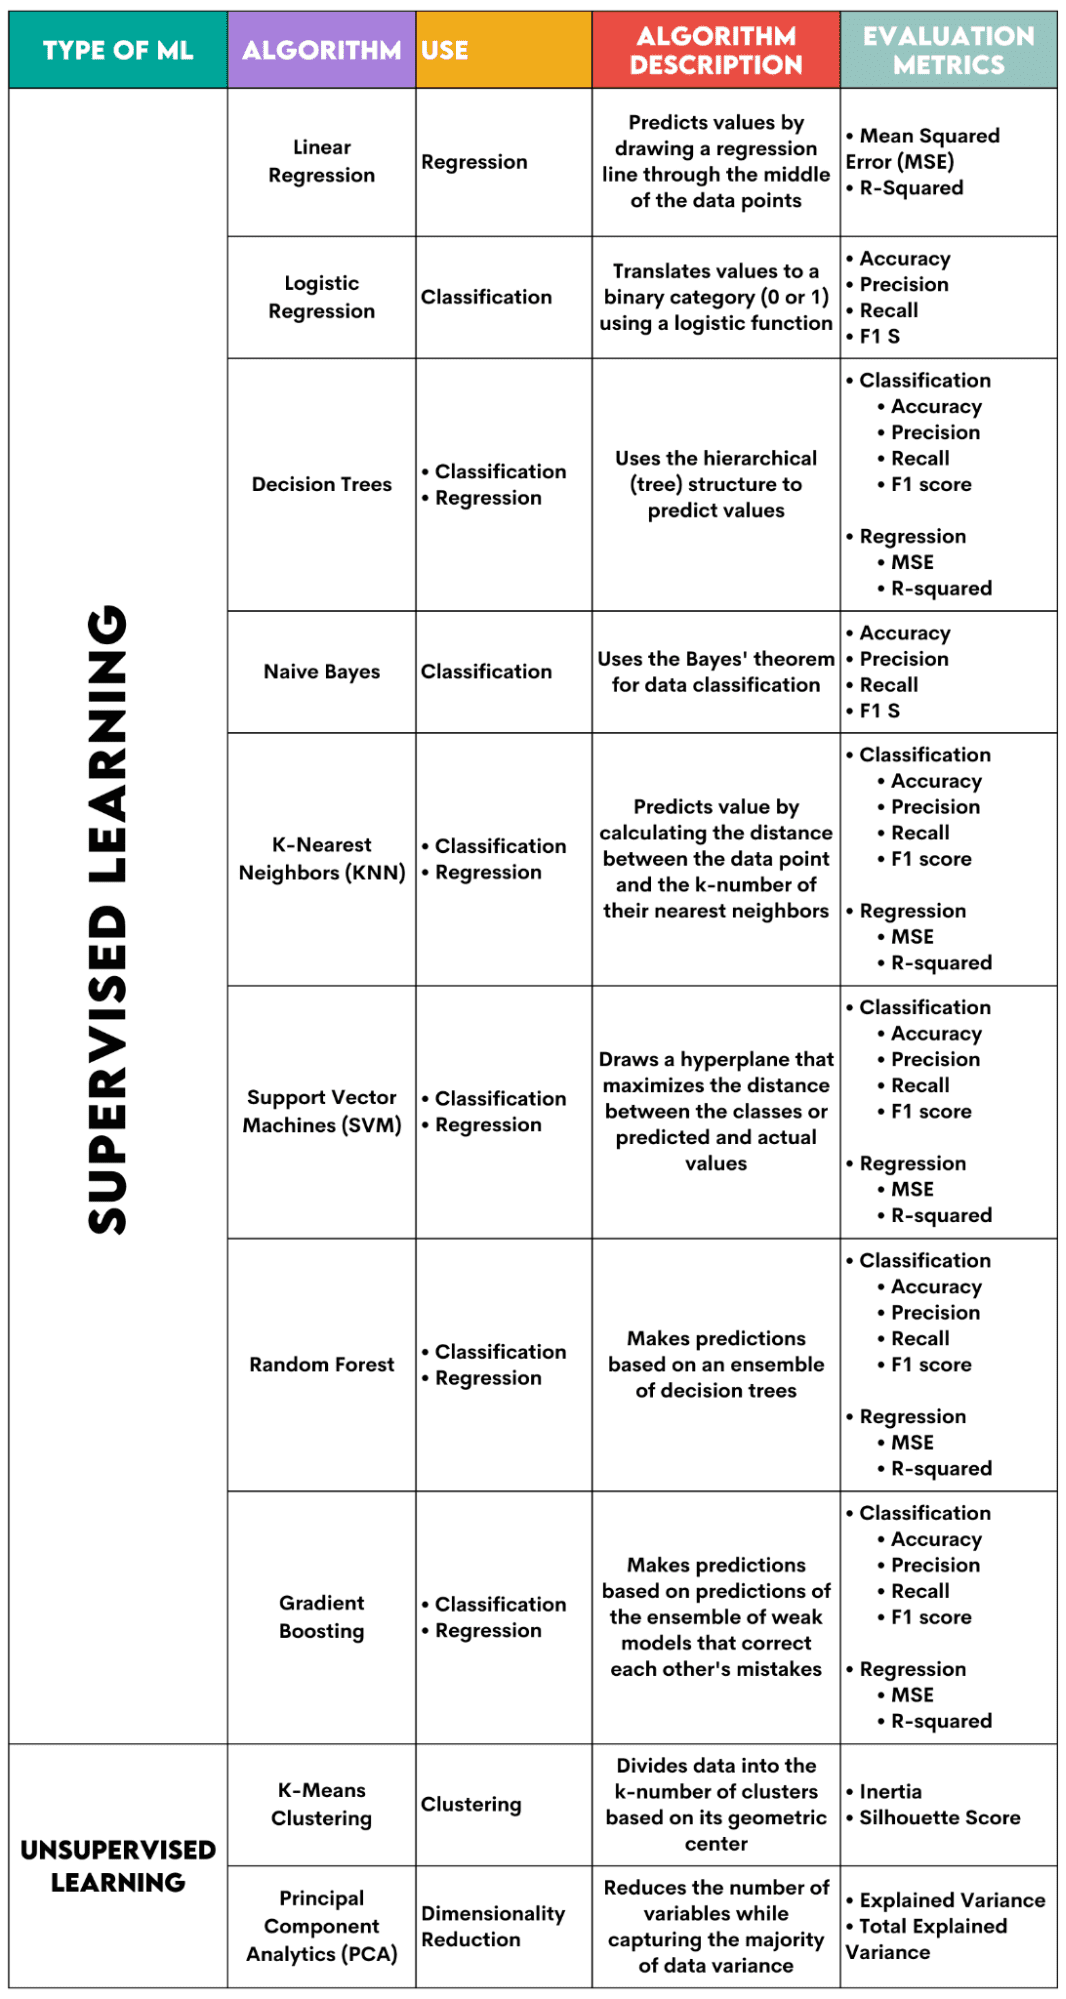
The field has a cluttered tool landscape. Here's what actually holds up under daily production use: Most widely adopted. Tracks metrics, hyperparameters, system resources, and model artifacts. The free tier covers individual developers. Its project grouping and comparison UI are genuinely useful. The one problem: it stores everything in their cloud by default, which is a non-starter for regulated industries. Run it in offline mode with wandb offline and sync later, or use their self-hosted version. Open source, self-hostable, runs anywhere. Tracks experiments, registers models, and serves them through a REST API. The tracking server approach is heavy if you don't need centralized storage. For small teams, just use the file store backend. It lives on disk at mlruns and that's perfectly fine for local development. The model registry is the feature most people ignore until they need it, then they're glad it exists.
Similar concept to WandB but lighter on the UX side. Has a good free tier and supports custom metadata well. I've used it on projects where the team needed to attach non-standard outputs like confusion matrices as visual cards and it handled that better than I expected. Built into TensorFlow. Still relevant if your stack is TF or Keras. Doesn't track datasets natively, which is a gap. It's also purely a visualization tool, not an experiment management system. Use it for debugging training curves, not for reproducing experiments months later. Feature-complete alternative to WandB. Has experiment branching, which some teams find useful. Pricing is higher after the free tier, and the interface feels slightly less polished. Worth testing against WandB for your own workflow before committing.
Get the Full Details
Pure Python library. Not a web UI. It records everything to Redis, MongoDB, or a local JSON file. Great if you prefer code-first logging and don't want a dashboard. The config management is clean. I switched to this for a research project where the team didn't want cloud dependency and needed full reproducibility guarantees. Full pipeline orchestration plus logging. The task queue feature is unique. It can auto-track git commits, environment specs, and hardware. Free for open source. The UI is less refined but functionally complete. Good for teams doing repeated training runs rather than one-off experiments. Not a tracking tool per se, but logs parameter variations in Jupyter notebooks. Pair it with MLflow and it covers the notebook workflow that most of the other tools ignore. Most ML logbook guides don't mention this, which is a mistake.
Data versioning focused. If your problem is more about which dataset produced which result than which hyperparameters, this is closer to what you need. It's heavier than a standard logbook and more infrastructure to maintain. Don't dismiss this. A well-maintained CSV or markdown table with columns for run ID, date, dataset version, model config, training time, and key metrics beats a half-configured tool that nobody uses. I've seen more abandoned WandB accounts than functional ones. The default tracking is metrics and parameters. That's insufficient. A logbook that only records loss curves gives you nothing when someone asks why model version 12 outperformed version 8. You need dataset lineage. The exact version of every data file, the seed value, the random splits, the preprocessing code commit hash. Without those, your logbook is just a scoreboard.
I once spent a day tracking down a performance drop that turned out to be caused by a changed float precision setting in a preprocessing script that wasn't tracked by MLflow. The model architecture and hyperparameters were identical. The difference was a single line that cast inputs to float32 instead of float64. Tools don't catch that. You have to write it down.
How to Start Using One Today
Don't overthink the tool choice. Pick one from the list above that fits your constraints and start using it on your current project. The worst decision is analysis paralysis while your experiments pile up untracked. Initialize tracking before you write a single line of training code. This is the most common mistake I see. Engineers build the model, get good results, then try to retrofit logging. By that point, the random seeds are lost, the environment isn't recorded, and the early experiments are unrecoverable. Wrap your training script with the logging SDK on day one. Make it part of your CI pipeline. Every training run should automatically generate a log entry. Manual logging gets abandoned within two weeks. Automation doesn't.
The Limitations
These tools don't solve the human problem. They can track what you tell them to track. If you don't record the data version, the tool won't invent it. They also create a false sense of reproducibility. I've seen teams with perfect WandB dashboards who still couldn't reproduce a result because the training data was modified manually outside the logged pipeline. The biggest bottleneck is tool sprawl. Teams accumulate four or five tracking systems because different sub-teams picked different tools. This creates more overhead than it solves. Pick one and enforce it.
When It Doesn't Work
Large language model fine-tuning is harder to log meaningfully. The parameter space is massive, the compute hours are expensive, and the incremental changes are subtle. Standard metric tracking barely scratches the surface. For LLM work, consider supplementing a logbook with automated evaluation runs on a held-out benchmark after every checkpoint. A logbook alone won't tell you if your SFT improved alignment or just overfit to the training distribution. If your project is a single quick prototype with no intention of sharing or revisiting, don't bother. The overhead isn't worth it. Logbooks exist for work that outlives the initial experiment.

My Personal Setup
MLflow for experiment tracking, Papermill for notebook parameterization, and a markdown logbook in the repo root for anything the tools miss. The markdown file has one entry per run with the fields I actually care about: what changed, what the result was, and what I'd try next. Three months in, that file is worth more than the MLflow dashboard because it captures decisions, not just numbers.